RoboPapers
@RoboPapers • 7,450 subscribers
@chris_j_paxton @micoolcho @DJiafei @ruijie_sg geeking out weekly with authors of robotics AI papers. On YouTube / X / Spotify / Substack
Videos

Achieving human-like dexterity is the next frontier for robotics, and yet dexterity data is often subtly hard to scale. Real-world dexterity data, including things like finger-pose estimates, is often slightly off, making it physically invalid and hard to execute on real hardware and hard to learn from. DO AS I DO is an algorithm for reconstructing and retargeting monocular RGB videos to robot hands, outperforming the state of the art and even working from generated videos. Bhawna Paliwal Haritheja Will Liang and Mahi Shafiullah 🏠🤖 join us to tell us more. Watch Episode 107 of RoboPapers, with Chris Paxton and Jiafei Duan, now!
RoboPapers30,668 views • 29 days ago

In many fields, automated research has become increasingly plausible with the improving capabilities of frontier language models, and the field robotics may be no exception. In ENPIRE, Wenli Xiao, Jia Xie, and Tonghe Zhang ✈️ CORL build a harness framework that captures physical feedback and allows for automated robotics research, minimizing human effort while training policies that achieve a 99% success rate on challenging, dexterous tasks like organizing a pin box or fastening a zip tie. Learn more in Episode 110 of RoboPapers, with Michael Cho - Rbt/Acc, Chris Paxton and RJ!
RoboPapers16,289 views • 17 days ago

Robotics has a data problem, and egocentric data is a compelling way to solve it because egocentric data is (1) scalable — it’s cheap to collect — and (2) easily captures the breadth and diversity of real human tasks, while (3) being true to real physics. Lightwheel recently released a hundred thousand hours of high-quality egocentric video data, spread across a wide range of human tasks from cleaning and tidying to assembly and construction to retail tasks. Here to tell us about this tremendous effort is Steve Xie, CEO and co-founder of Lightwheel. The data is also available on HuggingFace right now. Watch Episode 102 of RoboPapers, with Michael Cho - Rbt/Acc and Jiafei Duan, to learn more!
RoboPapers33,675 views • 1 month ago

Excitement about world-action models and robot learning has never been higher — they promise a way to use human egocentric data to train massive robotics models which can provide the “GPT” moment for robotics and unlock general-purpose embodied intelligence. And yet there’s been little concrete demonstration of scaling in robot learning. Dyna Robotics aims to change that, with an in-depth look at how scaling works as they approach 1 million hours of training data. Jason Ma Tianyu Li Anh-Quan Pham and Chet Bhateja joined us to tell us more. They show that as the amount of data they use in pretraining increased, they saw predictable, statistically significant gains on accuracy metrics on held-out data (data not seen during training). They go on to talk about what they learned, and show how this can be applied to many different problems. Watch Episode #99 of RoboPapers, with Michael Cho - Rbt/Acc Chris Paxton Jiafei Duan today to learn more!
RoboPapers26,249 views • 2 months ago

Diffusion Policy was one of the big breakthroughs that has enabled an explosion in real-world robot learning. However, it’s always had a weakness, which is that it works by computing a final action trajectory from random noise, which leads to high latency when predicting a final action sequence. Instead, why not initialize the search based on previous actions? This allows for incredibly fast policy inference and in many cases improved generalization, generating high-quality predictions with sub-ms latency. Jindou Jia and Jianfei Yang join us to explain. Learn more on Episode 95 of RoboPapers, with Michael Cho - Rbt/Acc and Chris Paxton!
RoboPapers28,629 views • 2 months ago

Robotics fundamentally involves understanding the dynamics of how things change in the world in response to action and force. This is impossible to learn from static images; instead, it’s far more effective and more data-efficient to learn from video. Elvis Nava joins us to talk about @mimicrobotic. One of the key findings from mimic-video is that pretraining on webscale video allows robots to learn physics priors; as a result, policies train faster, generalize better, and are capable of more impressive dexterity, versus training on static images or image-language pairs as per a VLM. Watch Episode #81 of RoboPapers with Michael Cho - Rbt/Acc and Chris Paxton to learn more!
RoboPapers48,892 views • 5 months ago

Specifying reward functions for robots is one of the hardest things about reinforcement learning. Robot rewards often need to be very detailed; metrics like progress can be ill-defined and hard to estimate. This leads to most robot learning defaulting to sparse rewards or simple preference learning. But naive preference learning (having human annotators choose one trajectory over another) is an easy solution, but obscures a lot of the signal in complex tasks and can make learning a lot less efficient. Marcel Torné, Anubha Mahajan, and Abhijnya Bhat join us to talk about their solution: freeform preference learning, which lets annotators define natural-language axes to compare trajectories over. This improves real-world performance on long-horizon manipulation tasks over sparse rewards and simple binary preference learning. Watch Epsiode 103 of RoboPapers, with Michael Cho - Rbt/Acc and Jiafei Duan, today to learn more!
RoboPapers17,501 views • 1 month ago

Memory is one of the most important problems in robotics. Long horizon memory is key for a variety of robot manipulation problems. However, there exist no good benchmarks for understanding progress in how well generalist robot policies can understand language. Yinpei Dai and Yuejiang Liu made RoboMME as a solution: it’s a large benchmark which shows 16 different robot tasks, like counting objects or mastering timing. They show 14 different memory-augmented generalist policies across these different benchmarks. It’s an incredibly thorough and interesting result, aimed at driving forward this core robotic capability. To learn more, watch Episode 91 of RoboPapers with Michael Cho - Rbt/Acc and Chris Paxton!
RoboPapers30,785 views • 3 months ago

One of the key advantages of legged robots like humanoids should be how effectively they can move across a wide variety of terrain types to accomplish their task. But Light-Loco-Parkour from the team at Light Origins aims to change that: using only onboard sensing, they show a policy which can decide when to walk, vault, climb, or otherwise traverse as it moves through a complex environment. Unlike many others, it uses sparse seeds instead of relying on a large motion corpus, learning when to use its skills to move around without specific sub-task labels. xiaodao chen and Yuntao Ma join us to go into the details. Watch Episode 104 of RoboPapers now, with Michael Cho - Rbt/Acc and Chris Paxton, to learn more!
RoboPapers14,895 views • 1 month ago

With enough data, robots and AI can learn “world models” that let them predict the results of their actions. These models are a way to learn how embodied AI agents can perform a wide variety of useful tasks — but they require a huge amount of data. The team at General Intuition General Intuition has a solution: use data from video games! Games teach movement, problem solving, and complex spatial reasoning, and they come in a staggering diversity of forms, covering a wide variety of problems. What’s more, the captured data is high-quality, without the noise or annotation error that can come from We sat down with Pim de Witte and Adam Jelley from the General Intuition team to learn more about their history, their plans, and their philosophy.
RoboPapers85,927 views • 11 months ago

Robots has a data problem, in that robotics data is rare. While human video is quite common, it’s not usually directly usable for robots for a variety of reasons, most significantly that it’s missing explicit, accurate robot actions. Instead, Jeremy Collins proposes that we predict keypoint trajectories — basically, how any given point in an object will move as a robot performs a task. This lets us use action-free human video to train robot skills. Learn more by watching Episode #37 of RoboPapers with Michael Cho - Rbt/Acc and Chris Paxton now.
RoboPapers89,011 views • 1 year ago

Robot policies must be both reliable and highly capable to be useful; the best way to achieve this level of performance is with reinforcement learning. However, for reinforcement learning you are usually stuck between two difficult options: reinforcement in the real world is often risky and expensive, while reinforcement learning in a traditional simulator takes a lot of engineering work and has a persistent sim-to-real gap. What if instead you could train your robot purely in a world model? RISE by Jiazhi Yang et al. uses a compositional world model to predict the future and evaluate progress. This allows for a self-improving pipeline, which learns a world model from real data and then learns how the robot should perform different tasks. This pipeline results in a data-driven way to improve policy performance from real data but without real-world reinforcement learning. Watch Episode #86 of RoboPapers, with Chris Paxton and Jiafei Duan, to learn more!
RoboPapers38,867 views • 4 months ago
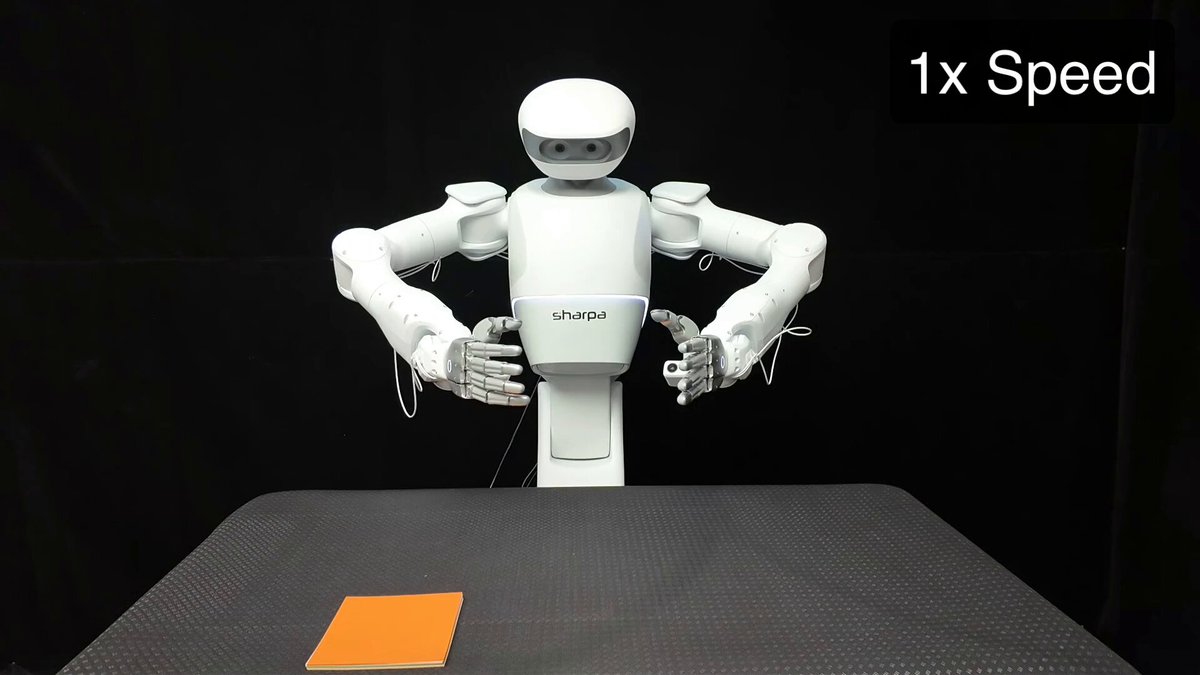

Many tasks cannot be completed by one robot alone. But coordinating multiple robots performing complex manipulation tasks is very difficult. Many solutions rely on complicated centralized control, which tends towards bespoke methods that do not scale well with team size. Enter CHORUS by Ria Doshi, Jeannette Bohg, and team. They train a single VLA to control multiple, diverse robots, given only local observations and identifying information. This allows robots to collaborate on tasks like using a tape measure, handing over a book, or lifting a laundry basket. To learn more, watch Episode #93 of Robopapers now, with Michael Cho - Rbt/Acc, Jiafei Duan, and Chris Paxton!
RoboPapers26,544 views • 2 months ago

Reinforcement learning has unlocked tremendous gains in broader AI and humanoid robot whole body control, but still has yet to deliver strong results for robot manipulation due to the difficulty of capturing tasks in an accurate simulation; one way to fix this is to create complex environments with learned world models. But learning fully within world models is often intractable as powerful world models are computationally too expensive. Instead, Joseph Amigo and Rooholla Khorrambakht propose to break the problem down: into a large-scale world model that can generate forward trajectories, and a lightweight, low-dimensional latent-space model which can approximate local dynamics of a problem, without needing to back-propagate through a heavy global model. What this means: you can do reinforcement learning in this coupled local-global world model, and learn contact rich skills for a robot. To learn more, watch Episode #101 of RoboPapers, with Michael Cho - Rbt/Acc and Jiafei Duan!
RoboPapers16,866 views • 1 month ago

Collecting robot data at scale is key to deploying working manipulation policies, and the team from Tutor Intelligence Tutor is here to tell us about how to accomplish it. Their new announcement: a massive, 100-robot “data factory,” with a behind-the-scenes look at how to build a teleoperation platform and how to make robots and policies that are useful for their customers. Tutor Intelligence is a full-stack robotics company: they build robot arms, they sell robot arms, they write the software and they train neural networks. Josh Gruenstein, Jesse Michel, Shiraz, and Joe McCalmon, and Joe McCalmon join us to tell us more about how they scale both teleop data and human interventions from their teleoperators in order to train the policies they need. Watch Episode #85 of RoboPapers, with Chris Paxton and Jiafei Duan, to learn more!
RoboPapers36,041 views • 4 months ago

Embodied AI is exploding, and it’s been amazing to learn about it with you all. We have now recorded over a hundred discussions with the best researchers in the world on embodied artificial intelligence and robotics, covering topics like scaling robot learning, humanoid whole body control, tactile sensors, sim-to-real, and so much more. For our hundredth episode, we brought on our newest co-host, RJ, to ask us what we’ve seen and learned in the first hundred episodes. Which were our most-watched episodes? Which institution shows up the most? Who was our most frequent guest? What did we learn? Find out on Episode 100 of RoboPapers, with Michael Cho - Rbt/Acc, Chris Paxton, Jiafei Duan, and RJ!
RoboPapers15,195 views • 1 month ago

Instead of choosing between training a world model and training a language conditioned robot policy, why not do both? LDA-1B s a new foundation model that is trained on 30,000 hours of human and robot interaction data. Part of the secret is that LDA-1B jointly learns forward dynamics, action prediction, and visual forecasting, all in a structured DINO latent space which avoids the pitfalls of redundant pixel-level prediction which isn’t necessarily aligned robot action. This approach works on both dexterous hands and simple robot grippers; it also generalizes across objects, tasks, and scenes. Jiangran Lyu joins us to explain. Learn more on Episode 98 of RoboPapers, with Michael Cho - Rbt/Acc and Chris Paxton!
RoboPapers16,345 views • 2 months ago

Robotics has changed dramatically over the last eight years. Ted Xiao has been involved in the cutting edge of robot learning through this period, spending those eight years at Google Brain/Google Deepmind. And he’s identified three eras of robot learning. These eras are: - The Era of Existence Proofs - trying different methods like QT-Opt, on-robot RL - The Era of Foundation Models - transitioning to data collection and clean objectives (i.e. supervised learning) - The Era of Scaling - orders of magnitude more data and larger models, enabling reasoning, long-horizon actions, and cross-embodiment transfer Watch Episode 78 of RoboPapers, with Michael Cho - Rbt/Acc and Jiafei Duan to learn more!
RoboPapers36,838 views • 5 months ago

For general-purpose robots to be useful, we must be able to teach them new tasks quickly and repurpose them to new roles. But most techniques for teaching robots — even from human demonstrations — take a great deal of new data. But it turns out that it is possible, in part through decomposing tasks into component subtasks, that it’s possible to learn a robot skills quickly. Kamil Dreczkowski Pietro Vitiello and Edward Johns join us to talk about their extensive study on how to teach robots new skills efficiently, while also generalizing to novel object instances, using a combination of task decomposition and retrieval, work that was published in Science Robotics. Watch episode #94 of RoboPapers now, with Michael Cho - Rbt/Acc and Jiafei Duan, to learn more!
RoboPapers19,495 views • 2 months ago