Command Code
@CommandCodeAI • 28,032 subscribers
Meet the coding agent built for open models. Command Code. Costco of AI. Model repairs, /design, #1 on leaderboards, world's best $10 GOAT plan w/ $100 usage.
Shorts




Videos
Introducing Command Code extension for VS Code & Cursor! Available today is beta. CLI, Desktop, and now Extension. Manage sessions, use files and selected code as context, review changes, instant edits with /design and slash commands for /model, /plan, /mcp.
Command Code187,645 görüntüleme • 19 gün önce

Fable 5 vs Grok 4.5 vs GPT 5.5 We put three top-tier models to build a same game challenge. Used Command Code /design, and the exact same prompt. Result: Grok 4.5 genuinely plays like a polished mobile game. Fable 5 and GPT 5.5 feel too fast. Everything feels rushed, lacks finish. Ranking based on DX & Features: → Grok 4.5: 9/10 → Fable 5: 7.5/10 → GPT 5.5: 7/10
Command Code914,316 görüntüleme • 3 ay önce
Introducing Command Code Desktop App! ⌘ Available today in beta for Mac, Linux, & Windows. Building the most powerful agentic app, starting with code. Multiple agents, files, Git, terminal, browser previews, plans, and instant edits with /design. This is just the beginning.
Command Code216,492 görüntüleme • 1 ay önce

Kimi K3 vs GPT-5.6 Sol vs Fable 5 Three top-tier models. Same /design prompt across all. Parameters reviewed: Pace, design sense, gameplay feel Result: Kimi K3 nails the design sense and knows exactly what to add in-game. Pace and gameplay held up well. Fable 5 and GPT-5.6 Sol both play too fast, video isn't sped up. Ranking (DX, Features & Cost): → Kimi K3: 9.5/10 · $0.030 → Fable 5: 7.5/10 · $0.38 → GPT-5.6 Sol: 7/10 · $0.11
Command Code377,957 görüntüleme • 3 ay önce

We ran a test between the new Qwen3.8-Max, Opus 5 and GPT-5.6 Sol. 3 models. same prompt. one-shot with the /design command. Reviewed gameplay features, UX/UI and cost. 🔹 Qwen3.8-Max → 9/10 · $0.0248 🔹 GPT-5.6 Sol → 9/10 · $0.150 🔹 Opus 5 → 8.5/10 · $0.253 Qwen3.8-Max is approximately 4.2× cheaper than GPT-5.6, Sol, Opus 5 and has the same level of UI, UX, and gameplay.
Command Code180,367 görüntüleme • 2 ay önce

GPT-5.6 Sol vs Fable 5 vs Grok 4.5 Built a car racing game with a UX-over-UI focus, using /design command. Parameters we reviewed: Car speed, crash behavior, scoring, smoothness, and feel. Results: Grok 4.5: best overall performance Fable 5: a close second, nearly matching Grok 4.5 GPT-5.6 Sol: great UI, weak gameplay (excess drift and friction) Ranking (based on actual gameplay): - Grok 4.5: 9/10 - Fable 5: 8/10 - GPT-5.6 Sol: 7/10 (UI was 10/10, gameplay wasn't)
Command Code79,680 görüntüleme • 3 ay önce

Tested Mimo-V2.6-Flash, Grok-4.7, and DeepSeek-V4.1-Flash with 3D SubwayBench using the same /design prompt. 🔹 DSV4.1-Flash: 9/10 · $0.024 · one-shot · strong 3D UI/UX + gameplay 🔹 Mimo-V2.6-Flash: 8/10 · $0.018 · playable 2D result in ~4 iterations 🔹 Grok 4.7: 3/10 · $0.35 · slower UI + gameplay, needs more iteration
Command Code31,073 görüntüleme • 1 ay önce

Ran FlappyBench on Muse Spark 1.3, Gemini 3.8 Flash, and Grok-4.6 with the same /design prompt. 🔹 Muse Spark 1.3: 9/10 · $0.072. Nailed UI in 2 iterations with lowest cost 🔹 Grok-4.6: 9/10 · $0.095 · Matched Muse’s output, but cost 2x more 🔹 Gemini 3.8 Flash: 7/10 · $0.205 · Most expensive and not fully finished
Command Code39,025 görüntüleme • 1 ay önce

We ran a test between GPT-5.6 Sol, Kimi K3, and Gemini 3.6 Flash. One prompt. Across all three models. Using our /design command. Results (gameplay, UX, and UI): 🔹 Kimi K3 performed well across all three. 🔹 GPT-5.6 Sol is good, but it gets annoying when the ball hits the wall. 🔹 Gemini 3.6 Flash is bad (took 5–6 attempts), but it has features the others don’t, like dropping coins for power-up balls and increasing the bar length. Ranking (DX, features, and cost): 🔹 Kimi K3: 10/10 · $0.10 🔹 GPT-5.6 Sol: 9/10 · $0.52 🔹 Gemini 3.6 Flash: 6/10 · $0.45
Command Code61,412 görüntüleme • 3 ay önce
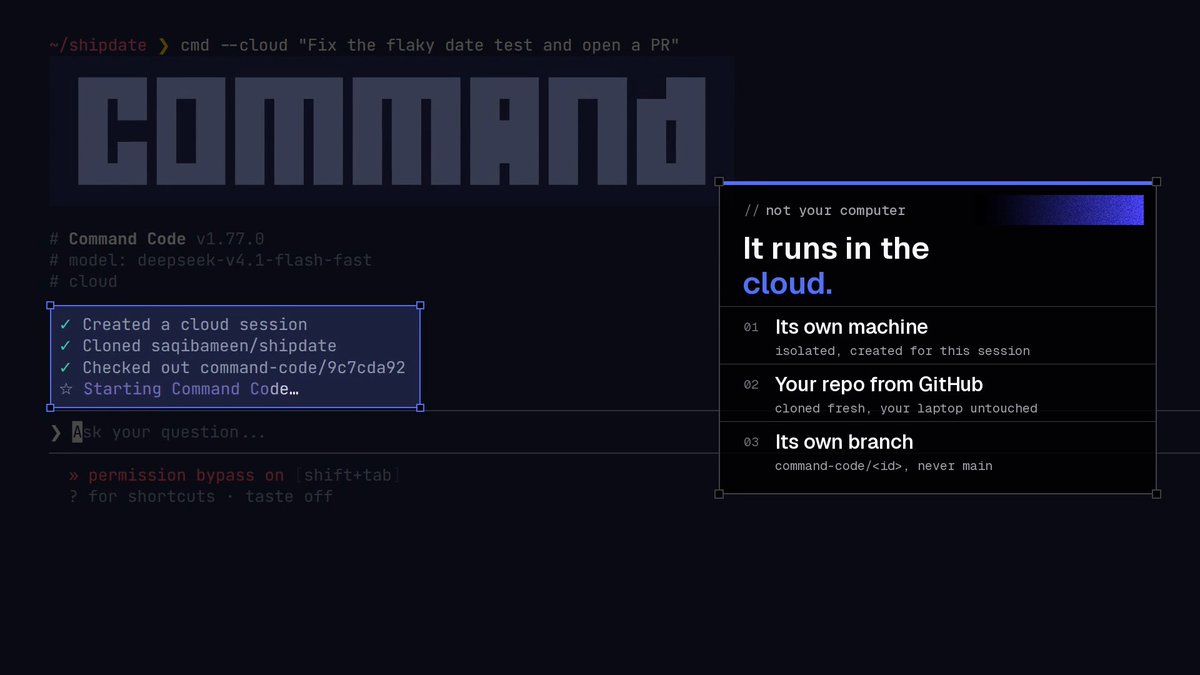
Introducing Cloud sessions with sandboxes in Command Code. · Run Command Code in the cloud on your GitHub repo · Close your computer and the session keeps working · Push changes and open a draft PR when done Try now with $ cmd --cloud Zero babysitting is here!
Command Code11,773 görüntüleme • 23 gün önce

Ran FlappyBench on DeepSeek V4.1-Flash, GLM 5.3, and Kimi K3 with the same /design prompt. 🔹 DSV4.1-Flash: 9/10 · $0.0089 one-shot with the lowest cost 🔹 GLM-5.3: 9.5/10 · $0.0184 · nailed the UI but cost 2x more 🔹 Kimi K3: 8/10 · $0.0740 · hard-coded gameplay and 8x more
Command Code20,527 görüntüleme • 1 ay önce

Tested FlappyBench with GLM 5.3, Fable 5 and GPT-5.6 Sol 3 models. Same prompt with /design command. Scored on features, UX/UI, and cost. 🔹 Fable 5 → 9.5/10 · $0.420 🔹 GLM 5.3 → 9/10 · $0.018 🔹 GPT-5.6 Sol → 9/10 · $0.150 Results: → Fable 5 wins on quality, but costs 23x more than GLM 5.3 → GLM 5.3 gives better output than GPT 5.6 Sol at 8x cheaper → Optimizing for cost? Go for GLM 5.3. Otherwise, Fable 5 if quality matters
Command Code22,894 görüntüleme • 2 ay önce


Writing tests is now the easiest part of your workflow. Pick a file, and Command Code will: - Analyze the code - Generate the right test cases - Run the test suite - Resolve failures - Re-run until all tests pass Try it on a file that hasn’t been tested yet.
Command Code20,621 görüntüleme • 2 ay önce

We ran a test between Opus 5, GPT-5.6 Sol, and Kimi K3. One prompt. Across all three models. With our /design command. Results: We reviewed gameplay, UX, and UI 🔹 Opus 5 is strong UI + motion, best gameplay 🔹 Kimi K3 has solid design and gameplay 🔹 GPT-5.6 Sol has best UI, worse gameplay Ranking (DX, features, and cost): 🔹 Opus 5: 10/10 · $0.25 🔹 Kimi K3: 9.5/10 · $0.12 🔹 GPT-5.6 Sol: 7/10 · $0.32
Command Code24,686 görüntüleme • 3 ay önce

