Biwei Huang
@huang_biwei • 5,109 subscribers
Founder @AetherLab_AI Assistant Professor @HDSIUCSD @UCSanDiego Causal World Model, Causality-driven Agentic System for the next AI paradigm
Videos

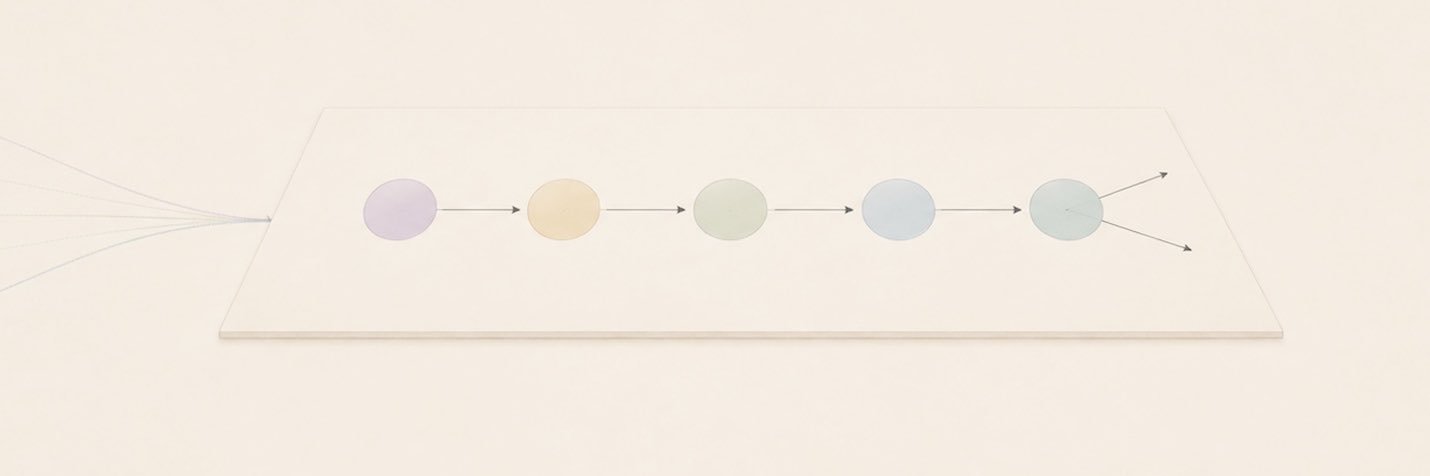
Can an agent explore a new environment, learn its causal structure, and keep improving without updating its model weights? We introduce RSIAgent, a framework for recursive self-improvement through autonomous exploration. Using Kimi-K3 and GLM-5.3 as base models, RSIAgent outperforms GPT-6 Astra on both OSWorld 2.0 and Agents’ Last Exam. RSIAgent decides what to explore, executes tasks, verifies outcomes, and consolidates stable action-condition-outcome relationships into memory for future use. With the underlying model weights fixed, RSIAgent achieves: - 78.98% Partial Score on OSWorld 2.0 (0808 offline), compared with 72.60% for GPT-6 Astra - 84.82% on Agents’ Last Exam (Near-term), compared with 82.26% for GPT-6 Astra We call this Scaling Experience. Agents can continue improving by acquiring, verifying, and reusing their own experience while the underlying model weights remain fixed. Links in the reply below.
Biwei Huang61,322 views • 16 days ago

World models have a causality problem. Realistic videos are not enough. A world model should predict the future caused by an action, not just a plausible future. We find that many latent-action world models generate convincing videos while barely responding to the supplied action. The root cause lies in Latent Action Models (LAMs): reconstruction objectives entangle action-induced dynamics with action-irrelevant visual changes, producing visually confounded latent actions. Our solution is CD-LAM (Causally Debiased Latent Action Model). It cleanses latent action representations before pre-training begins, requiring zero changes to backbone architectures, latent dimensions, or action interfaces. Key Benchmark Results: - Action Controllability: Cuts action-following error by >30% while simultaneously enhancing visual fidelity. - Extreme Sample Efficiency: Achieves baseline performance in just 3,000 post-training steps instead of 50,000 - a >10x speedup. By removing visual confounding, CD-LAM bridges the gap between passive video prediction and actionable causal intelligence for robotics. The next bottleneck for world models isn’t realism. It’s causality. Paper, project page and additional resources in the reply below. #WorldModels #EmbodiedAI #Robotics #CausalAI
Biwei Huang15,017 views • 2 months ago
No more content to load