Загрузка видео...

Не удалось загрузить видео

На главную

A Perfect Pairing! 5G & Edge Computing: Together they enhance responsiveness, capacity and reliability by processing #data closer to where it’s generated! 🌟See🔗 ◀️T-Mobile Business 🔸This is critical for applications such as augmented reality #AR and #customer interaction and especially in contexts where low latency and near-real-time data processing...

10,487 просмотров • 2 лет назад •via X (Twitter)

Комментарии: 10

Фото профиля Fati Sule
Fati Sule2 лет назад

@TMobileBusiness Eco-friendly initiative👌🙏 @sallyeaves 🌟 Think green 👉go green 🌿 Cleaner and healthier world🌐 #5G #Data 👉Edge Computing

Фото профиля Prof. Sally Eaves
Prof. Sally Eaves2 лет назад

@TMobileBusiness Super appreciated feedback @sulefati7 many thanks indeed for sharing, love your focus and passion for this area! Warmest wishes, Sally #5G #Data #Edge #ESG

Фото профиля Mitja Martini
Mitja Martini2 лет назад

@TMobileBusiness Nice to see edge computing in your feed - I used to be part of the larger 5G/edge computing tribe at Deutsche Telekom AG, T-Systems, my employer, provided the edge computing for 5G campus networks for some time.

Фото профиля Jean CAYEUX 🇫🇷
Jean CAYEUX 🇫🇷2 лет назад

@TMobileBusiness Thanks Prof and #HappyMonday #HappyNewWeek

Фото профиля Prof. Sally Eaves
Prof. Sally Eaves2 лет назад

@TMobileBusiness Always appreciated Dear Jean @jeancayeux many thanks indeed and likewise too! 💫

Фото профиля Mack - #TechTrends
Mack - #TechTrends2 лет назад

Absolutely a perfect pairing. MEC and 5G handshaking will be a game changer for any enterprise. 5G-MEC synergy provide more efficient interactions with end users. Ultra Low latency - reduced jitter - high speed mobility - SLA assurance - on demand cloud - Cost savings - openness - application agility and so on - a handful of collaborative benefits . Thanks Dear Sally 🙏 @sallyeaves #TMobile #5G #MEC #Cloud #EdgeComputing

Фото профиля Prof. Sally Eaves
Prof. Sally Eaves2 лет назад

A superb summary here Dear Mack @Analytics_699 thanks so much for sharing. Love your examples around the impact of #MWC and #5G handshaking and just wanted to share a few more of these in action. Thanks a million, Sally Reduced Jitter: In #telemedicine remote surgeries or real-time diagnostics can be performed using 5G and MEC, where having a stable and smooth #video transmission is critical. Reduced jitter ensures that live feeds and data remain steady and uninterrupted, improving the reliability of #healthcare services. Cost Savings: For #energy companies operating remote oil fields or wind farms, 5G and MEC reduce the need to transport vast amounts of data to centralized #cloud centers, lowering #data transmission costs. Edge processing of sensor data also reduces bandwidth needs, leading to cost savings. Application Agility: In the #entertainment industry, streaming companies can deploy edge-based video services using 5G for ultra-fast content delivery and low-latency interactive experiences, such as live-streamed #events or immersive augmented reality #AR . The agility of deploying new services and updates on demand ensures companies remain competitive in a fast-evolving market. Just a few detailed examples here - together, MEC and 5G enable real-time, high-performance applications that transform enterprise operations, drive innovation, and deliver cost-effective, scalable solutions! Thanks again Mack @Analytics_699 @TMobileBusiness

Фото профиля Gary Rodgers
Gary Rodgers2 лет назад

@TMobileBusiness 😀

Фото профиля Thorsten Linz
Thorsten Linz2 лет назад

@TMobileBusiness @sallyeaves Fascinating tech combo. Processing data locally enhances AR/VR experiences significantly. But what everyday use cases excite you most?

Фото профиля Beverley Eve #TechForGood 🌱🌸 #MWC24 #5G
Beverley Eve #TechForGood 🌱🌸 #MWC24 #5G2 лет назад

@TMobileBusiness Love this @sallyeaves! And all the work that @TMobileBusiness are doing here. Thanks for continuing to fly the flag for #Sustainability and #tech 💚

Похожие видео

🎥 New! Driving Transformation: Expanding Telecoms and Consumer Possibilities! 🗼 At the Paris #OSSBSSSummit2024 the CSP global community has come together with Ericsson Software to engage, learn, collaborate and drive forward ecosystem #innovation ! 🔸In this enriching context it is a pleasure to bring you this exclusive discussion onsite with🌟George Glass, CTO, TM Forum TM Forum and🌟Jason Keane, Head of Portfolio, Ericsson Business and Operations Support Ericsson - diving into the momentum of OSS and BSS transformation for CSP’s! 🔹From the advancing of agile programmable environments, standardized #OpenAPIs and Developer Marketplaces, alongside the critical role of end-to-end #orchestration - right through to role of #AI & #GenAI to transition to Autonomous Networks: 💡In this special we cover: 🔸The TM Forum’s perspective on the key focus areas for #OSS and #BSS 🔸How #CSPs are addressing these priorities 🔸Assessing progress on the journey to #AutonomousNetworks (Moving from Level 2.6-4) 🔸How AI/GenAI and ‘Closing the Loop’ on Intent can come together! Some very tangible change examples and advice shared by George and Jason here! ✅ 🗨️ Thanks for Watching! And all feedback welcome And please follow Ericsson Software for all the latest developments! All feedback and questions most welcome🗨️ Warmest wishes, Sally #OSSBSSSummit2024 #Ad #5G Allied Market Research #RaviVisvesvarayaSharadaPrasad #Telecom #InfoTech #data arlene newbigging Mack JC Gaillard #Telco Enrico Molinari #VivaTech2025 Dr. Theophano Mitsa ☦️🇬🇷🇺🇸 Laurent Alaus #Developer Knut Jägersberg Dinis Guarda Antonio Vieira Santos Dr. Khulood Almani | د.خلود المانع Fati Sule ipfconline Brian Ahier #Analytics Spiros Margaris BusinessIntelligence Greg Valancius Yann Marchand Dr. Marcell Vollmer #StaySafe #CES2026 Ian Jones Lionel Costes Xavier Gomez Jean-Baptiste Lefevre Estrella Baskaran Ambalavanan #ML Sahba Ferdowsi DO (conciergedoc) ALBERTO GARUCCIO TAEVision Mechanics #LLM CONETEC 2010 Tony Moroney #DigitalTransformation Chidambara .ML. #Networks 💙 #TechForGood 💙 Thomas J. Dettling #DigitalTransformation @FrRonconi

Sen. Sally Eaves

11,599 просмотров • 1 год назад

🎥 New! Unlocking Network Value! OSS & BSS Transformation and the Critical Role of AI, GenAI and Service Orchestration & Assurance Ericsson Software 🌟At the🗼Paris #OSSBSSSummit2024 the themes of unlocking value, new services and new revenue opportunities has been center stage, alongside increasing efficiency whilst reducing complexity ✅ 🔸In particular, #Innovation driving the exposure of advanced #mobile #network functionality that is made readily consumable to the global #developer community – and at scale – has really caught my attention. To explore more, it is a pleasure to introduce this live conversation with🌟Laurent Leboucher, Group CTO and SVP, Orange Innovation Network Laurent Leboucher Orange and🌟Mats Karlsson, VP and Head of Ericsson Business and Operations Support Systems Mats Karlsson 💡In this special we cover: 🔸Key changes in the business that #OSS and #BSS need to support 🔸The critical elements of transformation coming together within OSS & BSS Systems 🔸How Service #Orchestration and #Assurance fits into the requirements of differentiated connectivity services 🔸The most exciting changes that #AI will bring to OSS and BSS delivery 🔸And regards AI, look out for 3 excellent takeaways around positive impacts across 1) Internal Processes, R&D and Service Delivery 2) Product Interaction 3) Evolved pattern of usage in mobile networks – more uplink traffic with low latency ✅ Chuck Brooks 🗨️ Thanks for Watching! And all feedback welcome And follow Ericsson Software for all the latest developments! All feedback and questions most welcome🗨️ Warmest wishes, Sally #OSSBSSSummit2024 #Ad #Telecoms #5G Brian Ahier #5GStandalone TM Forum Knut Jägersberg #RaviVisvesvarayaSharadaPrasad #Telecom #InfoTech #GenAI ipfconline BusinessIntelligence Mack #ML Dr. Khulood Almani | د.خلود المانع @FrRonconi Anand Narang 💙 #TechForGood 💙 Laurent Alaus Dr. Marcell Vollmer #StaySafe #CES2026 Fati Sule #Networks Scott W. Luton #Paris Ian Jones #Analytics JC Gaillard corixpartners Dr. Theophano Mitsa ☦️🇬🇷🇺🇸 Lionel Costes Prof. Manish Thakur Spiros Margaris #CyberSecurity Chuck Brooks Xavier Gomez Eric T. #IoT TAEVision Mechanics Chidambara .ML. Tony Moroney #DigitalTransformation

Sen. Sally Eaves

13,045 просмотров • 1 год назад

🎥 New! Unlocking Ecosystem Potential and Driving Value with Singtel and Ericsson! ⚡ 💡At the🗼Paris #OSSBSSSummit2024 with Ericsson Software a new #MOU signing between Singtel’s Paragon #platform and Ericsson’s Service #Orchestration & #Assurance heralds a new advance in the simplification and automation of the creation, management and differentiation of #5G network services! Singtel Ericsson ⚡ TM Forum 🌟In 5 words: self-service, API-enabled, zero-touch, cloud-native and real-time – this is the impact of the combined resulting solution for ordering, provisioning and assuring communications services! 🗨️Or in other words, this #innovation readily allows enterprises to easily provision services like #networkslicing, with requests instantly executed through #APIs - The combined offering reduces network setup times, supports diverse use cases, and helps telcos monetize #5G and #edge capabilities while cutting operational costs ✅ 🔹To deep dive further into driving value by assuring quality of connectivity AND enabling superior service experience, it is a pleasure to introduce this live discussion with 🌟Manoj Prassana Kumar, CTO & Vice President, Singtel Digital InfraCo Singtel and🌟Aurelie Zanin, Head of Solution Line, Ericsson Business & Operations Support Systems Ericsson 💡In this special we cover: 🔸Why Singtel took the decision to create the Paragon platform 🔸Progress on the journey to take advantage of Open APIs, Network and Service API’s 🔸How #CSP ’s are advancing in their journey towards differentiated connectivity services 🔸Key focus areas when it comes to Network and Service APIs 🔸Additionally, look out for some excellent takeaways on the impact of #Regulation and attracting application #developers ! ✅ 🗨️ Thanks for Watching! And all feedback welcome And follow Ericsson Software for all the latest developments! All feedback and questions most welcome Warmest wishes, Sally #OSSBSSSummit2024 #Ad #Telecoms #5G #AI #GenAI Mila Violet Dr. Marcell Vollmer #StaySafe #CES2026 #RaviVisvesvarayaSharadaPrasad #Telecom #InfoTech #APISecurity Piggi Sahar Tahvili, Ph.D.| سحر تحویلی #API #Security Brian Ahier Dr. Theophano Mitsa ☦️🇬🇷🇺🇸 Knut Jägersberg #code FAzur #App 💙 #TechForGood 💙 Estrella #Open Baskaran Ambalavanan Marco Cappellari ipfconline Jean-Baptiste Lefevre #Data #Analytics Laurent Alaus Mack Eric T. #DevCommunity Chidambara .ML. #CIO Pinna Pierre - in summer break 😎🤙🏼 Dev Khanna #DataScience Greg Valancius @FrRonconi #OpenAI Siddharth Shah JC Gaillard Lionel Costes #ML

Sen. Sally Eaves

10,573 просмотров • 1 год назад

🎥A Tech in Education Special – Bridging the Digital Divide 💡with T-Mobile Business 💼New! As ‘Back to School’ is front of mind for many across the world, it was an absolute pleasure to spend time with Dr. Kiesha King Dr. Kiesha King Natl Head of Education Strategy, T-Mobile for Education – especially discussing action on areas so close to heart: Bridging the Digital Divide 💡And why does this matter so much? Putting this into context United Nations approved #research finds that today in 2024 2.2 billion – or 2 in 3 children and young people aged 25 years or less – do not have internet access at home - but there is progress happening and there is more we can do – for us this takes an innovation intersection: across #education #telecoms and #tech ! In this special we cover: 🌟Key efforts to bridge the #digitaldivide particularly in rural areas and the role of #Connectivity in modern education. This includes the criticality of collaboration between educators, technology companies and government to build sustainable digital equity programs ✅ 🌟We highlight specific initiatives such as T-Mobile’s $10.7 billion Project 10Million: Providing free internet access to underserved #student households to close the homework gap and the E-rate program which provides discounts to help schools and libraries obtain affordable #Internet access – including School Bus Wi-Fi, Hot-Spot Checkout Programs and Cybersecurity Funding 🌟We also explore the role of emerging technologies, such as #AI and #VR in empowering students and preparing them for the future workforce. The partnership between T-Mobile and Prisms VR is a great example, delivering 5G-enabled interactive #STEM lessons to bridge learning opportunity gaps 🔸 Our conversation concludes on the broader impact of #digital #inclusion including its potential to drive economic growth & #Sustainability All students regardless of their socioeconomic status have access to the digital tools and high quality education imperative for success in the 21st century, and we look forward to sharing more on this critical topic soon. 🗨️ Thanks for Watching! And all feedback welcome 💡To find out more, please explore the link below ↙️ 🖊️Education Report: 🔗 And follow T-Mobile Business for all the latest developments! Warmest wishes, Sally #5G #TFBPartner #education #Diversity ipfconline Knut Jägersberg Elitsa Krumova BusinessIntelligence Brian Ahier #WiFi #GCSEResults Amitav Bhattacharjee Estrella #CyberSecurity JC Gaillard Tony Moroney #DigitalTransformation Shi💙 Hana Dr. Marcell Vollmer #StaySafe #CES2026 Fields Jackson, Jr Xavier Gomez #DEI TAEVision Technology Jean-Baptiste Lefevre Ian Jones #STEAM Baskaran Ambalavanan Dev Khanna Fati Sule Mack Dinis Guarda #IoT Smaksked Skåne AB 🌐 #RaviVisvesvarayaSharadaPrasad #Telecom #InfoTech #mentoring Dr. Khulood Almani | د.خلود المانع corixpartners #GenAI #telco Laurent Alaus Jean CAYEUX @theomitsa #ML

Sen. Sally Eaves

29,874 просмотров • 2 лет назад

🚨🇨🇳China's Underwater Data Centers: Huge Win in the AI Power Race Deep under the South China Sea, China just took a major step toward AI supremacy. 🔸From Navy Tech to Commercial Compute China has launched its first commercial underwater data center off Hainan Island. Sitting 35 meters below the surface, the Hailanxin-built facility connects to shore via submarine cable and already serves AI and big data clients. Hainan Telecom and Atlas are online now. Tencent, Alibaba, and Pinduoduo will join later this year. Each massive 1,300-ton pod uses smart seawater cooling to achieve an impressive PUE of 1.07 — far more efficient than most land-based centers. 🔸Tech Roots That Matter Hailanxin wasn’t starting from scratch. The company once supplied intelligent systems to the Chinese Navy, with deep expertise in marine tech and seabed operations. In 2019, it acquired Canadian deep-sea firm OceanWorks and teamed up with China National Offshore Oil Corporation to build the pressure vessels. This blend of naval know-how and commercial ambition turned Microsoft’s earlier underwater experiment into a working, scalable reality — built for speed and cost advantage in the AI race. 🔸Why This Gives China a Real Edge By placing high-power servers directly in the ocean, China gains natural cooling without expensive infrastructure. The result: cheaper, denser, and more reliable compute capacity exactly when global AI demand is exploding. With plans for 100 pods delivering 50–100 megawatts, Beijing is positioning itself to export low-cost AI processing power worldwide. This underwater strategy strengthens China’s overall tech infrastructure and accelerates its push for leadership in artificial intelligence.

NewRulesGeopolitics

10,686 просмотров • 5 месяцев назад

Billion-Dollar Data Centers Are Taking Over the World | Lauren Goode, WIRED When Sam Altman said one year ago that OpenAI’s Roman Empire is the actual Roman Empire, he wasn’t kidding. In the same way that the Romans gradually amassed an empire of land spanning three continents and one-ninth of the Earth’s circumference, the CEO and his cohort are now dotting the planet with their own latifundia—not agricultural estates, but AI data centers. Tech executives like Altman, Nvidia CEO Jensen Huang, Microsoft CEO Satya Nadella, and Oracle cofounder Larry Ellison are fully bought in to the idea that the future of the American (and possibly global) economy are these new warehouses stocked with IT infrastructure. But data centers, of course, aren’t actually new. In the earliest days of computing there were giant power-sucking mainframes in climate-controlled rooms, with co-ax cables moving information from the mainframe to a terminal computer. Then the consumer internet boom of the late 1990s spawned a new era of infrastructure. Massive buildings began popping up in the backyard of Washington, DC, with racks and racks of computers that stored and processed data for tech companies. A decade later, “the cloud” became the squishy infrastructure of the internet. Storage got cheaper. Some companies, like Amazon, capitalized on this. Giant data centers continued to proliferate, but instead of a tech company using some combination of on-premise servers and rented data center racks, they offloaded their computing needs to a bunch of virtualized environments. (“What is the cloud?” a perfectly intelligent family member asked me in the mid-2010s, “and why am I paying for 17 different subscriptions to it?”) All the while tech companies were hoovering up petabytes of data, data that people willingly shared online, in enterprise workspaces, and through mobile apps. Firms began finding new ways to mine and structure this “Big Data,” and promised that it would change lives. In many ways, it did. You had to know where this was going. Now the tech industry is in the fever-dream days of generative AI, which requires new levels of computing resources. Big Data is tired; big data centers are here, and wired—for AI. Faster, more efficient chips are needed to power AI data centers, and chipmakers like Nvidia and AMD have been jumping up and down on the proverbial couch, proclaiming their love for AI. The industry has entered an unprecedented era of capital investments in AI infrastructure, tilting the US into positive GDP territory. These are massive, swirling deals that might as well be cocktail party handshakes, greased with gigawatts and exuberance, while the rest of us try to track real contracts and dollars. OpenAI, Microsoft, Nvidia, Oracle, and SoftBank have struck some of the biggest deals. This year an earlier supercomputing project between OpenAI and Microsoft, called Stargate, became the vehicle for a massive AI infrastructure project in the US. (President Donald Trump called it the largest AI infrastructure project in history, because of course he did, but that may not have been hyperbolic.) Altman, Ellison, and SoftBank CEO Masayoshi Son were all in on the deal, pledging $100 billion to start, with plans to invest up to $500 billion into Stargate in the coming years. Nvidia GPUs would be deployed. Later, in July, OpenAI and Oracle announced an additional Stargate partnership—SoftBank curiously absent—measured in gigawatts of capacity (4.5) and expected job creation (around 100,000). Microsoft, Amazon, and Meta have also shared plans for multibillion-dollar data projects. Microsoft said at the start of 2025 that it was on track to invest “approximately $80 billion to build out AI-enabled data centers to train AI models and deploy AI and cloud-based applications around the world.” Then, in September, Nvidia said it would invest up to $100 billion in OpenAI, provided that OpenAI made good on a deal to use up to 10 gigawatts of Nvidia’s systems for OpenAI’s infrastructure plans, which means essentially that OpenAI has to pay Nvidia in order to get paid by Nvidia. The following month AMD said it would give OpenAI as much as 10 percent of the chip company if OpenAI purchased and deployed up to 6 gigawatts of AMD GPUs between now and 2030. It’s the circular nature of these investments that have the general public, and bearish analysts, wondering if we’re headed for an AI bubble burst. What’s clear is that the near-term downstream effects of these data center build-outs are real. The energy, resource, and labor demands of AI infrastructure are enormous. By some estimates, worldwide AI energy demand is set to surpass demand from bitcoin mining by the end of this year, WIRED has reported. The processors in data centers run hot and need to be cooled, so big tech companies are pulling from municipal water supplies to make that happen—and aren’t always disclosing how much water they’re using. Local wells are running dry or seem unsafe to drink from. Residents who live near data center construction sites are noting that traffic delays, and in some cases car crashes, are increasing. One corner of Richland Parish, Louisiana, home of Meta’s $27 billion Hyperion data center, has seen a 600 percent spike in vehicle crashes this year. Major proponents of AI seem to suggest that all of this will be worth it. Few top tech executives will publicly entertain the notion that this might be an overshoot, either ecologically or economically. “Emphatically … no,” Lisa Su, the chief executive of AMD, said earlier this month when asked if the AI froth has runneth over. Su, like other execs, cited overwhelming demand for AI as justification for these enormous capital expenditures. Demand from whom? Harder to pin down. In their mind, it’s everyone. All of us. The 800 million people who use ChatGPT on a weekly basis. The evolution from those 1990s data centers to the 2000s era of cloud computing to new AI data centers wasn’t just one continuum. The world has concurrently moved from the tiny internet to the big internet to the AI internet, and realistically speaking, there’s no going back. Generative AI is out of the bottle. The Sams and Jensens and Larrys and Lisas of the world aren’t wrong about this. It doesn’t mean they aren’t wrong about the math, though. About their economic predictions. Or their ideas about AI-powered productivity and the labor market. Or the availability of natural and material resources for these data centers. Or who will come once they build them. Or the timing of it all. Even Rome eventually collapsed.

Owen Gregorian

55,427 просмотров • 9 месяцев назад

🚨$OSS is not an AI company. → It is the hardware that lets AI exist where the cloud cannot. Most investors don’t understand $OSS because they think AI = software. $OSS builds the physical “brains” that run AI in extreme environments where cloud computing fails. Jets. Ships. Tanks. Drones. Space. Hospitals. That’s the game. 1) What $OSS actually is $OSS (One Stop Systems) designs rugged high-performance computers and storage systems for AI at the edge. Meaning: They bring data-center-level computing power into harsh environments. Their products include rugged servers, GPU accelerators, storage arrays, and expansion systems used for AI, sensor processing, and autonomous systems. In simple terms: Cloud AI = brain in a safe building. $OSS AI = brain inside machines operating in chaos. 2) Why this is crucial Most AI today runs in data centers. But the future of AI is not in the cloud. It’s on: • autonomous vehicles • military systems • drones • ships • industrial machines • medical devices These systems cannot wait for the cloud. Latency, connectivity, security, and survival demand local AI. $OSS delivers “data-center performance at the edge” across land, sea, and air. Without companies like OSS, autonomous systems simply don’t work. 3) What OSS actually does: Think of OSS as building AI engines that survive reality. 🌊 SEA example: naval surveillance aircraft and ships. $OSS supplies rugged storage and compute systems for U.S. Navy reconnaissance aircraft to collect and process massive sensor data in real time. Translation: Instead of sending raw data back to base, the aircraft analyzes threats instantly onboard. $OSS = the onboard AI brain. 🪖 LAND example: military vehicles and tactical operations. $OSS delivers high-performance servers and FPGA systems for mobile military intelligence platforms used by the U.S. Department of Defense. Translation: Tanks and vehicles detect threats, process sensor data, and make decisions locally. $OSS = the battlefield computer. ✈️ AIR example: airborne AI. $OSS builds GPU-accelerated servers designed for aircraft, described as a “datacenter in the sky.” Translation: Jets and drones run AI models mid-flight. $OSS = flying supercomputers. 🚀 SPACE example: $OSS hardware is designed for extreme environments and autonomous systems across aerospace and defense. Translation: Future satellites, space drones, and autonomous spacecraft need onboard AI. $OSS = the computing core of autonomous space systems. BONUS: CIVILIAN & COMMERCIAL $OSS systems are used in: • autonomous trucking and farming • industrial automation • healthcare imaging • energy and mining • telecom and 5G Example:A medical imaging company uses $OSS hardware to run real-time AI diagnostics in next-gen breast cancer scanners. $OSS = AI where milliseconds matter. 4) Who their customers are (pattern, not names) $OSS sells to: • defense primes • government programs • industrial OEMs • AI infrastructure companies • medical device manufacturers These customers share one trait: They cannot rely on the cloud. That’s why $OSS exists. 5) The mental model that makes $OSS obvious $NVDA = AI chips $PLTR = AI software $OSS = AI hardware in the real world If AI is electricity, $OSS builds the generators that work in storms. Most investors understand AI software. Few understand AI infrastructure at the edge. That gap is the opportunity. 6) The real thesis The world is moving toward: • autonomous warfare • autonomous vehicles • real-time AI systems • distributed intelligence All of that requires rugged edge computing. $OSS is positioned exactly there. Infrastructure. The hardest layer to build. And often the most valuable.

Black Panther Capital

30,138 просмотров • 8 месяцев назад

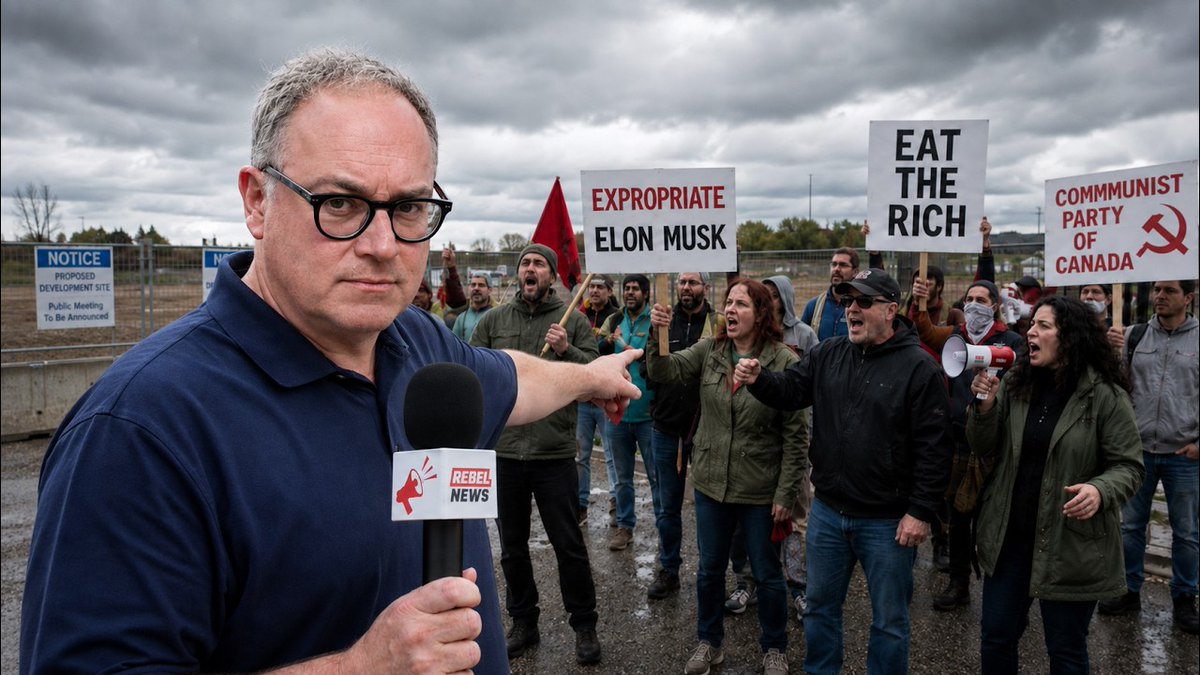
What I saw at Alberta's anti-AI protest A $13 billion investment from Meta, the parent company of Facebook and Instagram, will see a new data centre built near Edmonton. But not all Albertans are on board with the development, and Rebel News heard from protesters opposed to the project. I went to a protest against an Alberta data centre the other day. It was a Sunday, in a small town, and 200 people showed up. That’s a lot. And unlike most protests I go to, where the protesters have no clue what they’re protesting about, everyone here had a lot to say. Even stranger, they didn’t try to block Rebel News. And the strangest thing was, one of the protesters was a die-hard Rebel News fan. So, are these protesters right? Are data centres something we should fear? The demand for computer processing is so huge these days — think of streaming a Netflix show or making a Zoom call — that the computing power doesn’t come from your laptop or your phone anymore. It comes from buildings stuffed with computers, called data centres. And as artificial intelligence becomes more commonplace, the need for data centres is going to grow. There’s a bit of a race between China and America on AI, and that’s fuelling some of the fevered growth, too. And to me, that’s an important point, and one that I put to a number of the anti-AI protesters: AI isn’t going away. The question is, do you want AI controlled by Communist China, or do you want it controlled by America? Which is more likely to respect privacy and freedom? That was the real fear of the people I spoke with. Their objections to the big $13 billion data centre being built in northern Alberta wasn’t really about its proposed water use (it will use less than a golf course) or it’s power use (it’s actually building its own $4 billion power plant). It’s about AI itself. AI is something to worry about, and to make sure that it’s done right. No doubt it will change many things in our lives. But protesting a computer factory in Alberta isn’t going to change the answers to that — all it might do is push some construction jobs down to Texas, or China itself. Watch the full video I did with Sheila Gunn Reid in Morinville, Alberta. I did my best to let the protesters have their say. I wasn’t surprised that there were climate activists there, but I thought it was weird that the Revolutionary Communist Party was out in such force. I should tell you, I just finished doing a lengthy interview with Nate Glubish, the Alberta cabinet minister in charge of data centres. I actually went up to the construction site of the big new data centre to interview him on location. I’ll have that video for you later this week. What do you think? Is opposition to this data centre just a front for opposing AI itself? And if so, isn’t AI just like the Space Race — it’s a race between us and China, whether or not we like it?

Rebel News

12,809 просмотров • 1 месяц назад

Groq is serving the fastest responses I've ever seen. We're talking almost 500 T/s! I did some research on how they're able to do it. Turns out they developed their own hardware that utilize LPUs instead of GPUs. Here's the skinny: Groq created a novel processing unit known as the Tensor Streaming Processor (TSP) which they categorize as a Linear Processor Unit (LPU). Unlike traditional GPUs that are parallel processors with hundreds of cores designed for graphics rendering, LPUs are architected to deliver deterministic performance for AI computations. The LPU's architecture is a departure from the SIMD (Single Instruction, Multiple Data) model used by GPUs and favor a more streamlined approach that eliminate the need for complex scheduling hardware. This design allows every clock cycle to be utilized effectively, ensuring consistent latency and throughput. For developers, this means that performance can be precisely predicted and optimized which is critical in real-time AI applications. Energy efficiency is another area where LPUs shine. By reducing the overhead of managing multiple threads and avoiding the underutilization of cores, LPUs can deliver more computations per watt. Groq's innovative chip design allows multiple TSPs to be linked together without the traditional bottlenecks found in GPU clusters making them extremely scalable. This enables linear scaling of performance as more LPUs are added simplifying the hardware requirements for large-scale AI models and making it easier for developers to scale their applications without rearchitecting their systems. So what does this all mean? LPUs could provide a massive improvement compared to GPUs for serving AI applications in the future! If anything it will be great to have alternative high performing hardware since A100s and H100s are so in demand

Jay Scambler

318,454 просмотров • 2 лет назад

Introducing Sharpe Search: On-Chain Search AI Agent Powered by Hive Intelligence We’re thrilled to announce the launch of Sharpe Search, a crypto search AI agent powered by Hive Intelligence Designed to simplify blockchain data interaction, Sharpe Search represents a significant step toward making crypto more accessible and actionable for users at every level. Sharpe Search leverages Hive Intelligence’s advanced search API to provide real-time, actionable insights across the blockchain ecosystem. Here’s a detailed look at what Sharpe Search is, how it works: What Is Sharpe Search? At its core, Sharpe Search is an AI agent purpose-built for querying and analyzing on-chain data. It takes the complexity out of blockchain exploration by enabling users to ask questions in plain language and receive detailed, accurate responses. Whether you’re looking to monitor wallet activity, track portfolio positions, or analyze transaction history, Sharpe Search ensures that the answers are at your fingertips—accurate, comprehensive, and delivered instantly. How Does Sharpe Search Work? Sharpe Search is powered by Hive Intelligence, a search engine API designed to make blockchain data easily accessible and AI-ready. Here’s a breakdown of how it enables Sharpe Search to function effectively: 1. LLM-Optimized Query Processing Sharpe Search leverages Hive Intelligence's optimized responses for large language models. This ensures that AI agents can process blockchain data in a structured format, delivering precise answers to complex user queries. 2. Natural Language Interaction Forget the need for technical knowledge. Sharpe Search supports natural language queries, making it as simple as typing: - “What tokens are in my wallet? Am I eligible for any airdrop I haven't claimed yet?” - “Check me my last 100 transactions, tell me if I interacted with any protocol with recent hacks” - “Track my wallet activity over the past month, suggest optimised portfolio based on best stable yields available” 3. Real-Time Insights Across Multi-Chains Using Hive Intelligence, Sharpe Search connects to over 20 chains and 5000+ Protocols. This real-time access ensures that the AI agent provides up-to-date and actionable insights, no matter how dynamic the blockchain environment. 4. Unified API Access Sharpe Search consolidates fragmented blockchain data through Hive’s unified API. Instead of dealing with multiple integrations, Sharpe Search uses a single access point to aggregate and query data, reducing complexity for both users and developers. Technical Depth: The AI Agent Advantage Sharpe Search's design philosophy revolves around the principle of creating an intuitive, AI-driven experience. Here’s what makes its technology stand out: Data Indexing and Aggregation: Hive Intelligence employs advanced indexing algorithms to aggregate data from multiple chains. This ensures that Sharpe Search can retrieve information within milliseconds, even when querying vast datasets. Dynamic Updates: Blockchain data is volatile. Sharpe Search processes dynamic updates in real time, enabling users to act on the most recent metrics, transactions, and balances without delays. Contextual Understanding: The AI agent parses natural language queries and contextualizes them to blockchain-specific scenarios. For instance, when querying “Show portfolio details,” Sharpe Search understands the underlying requirements—fetching wallet holdings, token values, and current positions. Hive Intelligence: The Backbone of Sharpe Search While Sharpe Search takes center stage, Hive Intelligence provides the critical infrastructure to make it all possible. Its LLM-ready responses and multi-chain support ensure that Sharpe Search operates at the forefront of blockchain data accessibility. By launching Hive Intelligence through Sharpe Launchpad, Sharpe reinforces its commitment to supporting innovation in the blockchain space. Hive’s infrastructure not only powers Sharpe Search but also lays the groundwork for future AI agents to thrive in the ecosystem. What’s Next for Sharpe Search? Currently in invite-only access, Sharpe Search is preparing for a broader public release. Future updates will include: - Expanded Blockchain Coverage: More chains and protocols will be added. - Enhanced Query Flexibility: Even more advanced natural language capabilities. Stay tuned for the public launch and get ready to explore crypto like never before!

Sharpe AI

263,308 просмотров • 1 год назад

Sundial has raised $23M to build the analytics platform for the AI era! Our work is personal to me (though many have asked: Why? Aren't you into intuition and taste and experience which is ultimately unmeasurable?) But hear me out: I love building, and I have a deep respect for it. Making something people love is one of the hardest and most humbling endeavors. The art comes down to making high-quality decisions, which comes from an obsession with the cliff’s edge between customer understanding and product capability. You need to know what’s working and what isn’t. That’s why data matters. Data is *information* about how reality works. At Sundial, we live by the mantra: diagnose with data; treat with design. What does masterful decision-making look like? It comes down to 3 things: 1. extreme alignment 2. shared curiosity to unpeel deeper and deeper layers of truth 3. urgent execution The very fact is that good intuition and taste comes from data internalized across many, many reps. Yes, reality is infinitely more complex than what can be measured. But measuring gives us a better grasp of reality. Alas, using data well is like learning a new language. It requires years of skill and context building. It's easy to misuse, whether misguidedly or intentionally. I know this all too well. Mastery requires everything from how to break down an ambiguous question, to fluently reading triangle charts and dense tables, to remembering the specific name of a specific column using a specific dialect of SQL. Too many people, like me, regularly feel frustrated by a) how long it takes to get answers b) how to draw the right interpretations c) how much noise I have to wade through to find actually actionable insights. Instead of greater confidence and quality, we get conflicting signals, cherry-picked facts, and analysis paralysis. Sundial is our attempt to solve those problems. We’re bottling up opinionated intelligence to guide decision-makers towards faster and more confident decisions. We envision a world where *everyone* can be their own expert analyst. Sundial uses AI and expert analytical techniques to make insights accessible to every decision-maker. Exemplary analysis takes the listener through a story. Data should speak the language of business, not the other way around. Sundial is also smart in the ways you’d expect of an AI-native tool. It’s not just about looking up data (“What’s India ARR last month?”), which has become table stakes; rather, Sundial can also tackle deep, complex analysis (”Why did ARR decline? What are my levers?”). In a crowded landscape of fragmented data tools—dashboards, notebooks, ETL systems—Sundial brings it all together into one intuitive platform. We believe this era of AI will see teams doing far more with less, and moving faster than ever before. Our mission is to build the data brain for the next generation of AI-powered companies. We're thrilled to be backed by dj patil at GPV—the first U.S. Chief Data Scientist and coiner of the term "data scientist”, alongside industry luminaries like Amjad Masad, tobi lutke, Fidji Simo, alex schultz 🏳️‍🌈, Shishir, Ruchi Sanghvi, Avichal Garg - Electric ϟ Capital, Drew Houston, Howie Liu and firms including Sequoia Capital, Tribe Capital, Sunflower Capital, Unusual Ventures. The best part of building Sundial is the people we get to work with. Funding announcements are nice and all, but what really fuels us is the feedback and growth trajectory of our customers. There’s nothing better than working on interesting problems with people you like. Onward! (P.S. We’re hiring for AI engineers, data engineers, and data scientists in the Bay Area -- DM me if you resonate with our mission, love dissecting big problems down into smaller ones, and appreciate the consistent practice of craft.)

Julie Zhuo

129,299 просмотров • 1 год назад

NOBODY wants to send their data to Google or OpenAI. Yet here we are, shipping proprietary code, customer information, and sensitive business logic to closed-source APIs we don't control. While everyone's chasing the latest closed-source releases, open-source models are quietly becoming the practical choice for many production systems. Here's what everyone is missing: Open-source models are catching up fast, and they bring something the big labs can't: privacy, speed, and control. I built a playground to test this myself. Used CometML's Opik to evaluate models on real code generation tasks - testing correctness, readability, and best practices against actual GitHub repos. Here's what surprised me: OSS models like MiniMax-M2, Kimi k2 performed on par with the likes of Gemini 3 and Claude Sonnet 4.5 on most tasks. But practically MiniMax-M2 turns out to be a winner as it's twice as fast and 12x cheaper when you compare it to models like Sonnet 4.5. Well, this isn't just about saving money. When your model is smaller and faster, you can deploy it in places closed-source APIs can't reach: ↳ Real-time applications that need sub-second responses ↳ Edge devices where latency kills user experience ↳ On-premise systems where data never leaves your infrastructure MiniMax-M2 runs with only 10B activated parameters. That efficiency means lower latency, higher throughput, and the ability to handle interactive agents without breaking the bank. The intelligence-to-cost ratio here changes what's possible. You're not choosing between quality and affordability anymore. You're not sacrificing privacy for performance. The gap is closing, and in many cases, it's already closed. If you're building anything that needs to be fast, private, or deployed at scale, it's worth taking a look at what's now available. MiniMax-M2 is 100% open-source, free for developers right now. I have shared the link to their GitHub repo in the next tweet. You will also find the code for the playground and evaluations I've done.

Akshay 🚀

50,323 просмотров • 10 месяцев назад

In this post I will explain why people become borderline religious when they discover Qubic. Now with video. Please repost. I want people to learn about QUBIC. The ecosystem consists of 3 separate universes: AI, Mining, and Tickchain. AI is the primary product and purpose of QUBIC and it is supported by Mining to train the AI and by Tickchin for validation and decentralization. Here is how this whole thing works: AI: Let’s start with the AI. The main purpose of QUBIC is creating AGI (Artificial General Intelligence). It’s a type of AI that can self-develop, set tasks, grow, and learn on its own—much like the human brain does. This product is called AIGarth and it uses many cool ideas where AIs can create their own agents and have them compete against one another to evolve. It is basically robots creating robots with the survival-of-the-fittest evolution approach. Very impressive and thought out. To develop such an AI there are several requirements that even the industry giants like OpenAI, Microsoft, and Tesla are missing. One of them is the data processing for AI training. I mean they have their Datacenters, but those are only good enough to train limited Large Language Models such as ChatGPT and Grok. Mining / Training: Now QUBIC solves this problem with its mining architecture. Keep in mind, mining in QUBIC does not secure the chain, primarily it provides the processing power for training the AI. In a sense, QUBIC mining creates the largest distributed datacenter in the world, where individual miners provide their computers for training the AI and get paid with newly issued QUBIC coins. This way QUBIC gets constantly increasing processing power without having to really pay for the infrastructure. And here is another impressive bit of info. QUBIC’s distributed mining network currently ranks above the #1 supercomputer in the world - El Capitan. QUBIC Tickchain The QUBIC chain ties its AI and Mining together to create decentralization, the reward system for miners, it acts as a decision voting system for future development, and it allows AIGarth to function independently through Smart Contracts. In this summary I will not go over the specifics of QUBIC Tickchain. It’s pretty complex so it will be a separate post. Now, it’s an absolute genius piece of tech, which I consider the most advanced product within crypto industry. It is important to know that QUBIC chain runs directly out of Random Access Memory of its validators. It has instant finality and acts as its own operating system. That allows for speeds only bound by current hardware capabilities and it only increases as technology progresses. As I am writing this, QUBIC Tickchain is fully functional and it already hosts several smart-contract based web3 applications. QUBIC has designed its chain to be this fast for a single purpose, to give its future AI the speed it needs to evolve and to react quickly to the outside world. Ilya Shutskever the scientist, who developed ChatGPT clearly states that next generation superintelligence will make decisions in split second with less data. I believe QUBIC is that next generation. Why QUBIC? So out of the sea of AI projects in crypto why is QUBIC my #1 pick? Well, the first reason is that QUBIC is a unicorn AI startup that happens to use blockchain tech to reach it’s goals. In the real world of Venture Capital it would be fully funded instantly and you would not be invited. Second reason is that the industry admits that Large Language Models have plateaued. Even with enough processing power there is only so much information they can add to their data. Even Google CEO admits that. New approach is needed because the future progress is not possible with LLMs. The third reason is because Large Language Models will not create true AGI. It is evident by Ilya Shutskver latest presentation. Sam Altman of OpenAI is trying to change the definition of what is considered AGI just to lower the plank for his own product. Microsoft’s AI chief is now claiming that it would take 10 years to reach AGI, while QUBIC aims to do this in 2027. All these big players are using wrong technology for what they are trying to achieve and there isn’t enough investor funding for them to pivot. The fourth reason is that QUBIC is headed by Sergey Ivancheglo and 2 renowned AI scientists. Many claim Segey is the creator of Bitcoin. He was the 3rd person to mine bitcoin, he invented Proof of Stake consensus, which Ethereum uses now, he ran the first ICO, and he created 2 of the top gainers in crypto NXT and IOTA. QUBIC is his grand finale after 12 years of development and trials. I am including links below the post as the proof of my claims. Thank you for your time. Please live a like or a comment. It helps me continue making these extensive posts and videos.

retrodrive ⛏

24,757 просмотров • 1 год назад

The latest RAG trend for the current agent harnesses (Codex, Cowork) is to do two passes of document processing to solve a knowledge work task over a data room of documents: 1️⃣ A fast and light pass, oftentimes using a free/OSS doc parsing tool. This can be cheaply run across 10-100-1k’s of files, and enables the agent to then do retrieval (e.g. grep, semantic) to find relevant subsets of context. 2️⃣ A “just-in-time” VLM-based pass. Once the agent finds the relevant pages of context, it will screenshot the documents can call its own VLM (or write code) to dissect the pages. The issue with only using VLM-based OCR tools over massive ad-hoc customer file dumps is that it’s slow and expensive. Doing JIT VLM OCR allows the agent to filter through the data cheaply, but still preserve accuracy for the context that’s needed for the task. The agent harnesses do two-pass document processing by default using off the shelf-tools: pdf2text as the first pass, and using itself (Opus 5) as the second pass. See the below video where Cowork runs over a bunch of PDFs to answer a question about a benchmark graph in the Kimi k3 paper. The main issues here with the “out of the box” doc processing these agents offer are: * Opus 5 is not the best VLM for OCR. It is also way too expensive at scale and lacks grounding * The OSS tools like pypdf, pdf2text, may not be versatile enough as the first pass. * The agent will write a lot of throwaway code to rewrite things an OCR tool would’ve provided out of the box, like chart processing, bounding boxes, confidence scores, leading to increased cost and speed. We have all the tools within LlamaIndex 🦙 to help any agent do two-pass document processing with higher accuracy and lower cost. 1️⃣ We have liteparse for the first pass - a free/OSS parser written in Rust that’s faster/more accurate than other OSS parsers, and supports 50+ document types 2️⃣ We have LlamaParse for the second pass - an agentic document engine that uses VLMs+harnesses to achieve SOTA in accuracy and cost across various doc parsing and extraction tasks. It can be called from any agent harness as an MCP or skill. It takes in page numbers as input, so that the agent can choose to run LlamaParse over a subset of the doc instead of the full doc as a “zoom-in” pass. Come check it out! LiteParse: LlamaParse: All the relevant docs, including MCP, are here:

Jerry Liu

22,763 просмотров • 1 месяц назад

In 2016, Marvell's largest design win was a Wi-Fi chip in the Barbie Dream House (Save this). That is a documented fact about one of the most remarkable corporate transformations in semiconductor history. Ten years and $36 billion in acquisitions later, Marvell is now the company that Jensen Huang invites onto the COMPUTEX stage, the same stage where he announced a $2 billion strategic investment into the company. Over 75% of Marvell's revenue today comes from data centers. To understand what Marvell actually is now, you need to understand what Matt Murphy did when he walked in as CEO in 2016. The company had stagnant growth, governance scandals, and a business model built around chips for hard drives, printers, and consumer electronics, exactly the wrong place to be as the cloud era was beginning. Murphy made a ruthless decision to kill every low margin consumer business and go all in on data infrastructure. Then he went shopping. 2018 - Acquired Cavium for $6 billion, bringing ARM-based network processors and the foundation for cloud infrastructure compute. 2019 - Acquired Avera Semiconductor, formerly IBM's custom silicon team, which gave Marvell the ability to design bespoke ASICs for hyperscalers. This is what opened the door to Amazon, Microsoft, and Google design wins. 2021 - Acquired Inphi for $8.2 billion, securing leadership in high-speed optical interconnect, the technology that moves data between and within data centers at the speed of light. 2021 - Acquired Innovium, adding cloud-optimized Ethernet switching to the portfolio. 2025/2026 - Acquired Celestial AI for $3.25 billion, bringing photonic fabric technology that places optical connections directly inside the chip package itself. Each acquisition followed the same formula, buy the technology that will be absolutely essential in the next generation of computing before anyone else is paying attention. Now here's the vision Murphy laid out at COMPUTEX 2026, and why it's the most important thing he's ever said publicly. He made one central argument, AI scaling is no longer limited by compute or memory but rather limited by connectivity. Training a frontier model requires tens of thousands and eventually millions of processors working as a single engine and making that happen is a connectivity problem above all else. Today, data centers are constrained by copper. Copper traces connecting chips inside a server can only move data so far, so fast, before bandwidth collapses and latency rises, that's why today's AI servers have to bundle everything, CPUs, GPUs, memory onto the same physical board sitting centimeters apart. When you replace copper with optics, distance disappears entirely. An optically connected server rack can communicate with another rack in a different building at the same bandwidth and latency as if they were the same machine. Memory can sit in one physical location, compute in another, networking in a third and a software orchestration layer composes the exact ratio the workload needs, on the fly, in real time. Murphy called this a data center without distance, a globally optically interconnected infrastructure where the rigid physical boundaries of today's servers begin to disappear entirely, and data centers function as one unified system. That is not a 10 year vision because Marvell's CPO (co-packaged optics) products are sampling in 2027 with volume shipments beginning 2028. Nvidia's Vera Rubin platform has already adopted Spectrum-X Ethernet Photonics, the first CPO switch in commercial production. The reason this makes Marvell's TAM almost impossible to cap is the following. Right now, Marvell's addressable market is the optical interconnect market, a segment projected to be worth $200 billion per year by end of decade. But if the data center without distance architecture actually materializes and the evidence suggests it will, then Marvell's TAM is not just the optical interconnect market but rather every connection in every data center on earth. Bullish on Marvel! Come join Milk Road Pro for just a $1, If you want the full Marvell breakdown on where it sits in our AI infrastructure portfolio, and our entire AI thesis. Link below!

Milk Road AI

21,550 просмотров • 3 месяцев назад

Ahmedabad Crime Branch is making use of technical measures to avoid any stampede kind of situation. Anti stampede visual analytics,using reference area and crowd movement, head count algorithm. Anti-stampede algorithms on CCTV cameras are a crucial advancement in crowd management, leveraging AI and image processing to prevent dangerous situations in densely populated areas. Here's a breakdown of their usage: How they work: Real-time monitoring: AI-powered CCTV cameras continuously analyze video streams in real-time. Crowd density estimation: Algorithms calculate the number of people in a given area. This can involve: Pixel-based analysis: Converting images to black and white and counting "black pixels" (representing people). Object detection: Using machine learning models (like Mask R-CNN) to identify and count individuals, often by detecting heads or torsos. Thresholding: Pre-defined "threshold values" for crowd density are established. When the detected density crosses these thresholds, it triggers an alert. Anomaly detection: Beyond just density, these algorithms can identify unusual crowd behaviors such as: * Sudden surges in movement. * Unusual clustering patterns. * Fallen individuals. * Aggressive movements. Alerting authorities: Upon detecting a potential stampede risk, the system sends immediate alerts to security personnel or control rooms via LCD displays, GSM messages, or other communication channels. Predictive analytics: Some advanced systems use time-series prediction models to forecast crowd behavior and dynamics based on historical and real-time data, helping anticipate potential bottlenecks or overcrowding. Reinforcement learning: Algorithms can learn from past incidents to suggest optimal crowd flow routes and alternative evacuation paths during emergencies. Benefits: Proactive prevention: The primary benefit is the ability to detect and warn of potential stampedes before they occur, allowing authorities to take preventative measures. Real-time insights: Provides immediate and accurate data on crowd density and movement, far surpassing manual observation. Enhanced safety: Significantly improves safety in public spaces by reducing human error and enabling swift responses to risks. Optimized resource allocation: Helps in better deployment of security personnel and resources to areas with high crowd density. Improved efficiency: Automates a labor-intensive task, freeing up human operators for more complex decision-making. Data for future planning: The collected data can be analyzed to improve crowd management strategies for future events. Challenges: Accuracy limitations: While advanced, AI algorithms can still face challenges with: Occlusion: People blocking each other, making accurate counting difficult. Varying conditions: Changes in lighting, weather, and camera angles can affect accuracy. Bias in training data: Can lead to false positives or inaccurate detections. Computational complexity and cost: Developing and deploying such systems can be expensive due to the need for high-resolution cameras, powerful processing units, and sophisticated algorithms. Data privacy and ethical concerns: The extensive use of CCTV and AI raises concerns about individual privacy and potential misuse of data. Integration with existing infrastructure: Integrating new AI-powered systems with older CCTV networks can be complex. Human intervention still crucial: While AI can alert, human responders are still essential for effective intervention and crowd dispersal. As seen in the Kumbh Mela example, even with AI alerts, a lack of ground personnel can limit effectiveness. Defining thresholds: Determining appropriate crowd density thresholds for different environments and cultural contexts can be challenging. Real-world applications: Large public gatherings: Religious festivals (like the Kumbh Mela in India, which has used AI for crowd management), concerts, sports events, and political rallies. Transportation hubs: Railway stations, airports, and bus terminals to manage passenger flow. Shopping malls and commercial centers: To monitor crowd density during peak hours and special events. Stadiums and arenas: For managing ingress, egress, and crowd movement during events. Tourist attractions: To prevent overcrowding at popular sites. Overall, anti-stampede algorithms on CCTV cameras represent a significant leap forward in ensuring public safety, offering a powerful tool for proactive crowd management. However, their successful implementation requires careful consideration of technological limitations, ethical implications, and the continued need for effective human intervention. Ahmedabad Police અમદાવાદ પોલીસ Vijay Patel | Megh Updates 🚨™ | Akash Anand | | #BengaluruStampede | #Stampede

Janak Dave

339,758 просмотров • 1 год назад

What’s Left Before InterPredict Mainnet? 🟣🚀 InterPredict is getting closer to Mainnet but we are not rushing the process. ⏳ A successful Mainnet launch is about more than reaching a date on the calendar. It is about ensuring that the protocol, infrastructure and user experience are ready to operate reliably in a production environment. 🏗️🔐 Several important technical milestones have already been completed, while the remaining work is focused on integration, refinement and final preparation. 🛠️✅ ✅ Completed Milestones 1. Smart Contract Development and Testing 📜🔍 The smart contracts have been developed and tested, establishing the core on-chain foundation of the InterPredict protocol. This work is essential for ensuring that the protocol’s key functions operate as intended and can support the next stage of development. ⚙️⛓️ 2. Backend Deployment 🖥️🚀 The new backend infrastructure has been successfully deployed and is now running in a production environment. This provides the services required to support the platform and enables the frontend to communicate with the systems powering InterPredict. 🔗📡 3. Transaction and Activity Tracking 📊👀 Users can now clearly view the results of their interactions and monitor relevant activity within the platform. Improved visibility helps users better understand their transactions, actions and participation across the platform. ✅📈 4. Reliable Market Indexing 🗂️⛓️ Blockchain activity is being indexed consistently and reflected accurately within the application. Reliable indexing is important because it ensures that on-chain events, market updates and other protocol activity are displayed correctly for users. 🔄📍 5. Faster Data Synchronisation ⚡📡 The platform’s data synchronisation has been improved so that market states, votes, activities and other protocol information can be reflected in the dApp more quickly. Faster synchronisation creates a smoother and more responsive experience between blockchain activity and the information displayed in the application. 🚀📱 ⏳ Currently in Progress 1. Frontend and Backend Integration 🔌🖥️ The new frontend experience is being connected to the backend services so that both layers work together smoothly and reliably. This stage ensures that user actions, platform data and backend processes are properly connected across the entire application. 🔗✅ 2. User Experience Improvements 🎨📱 The Closed Beta provided valuable feedback and highlighted areas where the platform can become easier and more intuitive to use. The team is continuing to improve: • Navigation 🧭 • Mobile usability 📱 • Loading states ⏳ • Error handling ⚠️ • Market interaction flows 📊 • Overall platform usability ✅ These improvements are designed to make InterPredict clearer, faster and more accessible for both new and existing users. 🙌 3. Security and Reliability 🔐🛡️ The infrastructure and protocol are being reviewed and strengthened to ensure they are prepared for production use. This includes improving system stability, reviewing critical components and making sure the platform can operate reliably as activity and user participation increase. 🏗️📈 Security and reliability are not final checks to be rushed. They are essential parts of building a platform users can trust. 🤝 4. Mainnet Readiness 🚦🚀 The final stage is bringing all the moving parts together and testing the complete system as one connected platform. This includes the: → Smart contracts 📜 → Backend infrastructure 🖥️ → Frontend experience 🎨 → Market indexing 🗂️ → Data synchronisation 🔄 → Transaction tracking 📊 → Security systems 🔐 Each component must work correctly on its own and together with every other part of the protocol. ⚙️✅ Building for the Long Term 🏗️🌍 Mainnet is not simply a launch date. It is a major milestone that represents the beginning of the next phase for InterPredict. 🟣 The goal is not to launch as quickly as possible. The goal is to launch with a strong foundation that gives the team confidence to continue building, improving and scaling the platform after launch. 🚀📈 The Closed Beta showed us where improvements were needed. V2 is where those lessons are being applied. 💡🔧 There is still work to complete—but every step brings InterPredict closer to a more reliable, efficient and user-friendly platform. ⏳➡️✅ The Next Big Step 🟣🚀 The main technical foundations are now in place. The remaining focus is on integration, user experience, security, reliability and final Mainnet preparation. 🔐⚙️ We are not rushing to launch. We are making sure InterPredict is ready to launch properly. Stay updated and follow the journey towards Mainnet. 🟣🌐🚀 Follow InterPredict 📣 🔗 Follow InterPredict: InterPredict 📲 Join the Telegram community: InterLink Labs 👤 + 🌐 InterPredict InterLink Foundation KV Reina | InterLink Labs Mira #InterPredict #ITP #InterLink #ITLG #ITL #PredictionMarkets #ITL #ITLG #Web3 #Blockchain #dApp #Mainnet #Tokenomics

Tekkaus® | InterLink Global Leader • MOD • OG

100,095 просмотров • 18 дней назад

Dear ICP community, the Internet Computer has now been running strong for 5 years 👏👏👏 Here is a celebratory preview of ICP "cloud engines," the sovereign frontier cloud technology the network shall soon provide from Main points: — Cloud engines enable anyone to spin up their own sovereign frontier cloud. The technology involves an extraordinary inventive step, in which cloud is created from a mathematically secure network of nodes. The nodes run as part of the Internet Computer network ( but are selected and configured by the cloud engine's owner. — The frontier cloud provided by engines is strongly focused on enabling AI agents to build and update online applications and services for us. The world is changing fast, and nearly all new online apps and services are already being built with the help of AI, and thus cloud engines target the future of cloud. — Software hosted on cloud engines is tamperproof, which means that it is immune to infrastructure hacks, because it runs inside a mathematically secure network protocol, rather than on computers directly. This means that AI agents, and those building with them, don't need to have a security team in the loop, or to trust someone else's security team. This is crucial, because in the future, non technical people will demand the freedom to build with full automation — where they just need to issue instructions to AI about what to build, and don't need to worry about anything or anyone else. Of course, apps and services running on engines are also vastly safer from the new breed of hacker being enabled by frontier AI. (The cloud engines themselves are also "tamperproof." Even if a hacker gains physical access to some portion of a cloud engine's nodes, and can make arbitrary changes, the computations and data of the hosted apps and services cannot be corrupted or interrupted so long as the network's fault bounds aren't exceeded. The recent hack of Vercel, a major cloud platform, which gave hackers access to the apps it hosted, provides additional perspective on the importance of this advantage.) — Software hosted on cloud engines is guaranteed to run, so long as a sufficient number of the engine's nodes are running. This means that AI can build applications and services without the need to have a human systems admin team constantly tinkering with the underlying platform to keep it running, which is again crucial, because in the future, non technical people will expect the freedom to use AI to build without the support of others. — New frontier programming language technology, in the form of the Motoko language developed by Caffeine Labs, leverages seminal "orthogonal persistence" technology that unifies program logic and data to deliver further unlocks for AI (Motoko is the first computer language being developed that targets agents that are writing software rather than humans engineers per se). Nowadays, AI can build and update production apps at a prodigious rate, even at the speed of conversation. But it can also make mistakes, and there's a risk that an update it creates might be "lossy" in the sense it causes some transformed data to be lost. Again, in this new world, it's both undesirable and impractical for everyone to have to have a systems admin team on-hand to detect lossy updates and roll them back, but Motoko provides a solution: it can detect new software updates are lossy before they are applied, reducing potentially catastrophic errors by AI to harmless coding retries. — Software hosted on cloud engines is "serverless" but unlike traditional serverless software, directly it directly incorporates data through "orthogonal persistence." Another key purpose is simplify backend software logic and fuel the modeling power of AI by increasing abstraction (sorry for the technical language!!!). Put simply, this enables AI to produce more sophisticated backends, faster, and at dramatically lower costs, as measured by the number AI API tokens consumed during coding. (Tip for the technical: orthogonal persistence is a new paradigm where "the program is the database," and data lives inside program variables, which is possible because it's as if hosted software runs forever in persistent memory). — An expanding database of skills at shall make it possible to develop and directly deploy apps and services to your cloud engines directly from Claude Code, Perplexity, Codex and other AI platforms. Further, your account on can be connected, so that new apps and updates created through conversation automatically appear hosted from your cloud engine. In the future, R&D is going to be very seamless. You converse with AI, and your secure and unstoppable apps or services are created or updated. Cloud engines are designed to directly support this "self-writing cloud" future where we can work hands-free. — Tech sovereignty is becoming a huge issue worldwide, with governments and corporations seeking to create sovereign tech stacks owing to geopolitical tensions. Increasingly, people are realizing that tech provided by foreign nations can come with hidden backdoors and kills switches, from the base platform, right up through hosted apps and services. ICP technology is open source, and those building on ICP using AI own their own source code. When you have the source code, you can verify that there are no backdoors, and when you own the source code thanks to AI, you can update it at will, freeing you from vendor lock-in. But cloud engines take sovereignty much further... — You create a cloud engine by selecting the nodes that will be combined. You can choose the class of nodes used, and their number, but more importantly, you can choose who operates the nodes, and where they are located. Almost any configuration is possible, because the Internet Computer scales the security privileges afforded to hosted software within the network according to configuration (software hosted on cloud engines can directly interoperate with software on other engines and traditional subnets, but base restrictions are applied according to security rules). A cloud engine can be created within a region such as Europe, to comply with regs such as GDPR, or completely within a sovereign state like Switzerland or Pakistan. But cloud engines go further still... — Sovereignty is also about freedom from vendor lock-in. Cloud engines are essentially ICP (Internet Computer Protocol) network configurations, and this means the underlying compute nodes they combine can be swapped out without interrupting their hosted apps and services. This is a big deal. In addition, cloud engines now support nodes that are instances running on Big Tech's clouds, in addition to nodes that are dedicated specialized hardware, as per the Gen I and Gen II nodes that dominate the Internet Computer today. For example, it is possible to have an engine running across different AWS data centers, say, and then reconfigure the engine to run across a mixture of AWS, Google, Azure and Hetzner for even more resilience, without the users of hosted apps and services noticing a thing. That's true freedom. — Sovereign AI is becoming increasingly important too, and cloud engines allow special "AI nodes" to be added to them, so that hosted software can perform inference on hardware provisioned by the owner from a location the owner has selected. Even though the AI nodes are only accessible within the cloud engine, they can still benefit from the forthcoming Internet Intelligence Gateway (IG), which will make it possible to validate inference performed on key frontier open weights LLMs, even when the inference is performed on completely independent AI clouds. When the results of inference are received, this technology can verify that neither the prompt+context (input) nor the inference result (output) have been modified, and that the results were produced by the precise LLM expected. This ensures that AI clouds don't cheat by running inference on cheaper models than are being paid for, and bad actors aren't modifying the inputs or outputs to surreptitiously insert advertising into results, say, or change facts, or insert malware when code is being generated. What's super cool about this technology is the cost of the verification is scalable. A very valuable additional security can be achieved with only 1-2% of extra cost. — Scaling apps and services when they hit capacity limits is another thorny problem that cloud engines help the world address. Engines make scaling possible without rewriting or reconfiguring software. The query workload capacity of hosted software can be horizontally scaled simply by adding new nodes to an engine, and nodes can also be added in geographical proximity to demand. Meanwhile, update workload capacity can first be scaled-up by swapping an engine's nodes out for the next class up, and then when no larger class of node is available, horizontally scaled-out by "splitting" the engine into two, which doubles available capacity. (Technical tip: horizontally scaling update capacity by splitting engines requires multi-canister architectures). — For those who have been following how Caffeine builds apps that can efficiently store large numbers of files, I should mention that apps built on cloud engines will also support the new ICP Blob Storage cloud network (since cloud engines currently have up to about 3 TB of memory, which apps storing large amounts of files can easily exceed). We are also working on allowing blob storage nodes to be added to cloud engines, to enable sovereign mass blob storage within an engine, similarly to how AI nodes can be added currently. — Lastly, but certainly not least, I should mention that cloud engines are multi-blockchain capable, and ready for digital assets, thanks to the clever math at their core. For example, an e-commerce service built on a cloud engine can securely accept and custody stablecoin payments, or a multi-chain DEX could be hosted. Further, engines can support software autonomy (software orchestrated and controlled by other autonomous software, in a decentralized way) and can themselves be orchestrated by SNS technology, and thus run autonomously too. Today, though, the focus is on *mainstream* cloud. This year, the cloud industry will generate approximately one trillion dollars in revenue. That number is already huge, but is expected to grow to two trillion dollars by 2030. After years of continuous development, which have seen more than $500m spent on R&D, the Internet Computer network is now tacking directly toward this mainstream cloud market with cloud engine technology. In their first version, cloud engines are not meant to be a cloud panacea. For example, currently they are not ideal for working with big data. You should use something like DataBricks for that. Cloud engines are carefully targeted at enabling AI to produce traditional online applications and services, including SaaS, in a safer and more productive way, which represents a new market segment with tremendous potential. Of course, DFINITY will continue to work relentlessly to push forward ICP's capabilities, so expect further developments. It's worth mentioning that this cloud segment isn't just about creating new apps and services using AI, it's also about replacing legacy systems and apps built on super expensive SaaS services. Caffeine Labs is working to produce technology (Caffeine Snorkel) that can study an enterprise's legacy systems and app built on SaaS, create replacement systems and apps, and migrate the data, while supporting key stakeholders through the process over email and chat, with full automation. Thus the legacy systems and SaaS markets shall also be addressed by cloud engines. Zooming out, and reasoning in a more metaphysical way, we believe, as we always have, that there is room for a new kind of cloud created by mathematical networks, that provides seminal advances in the fields of security and resilience, as well as true sovereignty and freedom from lock-in. That this same technology, with the help of additional technologies like orthogonal persistence and Motoko, enables AI to build for us without the need for so much oversight, and to create more backend sophistication while consuming fewer AI API tokens, enables ICP to bring game-changing advances to the world. Cloud engines will work synergistically with the Intelligence Gateway, which will enable apps and services running on engines to seamlessly leverage AI, wherever that AI is running, while providing verifiability at extremely low cost for open weights frontier models. We believe that cloud engines represent an inflection point in the storied history of the Internet Computer project, and I'm very proud to be sharing the details with you on the network's fifth birthday 💪 I'll be back with more news soon!!

dom | icp

324,632 просмотров • 4 месяцев назад