Загрузка видео...

Не удалось загрузить видео

На главную

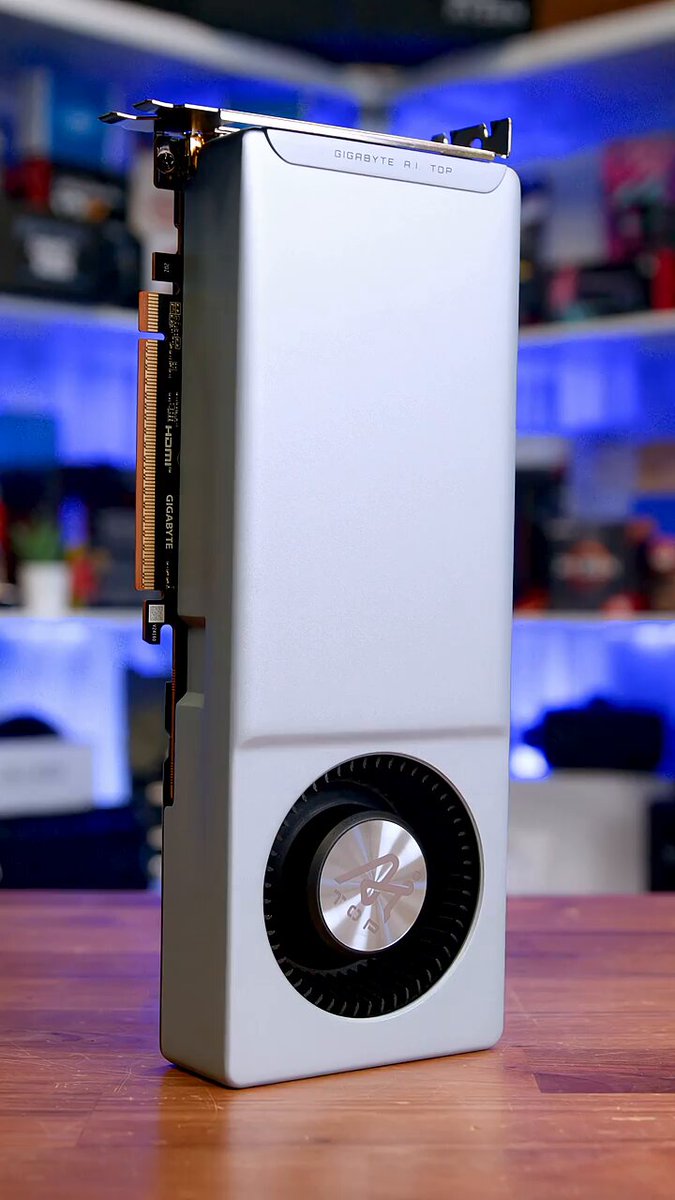
BOLT A GPU ONTO THIS $200 FANLESS BOARD AND IT DOES THE TWO THINGS A RASPBERRY PI PHYSICALLY CAN'T: LOCAL AI AND 4K TRANSCODING. that clip is a zimaboard with a graphics card plugged straight into its pcie slot. that slot is the whole point. a pi has gpio...

24,813 просмотров • 3 месяцев назад •via X (Twitter)

Комментарии: 3

Фото профиля AI Mastery Guide
AI Mastery Guide3 месяцев назад

$200 for that setup is a steal

Фото профиля Briggsll2262
Briggsll22623 месяцев назад

that pcie slot turns it from a tinker toy into something that actually earns its keep

Фото профиля gkrovso
gkrovso3 месяцев назад

wonder how it handles thermals with a gpu

Похожие видео

ANTHROPIC CHARGES $200 A MONTH SO SOMETHING IS ALWAYS AWAKE FOR YOU. THIS FANLESS BOARD DOES THAT AT ROUGHLY 8 WATTS AND WAKES THE EXPENSIVE MACHINE ONLY WHEN A REQUEST ACTUALLY ARRIVES here is the whole shape, always-on to burst: a Zima Board 2, passively cooled in a machined case, silent by design -> dual 2.5 gigabit ethernet, two SATA ports, a PCIe Gen3 slot on the side -> it sits on 24/7 and costs almost nothing to leave running -> it holds the queue, the router and the API endpoint -> when real work lands it wakes the big rig, hands off, and the big rig sleeps again. the expensive part of local AI is not the tokens, it is the idle. a workstation doing nothing still pulls 40 to 120 watts, and that is the number that turned a $1,920 pallet into a $6,000 power bill in the last video. the always-on box and the compute box should not be the same machine. that is the whole idea, and it is five things: separate the front door from the factory -> a fanless 8W board can hold your endpoint, your queue and your web UI forever -> the GPU machine only needs to exist during the seconds it is actually generating idle watts compound, peak watts do not -> 40W of idle for a year is roughly the same money as a few hundred hours of real inference -> nobody measures idle because it never shows up in a benchmark dual 2.5GbE is the feature that makes this work -> one port to your network, one to the compute box, so wake-on-lan and handoff are clean -> this is the difference between a hobby setup and something the rest of the house can actually use the PCIe slot means it can do small jobs itself -> a low power card in that slot handles embeddings, classification and speech to text without waking anything -> route by size: tiny jobs die here, big jobs get escalated passive cooling is a reliability spec -> no fan means no fan failure, which matters for the one machine that is never supposed to go down -> the loud rig can be loud, it is only awake for minutes a day openai and anthropic sell you a warm machine that is always ready. that readiness is real, and it costs them a fortune at scale. at home it costs about 8 watts. my take, and it is the uncomfortable one: most people who priced local AI compared a sleeping subscription to a rig that never sleeps, and the fix is two machines instead of one. read the article below. that's how you stop paying for idle.

Antid

13,140 просмотров • 1 месяц назад

A USED $700 RTX 3090 HAS MORE MEMORY AND FAR MORE SPEED THAN THE ~$1,000 A2 GOING INTO THIS SERVER. THE A2 STILL WINS - FOR ONE REASON THAT ISN'T PERFORMANCE. that clip is a dell poweredge r760 - a 2u rack server - getting an nvidia a2 dropped in through a riser. this is the enterprise route to local ai. the rung the desktop ladder skips entirely. the a2, verified: 16gb of memory, single-slot, low-profile, and just 40 to 60 watts it's an inference card, built to sit in a server that has no room or spare power for a real gpu so why not a 3090? a used rtx 3090 gives you 24gb and many times the compute for around $700. the a2 gives 16gb, much slower, for roughly a thousand. on raw local-llm value, the desktop card wins, and it isn't close. the a2's whole reason to exist is the thing you can't see on a spec sheet: it fits. a 2u server has no spare gpu power and no room for a triple-slot furnace. the a2 slips into one low-profile slot on 60 watts and lets an existing server do inference without a rebuild. the honest caveats: the r760 is not a desk machine. loaded, it idles at hundreds of watts, and its fans sound like a hair dryer that never turns off. it belongs in a rack or a closet 16gb is still 16gb. the same 7b-to-32b ceiling as the cheap cards. the enterprise badge doesn't buy you a bigger model what it does buy: ecc memory, redundant power, remote management, hot-swap everything. reliability, not speed so who this is for: someone who already runs a rack and wants to add private inference without touching the power or cooling budget. for anyone starting from a desk, the mac mini or the 3090 wins on every axis that matters. the real point: the "best" local ai box depends entirely on what you already own. on a desk, efficiency wins. in a rack, fit and reliability win. the a2 isn't a bad card - it's a card for a constraint the ladder never mentions. no fastest gpu here, no desk-friendly box, no bigger model than the cheap cards already run. save this before you buy enterprise gear for a desktop job.

Grimmer

24,287 просмотров • 3 месяцев назад

UC Berkeley just open-sourced FreeToken. (2–4x faster local LLM inference than Ollama) the results are wild: - Qwen3.6-35B on an 8GB GPU at 39.3 tokens/s - DeepSeek-V4-Flash 284B on a 32GB GPU at 22 tokens/s - GLM-5.2 753B on a 96GB GPU at 14.9 tokens/s a 35B model at 16-bit precision needs about 70GB just for its weights. even at 4 bits it is close to 18GB, and FreeToken serves it on an 8GB GPU. let me explain how: all three models mentioned above are Mixture-of-Experts, and that is what FreeToken takes advantage of. each layer holds hundreds of separate experts plus a small router that picks a few of them per token. Qwen3.6-35B activates roughly 3B of its 35B parameters per token. DeepSeek-V4-Flash picks 6 of 256 experts per layer, so 13B of its 284B run at a time. so compute was never the bottleneck. the weights a single step touches fit comfortably on a consumer GPU. every expert the router might pick still has to exist somewhere. they sit in system RAM, and the GPU keeps a cache of the ones the model has been using recently. so everything comes down to what happens when the router picks an expert that is not on the GPU. there are two ways to serve that miss: 1. copy it over PCIe and run it on the GPU 2. run it on the CPU, where it already lives both read from the same system memory, so they compete for one pool of bandwidth instead of adding to each other. existing engines pick one option and freeze it when the model loads. but routing changes on every token, so a fixed choice misses most of what the model asks for. FreeToken measures both bandwidths on your machine and splits each step's misses between the two paths in proportion. the GPU and CPU results then merge exactly, with no approximation. two machines with the same GPU can end up wanting opposite strategies, which I did not expect. a 5090 in a gaming desktop should push nearly everything over PCIe, while an 8GB laptop is better off computing most misses on the CPU. none of that is readable off a spec sheet, so the engine profiles it once per machine. the second half of the design is about agents. coding agents constantly rewrite their own history, and every edit normally forces thousands of tokens back through prefill. FreeToken saves its checkpoints at the exact boundaries agent frameworks cut on, so it only reprocesses the new part. its slowest first token stays under 44 seconds, while llama.cpp peaks at 232 and KTransformers at 946. it serves the OpenAI and Anthropic APIs under Apache 2.0, so Claude Code and Codex can point at it directly. releasing weights publicly decides who can download a model, not who can afford to run one. frontier open models keep shipping, and running them still assumes a rented cluster. meanwhile there are over a hundred million consumer machines with discrete GPUs sitting mostly idle. closing that gap was never a hardware problem, and work like this is what turns open weights into something you can actually use. paper: repo: almost every idea in this post, from why memory bandwidth decides the outcome to why moving weights costs more than computing on them, comes straight out of how a GPU is built. I wrote a detailed primer on that. the article is quoted below.

Akshay 🚀

346,057 просмотров • 2 месяцев назад