Загрузка видео...

Не удалось загрузить видео

На главную

Cloud GPU training is a scam. A single M4 MacBook does 2.9 TFLOPS. Seven friends with MacBooks match an NVIDIA A100. Alexander Hayes just open-sourced a tool that makes this work over Wi-Fi. It's called AirTrain. Here's how it works: Traditional distributed training (DDP) syncs gradients after every single...

160,201 просмотров • 5 месяцев назад •via X (Twitter)

Комментарии: 0

Нет доступных комментариев

Здесь появятся комментарии из оригинального поста

Похожие видео

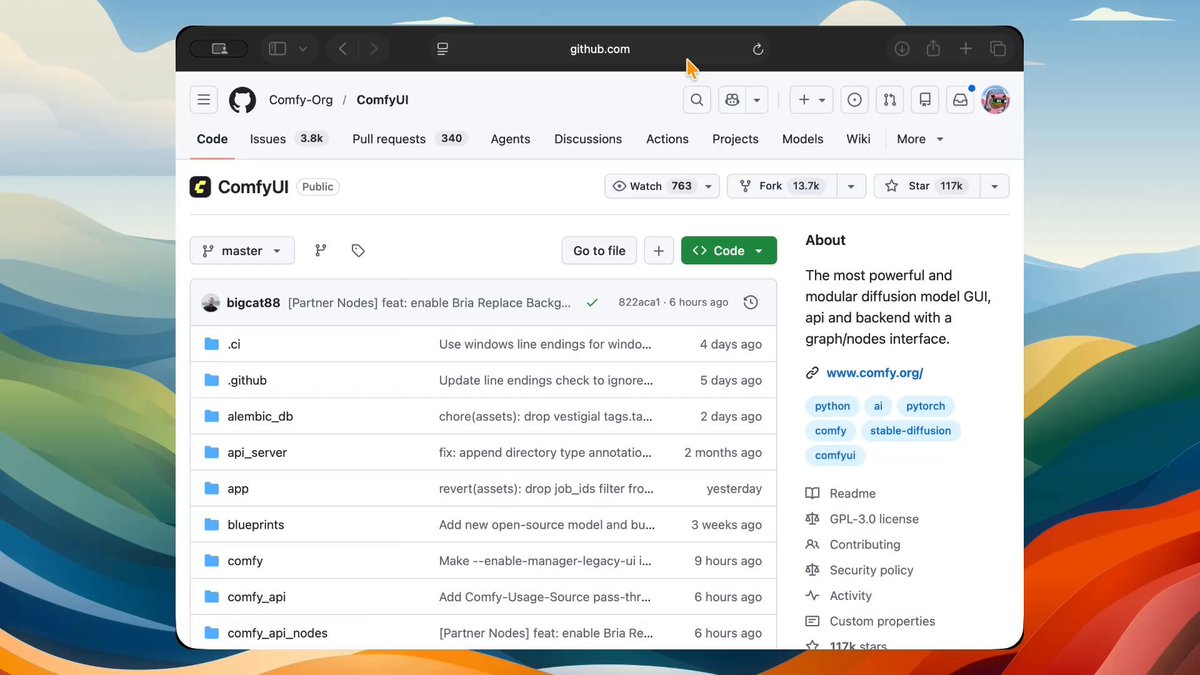
no money for grok or midjourney? this tool is for you. there's a FREE tool created by an anon dev. open-source. runs locally. 117k stars on github. it generates: > images & video > 3d models > audio > 20+ models here's how to set it up in under 5 minutes: 1️⃣download ComfyUI Desktop go to and grab the desktop app for your system. windows 10+, mac (apple silicon), or linux. it installs like any normal app, it sets up python and every dependency for you in the background. no terminal, no config files. 2️⃣open it first launch, it spins up its own environment automatically. you just wait a few seconds and you're in. you'll land on a node canvas, that's the whole interface. 3️⃣load a starter workflow top menu → Workflow → Browse Templates → Image Generation. click it. this drops a ready-made setup onto your canvas so you don't build anything from scratch. 4️⃣grab a model comfyui ships empty on purpose, the model is the brain, and you pick it. in the template, the "Load Checkpoint" node has a Download button when no model is installed. click it. it pulls one in for you (a few GB, this is the only real wait). 5️⃣install ComfyUI Manager this is the one add-on you don't skip. it lets you install models, custom nodes, and updates with a click instead of the command line. grab it from github (link in comments). it's the difference between fighting comfyui and flying in it. one honest note: an NVIDIA gpu makes this fast, apple silicon works great too, and a weak machine still runs it just slower. that's the whole setup. you now own an image, video, and 3D studio that costs you nothing per month. save this. and the next time grok or midjourney asks for your card. you won't need it. disclaimer: comfyui itself is 100% free. so are the local models (sdxl, flux, wan 2.2, ltx-2). some premium models like seedance are pay-per-use api models, only if you want top-tier quality. the free local ones cover most of what you need. (github link in the comments) follow and turn on post notification for daily AI contents.

m0h

14,542 просмотров • 3 месяцев назад

Everyone wrote Apple off as the AI loser, but one hardware spec might flip that story upside down (Save this). @jason called Apple a screaming buy on the back of a single chip detail. The rumored M7 Ultra, expected around 2028, is designed to support up to 1.5TB of unified memory, enough to run frontier class trillion parameter AI models locally, with no cloud required. The Street's bear case on Apple is straightforward. Apple has no frontier model of its own, Siri has stumbled for years and the company effectively rents OpenAI's models for its hardest queries. That narrative treats Apple as the one Magnificent Seven name that missed the AI wave entirely but the bull case flips that framing on its head. If frontier AI models keep shrinking and getting cheaper to run, Apple doesn't need the smartest model in the world, it just needs to own the device that model runs on. And unified memory is the mechanism that makes this possible. Unlike traditional systems where the CPU and GPU each need separate memory, Apple's architecture lets the CPU, GPU and Neural Engine draw from one shared pool. A fully specced M7 Ultra could theoretically run something on the scale of a 1.2 trillion parameter model locally and that capability plugs directly into the one advantage Apple has spent over a decade building: privacy. Apple has already shipped Private Cloud Compute, a system designed so even Apple can't access user data processed off device. Apple doubled down on this at WWDC 2026, framing on device privacy as non-negotiable while rivals default to the cloud. If the best AI models get small enough to run on Apple silicon, the moat stops being the model and becomes the hardware it has to sit on. Milk Road Pro remains bullish on Apple and it remains as one of our core positions, if you want the full thesis + our full AI trades, come join us using the link below for just a $1.

Milk Road AI

37,459 просмотров • 2 месяцев назад

a team of researchers just proved you don't need a bigger model, you need a smarter plan researchers from Tsinghua and South China University of Technology built a framework called Atomic Task Graph. it turned 7B-8B open-source models into GPT-4 competitors on complex agent benchmarks, beating it on two out of three. no fine-tuning. no extra training. zero parameter updates. current AI agents plan in a straight line. step 1, step 2, step 3. when step 4 fails, the whole chain breaks. and the longer the chain gets, the more the model hallucinates because it's reasoning over a ballooning text history. here's how it works. 1. instead of a linear chain, ATG breaks any complex task into a directed graph where subtask inputs and outputs are explicitly mapped 2. it recursively decomposes each subtask until every node is one atomic tool call 3. independent branches run in parallel instead of waiting in line 4. before anything executes, a lightweight "thought experiment" simulates the plan internally to catch bad dependencies and missing steps early 5. when something breaks at runtime, ATG traces the failure to the exact subgraph that caused it and repairs only that piece. validated work stays frozen. the old way meant a failure at step 5 forced a full replan from scratch. hallucinated actions piled up the longer the task ran. ReAct hit a 43% hallucination rate on household tasks. ATG on an 8B Llama model scored 63.65 on ALFWorld. GPT-4 with ReAct scored 41.24 on the same benchmark. hallucinated actions dropped to 12%. those numbers happened because someone stopped throwing compute at the problem and started thinking about how work gets organized. that's the part that gets me. the industry is spending billions on scale. this team spent time on architecture. and the architecture won.

Alex Veremeyenko

174,269 просмотров • 2 месяцев назад

UC Berkeley just open-sourced FreeToken. (2–4x faster local LLM inference than Ollama) the results are wild: - Qwen3.6-35B on an 8GB GPU at 39.3 tokens/s - DeepSeek-V4-Flash 284B on a 32GB GPU at 22 tokens/s - GLM-5.2 753B on a 96GB GPU at 14.9 tokens/s a 35B model at 16-bit precision needs about 70GB just for its weights. even at 4 bits it is close to 18GB, and FreeToken serves it on an 8GB GPU. let me explain how: all three models mentioned above are Mixture-of-Experts, and that is what FreeToken takes advantage of. each layer holds hundreds of separate experts plus a small router that picks a few of them per token. Qwen3.6-35B activates roughly 3B of its 35B parameters per token. DeepSeek-V4-Flash picks 6 of 256 experts per layer, so 13B of its 284B run at a time. so compute was never the bottleneck. the weights a single step touches fit comfortably on a consumer GPU. every expert the router might pick still has to exist somewhere. they sit in system RAM, and the GPU keeps a cache of the ones the model has been using recently. so everything comes down to what happens when the router picks an expert that is not on the GPU. there are two ways to serve that miss: 1. copy it over PCIe and run it on the GPU 2. run it on the CPU, where it already lives both read from the same system memory, so they compete for one pool of bandwidth instead of adding to each other. existing engines pick one option and freeze it when the model loads. but routing changes on every token, so a fixed choice misses most of what the model asks for. FreeToken measures both bandwidths on your machine and splits each step's misses between the two paths in proportion. the GPU and CPU results then merge exactly, with no approximation. two machines with the same GPU can end up wanting opposite strategies, which I did not expect. a 5090 in a gaming desktop should push nearly everything over PCIe, while an 8GB laptop is better off computing most misses on the CPU. none of that is readable off a spec sheet, so the engine profiles it once per machine. the second half of the design is about agents. coding agents constantly rewrite their own history, and every edit normally forces thousands of tokens back through prefill. FreeToken saves its checkpoints at the exact boundaries agent frameworks cut on, so it only reprocesses the new part. its slowest first token stays under 44 seconds, while llama.cpp peaks at 232 and KTransformers at 946. it serves the OpenAI and Anthropic APIs under Apache 2.0, so Claude Code and Codex can point at it directly. releasing weights publicly decides who can download a model, not who can afford to run one. frontier open models keep shipping, and running them still assumes a rented cluster. meanwhile there are over a hundred million consumer machines with discrete GPUs sitting mostly idle. closing that gap was never a hardware problem, and work like this is what turns open weights into something you can actually use. paper: repo: almost every idea in this post, from why memory bandwidth decides the outcome to why moving weights costs more than computing on them, comes straight out of how a GPU is built. I wrote a detailed primer on that. the article is quoted below.

Akshay 🚀

343,270 просмотров • 1 месяц назад

Alibaba just released a coding model that hits 82 percent on SWE-Bench Verified. That is the highest score ever published for an open-source model. The weights are free. The license is Apache 2.0. You can run it today. The model is Qwen 4 Coder 32B. Here is what 82 percent on SWE-Bench Verified actually means. SWE-Bench Verified tests whether an AI can autonomously resolve real bugs pulled from real production GitHub repositories. Not synthetic exercises. Real open-source projects that real teams depend on. A model gets a bug report, reads the code, writes a fix, and either passes the test suite or it does not. At 82 percent, Qwen 4 Coder 32B resolves 82 out of every 100 real production bugs it is given. Without a human guiding it. On code it has never seen before. For comparison: Qwen 4 Coder 32B: 82 percent SWE-Bench Verified. Open source. Apache 2.0. Claude Fable 5: 80.3 percent SWE-Bench Pro. $10 input / $50 output per million tokens. Currently suspended. GPT-5.6 Sol: Competitive on Terminal-Bench. $5 input / $30 output per million tokens. An open-weight model that you can download and run for free just beat both of them on the benchmark designed to measure real software engineering capability. Here is the architecture. Qwen 4 Coder 32B is a 32 billion parameter dense model. Not a Mixture-of-Experts. Every parameter is active on every request. This matters for inference: a dense 32B model runs on 22 gigabytes of VRAM, which fits on a single high-end consumer GPU or a MacBook Pro with 64GB of unified memory. The smaller variant, Qwen 4 Coder 4B, runs at approximately 135 tokens per second on an M5 Max and fits inside 8 gigabytes of RAM. For a model with usable coding capability, that is a new bar for what fits in a single laptop. The training methodology continued Alibaba's approach of reinforcement learning on verifiable coding tasks. The model gets rewarded when its code passes tests. It gets penalized when it fails. Over millions of training steps, the model learns to write code that actually runs rather than code that looks plausible. License: Apache 2.0. Full commercial use. No attribution requirement. No revenue threshold. No monthly active user ceiling. Weights: Hugging Face, available today. Runs on: vLLM, Ollama, SGLang, and any standard GGUF-compatible inference engine. Qwen 4 32B also runs at approximately 135 tokens per second on an M5 Max chip, setting a new bar for what a sub-8GB model can do on Apple Silicon. The open-source coding model just beat the best closed-source model in the world on the benchmark designed to test whether AI can actually do software engineering. The weights are free. The subscription is optional. Source: Autom8Labs AI Insight July 2026, State of Open Source LLMs June 2026, Kunal Ganglani blog June 2026.

Harman

41,278 просмотров • 2 месяцев назад

The bottleneck in AI has quietly shifted. - It's not the models. They are capable. - It's not the frameworks. They are mature. - It's not even the data, in many cases. When you want to train a model today, the first question isn't "what architecture should I use?" Instead, it's: "Where am I going to get infrastructure that actually works?" Not just GPUs but the entire stack: compute, deployment, scaling, storage. The traditional path is major cloud providers or specialized GPU clouds. Both have the same problem: they're built for enterprises with committed workloads, minimum spend requirements, contract negotiations, and involve quota approvals that take days. Even the "on-demand" options require you to piece together training, deployment, and scaling across different services. By the time you're actually training, hours, if not days, have passed. And there's a subtler cost: part of your brain is always managing infrastructure instead of thinking about the actual problem. I've been using Runpod for a while now, and it's the closest I've found to infrastructure that just disappears. I pay for the serverless solution by the second, and stop when I'm done. This sounds like it should be the default across all providers, but it isn't. For instance, when I'm prototyping, I don't need an H100. Instead, I need the flexibility to use cheaper GPUs that are actually available, where I can iterate fast and not worry about cost. An A40 at a few cents per hour is perfect for this. Then, when the approach is validated, I scale up. This matches how good engineering actually works. Running distributed training across multiple nodes for multi-GPU training usually requires significant infra work. RunPod abstracts most of this away. A lot of the advantage in AI comes from iteration speed. Infra that adds days of latency to that loop is a real cost, even if it's hard to measure. But good infra gets out of your way. It's available when you need it, invisible when you don't. In the video below, I have shown a simple model training workflow trained using PyTorch in Jupyter Lab. It runs in a dedicated PyTorch Pod hosted on Runpod, and I worked with the team to put this together for you. Find a link to start using Runpod in the replies!

Avi Chawla

13,696 просмотров • 8 месяцев назад

I had to test it myself to believe this unreal inference speed. 3,000 tokens/s for 1 user on standard datacenter GPUs. They leveraged a hidden efficiency gap in how GPUs generate tokens. Kog just achieved 3,000 tokens/s on 8× AMD MI300X GPUs and 2,100 on 8× NVIDIA H200 (FP16, no speculative decoding). Their tech preview is on a 2B model, and they show how their techniques will scale to large frontier MoE models at similar speeds. That's a huge number because normal low-batch GPU decoding for 2B to 8B models is usually closer to 100 to 300 tokens/s per request, so Kog is claiming something like a 10X to 30X jump in the speed one user actually feels. Their trick: they are getting the speed by treating LLM decoding as a memory streaming problem, not mainly a math problem. For 1 user at batch size 1, the GPU is not doing big, efficient matrix-matrix work like in training or large-batch serving; it is repeatedly pulling the model’s active weights from high-bandwidth memory for each new token, so speed depends on how smoothly those weights keep flowing. Normal inference stacks keep breaking that flow. They run many separate GPU programs for different parts of the model, move intermediate results through memory, wait at synchronization points, talk back to the CPU for scheduling or sampling, and then repeat this token after token. Kog’s answer is to co-design 3 things that are usually tuned separately: the runtime, the low-level GPU code, and the model architecture. The biggest engineering move is the monokernel, where the whole decode pass runs as 1 persistent GPU-resident program, including sampling, so the system does not keep stopping for kernel launches, CPU scheduling, and intermediate memory round trips. They also rebuilt synchronization, because their own measurements say grid sync was eating around 35% of token-generation time; instead of making every compute unit wait at a broad barrier, each unit waits only for the exact data it needs. On AMD MI300X, they also map memory access around the chiplet layout, because memory latency changes depending on which die makes the request. Then their Laneformer model uses Delayed Tensor Parallelism, which lets cross-GPU communication happen in the background instead of blocking every layer.

Rohan Paul

13,282 просмотров • 4 месяцев назад

This Chinese developer runs 9 agents on Claude Code under a GPT-5.5 orchestrator and they close 500 client tasks a month without a single assistant. His client work is closed without him, on a single laptop and only three subscriptions. The entire system lives on one MacBook Pro M4 with 128 GB of memory and subscriptions to Claude Code and GPT-5.5 cost him approximately $300 a month. There is no CRM, no team, no office only a terminal window with 9 parallel streams. The orchestrator works with a simple system prompt: «You are the orchestrator of a client inbox. Classify every incoming email into 4 categories: code, content, analysis, communication. Delegate to the corresponding worker agent. When the result is ready, check it for completeness, send it to the client on my behalf, and mark the task as closed. Do not ask clarifying questions.» And the orchestrator checks the inbox every 30 seconds, classifies fresh emails, and distributes them to 9 worker agents on Claude Code, each of whom is responsible for their own class of tasks. Here is an example of how one of them closes a request to refactor a client's auth module: Task: refactor user-auth module Broke the monolith into 3 files by responsibilities Added unit tests, coverage increased to 87% Renamed 4 functions to camelCase according to the style guide PR is ready for review, link below» And so about 50 cycles a day. By noon 25 tasks are closed, by dinner 50, and by the end of the month 500. On average, it takes about 7 minutes from the appearance of an email in the inbox to sending the result to the client. This is more than what a live team of 6 developers, copywriters and analysts working 8 hours a day closes. This is no longer an agency. This is a workstation where an orchestrator replaces a manager, and 9 worker agents replace the staff. The pipeline goes from inbox to closing 500 times a month without human participation at any step.

Blaze

29,917 просмотров • 4 месяцев назад

This Chinese developer linked two $2,999 NVIDIA DGX Sparks into one box and runs the full Qwen3-235B at home, after dropping his $1,999-a-month cloud bill to zero. He wired 2 small boxes into a single computer, split a giant 235-billion-parameter model in half between them, and serves it across his own network at about 10 tokens a second, with no internet, no cloud, right there on the desk. No data center, no thousand-dollar graphics cards, no monthly cloud bill. Just him, 2 gold boxes the size of a sandwich, one cable between them, and 1 power strip. And here is the whole payoff. He used to pay the cloud $1,999 a month for the same model, and the meter ticked on every request. Now he paid $5,998 once for 2 boxes, they covered their cost in 3 months, and after that he sends as many requests as he wants for free, only electricity. The two Sparks talk over one fast cable, each holds 128GB of memory, and together they carry the whole model, about 73GB loaded per box, with the chip inside pinned near the limit at 96%. Both boxes work as one and keep trading data over the cable, with no cloud in the loop and no single word leaking out. The ready model sits on one local address, and any app on his network calls it as easily as ChatGPT. And here is how he described, in plain words, what this pair of boxes does: "this is a pair of boxes that holds the huge Qwen3-235B model and serves it to one network. the model is split in half, and each box owns its half. parts: // Box 1 (holds the first half of the model and starts the answer fast, the first word appears in under a second) // Box 2 (holds the second half and writes out the rest, about 10 tokens a second) // Cable (connects the 2 boxes and moves data between them on every step, with no lag) // Address (one local address where any app sends its request, like to a cloud model) // Test (a script that runs big prompts through and measures speed and delays) // Monitor (checks temperature, power draw, and load on both boxes every 2 seconds). the model never goes to the cloud. he only steps in when a box runs hotter than 80 degrees or the cable between them starts dropping data." So the system knows exactly what it is, what it is for, and where its limits are. It knows it has to hold the whole huge model across 2 boxes on its own. It knows it has to answer every request locally, with no meter, no limits, and no internet. It knows the human is only needed when a box overheats or the link between them stalls. → The setup runs around the clock on 2 boxes, each pulling under 60 watts → However many requests he sends, the monthly bill is $0, only electricity → The first box starts the answer in under a second → The second writes text at about 10 tokens a second → One request at a time: 838 tokens in 85 seconds, first word in 0.8s → Two requests at once: 697 tokens in 108 seconds, first word in 0.7s → Both boxes sit at 96% load and warm up to 76-78 degrees And only when a chip in a box runs hotter than 80 degrees or the cable between the 2 Sparks drops data does the system call the owner. And when he himself is out on a run or in a coffee shop, he still reaches his own model at home from his phone: sends a big prompt to the local Qwen3-235B, gets the full answer back in under a minute and a half, with no token meter ticking and no limit to hit. Here is what the test shows on his screen during one of the night runs: "one request at a time: 838 tokens in 84.9 seconds, first word in 0.8s, then 0.1s per token." "two requests at once: 697 tokens in 107.6 seconds, first word in 0.7s, then 0.15s per token." "Box 1: chip at 96% load, 76 degrees, 56 watts, 73GB used in memory." "Box 2: chip at 96% load, 78 degrees, 56 watts, the Qwen3-235B model fully loaded." And while everyone around is paying for AI by the month and bumping into limits, his top-tier model just sits on the desk and works as much as he wants: his own little power plant instead of a forever meter. He has no server rack of his own and no cloud account behind it. Just 2 DGX Spark boxes on a desk, one model split in half between them, one local address, and a folder of prompts next to it. Out of everything I have seen this year, this is the cleanest way to stop paying for AI: $5,998 of hardware on the desk once, $0 a month to the cloud, unlimited forever, and between them 2 gold boxes, 1 cable, and the full Qwen3-235B answering at home with no internet.

Blaze

93,871 просмотров • 3 месяцев назад

We made a thing! Very happy to announce sqlcoder-pro and the Defog Alignment Platform. Available to use immediately without a wait-list, weights will be open-sourced very soon. The video does a quick show and tell comparison against ChatGPT (with gpt-4o). Read on for more details! TLDR 💪 equal (or better) performance on text-to-SQL as the most capable Claude-3.5 or GPT-4 models 🤝 You can use it today on a free plan/free trial, without a waitlist 🪽 self-hostable on a single RTX4090, with 2 second median generation times for SQL queries 🔁 exactly the same output every time, give the same prompt 👨🏻‍🏫 teachable and steerable: show the model what you want it to do 🛞 debuggable – you can understand WTF is going on inside the model, instead of treating it like a black box Let's dig into each of these one-by-one! Performance SQLCoder-8b-pro significantly exceeds the performance of our previous sqlcoder-8b model on Postgres text-to-SQL (from 88.2% to 90.2% accuracy - gpt-4o is at 87.6%, for reference). It is also better at following instructions. This was done via self-merges, hand crafted fine-tuning data, and adapting the training data to fit our tokenizer. Cost You can host this on the model on a single $3,500 RTX4090, and support ~5 requests/second via VLLM. If you're looking to host on the cloud instead, you can run it on a single L4 GPU that costs $300/mo on GCP Repeatability We have a dense 8b model with no MoE shenanigans. For the same prompt with temperature=0, you'll always get the same answer – which is critical in BI. Teachable In our alignment and feedback modes, you can give the model feedback on how it answered certain questions, and it will automatically adapt to the feedback. Debuggable You can use logprobs and attention scores to determine where, exactly is the model paying attention to inside a prompt + what it's getting confused by when generating outputs. Available today You can use Defog on the cloud today by going to docs[dot]defog[dot]ai, and getting an API key. Excited to hear what you think!

Rishabh Srivastava

13,469 просмотров • 2 лет назад

September 2009. Jensen Huang walks onto a small stage at the Fairmont hotel in San Jose. About 1,500 people are in the room. He runs a company that makes chips for video games. He spends the next 8 minutes doing math on a whiteboard, explaining why the future of computing won't come from making CPUs faster. He calls it "CEO math" and apologizes in advance to every computer science professor in the audience. Then he lays out an argument that almost nobody took seriously at the time: the way to make computers dramatically faster is to pair a regular CPU with hundreds of tiny parallel processors, the kind that already exist inside graphics cards. One CPU for the sequential stuff. Hundreds of GPU cores for everything else. He calls it "heterogeneous computing." He shows the math. A workload that can be split into many pieces at once gets up to 200x faster on this combined system. A workload that has to run one step at a time loses nothing. "The most important thing in creating a new architecture," he says, "is to make sure it does no harm." This was the first GPU Technology Conference. NVIDIA had launched a software platform called CUDA three years earlier, in 2006, to let developers write programs that run on graphics cards instead of just regular processors. Almost nobody cared. GPUs were for rendering Call of Duty, not for scientific computing. The academic world was polite but skeptical. The enterprise world ignored it entirely. By this point, Huang had been making this argument for years. NVIDIA was a $7 billion company. It competed with AMD and Intel for market share in the graphics market. That was the whole business. Jensen kept saying the GPU wasn't just a gaming chip; it was a computing platform. He kept saying parallel processing would reshape every industry from medicine to finance to physics simulations. People kept nodding, then doing nothing. Then deep learning happened. Around 2012, AI researchers discovered that training a neural network, which means teaching a computer to recognize patterns by running the same calculation millions of times across huge datasets, was exactly the kind of workload Jensen had been describing. GPUs can train AI models 10 to 50 times faster than CPUs. The architecture he outlined in this 2009 talk, with one CPU handling step-by-step tasks while hundreds of GPU cores crunch through massive amounts of parallel data, is now the literal blueprint for every AI data center on earth. ChatGPT runs on NVIDIA GPUs. Claude runs on NVIDIA GPUs. Gemini, Llama, Midjourney, nearly every major AI model you've heard of was trained on NVIDIA hardware using CUDA, the software platform Jensen built for a market that didn't exist yet. NVIDIA was worth about $7 billion when Jensen gave this talk. It is worth over $4.4 trillion today. That's a 600x increase. Jensen Huang, who founded the company at a Denny's in 1993 with two friends, now has a net worth of over $160 billion. He made Forbes' list of the 10 richest people for the first time this year. GTC 2026 is currently ongoing. 17,000 people are packing a hockey arena to watch the same guy explain what comes next. In 2009, 1,500 people showed up at a hotel ballroom, most of them for gaming graphics.

Anish Moonka

414,415 просмотров • 6 месяцев назад

Every AI agent you've tried has amnesia. It does one task, forgets everything, and tomorrow you start from zero. That's not an employee. That's a temp you have to retrain every single morning. Hyperagent by Airtable is the first platform I've used that actually fixes this. Here's what got me: 1. Agents that compound. Each agent has memory. The one running today is smarter than the one you shipped three weeks ago. Same prompt, same integrations, but weeks of your judgment baked in. 2. Real deliverables, real receipts. You don't get a chat transcript. You get finished work with the cost and runtime printed right on it. A full research report for under ten bucks. Try getting that invoice from an agency. 3. A fleet, not a chatbot. Build a specialist for outreach, another for research, another for reporting. Give each one its own tools, its own memory, and its own budget cap so nothing runs away with your credits. 4. Deploy to Slack and your whole team uses the agent you built. One competitive intel agent, @ mentioned by everyone. Airtable runs its own data team this way. 5. Each agent gets its own cloud machine with a real browser and code execution. It works while you sleep. No babysitting, no local setup, no laptop that has to stay open. I put it to work in the video below. Watch what it builds. The teams treating agents as durable assets instead of one-off prompts are going to lap everyone else. This is the first tool that actually treats them that way. #ad Hyperagent

Leonard Rodman

94,961 просмотров • 2 месяцев назад

I'm making $8,000 a month building Claude skills for other people's businesses. I call it the AI Concierge. I have 5 clients paying $1,200 to $2,000 a month each. My effective rate is about $1,200 an hour. Every engagement runs on one framework I call AOA: Audit, Optimize, Automate. Here's the entire model: 1) Most people skip straight to Automate. That's the fun part. It's also how you end up automating a broken process. 2) Audit first. The client shares their screen and walks the process in painful detail while I take notes in a Google Doc and interrupt with a million questions. 3) Capture the plumbing, not just the steps. Who owns each step, which tool it runs in, where the data lives, and whether that tool can connect to Claude. 4) Hand the audit doc to Claude and ask it to find a better way. Then push back. Claude's first synopsis is usually partly wrong, and the client catches it. 5) Cut the fat. Most processes are 15 steps and only need to be 11. Most clients use 3 tools where 2 would do. 6) One home per fact. One client stored customer data in ClickUp and the CRM. We killed the ClickUp copy. Duplicates are just human error waiting to happen. 7) Have Claude write the build plan. It splits the process into skills, scaffolds each one, and lists next steps. Then you lock the doc. 8) A skill is a markdown file plus reference files. A reference file is just an example of what good looks like. Claude builds all of it. 9) Build one skill at a time from the build plan. If the audit was done right, Claude one shots it. Test on a real run, let Claude interview you, iterate. Version 2 is usually the keeper. 10) Draft first, never auto send. A speed to lead skill drafts replies for review on day one. It earns auto send later. Two things that make this work: 1) Audit and Optimize are 80% of the work. Automate is the 20%. You have to earn the right to build. 2) Skills do one thing well. Split at every point a human or a wait interrupts the chain, then let an orchestrator run them back to back. Full step-by-step playbook for starting a profitable AI Concierge business (free): Full breakdown below. Enjoy!

Corey Ganim

68,713 просмотров • 11 дней назад

Training Volume / Intensity / Rep Range / Progressive Overload — Everything You Need To Know: (This is what will grow MOST people best) 𝗧𝗢𝗧𝗔𝗟 𝗦𝗘𝗧𝗦 𝗣𝗘𝗥 𝗪𝗘𝗘𝗞 45ish-60ish total working sets per week - If training 3x per week, this will mean 16, 17, 18ish sets per session - If training 4x per week, this will mean 13, 14, 15ish sets per session - If training 5x per week, this will mean 10, 11, 12ish sets per session 𝗧𝗢𝗧𝗔𝗟 𝗦𝗘𝗧𝗦 𝗣𝗘𝗥 𝗕𝗢𝗗𝗬 𝗣𝗔𝗥𝗧 𝗣𝗘𝗥 𝗪𝗘𝗘𝗞 - For balanced development, you’re going to want to perform 5, 6, 7, 8ish sets per body part per week - If prioritizing a muscle group, you’re going to want to perform 8, 9, 10, MAYBE 10+ sets for that body part each week - If deprioritizing a muscle group, you only need 2, 3, 4ish sets for that body part each week to maintain existing development 𝗙𝗥𝗘𝗤𝗨𝗘𝗡𝗖𝗬 In all likelihood, you will get MORE (in the way of stimulus) by splitting the work you do for a given muscle group across 2 sessions per week Splitting the work you do for a given muscle group across 3 sessions per week can work as well but the potential benefit is probably NOT that large and it diminishes the margin of safety Performing all the work you do for a given muscle group on ONE day (Bro Split Style) can work but it like has an opportunity cost associated with it 𝗧𝗢𝗧𝗔𝗟 𝗦𝗘𝗧𝗦 𝗣𝗘𝗥 𝗘𝗫𝗘𝗥𝗖𝗜𝗦𝗘 The sweet spot is generally 2-3 sets for a given exercise in a given session 1 set is fine depending on the context of the programming as a whole but you likely didn’t squeeze all the juice out of the lemon If you preform 4+ sets of a given exercise in a given session, what the fuck were you doing the first couple of sets? 𝗜𝗡𝗧𝗘𝗡𝗦𝗜𝗧𝗬 The intensity you take sets to can GREATLY IMPACT how many total sets you can perform while still allowing for adequate recovery from session to session Generally speaking, it is a good idea to leave about 1 RIR on most exercises to ensure stimulus is robust but fatigue is kept at bay There is one HUGE caveat to that however: If you do not trust your ability to accurately gauge RIR, it is better to just take your sets to 0 RIR/Failure than it is to risk sandbagging sets by leaving an incidental 2, 3, 4+ reps in the tank…just know you will not be able to generate as high a net stimulus throughout the week if you live in this intensity range 𝗥𝗲𝗽 𝗥𝗮𝗻𝗴𝗲/𝗣𝗿𝗼𝗴𝗿𝗲𝘀𝘀𝗶𝘃𝗲 𝗢𝘃𝗲𝗿𝗹𝗼𝗮𝗱 Pick a weight you can do for 5-6ish reps with GOOD-GREAT technique @ the prescribed RIR (should be 0-2 RIR) Once you can hit 7, 8, 9, 10ish reps with the same GOOD-GREAT technique @ the prescribed RIR, increase the load You can weight select on a SET BY SET BASIS — this means in theory some of your sets could be heavier/lighter than others (assuming you’re doing multiple sets of a given exercise on a given day)

Dean Turner

18,116 просмотров • 7 месяцев назад