Video wird geladen...

Video konnte nicht geladen werden

Zur Startseite

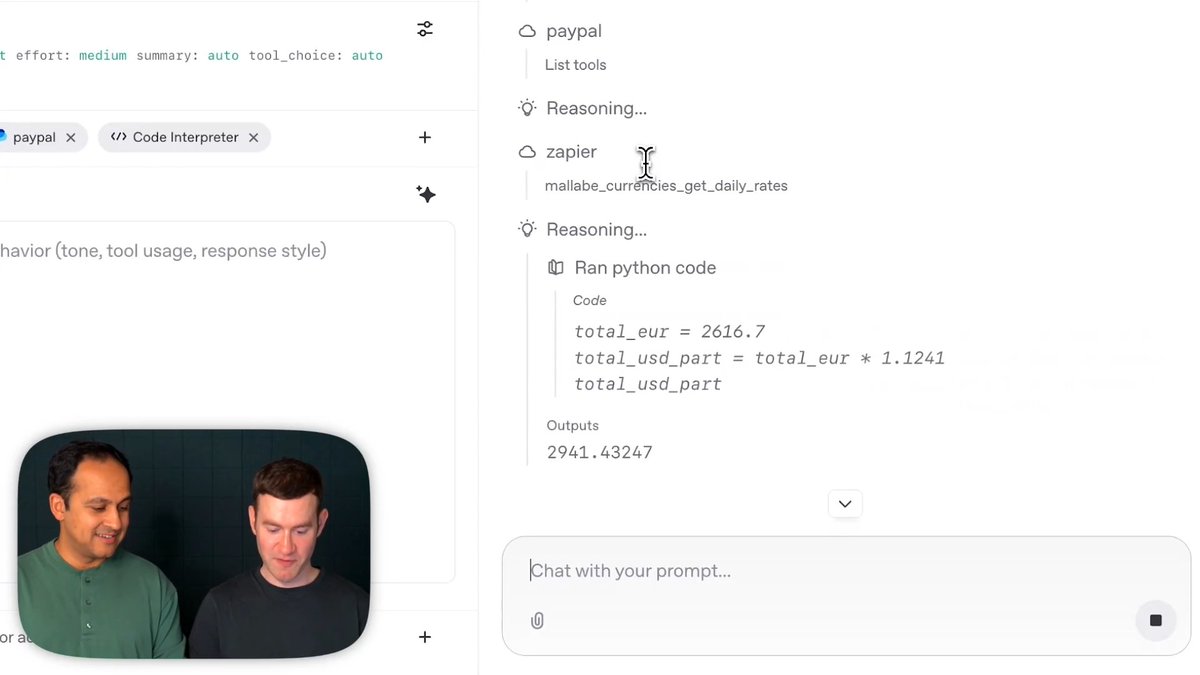
Evals now supports tool use. 🛠️ You can now use tools and Structured Outputs when completing eval runs, and evaluate tool calls based on the arguments passed and responses returned. This supports tools that are OpenAI-hosted, MCP, and non-hosted. Read more in our guides below.

65,080 Aufrufe • vor 1 Jahr •via X (Twitter)

11 Kommentare

Profilbild von OpenAI Developers
OpenAI Developersvor 1 Jahr

Web Search evaluation:

Profilbild von OpenAI Developers
OpenAI Developersvor 1 Jahr

Tools evaluation:

Profilbild von OpenAI Developers
OpenAI Developersvor 1 Jahr

Structured Outputs evaluation:

Profilbild von OpenAI Developers
OpenAI Developersvor 1 Jahr

MCP evaluation:

Profilbild von Matt Figdore
Matt Figdorevor 2 Jahren

This is the biggest productivity cheat code right now. Kiss reading documents goodbye. You can get an instant summary of any document with this tool.

Profilbild von Opulent Byte
Opulent Bytevor 1 Jahr

When o3 pro? 🥲🫠

Profilbild von Brij Singh
Brij Singhvor 1 Jahr

this is good!

Profilbild von Cliffinkent 🇬🇧
Cliffinkent 🇬🇧vor 1 Jahr

You keep building and shipping!

Profilbild von Prashant
Prashantvor 1 Jahr

This just makes running evals so much easier. Thank you

Profilbild von Vishal
Vishalvor 1 Jahr

Tool support in Evals makes testing AI tools easier and improves accuracy.

Profilbild von Henkjan de Krijger
Henkjan de Krijgervor 1 Jahr

Does relying on eval tools hinder critical thinking in AI systems?

Ähnliche Videos

10 agent evals every AI engineer should know 1) golden set a frozen set of cases you run after every prompt model or tool change use it as your baseline to see whether the system improved or quietly broke OpenAI Evals helps you build repeatable benchmark sets and compare model changes → 2) llm as judge a second model scores open ended answers against a written rubric use it when there is no exact output to compare against OpenEvals provides ready made evaluators for LLM applications → 3) rubric scoring score correctness tone safety and cost separately one quality number hides the problem DeepEval helps you create custom metrics and score every dimension independently → 4) trajectory eval grade the path the agent took not only the final answer AgentEvals checks agent actions decisions and tool calls across the full trajectory → 5) tool unit tests test every tool with fixed inputs and outputs no model in the loop MCP Inspector helps you inspect and test MCP servers tools and responses separately → 6) regression suite replay previous runs against every new prompt model or toolset then compare the results Promptfoo helps you run repeatable eval suites catch regressions and add checks to CI → 7) a b in prod split real traffic between two versions and compare actual outcomes GrowthBook provides feature flags controlled experiments and product analytics → 8) human review sample real runs and let a person grade them honestly use it to calibrate your automated judge Argilla helps teams collect human feedback review outputs and build better datasets → 9) shadow run let the candidate run on real traffic while its output is shown to nobody use it before a risky rollout Langfuse helps you trace production runs compare candidates and monitor eval results → 10) red team attack the system before somebody else does jailbreaks prompt injection data leaks and tool abuse Garak scans LLM systems for vulnerabilities and unsafe behavior → offline evals tell you it works online evals tell you it still works you probably do not need all ten today start with the two that would have caught your last outage bookmark this

elune

155,026 Aufrufe • vor 2 Monaten