正在加载视频...
视频加载失败
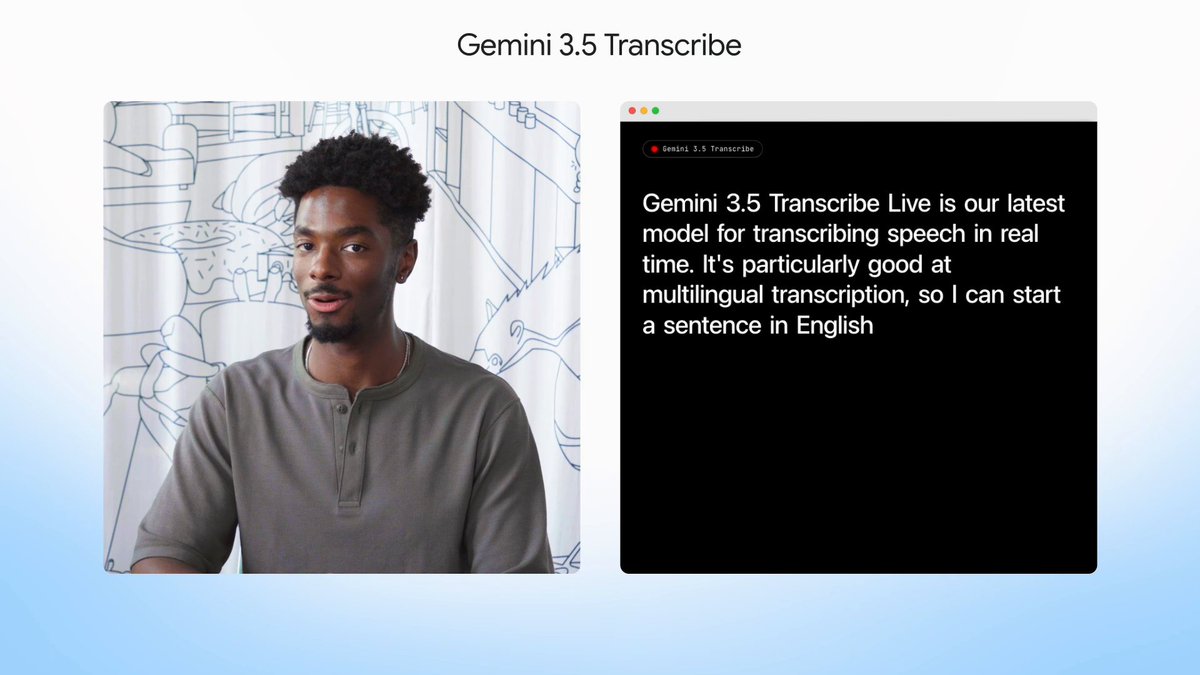
Gemini 3.5 Transcribe is our latest speech-to-text model for precise and intelligent transcriptions. 🧵
69,615 次观看 • 1 个月前 •via X (Twitter)
32 条评论

Here’s what’s new: 🔵 It’s better at understanding complex phone numbers, postal codes, and order IDs – even in noisy environments. 🔵 It can remove filler words and auto-format your text. 🔵 It recognizes custom vocabulary so the model knows unique names and product titles. 🔵 It automatically detects and transcribes speech in 85+ languages. Try it now in the @Geminiapp on macOS and Gboard on @Android. Start building in @GoogleAIStudio and @Antigravity →

If it's actually precise, the court reporting and medical transcription industries won't survive another year.

Word accuracy is mostly solved now. The hard part in production is handling crosstalk, natural pauses, and end-of-turn detection with zero latency.

yo other labs are closing in on AGI and you're here still making speech to text models that were pretty much perfected in 2022. get your game up google

Congratulations! We're excited to support the new model in @visionagents_ai 🎉

Curious about the timings more than the accuracy. Do you get word level timestamps out of it? That's what decides whether a transcript survives being turned into subtitles in another language.

Czech mentioned 🇨🇿

Is it available through Live Transcribe app?

Let's Go! pumped to try this model out as part of my voice agent pipeline.

So it's basically Wispr Flow ? That's nice.

Transcription is unglamorous and load-bearing for anyone cutting dialogue. The thing worth knowing is how it handles overlapping speech, because that is where every previous model has given up.

Good model, wrong queue. The Pro line has not shipped since February 19 while Flash went 3.5, 3.6, 3.7. Transcription was never the bottleneck.

Why isn't it on Gboard???

Phone numbers, postcodes and order IDs is a pointed list. Those are the cases with no semantic prior to lean on, so a language model can't reason its way out of B versus P. Picking that as the headline is a real claim, not marketing.

Every claim here is comparative with nothing to compare against: better at postal codes, better in noise. Better than 3.0, or than Whisper? The noise condition decides a speech result, so a WER at a stated SNR would settle it. Is there a card naming the test sets?

if it survives two people talking over each other on a bad call, then ok

Phone numbers, postal codes, and order IDs are where speech-to-text stops being a demo. Anyone can transcribe a clean podcast. The unglamorous win is a support call with a 16-digit ID in restaurant noise, because that string is the primary key. If Gemini 3.5 Transcribe gets those right, it belongs on the write path of tickets and orders, not in a subtitle sidebar.

Please improve here google, its very important for us

Espero que chegue no YouTube, porque a legenda do YouTube é bem genérica e imprecisa. Eu, pessoalmente, prefiro a legenda à dublagem automática.

finally. transcription demos are perfect until the customer has a surname, an order id, or a product with a stupid name.

Custom vocabulary, filler word removal, and accurate transcription in noisy environments covers the three biggest pain points in speech-to-text. How does it hold up against Whisper and Assembly AI on technical jargon and accented speech specifically?

billions in R&D just so you don't have to listen to your friends talk

🙋♀️ can you format the transcript differently? For example, like a court transcript/multi person conversation?

Transcription gets much more useful when the model understands the conversation, not just the words.

Now add computer vision for sign language to make it truly multimodal and multilingual!

theres nothing faster than cpu level fast and you know that only for reliable low latency internet will this work right?

Gemini 3.5 Transcribe likely leverages streaming decoding with aggressive quantization to keep latency ultra‑low for real‑time transcription.

语音转写模型上线企业流程时,识别率之外真正决定体验的是三件事:说话人分离在会议超过 6 人时是否稳定、专有名词/术语能不能靠 hint 或 vocabulary 灌进去、以及事后编辑修正能不能反哺定制词典。这些环节没打通,Word Error Rate 再低也接不上业务。

Conditioning audio transcription on active workspace state (open buffers, variable names, and agent thoughts) fundamentally solves the biggest pain point in voice coding: camelCase and obscure file path hallucinations. Generic STT models always struggle with domain-specific codebase jargon without that contextual prior.

Impressive accuracy for technical jargon. It's a vital improvement, especially considering the 2023 disaster where a major automated transcription error during a T-Mobile earnings call led to widespread market confusion over their dividend payout figures

What’s the pricing per hour ?

2.6% of words come out wrong on recordings, 4.0% when it's live. google says the final text shows up 70% faster than chirp 3.