Загрузка видео...

Не удалось загрузить видео

На главную

GLM-5.3-Flash (320B MoE) serving on Kaggle's free TPU: ~64 tok/s, 262k context. No stack could run this model on a TPU, so I wrote a JAX engine for it: 3-bit experts (from Unsloth AI) in HBM; Pallas kernels decode them inside the matmul. Z.ai Kaggle
107,726 просмотров • 11 дней назад •via X (Twitter)

Комментарии: 29

Фото профиля Abdur Rahim
Abdur Rahim11 дней назад

Kaggle Notebook:

Фото профиля Rahman Qureshi
Rahman Qureshi10 дней назад

@UnslothAI @Zai_org @_ARahim_ Rahim bhai, your GLM-5.3-Flash TPU notebook is fire 🔥 Can you please make one for uncensored models too? Especially Qwen3.8-27B and an uncensored version of GLM-5.3 Flash. Would be super useful! 🙏

Фото профиля JeffersonNunn.eth
JeffersonNunn.eth10 дней назад

@UnslothAI @Zai_org I, uh, wait what? Like … these are words that shouldn’t go together. WOW

Фото профиля Abdur Rahim
Abdur Rahim10 дней назад

@UnslothAI @Zai_org Thanks ✌🏻

Фото профиля Karol Olszacki
Karol Olszacki10 дней назад

@UnslothAI @Zai_org Finally a good model running on Google's TPUs 😅

Фото профиля Abdur Rahim
Abdur Rahim10 дней назад

@UnslothAI @Zai_org Thanks. In case you missed it, Qwen3.8-27B in bf16 also runs super fast.

Фото профиля Vasko
Vasko10 дней назад

@UnslothAI @Zai_org guys someone hire this guy cuz theres no fucking way this is so cool

Фото профиля Abdur Rahim
Abdur Rahim10 дней назад

@UnslothAI @Zai_org Haha, thanks.

Фото профиля 0xSero
0xSero10 дней назад

@UnslothAI @Zai_org Wow

Фото профиля Abdur Rahim
Abdur Rahim10 дней назад

@UnslothAI @Zai_org Thank you 😍

Фото профиля man wei
man wei10 дней назад

@UnslothAI @Zai_org This is wild. Just saw the notebook is public — 320B MoE on free Kaggle TPU. Forking this weekend to try it out. Thanks for sharing ~

Фото профиля Abdur Rahim
Abdur Rahim10 дней назад

@UnslothAI @Zai_org Thanks. I'd appreciate any feedback you might have after trying it.

Фото профиля Dominik Gstöhl
Dominik Gstöhl10 дней назад

@UnslothAI @Zai_org bro thinking around 2 corners

Фото профиля internet user
internet user10 дней назад

@UnslothAI @Zai_org Can it run DSv4.1 Flash?

Фото профиля Abdur Rahim
Abdur Rahim10 дней назад

@UnslothAI @Zai_org To my knowledge, not yet. But I am working on that. My TPU quota for this week is gone! So I will resume working on that next week. Let's hope for the best.

Фото профиля Squiggles
Squiggles10 дней назад

@UnslothAI @Zai_org Based based based

Фото профиля Jigs
Jigs10 дней назад

@UnslothAI @Zai_org Wow, that's cool

Фото профиля Emircan ERKUL
Emircan ERKUL10 дней назад

@UnslothAI @Zai_org How long does their free credit last for this? 10m?

Фото профиля Abdur Rahim
Abdur Rahim10 дней назад

@UnslothAI @Zai_org It's not "free credits". It's a fixed 20 hours per week for a verified Kaggle account.

Фото профиля Emircan ERKUL
Emircan ERKUL10 дней назад

@UnslothAI @Zai_org Aha 20h/w is really good. I'll try

Фото профиля Yicheng Xia
Yicheng Xia10 дней назад

@UnslothAI @Zai_org No wonder Kaggle TPU queue is longer than ever these days

Фото профиля Abdul Rehman
Abdul Rehman10 дней назад

@UnslothAI @Zai_org W

Фото профиля Lemon🇹🇷🇵🇰🇵🇸🇸🇩
Lemon🇹🇷🇵🇰🇵🇸🇸🇩10 дней назад

@UnslothAI @Zai_org Crazy

Фото профиля thaypley
thaypley10 дней назад

@UnslothAI @Zai_org oh wow.. on my way to check this out!

Фото профиля Petr Glaser
Petr Glaser10 дней назад

@UnslothAI @Zai_org Would be great to have abliterated models or cyber-specialised models there! Do I need to do anything specific with HF model to let it run there?

Фото профиля No Body
No Body10 дней назад

@UnslothAI @Zai_org wtf this sounds cool why am i a rookie and never never heard of this

Фото профиля Rahman Qureshi
Rahman Qureshi10 дней назад

@UnslothAI @Zai_org You are crazy man

Фото профиля chotu
chotu10 дней назад

@UnslothAI @Zai_org Free tpu for everyone ?

Фото профиля Abdur Rahim
Abdur Rahim10 дней назад

@UnslothAI @Zai_org Yes, if you have a verified Kaggle account, you'll have 20 hours of TPU usage per week, free.

Похожие видео

Qwen3.8-27B running at full BF16 on a free Kaggle TPU is kind of ridiculous. No quantization. No tiny context window. No expensive GPU instance. Just Qwen3.8-27B running on a Kaggle TPU v5e-8. The reported numbers: ~130 tok/s decode ~10,000 tok/s prefill 262K context That prefill number is especially wild. You can throw a huge amount of code or context at the model and ingest it extremely quickly, while still getting around 130 tokens per second during generation. And because it’s running in full BF16, you’re not relying on an aggressive quant just to make the model fit. But the really interesting part isn’t even the raw throughput. You can expose it as an OpenAI-compatible endpoint. That means you can plug the model into tools that already understand OpenAI-style APIs. Claude Code. Codex. OpenCode. And other compatible clients. So the workflow becomes pretty simple: Spin up the Qwen3.8-27B endpoint on Kaggle. Point your coding tool at the API. And suddenly you have a 27B coding model sitting behind the same interface you’d normally use for hosted models. The 262K context is also a huge deal for agentic coding. Large repositories can fit into a single context. Long conversations don’t need to be constantly trimmed. And tools can feed much more information back to the model without hitting a tiny context ceiling. The fact that this can be built around a free TPU environment is what makes this especially interesting. We’re getting to a point where experimenting with serious open models doesn’t always require owning a $2,000 GPU or paying for a large cloud instance. Free compute + open weights + an OpenAI-compatible API + existing coding agents. That’s a pretty powerful combination. Qwen3.8-27B is already an interesting model. Running the full BF16 version at ~130 tok/s with 262K context on free Kaggle TPU compute makes it a lot more interesting.

FHILY👑

35,794 просмотров • 20 дней назад

glm 5.3 flash is 7.5x cheaper, but 3.4x slower than gemini 3.7 flash Z.ai glm 5.3 flash – shipped aug 26, $0.07/$0.25 per 1m Google DeepMind gemini 3.7 flash – shipped aug 13, $0.38/$1.88 per 1m we put the two models on one job: write one html file that draws an animated 3d scene in the browser. no images, no downloads, and it has to look the same on every load. the setup: three scenes – a glass aquarium in a lit room, the solar system, a night city under a thunderstorm. identical brief word for word, reasoning effort high, 64k output cap. the numbers below are not the whole run. they cover the three scenes we kept – the best one per task from each model, the ones in the video. - total generation time for the three scenes #1 gemini 3.7 flash – 10m 36s #2 glm 5.3 flash – 36m 30s - tokens spent on those three scenes #1 glm 5.3 flash – 110k #2 gemini 3.7 flash – 111k - cost of those three scenes #1 glm 5.3 flash – $0.027 #2 gemini 3.7 flash – $0.202 observations: • glm's first 10 attempts: 7 blank pages. it kept inventing short random helpers and forgetting to define one of them. the fix was one line in the brief: use exactly one random helper, named rand(), and don't invent shorthands next to it. next 12 attempts: 11 alive, 0 crashes. • glm spends 66% of its output on reasoning, gemini 57%. that is the whole speed gap. • gemini's storm came back as a black rectangle in 4 of 6 runs. glm's best storm has a branching bolt, lit rain and wet asphalt – for $0.01. conclusion: same three scenes, same token spend – glm 5.3 flash billed $0.027 and took 36m 30s, gemini 3.7 flash billed $0.202 and took 10m 36s. glm wins gemini on price and made the best storm of the whole run follow thehype. for 24/7 ai news, analysis and breakdowns

thehype.

15,997 просмотров • 1 месяц назад

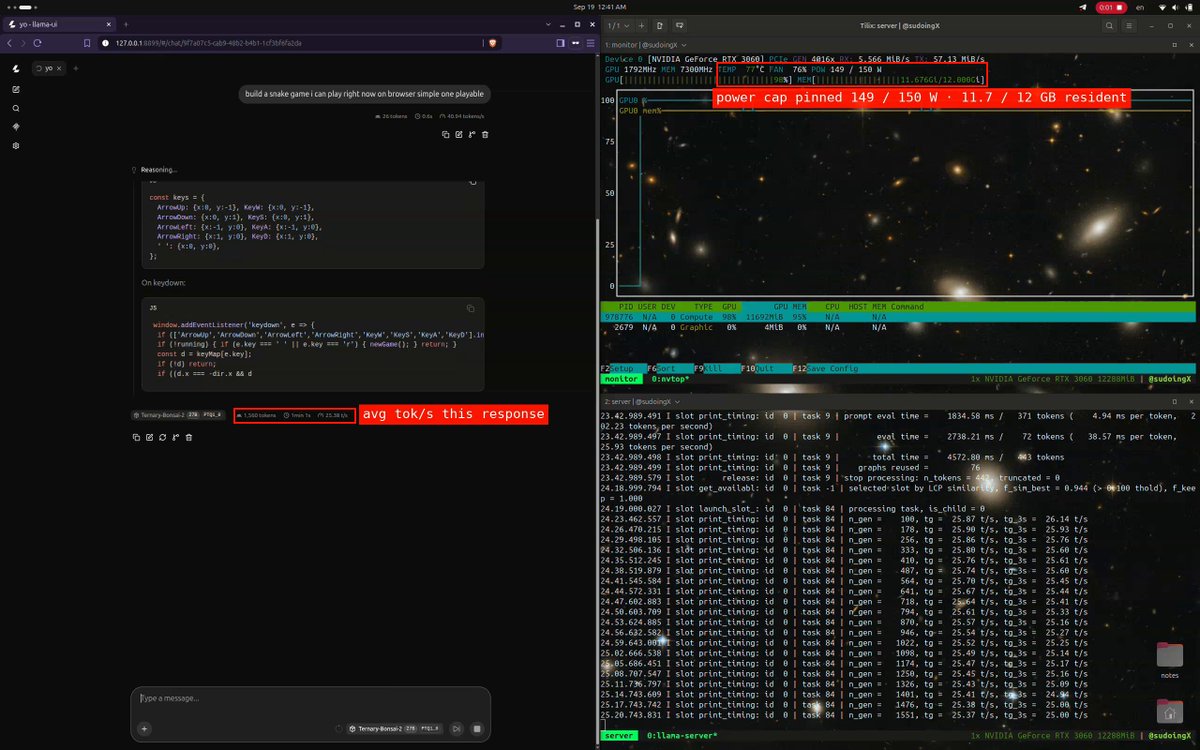
bonsai 2 27b on an rtx 3060 12gb, the full receipt sheet. save this one, the 12gb row of the small gpu guide is built from it. speed by depth, then what context costs, live server, thinking on, real sessions > 7k deep: 24.4 tok/s > 12k deep: 21.9 tok/s > 35k deep: 17.8 tok/s > 77k deep: 13.0 tok/s > 64k window: 7.3gb resident > 128k window: 8.8gb resident > 192k window: 10.2gb resident > 262k window: 11.7gb resident, 0.6gb to spare, the whole native window on a 12gb card > every 64k of context costs 1.47gb, so 327k would not fit > a 41,312 token build session from 35k to 77k of context averaged 15.0 tok/s across 46 minutes > prefill 295 tok/s at 2k of context, 243 tok/s at 35k, first token in 0.6 seconds, fresh decode 26.1 tok/s > the card pinned 149 of 150 w the entire time, 78c, fan at 80%, power bound, not heat bound > 0.158 tok/s per watt at the fresh end the setup > model: ternary bonsai 2 27b, PTQ1_0, 1.75 bits per weight, 5.95gb on disk, base qwen 3.8 27b, apache 2.0 > runtime: prismml llama.cpp fork, prebuilt cuda 12.4 binary, no compile > serve: full 262k native window resident, q4 kv cache, flash attention, one slot, 11.7 of 12gb in use for anyone who followed bonsai 1 in july, that was the 3.9gb 1bit file at 42 tok/s on a 3060 ti, a faster card and a smaller file, so the same card comparison is not on the table yet, it comes with the 8gb test. what changed is the base, qwen 3.8 instead of 3.6, and the retention, 98.2% on their suite instead of 95%, and the whole 262k window fitting on 12gb.

Sudo su

31,174 просмотров • 7 дней назад

glm 5.3 vs qwen 3.8 vs gemini 3.7 vs deepseek v4 flash four models designed and built three structures each on a physics-backed site, with no dimensions anywhere in the brief the setup: our own agent loop on OpenRouter, a construction site as the tool set – footings, walls, arches, roofs, scaffold, a lamp. the site enforces physics and nothing else: unsupported brick falls, a roof needs walls under it, a worker reaches 3.2 m above whatever he stands on, an arch needs centring until the keystone is set, concrete cures before it carries. no budget ceiling – material cost is tallied and reported, never blocked. tasks: 1. house – a plot and a palette, no plan. shape, height and material are the model's call 2. lighthouse – a headland cut by a gully, with a rock stack standing 30 m offshore. the lamp must burn, it must be the highest thing built, and the keeper must be able to walk to it 3. bridge – a river with one islet and banks at different heights. cross it however you want models: Z.ai glm 5.3 flash, Qwen qwen 3.8 flash, Google DeepMind gemini 3.7 flash, DeepSeek v4 flash vision all twelve objects were finished and signed off by the models themselves. tallest lighthouse is qwen's at 38.4 m, planted on the offshore stack with a bridge run out to it – the only model that read the site that way. deepseek signed off its bridge on an empty riverbed: 0 bricks, 107 minutes, $1.16m of material tallied - total cost, three builds #1 glm 5.3 flash – $0.201 #2 gemini 3.7 flash – $0.871 #3 qwen 3.8 flash – $1.058 #4 deepseek v4 flash – $1.567 - wall clock, three builds #1 gemini 3.7 flash – 91m #2 glm 5.3 flash – 228m #3 deepseek v4 flash – 502m #4 qwen 3.8 flash – 912m - total tokens #1 gemini 3.7 flash – 3,567,052 #2 glm 5.3 flash – 4,732,748 #3 qwen 3.8 flash – 13,469,333 #4 deepseek v4 flash – 18,230,076 - defects logged by the site #1 deepseek v4 flash – 59 #2 gemini 3.7 flash – 132 #3 glm 5.3 flash – 221 #4 qwen 3.8 flash – 350 - material tallied across three builds #1 gemini 3.7 flash – $359,884 #2 glm 5.3 flash – $583,358 #3 deepseek v4 flash – $1,327,484 #4 qwen 3.8 flash – $2,188,625 observations: • glm is the cheap one and nothing here is close – $0.201 for three buildings, $0.042 per million tokens, 6x under gemini's rate • what glm spends it on is bulk, not care: 166,228 bricks in one house and 156 defect weight, the worst single object in the set • gemini is the efficiency line – 91 minutes and 3.57m tokens for all three and an eighth of qwen's clock • gemini also builds the smallest of everything. its lighthouse is 22.5 m against qwen's 38.4, its house 6.9 m against 19.3 • qwen is the maximalist: 1.18m bricks, $2.19m of material, tallest on all three tasks, and 912 minutes – 15 hours – to get there conclusion: twelve finished objects for $3.80 all in, and a 7.8x price spread between the cheapest model and the priciest! follow thehype. for 24/7 ai news, analysis and breakdowns

thehype.

26,360 просмотров • 28 дней назад