Video wird geladen...
Video konnte nicht geladen werden
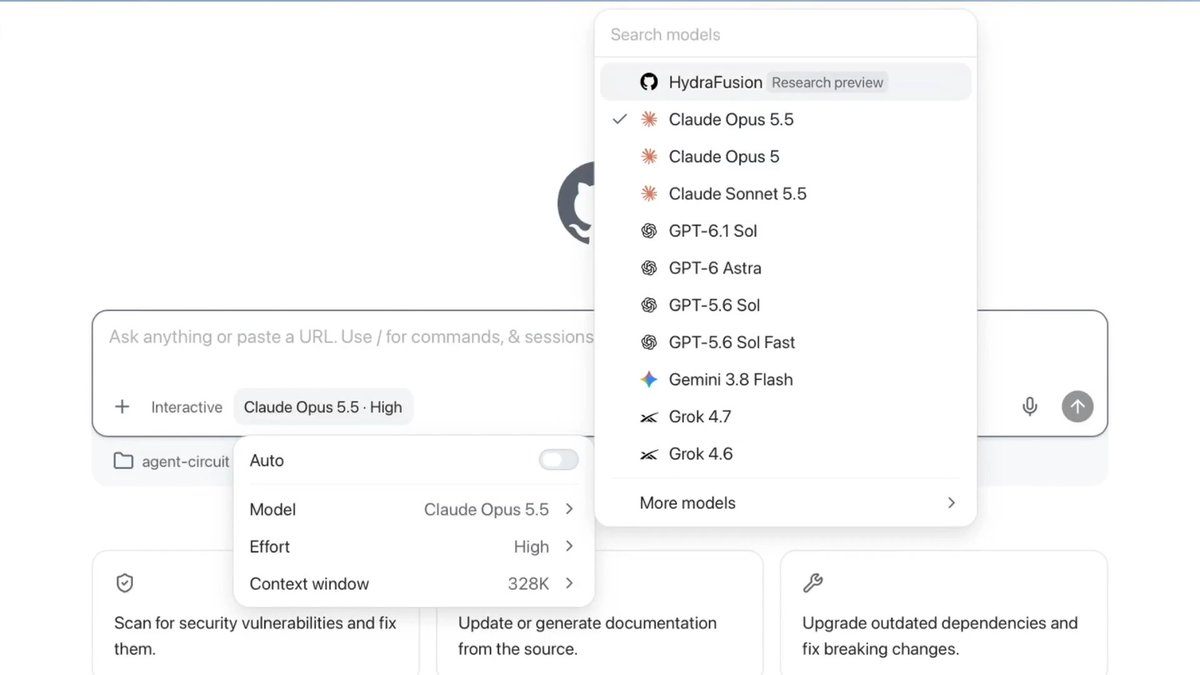
Introducing Critique, a new multi-model deep research system in M365 Copilot. You can use multiple models together to generate optimal responses and reports.
1,393,888 Aufrufe • vor 6 Monaten •via X (Twitter)
34 Kommentare

Benchmarks show this delivers best-in-class deep research!
Available today in Frontier:

Hasn’t $PLTR been doing this for years with K-LLMs in AIP?

introducing Critique: because when one AI hallucinates, the solution is obviously to add more AIs to vote on which hallucination sounds most professional

People with Copilot:

The way Microsoft keeps pumping out products pretending they are useful is just crazy! Single handedly the biggest inability to read the room.

how many fucking copilot models are you going to come out with jfc

Oh great, more AI to make everything even worse. I can't wait for this bubble to pop. I'm so sick of slop.

Nobody wants this garbage, no one wants to read ai generated slop How about getting the regular stuff like file search working for starters

Great! I still think Copilot needs a rebranding.

Stop playing with slop and get to work

Microsoft launching ‘new’ Copilot features

"GPT responses, refined by Claude" is the real headline. the critique layer might matter more than the generation layer.

hey sat. is it good yet? once it’s good i’ll review it and turn the x tide. just lmk.

If I ask your pile of shit to make a pivot table, I expect it to happen, not “optimal responses” and reports. Give me the bare-arse basics to begin with and cut the shit. Speak plainly, you dummy.

Built a version of this. Synode runs multiple AI models on the same question simultaneously. No deep research support yet. Local LLMs, bring-your-own-keys, Telegram messaging. Native desktop app for macOS and Windows. Open source:

Bro, nobody needs conpilot and microslop stuff. Do you know the reason why market researches and business intelligence exist?

Copilot 2023 vs Copilot 2026

this multi model critique thing is overhyped. its just layering models to fix what one should do. our dev team benchmarked it yesterday and accuracy only up 15% while query time doubled. does msft plan to eat the extra compute cost for enterprise users?

You can stop pushing this slop, we've had just about enough, thanks.

Can you find a way to incentivize this for creators on X ? Because we all use AI to enhance our work flows either one way or the other. Someone was pointing to Elon musk about doing it with Grok here on X. Especially, to utilize the usage of AI tools in creative workflows for the purpose of also earning creators revenue. He ignored ! Microsoft can take the chance. Cause it is right here !

How can I fully remove Copilot so it doesn't keep nagging me to use it, as I'm forced to use Microsoft products at work.

Just fix your damn OS before working more on this #slop

Looks strong on benchmarks, but I wonder how it holds up when the research spans messy real-world data versus clean test sets. Anyone seeing latency tradeoffs yet in actual use?

I just tried to get Copilot to make a slide in Powerpoint. It said it did, click here to get it, and nothing. I told it that, it apologized and said here it is, not there. 4 tries later, I got it and it looked like a crayon eating child had made it. Oh... and quit firing Americans to hire H1Bs and Indians.

Enough with the Microslop already!

First you name a product Foundry… and now this??? 😵

using claude as a dedicated fact checker for gpt is such a brutally funny dynamic. microsoft basically invested billions into openai just to realize they still needed anthropic to actually trust the output. the orchestration layer is literally the only place where value is going to accrue this year. how many of you were already doing this manually in two separate browser tabs anyway?

interesting,

The architectural choice here says more than the benchmark. Microsoft separated generation (GPT) from evaluation (Claude), meaning every Researcher output gets fact-checked by a competitor's model before delivery. On DRACO, the multi-model Critique scores 57.4, a 13.8% lift, but still trails Perplexity Deep Research at 70.5. The real edge isn't the score. It's that Researcher connects to Salesforce, ServiceNow, and Confluence data that no standalone deep research tool can touch. With only 3.3% of M365's 450M seats paying for Copilot, this is Microsoft's play to convert the other 435 million, using multi-model trust as the wedge.

Multi-model deep research is the future. Exciting to see Microsoft pushing Agent capabilities even further.🧐

This is a game-changer! "Critique" in Microsoft 365 Copilot — orchestrating multiple AI models for deep, multi-perspective research reports — feels like the true leap toward agentic AI in the enterprise. Love how it builds on Researcher/Analyst agents, turning hours of competitive analysis or strategy prep into minutes with better accuracy and balanced insights. Smarter workflows, fewer blind spots, and grounded in our M365 data. Excited to test this for complex decision-making. What's the rollout timeline? India’s tech ecosystem (especially in cloud & AI) is ready to adopt this at scale! 🇮🇳 #MicrosoftCopilot #AICritique #FutureOfWork

Focus less on copilot and more on making Windows 11 not a complete piece of shit

Tested copilot in my org last week and it's so damn bad It should be considered highway robbery to charge people for it. Asked it to check my inbox and give me a Todo list(I only have 25 emails in my inbox) and it pulled shit up that's been deleted for weeks. Garbage software