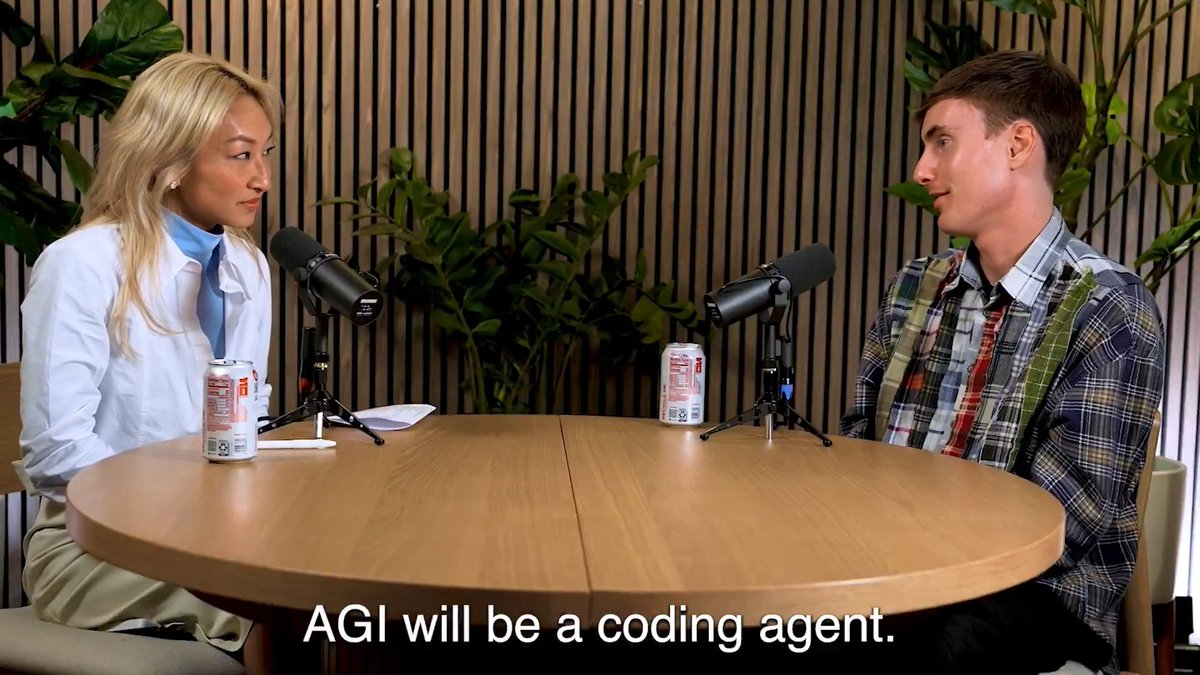
Video yükleniyor...
Video Yüklenemedi
Introducing Scorers: Agents that grade your agents. Use LLM-as-a-judge to grade past coding agent sessions on: • Quality • Efficiency • Compliance • Or any custom dimension Scores feed into performance measurements and automatic self-improvement for software factories
193,674 görüntüleme • 6 gün önce •via X (Twitter)
15 Yorum

agents grading agents feels like the point where i stop fully understanding my own pipeline, in a good way i think

But who grades the grading agent? 🤔

Scorers need a receipt next to the grade: session id, task, repo state, judge prompt, rubric version, failing span, and fix commit. Otherwise the agent learns to please the grader instead of improving the work.

Start from a record of agent conversations you want to grade. In Warp Factories, all agent runs are tracked across your team with agent traces, artifacts, and code output. You can score all of your agent runs, or define a sampling you want to test (ex. frontend tasks)
Then, create your scoring agents. These analyze individual conversations and give them a grade. Scorers follow rubrics that you define. Here's a "redundant test" scorer we use internally to judge the quality of tests that our agents write: 🔖
There are many different scorers that you can define. These are the ones we'd start with: Compliance: did the agent complete the task per the user’s request? Efficiency: did the agent complete the task efficiently, or did it do a bunch of unnecessary work? Verbosity: did the agent write succinct code with clear code comments, or was the output unnecessarily elaborate? Quality: for a coding task, was the quality of the code good? Did it match expected conventions?
Then, aggregate scores to view success and failure trends overtime. This helps observe regressions and track improvements as you ship changes to your factory. Here you can see dips in our redundant test quality, with visibility into failed runs for deeper investigation:
Finally, use these metrics to have agents suggest improvements to your setup automatically. Self-improvement agents run on a schedule and review failing grades to suggest changes to your setup. Here is an example agent skills PR with evidence cited from previous scoring runs:
If you want to set this up, scoring is part of Warp Factories in early access. We are offering up to $10k in usage to qualified companies. 🔖

I’d score agents on recovery too, not just final output. The useful signal is whether they notice a bad tool result and tighten the next step instead of plowing ahead.

Warp - how quickly does a score change the next run?

self-improvement loops that only score the last run are still theater if the agent can be silently relaunched empty.

I do not know what Warp had to do that would convince me to use it. I do not see the benefit in using Warp, not a single one. This does not convince me at all.

A scorer is only as useful as its holdout. If the judge rewards the same visible heuristics the agent optimizes, self-improvement just trains better rubric gaming. Keep a few adversarial tasks out of the loop.

scoring quality, efficiency, and compliance in one loop feels like the missing layer for making agent runs measurable.