Загрузка видео...
Не удалось загрузить видео
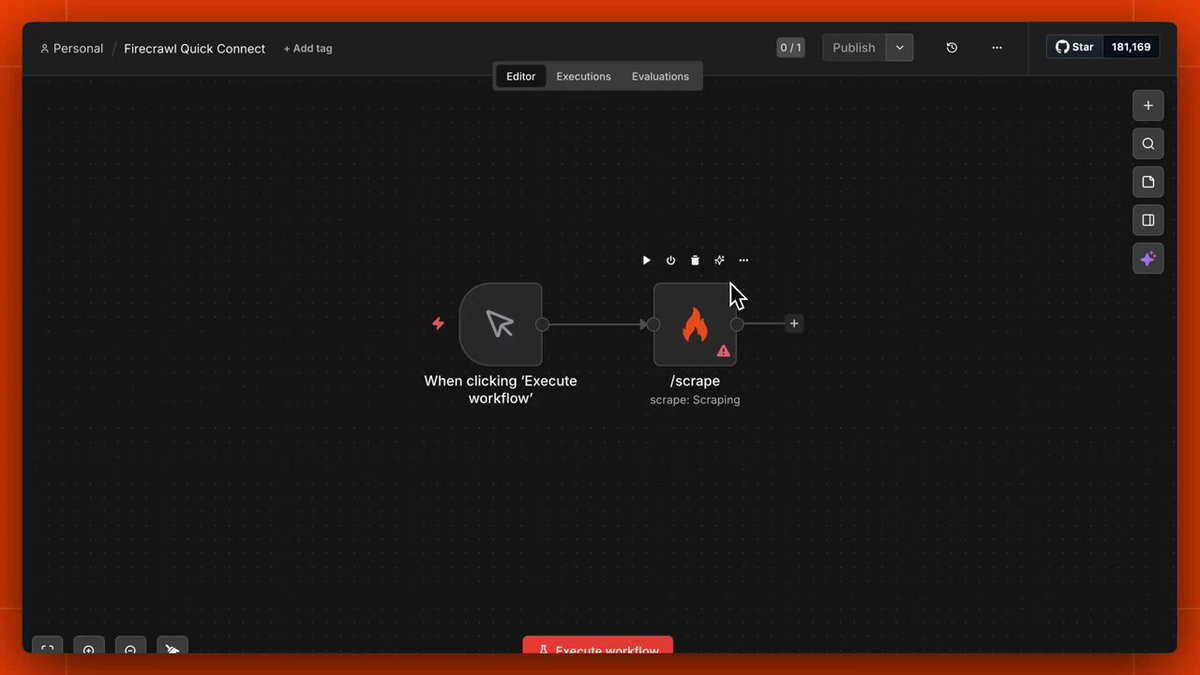
Introducing Universal Scrape. Give your agents context from web pages, PDFs and images + people profiles, financial data, podcasts and beyond. Access any data from the web, files, & 200+ providers powered by Alexandria, all with one API.
80,249 просмотров • 9 дней назад •via X (Twitter)
Комментарии: 25

Why do you keep releasing new products when you could just make your existing product better?

there’s no better way to scrape

ALL THE DATA

@juampitech Lfg

scrape it all

are you guys on steroids!? i have been thinking about building a protocol that changes the way artifacts are fetched on the internet in today’s world. w the advancements across ai and tooling i figured we need a better way to query and fetch resources on the internet as well.

give me all the data

does the response tell the agent when each page was fetched, or can cached data look identical to fresh? that decides whether i'd trust it for financial stuff

Does this include originally blocked sources like social sites..?

food for thought. or for agents :)

Can I request some credits pls!!!

@grok can this feature scrape twitter account ?

Ready to scrape the back end of Alexandria 🫡

thought this was cloudflare for a second

please keep a backup of Alexandria this time

one API to feed your agents everything they need ser

cool tool for data bro hehe

Universal Scrape looks incredibly powerful

I run a small version of this for people profiles: 2 providers behind one API. the surprise was the misses. one bills a profile it can't find ($2.30 per 1,000), the other doesn't. across 200 providers, who pays for a miss, the agent or you?

The issue is you need to have paid access to a number of sources referred to here. Plus LinkedIn is on major lockdown for any tools that it detects, including AI. Free sources though, yes.

You guys keep cooking omg

pulling together all that data into one API could save teams a ton of time

Congrats. Firecrawl is one of the tools our agents reach through Scrollport, so more behind one scrape call is good news on our side. Will run it on a lead-list job and post what it does.

context in is basically solved. context out, as in what it means, is still wide open

Agents are going from reading PDFs to catching up on podcasts, busy schedule