Video yükleniyor...

Video Yüklenemedi

Ana Sayfaya Dön

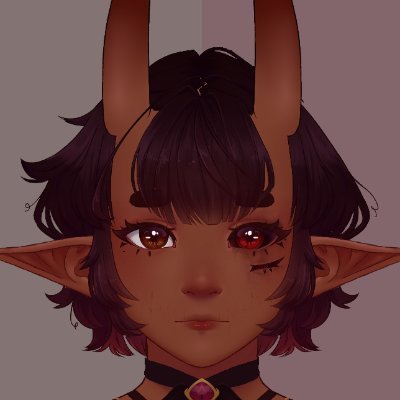
It's always been this easy to edit the normals into a more 2D style and i've only just figured it out 🥲 no more concave eye shadows 🙏 Alt+N > Copy Vectors > Paste Vectors #blender
39,161 görüntüleme • 2 yıl önce •via X (Twitter)

8 Yorum

Ponrayne profil fotoğrafı
Ponrayne2 yıl önce

How does this look for the end product? It looked like it made the brows more floaty

RainHet ~*~ VRC/Vtube Comms ~*~ profil fotoğrafı
RainHet ~*~ VRC/Vtube Comms ~*~2 yıl önce

The eyes will look flatter instead of caverns. But only when shader is set up for it

Frogpotato profil fotoğrafı
Frogpotato2 yıl önce

I've been constantly learning photoshop for over 10 years and I still find new things, I expect to be learning blender for my whole life 😅could you explain a bit more the principle behind the vectors and the normals and how that relates to shading for us rookies in the back pls?

RainHet ~*~ VRC/Vtube Comms ~*~ profil fotoğrafı
RainHet ~*~ VRC/Vtube Comms ~*~2 yıl önce

It allows you to force Impossible shading so you can create more 2d looking lighting instead of being forced by the shape of your model :) for example the eyes will look flat instead of concave

SylviaCrisp profil fotoğrafı
SylviaCrisp2 yıl önce

There something similar that I do with fur, where I use a Data Transfer modifier and use a vertex group gradient to blend in the fur into the main mesh.

LEMONADE TANTRUM profil fotoğrafı
LEMONADE TANTRUM2 yıl önce

If you want an addon for helping to take even more full control of the normals, the addon on GitHub called "Abnormal" recently just got updated for the newest version of blender. It adds whole new layout just entirely for editing the vertex and face vectors on your mesh!

Lun🍓 profil fotoğrafı
Lun🍓2 yıl önce

This will be very useful for the fucked up shading on my lashes, thanks!

Sky “Moon★Moon” Moonquan profil fotoğrafı
Sky “Moon★Moon” Moonquan2 yıl önce

There’s also a free add on (which I can’t remember the name rn, I’ll add it when I figure it out) that can help with normals for a npr look where you select your mesh > select the normals style > press enter and done lol

Benzer Videolar

[CLIP] by Hand ✍️ The CLIP (Contrastive Language–Image Pre-training) model, a groundbreaking work by OpenAI, redefines the intersection of computer vision and natural language processing. It is the basis of all the multi-modal foundation models we see today. How does CLIP work? Goal: 🟨 Learn a shared embedding space for text and image [1] Given ↳ A mini batch of 3 text-image pairs ↳ OpenAI used 400 million text-image pairs to train its original CLIP model. Process 1st pair: "big table" [2] 🟪 Text → 2 Vectors (3D) ↳ Look up word embedding vectors using word2vec. [3] 🟩 Image → 2 Vectors (4D) ↳ Divide the image into two patches. ↳ Flatten each patch [4] Process other pairs ↳ Repeat [2]-[3] [5] 🟪 Text Encoder & 🟩 Image Encoder ↳ Encode input vectors into feature vectors ↳ Here, both encoders are simple one layer perceptron (linear + ReLU) ↳ In practice, the encoders are usually transformer models. [6] 🟪 🟩 Mean Pooling: 2 → 1 vector ↳ Average 2 feature vectors into a single vector by averaging across the columns ↳ The goal is to have one vector to represent each image or text [7] 🟪 🟩 -> 🟨 Projection ↳ Note that the text and image feature vectors from the encoders have different dimensions (3D vs. 4D). ↳ Use a linear layer to project image and text vectors to a 2D shared embedding space. 🏋️ Contrastive Pre-training 🏋️ [8] Prepare for MatMul ↳ Copy text vectors (T1,T2,T3) ↳ Copy the transpose of image vectors (I1,I2,I3) ↳ They are all in the 2D shared embedding space. [9] 🟦 MatMul ↳ Multiply T and I matrices. ↳ This is equivalent to taking dot product between every pair of image and text vectors. ↳ The purpose is to use dot product to estimate the similarity between a pair of image-text. [10] 🟦 Softmax: e^x ↳ Raise e to the power of the number in each cell ↳ To simplify hand calculation, we approximate e^□ with 3^□. [11] 🟦 Softmax: ∑ ↳ Sum each row for 🟩 image→🟪 text ↳ Sum each column for 🟪 text→ 🟩 image [12] 🟦 Softmax: 1 / sum ↳ Divide each element by the column sum to obtain a similarity matrix for 🟪 text→🟩 image ↳ Divide each element by the row sum to obtain a similarity matrix for 🟩 image→🟪 text [13] 🟥 Loss Gradients ↳ The "Targets" for the similarity matrices are Identity Matrices. ↳ Why? If I and T come from the same pair (i=j), we want the highest value, which is 1, and 0 otherwise. ↳ Apply the simple equation of [Similarity - Target] to compute gradients of for both directions. ↳ Why so simple? Because when Softmax and Cross-Entropy Loss are used together, the math magically works out that way. ↳ These gradients kick off the backpropagation process to update weights and biases of the encoders and projection layers (red borders).

Tom Yeh

67,896 görüntüleme • 2 yıl önce

In 2006, Netflix offered $1,000,000 to anyone who could improve their recommendation algorithm by 10%. Over 2,000 teams competed for three years. The team that won did not use more data. They used fewer dimensions. They found a basis - a small set of independent vectors that captured everything important about 100,000,000 movie ratings. The lead mathematician on the winning team: $2,800,000 a year. A machine learning engineer at Spotify building the same kind of system: $245,000 a year. This is MIT 18.06, Lecture 9 - Gilbert Strang. Free on YouTube. Most people think independence is obvious. Two vectors pointing in different directions. Then the definition. Independence means no combination of your vectors gives the zero vector - except the trivial one where all the coefficients are zero. That's it. That's the whole definition. But watch what it unlocks. Watch the moment Strang puts three vectors in a two-dimensional plane. He doesn't even tell you which three vectors. He just draws them. And immediately says: dependent. No question. No calculation. Why? Because three vectors in two-dimensional space means more columns than rows. More unknowns than equations. That always forces a free variable. A free variable always gives a non-zero solution to Ax = 0. And that non-zero solution is a combination of the columns that produces zero. Dependence. "Three vectors in the plane have to be dependent. That's the key fact." Then the basis. A basis is vectors that are independent and span the space. Not too few, not too many. Just right. The pivot columns of any matrix form a basis for the column space. Every other basis you can think of will have exactly the same number of vectors. Then the dimension. All bases for the same space have the same number of vectors. That number is the dimension. The rank of a matrix is the dimension of its column space. The number of free variables is the dimension of the null space. And rank plus null space dimension equals the total number of columns. "I don't take the dimension of A. I take the dimension of the column space of A. If you use those words right, it shows you've got the idea right." A data scientist at Netflix building recommendation engines: $230,000 a year. A quantitative researcher at Two Sigma finding independent factors in financial markets: $350,000 a year. A computer vision engineer at Apple using low-dimensional representations for face recognition: $260,000 a year. They all needed to know how many dimensions were really there. bookmark this and watch later - after this lecture every dataset you look at will feel like a matrix waiting to be reduced to its basis.

Zyphor

14,720 görüntüleme • 22 gün önce