Loading video...
Video Failed to Load
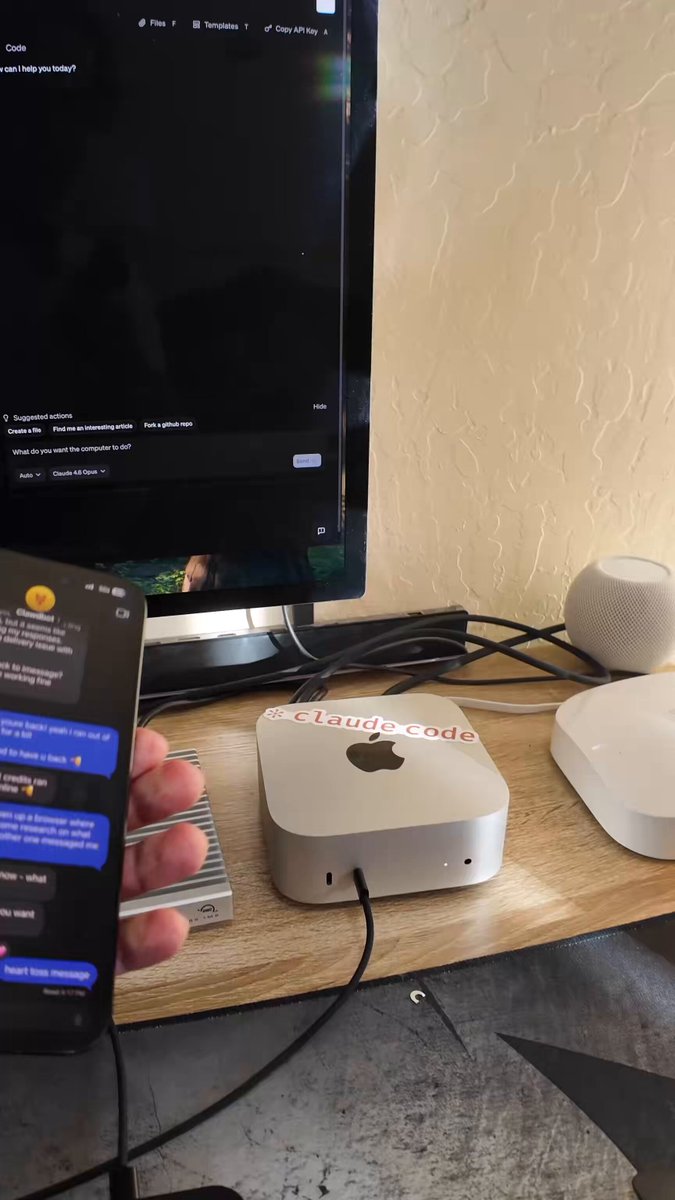
Okay so Jev can actually do computer use really well Without any screenshots, or LLMs and no Pixels leave my mac I dont even read the Dom elements A local CoreML model segments every button and UI element on screen. On-device OCR reads the labels. That text is all... show more

116,719 views • 1 day ago •via X (Twitter)
62 Comments

If this gets enough attention I’ll make it open source. Meanwhile check out my other stuff

I think the future is multiple other companies building new kind of llm models for individual tasks with which you just plug it in with frontiers model for steering and thinking Also domain specific harness and custom trained models with your data for specific use cases are going be more relevant and we are going to see even more than before
I agree that’s where things are headed

hey man, do you mind doing a test with a local model that uses the same architecture? like this one based on qwen-2.5-1b?
I’ll check it out

very cool!
Thank you!

wow insane, which local model does the window UI segmenting ?
Omniparser!

local segmentation plus OCR instead of a vision model. cuts what you send to the model, and it runs offline too.

Thats very slick. Does it use a larger model to know where to go? So if you ask it something complex to do in Blender for example it can break it down into steps?
There is literally no other larger models being used in this. Its as simple as it gets
Open source when lol
Haha let me clean it up and then I’ll do it promise :D Its based on my other open source project already called tiptour macos
Yea love it, I've been following your work for a while. Thanks for sharing it!

The interesting part is the interface boundary. Segmentation and OCR turn pixels into a compact, structured state before Jev plans an action. That makes local inference practical and keeps the sensitive screen data on-device.

Bro, you build way too fast :D
Thats how I roll :D

chat too

Yes. Share. Also, should go into OMB, will create a really good setup.
Great idea

Can you add voice to text on top so you can control it with your voice
Totally i can

SupaaaaFastttt computer use

I would love to use this and test it out
What are you using for on-device OCR
Apple ships it natively on all devices

90ms local loops make 5-second cloud VLM latency look unplayable. How does it handle icon-only buttons where OCR finds zero text?

This is really nice!!!!
I know right!!

Dude this is sick, would really love to try this out with some desktop applications!
Alright man. I’ll send it to you when its ready
🙏 much appreciated! btw - love openmaus - got it configured on my machine and made a few tweaks to my system - need to pull some of the latest features you've shipped !
Lfgg

this one can do it too and it's local

Very cool

Loved it, crazy capabilities
Indeed

Make it open source.
Will do

How can it be used to do computer use in bg?
I’m sure @trycua can

Que brutalidade!!! 🤯
Sí!!!

Impliment into maus 🙏🙏🙏
Hell yeah

how does the LM come up with more complex interactions, like in Blender, dragging while holding down buttons?
Gotta pair this with an llm to do that
Message me the details on WhatsApp, I have new investors for the stuff, doing a seed round the coming weeks. Getting the production cost from ~48ct to ~20ct could be realistic with this new tooling.

Dude, I need this!
Releasing soon

+1 for the open source version. Great demo!
Thanks! Repo coming shortly

this is really cool @milindlabs I’ve been trying out Jev for some browser use features as well, here you runs loop with ocr model right ?
I do yes along with the segmentation model

Does it support multi-screen ?
It does

@bot @poteto 😅🤘🏽

open source pls
If you say so

@iamgingertrash how did you know

a click loop without an llm can still own the machine. i am building refuse rules on the write surface so speed never becomes silent permission.