Video yükleniyor...

Video Yüklenemedi

Ana Sayfaya Dön

oMLX 0.7.1.dev1 is out! This dev release adds decision models (Clef, OpenJev), batched prefill for concurrent requests, a refreshed web UI, and faster Qwen3.8, Qwen3.6, GLM-5.3-Flash and DeepSeek V4.1. Speedups in this release - Qwen3.6-35B-A3B decode on M5 Max: 156 -> 205 tok/s (+31%). - GLM-5.3-Flash decode on M3...

24,706 görüntüleme • 9 gün önce •via X (Twitter)

24 Yorum

Frank profil fotoğrafı
Frank9 gün önce

This is rapid. GLM-5.3F Q4/8 on M5U doing ~1900t/s prefill and ~78t/s decode. Impressive.

Jonathan Spangler profil fotoğrafı
Jonathan Spangler9 gün önce

Wow decision model support already . Can't wait to try this .

Ash Hart profil fotoğrafı
Ash Hart9 gün önce

🚀🙌🏻

Code댄스 profil fotoğrafı
Code댄스9 gün önce

오 omlx 만든분을 엑스에서 뵐줄이야. 잘 사용하고 있습니다. 좋은 프로그램 만들어줘서 감사합니다.

Jun Kim profil fotoğrafı
Jun Kim9 gün önce

한국의 oMLX 사용자님 반갑습니다! 감사합니다!

Aleksandar Janca profil fotoğrafı
Aleksandar Janca9 gün önce

the fused decode kernels running on m3 too is the part I care about, my whole coding setup runs on an m3 pro

Arnav Prabhu profil fotoğrafı
Arnav Prabhu9 gün önce

Love oMLX!

Zhibo 𝕏 profil fotoğrafı
Zhibo 𝕏9 gün önce

I love Friday releases! :-)

Andrés- e/acc profil fotoğrafı
Andrés- e/acc9 gün önce

Decode speedups help after you decide to call. The gate that says yes or no is the one I keep on-device; cloud only after that.

Avelyrah profil fotoğrafı
Avelyrah9 gün önce

Impressive performance gains and exciting improvements for local AI

诗 profil fotoğrafı
诗9 gün önce

Good job. Thank you very much

CryptoKCarats profil fotoğrafı
CryptoKCarats9 gün önce

Nice to meet you oMLX…. But the newest release doesn’t load a model for me. None of them. Ceiling raised significantly, plenty of ram available. Still experiences memory max. 0.6.4 loads anything, has endless context, & compresses things well. I can’t say I’m a fan of the update. No work. No bueno.

Jun Kim profil fotoğrafı
Jun Kim9 gün önce

Sorry about that. Could you open a GitHub issue with your logs, or send them to me by email? That would really help me find the cause. Also, could you check if it still happens with the memory guard turned off?

EDDY VU profil fotoğrafı
EDDY VU9 gün önce

Batched prefill for concurrent requests is huge for local throughput, really excited to test this dev build.

T.Rex-Baby profil fotoğrafı
T.Rex-Baby9 gün önce

Excellent work, did you manage to add in the Lazarus branch MLx-VLM for the uncensored DeepSeek V4.1 support or did it not make the list?

Potato Bob profil fotoğrafı
Potato Bob9 gün önce

🔥🔥💪

西里 profil fotoğrafı
西里9 gün önce

不错,又更新了!👍

Adi Jain profil fotoğrafı
Adi Jain9 gün önce

Is it possible to add support for local decision models like lays?

adrian0115 profil fotoğrafı
adrian01159 gün önce

🚀🙏 prolly a dumb question but do we need to redo quantization from BF16 for increased accuracy (vs. the same existing oQe model)?

Jun Kim profil fotoğrafı
Jun Kim9 gün önce

Unfortunately, the existing quants can’t be improved structurally, so they need to be re-quantized. I’ll post on X again once I’ve uploaded the improved oQe quants for the major models to the jundot repo on Hugging Face!

Kev profil fotoğrafı
Kev8 gün önce

And I only just got to this one - More accurate oQe quantization, with 11-15% lower KL to the original model. Any improvement that results in higher quality is awesome. Just need to do some re-quantizing now of oMLX specific variants.

BitAres profil fotoğrafı
BitAres9 gün önce

Does canceling one request leave the other queued jobs running?

Fipco-tech profil fotoğrafı
Fipco-tech8 gün önce

Thanks. oq4e flash models on M3U-256 get speed improvement on Qwen-fn and GLM in tok/s over prior oMLX version. For complex coding task completion, task time also better for Qwen. For GLM-f, less coherent, a bit worse.

Kev profil fotoğrafı
Kev8 gün önce

Thanks so much for adding clear sessions to the dashboard. 🙏 It seems small, it isn't.

Benzer Videolar

Qwen3.8 Flash Next is starting to look ridiculous on Apple Silicon. I’m running the 4-bit MTP build locally on an M3 Ultra Studio, and the latest OMP run hit: 97.1 tok/s decode 23K context ~1,131 tok/s uncached prompt processing That first number is the one that caught my attention. Nearly 100 tokens per second from a local Qwen3.8 Flash Next setup is already fast enough that the usual “local models are slow” argument starts feeling pretty outdated. And the prompt processing speed is even crazier. Over 1,100 tok/s on an uncached prompt means the model can chew through a large amount of context before generation even starts. The setup matters here. This isn’t just Qwen3.8 Flash Next running untouched. It’s a 4-bit quantized build with MTP, and the inference stack is clearly doing a lot of work behind the scenes to make the hardware perform like this. There’s already a PR open for the implementation on oMLX, so this isn’t just a one-off local experiment either. If these optimizations make their way into the broader MLX ecosystem, running large models locally on Apple Silicon gets even more interesting. The other thing I like about numbers like this is that they put the focus back on the entire inference stack. Model size is one variable. Quantization is another. Then you have MTP, KV cache configuration, runtime optimizations and the hardware itself. Change the recipe and the same model can feel completely different. Qwen3.8 Flash Next at ~97 tok/s on an M3 Ultra is a pretty good demonstration of that.

FHILY👑

15,378 görüntüleme • 1 ay önce

The VRAM barrier is officially dead. I just ran Qwen 3.8 Flash Next (MoE) 125B A6B with a 250,000 context window on a single 24GB RTX 4090. 21 tokens/sec decode. 364 t/s prefill. no mtp. no dflash. no kv cache quantization! We are running datacenter models on consumer hardware. Tested on Ubuntu 22 | CUDA 13.0 | PCIe 4.0 x16 | 110 GB DDR4 System RAM with a continuous 28k prompt across all runs. ### The Benchmarks & Scaling # 1. Hybrid Offload (-ncmoe 40 @ 80k Context) Offloaded 40 expert layers to the GPU, pushing VRAM to the ceiling. ./build/bin/llama-server -m Qwen3.8-Flash-Next-UD-Q4_K_XL-00001-of-00004.gguf -c 80000 --port 8080 -v --fit off -b 4096 -ub 4096 -ncmoe 40 Prefill: 383.85 t/s | Decode: 22.52 t/s Footprint: 23.85 GB VRAM | 97 GB RAM # 2. Full CPU MoE Offload (-cmoe @ 80k Context) Pinned all 512 expert layers to DDR4 RAM (-cmoe), keeping attention on the 4090. llama.cpp flags: (Same as above, replace -ncmoe 40 with -cmoe) Prefill: 355.72 t/s | Decode: 20.84 t/s Footprint: 11.66 GB VRAM (12GB+ VRAM freed up!) | 110 GB RAM # 3. The 180,000 Context Run Prefill: 357.75 t/s | Decode: 20.98 t/s | VRAM: 15.6 GB | RAM: 110 GB # 4. The 250,000 Context Absolute Ceiling ./build/bin/llama-server -m Qwen3.8-Flash-Next-UD-Q4_K_XL-00001-of-00004.gguf -c 250000 --port 8080 -v --fit off -b 4096 -ub 4096 -cmoe Prefill: 364.29 t/s | Decode: 20.97 t/s Footprint: 18.3 GB VRAM (Still ~5.7 GB of VRAM headroom!) | 110 GB RAM ### Key Insights: -b 4096 -ub 4096: doubles the prompt ingestion from ~150 to 364+ t/s. -cmoe Free Lunch: Shifting expert layers to DDR4 RAM slashes VRAM from 24GB to 11.6GB with virtually zero decode penalty (22.5 -> 20.9 t/s), enabling the 250k context ceiling. Qwen 3.8 Flash-Next (UD-Q4_K_XL) is a massive 111.4 GB model split across 4 shards. To run this architecture, you must build from the experimental PR branch (#27742) by Daniel Han: git clone && cd llama.cpp git fetch origin pull/27742/head:qwen-next && git checkout qwen-next cmake -B build -DGGML_CUDA=ON -DCMAKE_CUDA_ARCHITECTURES=native -DBUILD_SHARED_LIBS=OFF cmake --build build --config Release -j $(nproc) --target llama-server A single 4090 paired with 100 GB of cheap DDR4 RAM will comfortably serve production grade 125B inference. While Qwen 3.8 27B (dense) still holds the crown for single 3090/4090 rigs, Flash Next proves 125B hybrid models are officially viable on consumer hardware. Hugging Face GGUF link and complete performance telemetry graphs are dropped in the replies below. GLM 5.3 Flash VS Qwen 3.8 Flash Next, which one takes the open weights crown this week?

Alok

1,043,568 görüntüleme • 1 ay önce

Google's Gemma 4 26B A4B QAT hits 25+ tokens/sec and 320+ tokens/sec prefill on 8 GB VRAM (RTX 4060) + 16 GB RAM using TurboQuant Prefill just went from 200 → 320+ tok/s on the same 8GB card. 1.6x, no new hardware, no new quant, just a KV cache trick stacked on top of the Gemma 4 26B MoE setup from a few days ago. A few days ago I posted Gemma 4 26B A4B hitting 28 tok/s decode on 8GB VRAM using native MTP. prefill was stuck around 200 tok/s. fair callout by the community. So today I tested something I'd already been meaning to try: TheTom/llama-cpp-turboquant, the TurboQuant KV cache fork by Tom Turney (Tom Turney). (github link in the comments) thanks to him, the fork just got resynced to mainline, so MTP + TurboQuant now run together cleanly (I didnt see any meaningful gains by using MTP with this setup though but you can try). The flags (No MTP): -m gemma-4-26B-A4B-it-qat-UD-Q4_K_XL.gguf -cnv -c 64000 --cache-type-k q8_0 --cache-type-v turbo3 Results on the same RTX 4060 8GB, tested with a 27k token prompt at 64k context loaded: Prefill: 200 tok/s → 320+ tok/s Decode: stayed above 25 tok/s (without MTP) Why it works: TurboQuant uses walsh hadamard rotation + polar quantization on the KV cache. keys are sensitive to compression, values aren't much, so it splits the difference: K stays at q8_0, V drops to turbo3 (~3 bits). bonus from the memory savings: same 8GB card can now stretch to 100-120k context with minimal decode penalty. It should now be snappier with any agent harness such as hermes agent without compromise on intelligence. If you're already running Gemma 4 on a small card, this stacks on top for free. Try --cache-type-k q8_0 --cache-type-v turbo3 on your setup and report back what your prefill/decode split looks like. unsloth model gguf and llama.cpp turboquant fork links in the comments. what's your prefill number before vs after?

Alok

119,821 görüntüleme • 4 ay önce

Deepseek V4 Flash 0731 (Q2) - 12 tokens/sec - Single RTX 4090 - 650+ tokens/sec prefill - 250k context - no kv cache quantization! DeepSeek just dropped the official V4 Flash 0731 two days ago with a massive agent capabilities upgrade. The official benchmarks are literally crushing their own V4-Pro-Preview on agentic tasks like Terminal Bench 2.1 and DeepSWE. Unsloth AI said they couldn't wait to bring it to local devices, and they delivered. If you thought my 118B Poolside Laguna S 2.1 MoE run last week on a single GPU was wild, hold onto your hardware. I just successfully ran Unsloth’s brand new 91GB DeepSeek-V4-Flash-0731 (UD-IQ2_M) GGUF entirely locally. And I pushed it to a mind-bending 250,000 context window. The VRAM ceiling is an illusion if you know how to optimize llama.cpp. Here are the benchmarks and the cheat codes to run a local frontier class model yourself. For the hardware and setup, I used a single NVIDIA RTX 4090 (24GB VRAM) hooked up via a PCIe 4 bus, running Ubuntu 22.04 LTS and CUDA 13.0. You don't need a massive enterprise server for this, if you have more than 80 GB of standard DDR4 RAM and a 24GB card like an RTX 3090 or 4090, you can run this exact stack yourself. All benchmarks were run using a massive 28k token prompt to truly stress test the prefill limits. no kv cache quantization THE BENCHMARKS (Scaling Context): # 80k Context (Baseline: -b 2048 -ub 2048): Prefill: 465.43 t/s | Decode: 13.00 t/s | VRAM: 22.87 GB # 80k Context (Optimized: -b 4096 -ub 4096): Prefill: 643.15 t/s | Decode: 12.20 t/s | VRAM: 23.00 GB (Notice how doubling the batch flags spiked my prefill throughput by nearly 200 t/s with almost zero VRAM penalty) # 180k Context (-b 4096 -ub 4096): Prefill: 629.18 t/s | Decode: 11.92 t/s | VRAM: 23.40 GB # 250k Context MAXIMUM (-b 4096 -ub 4096): Prefill: 619.02 t/s | Decode: 11.54 t/s | VRAM: 23.40 GB # THE SECRET SAUCE (Why this works): Unsloth’s UD-IQ2_M quant is ~91GB across 3 files. Since I only have 24GB of VRAM, the PCIe 4 bus and system RAM have to do the heavy lifting. The magic bullet is the --no-mmap flag. By completely bypassing OS disk paging, I forced llama.cpp to load the massive model weights directly into the system RAM upfront. Combined with Flash Attention (-fa on) and exactly 12 CPU threads (--threads 12), I maintained an incredibly stable 11.5+ tokens/sec decode speed even at a quarter million token context. # THE EXACT COMMAND: ./build/bin/llama-server -m /workspace/models/DeepSeek-V4-Flash-0731-UD-IQ2_M-00001-of-00003.gguf -c 250000 -fa on --port 8080 --threads 12 -b 4096 -ub 4096 --no-mmap -v Local conversational and agentic coding AI is fully here. You don’t need an API or an H100 cluster. Qwen 3.8 27b drops next week making the 24GB VRAM tier even more worthwhile. What does your current local AI rig look like, and what's the craziest model you've managed to squeeze into it? Official huggingface GGUF links from Unsloth and performance graphs are dropped in the replies below!

Alok

46,100 görüntüleme • 2 ay önce

glm 5.3 vs qwen 3.8 vs gemini 3.7 vs deepseek v4 flash four models designed and built three structures each on a physics-backed site, with no dimensions anywhere in the brief the setup: our own agent loop on OpenRouter, a construction site as the tool set – footings, walls, arches, roofs, scaffold, a lamp. the site enforces physics and nothing else: unsupported brick falls, a roof needs walls under it, a worker reaches 3.2 m above whatever he stands on, an arch needs centring until the keystone is set, concrete cures before it carries. no budget ceiling – material cost is tallied and reported, never blocked. tasks: 1. house – a plot and a palette, no plan. shape, height and material are the model's call 2. lighthouse – a headland cut by a gully, with a rock stack standing 30 m offshore. the lamp must burn, it must be the highest thing built, and the keeper must be able to walk to it 3. bridge – a river with one islet and banks at different heights. cross it however you want models: Z.ai glm 5.3 flash, Qwen qwen 3.8 flash, Google DeepMind gemini 3.7 flash, DeepSeek v4 flash vision all twelve objects were finished and signed off by the models themselves. tallest lighthouse is qwen's at 38.4 m, planted on the offshore stack with a bridge run out to it – the only model that read the site that way. deepseek signed off its bridge on an empty riverbed: 0 bricks, 107 minutes, $1.16m of material tallied - total cost, three builds #1 glm 5.3 flash – $0.201 #2 gemini 3.7 flash – $0.871 #3 qwen 3.8 flash – $1.058 #4 deepseek v4 flash – $1.567 - wall clock, three builds #1 gemini 3.7 flash – 91m #2 glm 5.3 flash – 228m #3 deepseek v4 flash – 502m #4 qwen 3.8 flash – 912m - total tokens #1 gemini 3.7 flash – 3,567,052 #2 glm 5.3 flash – 4,732,748 #3 qwen 3.8 flash – 13,469,333 #4 deepseek v4 flash – 18,230,076 - defects logged by the site #1 deepseek v4 flash – 59 #2 gemini 3.7 flash – 132 #3 glm 5.3 flash – 221 #4 qwen 3.8 flash – 350 - material tallied across three builds #1 gemini 3.7 flash – $359,884 #2 glm 5.3 flash – $583,358 #3 deepseek v4 flash – $1,327,484 #4 qwen 3.8 flash – $2,188,625 observations: • glm is the cheap one and nothing here is close – $0.201 for three buildings, $0.042 per million tokens, 6x under gemini's rate • what glm spends it on is bulk, not care: 166,228 bricks in one house and 156 defect weight, the worst single object in the set • gemini is the efficiency line – 91 minutes and 3.57m tokens for all three and an eighth of qwen's clock • gemini also builds the smallest of everything. its lighthouse is 22.5 m against qwen's 38.4, its house 6.9 m against 19.3 • qwen is the maximalist: 1.18m bricks, $2.19m of material, tallest on all three tasks, and 912 minutes – 15 hours – to get there conclusion: twelve finished objects for $3.80 all in, and a 7.8x price spread between the cheapest model and the priciest! follow thehype. for 24/7 ai news, analysis and breakdowns

thehype.

26,360 görüntüleme • 1 ay önce

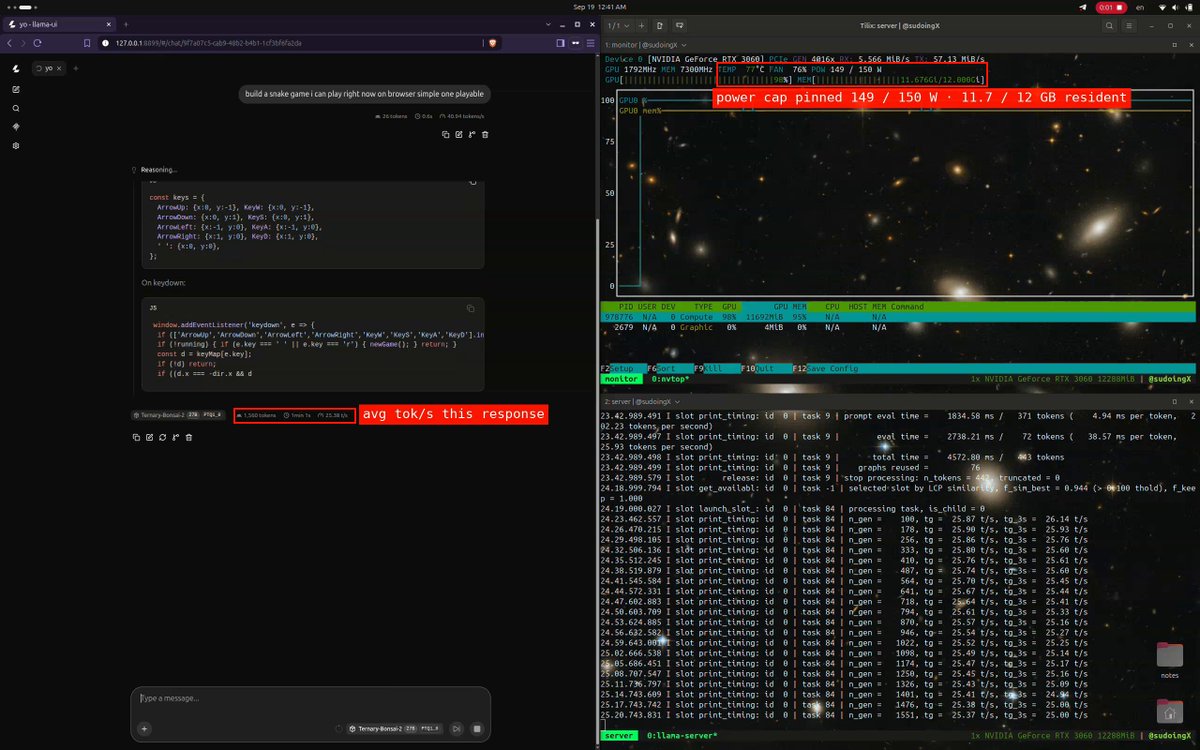
bonsai 2 27b on an rtx 3060 12gb, the full receipt sheet. save this one, the 12gb row of the small gpu guide is built from it. speed by depth, then what context costs, live server, thinking on, real sessions > 7k deep: 24.4 tok/s > 12k deep: 21.9 tok/s > 35k deep: 17.8 tok/s > 77k deep: 13.0 tok/s > 64k window: 7.3gb resident > 128k window: 8.8gb resident > 192k window: 10.2gb resident > 262k window: 11.7gb resident, 0.6gb to spare, the whole native window on a 12gb card > every 64k of context costs 1.47gb, so 327k would not fit > a 41,312 token build session from 35k to 77k of context averaged 15.0 tok/s across 46 minutes > prefill 295 tok/s at 2k of context, 243 tok/s at 35k, first token in 0.6 seconds, fresh decode 26.1 tok/s > the card pinned 149 of 150 w the entire time, 78c, fan at 80%, power bound, not heat bound > 0.158 tok/s per watt at the fresh end the setup > model: ternary bonsai 2 27b, PTQ1_0, 1.75 bits per weight, 5.95gb on disk, base qwen 3.8 27b, apache 2.0 > runtime: prismml llama.cpp fork, prebuilt cuda 12.4 binary, no compile > serve: full 262k native window resident, q4 kv cache, flash attention, one slot, 11.7 of 12gb in use for anyone who followed bonsai 1 in july, that was the 3.9gb 1bit file at 42 tok/s on a 3060 ti, a faster card and a smaller file, so the same card comparison is not on the table yet, it comes with the 8gb test. what changed is the base, qwen 3.8 instead of 3.6, and the retention, 98.2% on their suite instead of 95%, and the whole 262k window fitting on 12gb.

Sudo su

31,174 görüntüleme • 1 ay önce

Run Updated Gemma 4 26B A4B QAT (MoE) with Vision at 25 tokens/sec and massive 120k context window on a single RTX 4060 (8 GB VRAM + 16 GB RAM Only!!) Yesterday I pushed Gemma 4 26B A4B QAT to 250k context on a single RTX 4060 using nothing but Q8 KV cache and optimized -b and -ub flags for higher prefill throughput. Today I stacked Multi Token Prediction (MTP) self speculative decoding AND the vision projector (mmproj) on top of that same card, same batch size optimization, same $250 GPU and pushed it until it broke, then found the fix. All text only runs consist of a 28k prompt. vision runs consist of 28k text prompt + an image. # 1. MTP alone. near free decode speed, no catch MTP draft assistant is a separate small model (MTP heads are backed into the main model itself for the qwen 3.5+ models but its a separate small model for gemma 4 series), 240 MB gguf 80k ctx: Prefill 510 t/s | Decode 29.5 t/s 120k ctx: Prefill 433 t/s | Decode 29 t/s 180k ctx: Prefill 240 t/s | Decode 24.9 t/s 250k ctx: Prefill 63 t/s | Decode 13 t/s llama.cpp flags: m gemma-4-26B-A4B-it-qat-UD-Q4_K_XL.gguf --spec-type draft-mtp -md mtp-gemma-4-26B-A4B-it.gguf-c 180000 -b 1024 -ub 1024 --spec-draft-n-max 6 --spec-draft-p-min 0.7 -ctk q8_0 -ctv q8_0 # 2. Add vision on top. the tax you actually pay the vision projector gguf is about 1.1 GBs 80k ctx: Prefill 360 t/s | Decode 25.4 t/s 120k ctx: Prefill 230 t/s | Decode 23.8 t/s 180k ctx (Q8 KV): Prefill 75 t/s | Decode 12.5 t/s - cliff flags: -m gemma-4-26B-A4B-it-qat-UD-Q4_K_XL.gguf --spec-type draft-mtp -md mtp-gemma-4-26B-A4B-it.gguf -c 80000 --port 8080 -b 1024 -ub 1024 --spec-draft-n-max 6 --spec-draft-p-min 0.7 -ctk q8_0 -ctv q8_0 --mmproj mmproj-F16.gguf # 3. The fix if you want to run vision over 120k context: swap Q8 KV for Q4 KV past 120k Stack MTP + vision + Q8 KV past 120k context and you hit a wall. draft model overhead plus KV pressure tanks everything. Drop to Q4 KV and the wall disappears: 180k ctx (Q4 KV): Prefill 220 t/s | Decode 25.5 t/s -ctk q4_0 -ctv q4_0 --mmproj mmproj-F16.gguf (rest same as above) Bottom line: MTP gives you a near free +20-30% decode boost up to 120k context. Past that, it's fighting your VRAM, not helping and if vision is loaded too, Q4 KV isn't optional past 120k, it's mandatory. 30% boost is model and card specific, MTP boosted decode 2x for gemma 4 31b on a single rtx 4090. Same 8GB card. Same $250 GPU. Multimodal, speculative decoding, 180k usable context, zero upgrades. You gotta try this if you have a single NVIDIA RTX 3050, 3060, 3070, 4050, 4060, 5050 or 5060. You can try it with a 6 GB VRAM card as well but you will have to lower the context window. Hugging Face links to the updated Unsloth's QAT quants and performance graph are in the replies below. Which models are you running on your 6/8/12GB cards with MTP?

Alok

16,434 görüntüleme • 2 ay önce

GLM-5.3 Flash vs Qwen3.8 Flash-Next. Both local on my 4x 3090, both left alone with 1 prompt per task. 11 scenes, 18 hours, 2.4M tokens out. All of it is in the video. I wanted a clear winner. I didnt get one, but I know which one stays on my rig. GLM-5.3 Flash: Maya-M quant, 116 GB, runs in Project Maya on all 4 cards plus RAM. 35 to 48 tok/s while it works. Qwen3.8 Flash-Next: IQ3_S quant, 78 GB, runs in Strata on 2 cards. 85 to 118 tok/s. Both have 262K context and vision, so the agent opens its own page, takes a screenshot, looks at it and fixes what it sees. 1 prompt per scene. No follow ups and no hints from me. 120 minutes max per scene, 150 for the kart game. I ran them in 2 harnesses, OMP first and then DeepSeek Harness. Minutes until the model said it was done: Pelican in OMP: GLM 39, Qwen 66 Pelican in DeepSeek Harness: GLM 93, Qwen 86 Kart game in OMP: GLM 130, Qwen stopped by the 150 limit Millipede in OMP: both stopped by the 120 limit Millipede in DeepSeek Harness: Qwen stopped at 120 again Battle diorama in DeepSeek Harness: GLM 81, Qwen 113 Thats 11 of 16 combos. I ran out of time for the other 5, sorry. They work in a very different way and I didnt expect that. GLM thinks for a long time and then writes a lot at once. Its first pelican took only 36 turns. For the diorama it gave 1 answer of 47K tokens that ran for almost 18 minutes, with the full scene in a single file. Qwen goes in small steps and checks everything. The same pelican was 240 turns and 45 browser checks. In total GLM wrote 513K tokens in 5 runs and Qwen wrote 1.9M in 6 runs, so Qwen puts out 2.6x more per minute of real time, on half the cards. The harness also changed more than I thought it would. OMP keeps only 5 images in a request when the provider is local. So every new screenshot removes the oldest one, the prompt changes in the middle, and the server has to read the context again from the start. GLM lost 37 of its 130 kart minutes just on that. In DeepSeek Harness, on the diorama, it lost 3.5 minutes out of 81. Qwen reads a prompt almost 4x faster on my rig (84K tokens in 23 seconds, GLM needs 100 seconds for 96K), so in OMP it lost only 9 to 12 minutes per run. I cant give you a winner. GLM is the only one that finished the kart game inside the limit, and its scenes look cleaner to me. But its millipede is bad. Qwen puts more detail into everything, and its diorama and millipede from DeepSeek Harness are my favorite scenes in the video. It also got stopped by the time limit in 3 of its 6 runs, because it just keeps polishing. For my own use I'd take Qwen. It is a lot faster and it needs only 2 cards, so the other 2 stay free and I can run something else next to it. This is 1 run per combo, so dont read it as statistics. Both models ran with my refusal projection on, because thats how I use them every day. And in the kart clips the game's own AI is driving the player kart, I only recorded the screen. Music: YuE2

Alexey Fateev

12,889 görüntüleme • 7 gün önce

Qwen3.8-27B running at full BF16 on a free Kaggle TPU is kind of ridiculous. No quantization. No tiny context window. No expensive GPU instance. Just Qwen3.8-27B running on a Kaggle TPU v5e-8. The reported numbers: ~130 tok/s decode ~10,000 tok/s prefill 262K context That prefill number is especially wild. You can throw a huge amount of code or context at the model and ingest it extremely quickly, while still getting around 130 tokens per second during generation. And because it’s running in full BF16, you’re not relying on an aggressive quant just to make the model fit. But the really interesting part isn’t even the raw throughput. You can expose it as an OpenAI-compatible endpoint. That means you can plug the model into tools that already understand OpenAI-style APIs. Claude Code. Codex. OpenCode. And other compatible clients. So the workflow becomes pretty simple: Spin up the Qwen3.8-27B endpoint on Kaggle. Point your coding tool at the API. And suddenly you have a 27B coding model sitting behind the same interface you’d normally use for hosted models. The 262K context is also a huge deal for agentic coding. Large repositories can fit into a single context. Long conversations don’t need to be constantly trimmed. And tools can feed much more information back to the model without hitting a tiny context ceiling. The fact that this can be built around a free TPU environment is what makes this especially interesting. We’re getting to a point where experimenting with serious open models doesn’t always require owning a $2,000 GPU or paying for a large cloud instance. Free compute + open weights + an OpenAI-compatible API + existing coding agents. That’s a pretty powerful combination. Qwen3.8-27B is already an interesting model. Running the full BF16 version at ~130 tok/s with 262K context on free Kaggle TPU compute makes it a lot more interesting.

FHILY👑

35,910 görüntüleme • 1 ay önce

dflash-mlx v0.1.7 is out. Big adaptive-runtime update, still focused mostly on Qwen3.6 27B 4-bit. @ 2048 tokens, M5 Max, stock mlx_lm baseline: ► 1024: 33.26 → 98.05 tok/s (x2.95) ► 2048: 32.34 → 90.67 tok/s (x2.81) ► 4096: 30.58 → 93.55 tok/s (x3.06) ► 8192: 26.03 → 79.12 tok/s (x3.04) ► 16384: 21.50 → 60.77 tok/s (x2.78) Main change: adaptive verify got a lot smarter. Instead of blindly trying to verify large 16-token blocks all the time, DFlash now watches acceptance + tokens/cycle + real cycle cost. When the draft gets weaker, it drops to smaller 4-token blocks, then probes back up only when the recent cycles make sense. In practice: less wasted verify work, better long-context behavior, and much more useful metrics to understand what is happening. ► retuned adaptive verify for long-context / agentic decode ► richer metrics: tokens/cycle, adaptive block state, CopySpec counters ► /metrics now has real decode avg + logical/real/restored prefill rates ► AIME25 benchmark suite with exact integer scoring ► Qwen thinking default now follows tokenizer/request behavior ► GDN recurrent exactness fixes I also started running AIME25-style long generations. Even around 45k generated tokens, I was still seeing ~40 tok/s on 27B 4-bit. Over the next few days I’ll share more demos: AIME runs, real OpenCode game/project sessions, and full metrics along the way. Still optimizing hard for 27B 4-bit first, while working on custom kernels per Apple GPU generation so more machines can benefit.

bstn 👁️

16,464 görüntüleme • 5 ay önce