Загрузка видео...
Не удалось загрузить видео
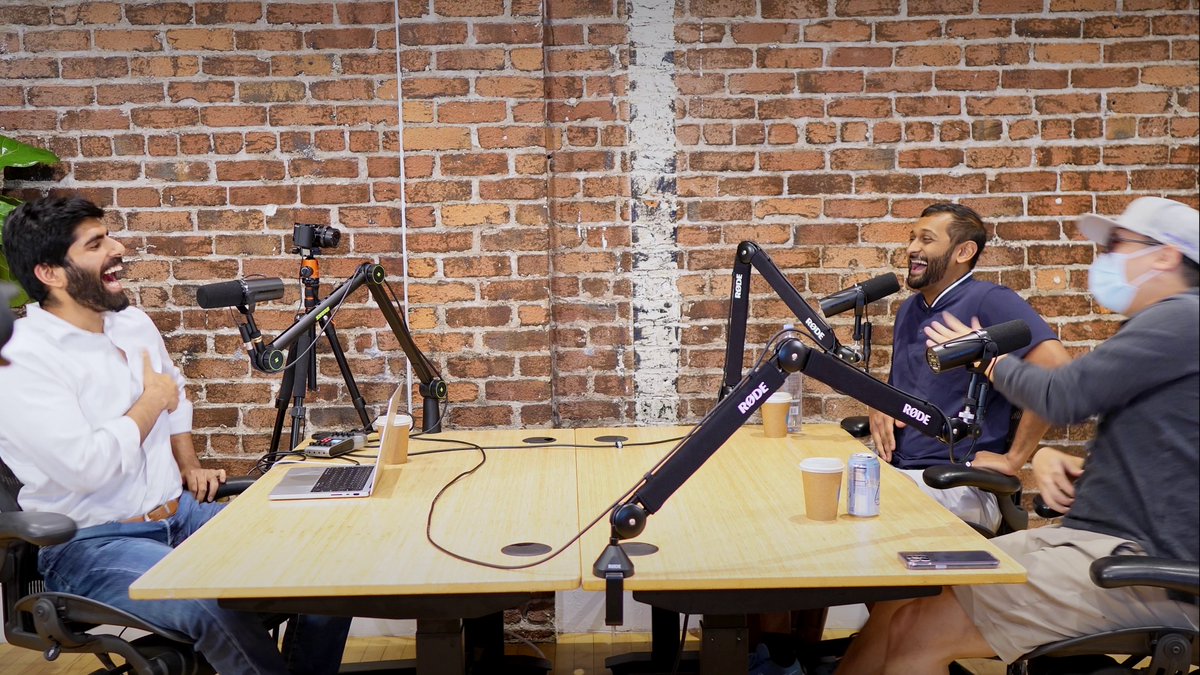
Our new podcast on evals, with Max Niederman, Ege Erdil, and Stephen Yang. 0:00:00 – What's an eval, and how's it different from an RL environment? 0:19:33 – Why are models bad at building an emulator when the task is fully verifiable? 0:42:00 – How does training on bad... show more
40,871 просмотров • 3 месяцев назад •via X (Twitter)
Комментарии: 9

Mechanize3 месяцев назад
Youtube: Substack: Spotify:

Matthew Berman3 месяцев назад
@Mascobot How do I get in touch?
Mechanize3 месяцев назад
@Mascobot DM'd

Alessio Toniolo3 месяцев назад
Enjoyed the commentary on RL environment scaling and software engineering. Thanks guys!

Shman3 месяцев назад
Apple podcast link?

Ariel Lillie3 месяцев назад
this sounds super intriguing, especially the bad data angle. can't wait to dive in!

Clemens Helmut Sageder3 месяцев назад
@tamaybes interesting podcast

Seungju chae3 месяцев назад
this is gold, thank you

Zarroc.BTC 🧠3 месяцев назад
let's be real, the bad data part is a game changer, can't wait to hear the full breakdown