Video yükleniyor...
Video Yüklenemedi
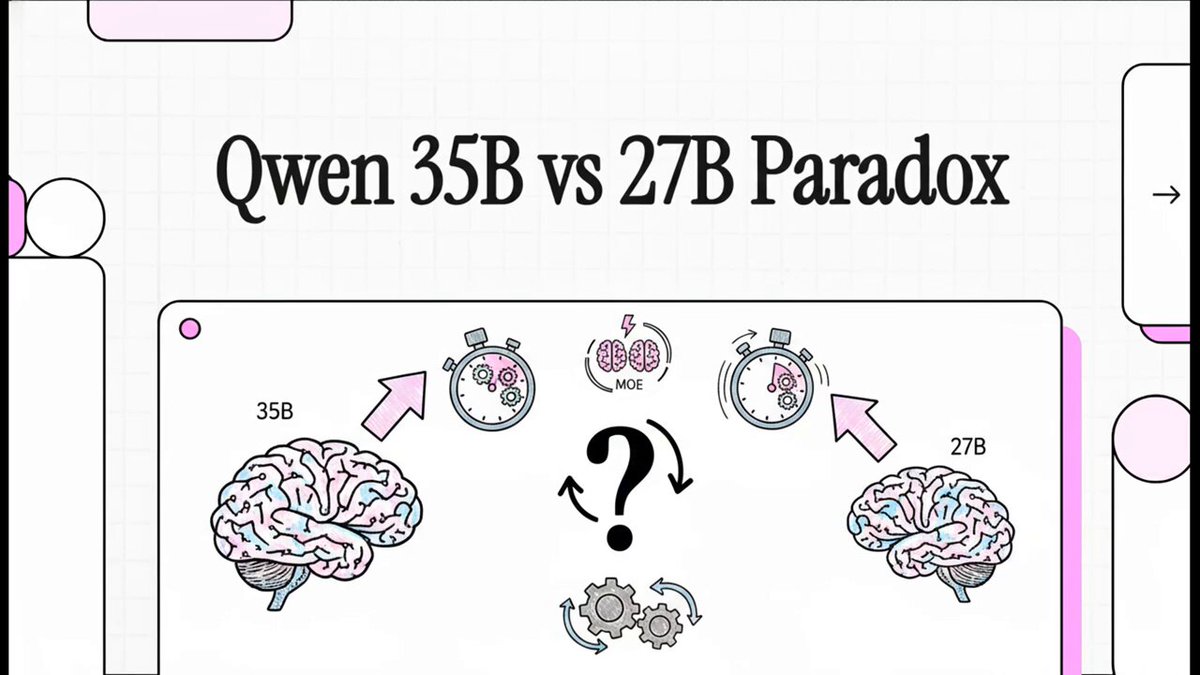
Qwen3.6 35B-A3B MTP is a devil performing around 1,000 tok/s on code with RTX 5090 once the prediction gets easier. Been a while I've tried 35B-A3B. Seems I might be sticking around for the fun.
49,211 görüntüleme • 2 ay önce •via X (Twitter)
28 Yorum

Mainline llama.cpp ``` command: - /opt/llama/bin/llama-server - -m - /models/Huihui-Qwen3.6-35B-A3B-abliterated-ggml-model-Q4_K.gguf - --host - 0.0.0.0 - --port - 8081 - -t - 10 - --chat-template-file - /models/qwen36_chat_template.jinja - --temp - 0.05 - --top-p - 0.75 - --top-k - 10 - --min-p - 0.0 - --presence-penalty - 0.0 - --repeat-penalty - 1.00 - --repeat-last-n - 256 - --seed - 42 - --flash-attn - on - -b - 256 - -ub - 256 - --no-mmap - --parallel - 4 - -ngl - 999 - --kv-unified - --spec-type - draft-mtp,ngram-mod,ngram-map-k4v - --spec-draft-n-max - 3 - --spec-draft-p-min - 0.0 - --spec-ngram-mod-n-match - 24 - --spec-ngram-mod-n-min - 48 - --spec-ngram-mod-n-max - 64 - --spec-ngram-map-k4v-size-n - 16 - --spec-ngram-map-k4v-size-m - 96 - --spec-ngram-map-k4v-min-hits - 1 - --no-cache-idle-slots - --cache-ram - 0 - --ctx-checkpoints - 32 - --cache-reuse - 0 ```

Cmon man ;) It's perrforming copy-paste @ 1000t/s ;) Real decode was ~280t/s

wow 1k tok/s is impressive! i also just did a benchmark for qwen3.6 27b nvfp4 by @UnslothAI on a 5090, it was ~120 tok/s with nspec = 3 plan to do another benchmark for qwen3.6 35b nvfp4 today.
Haven't had the patience to make another docker to try Unsloth's NVFP4 so I got stuck with Nvidia's. Pretty awesome PP - upwards 15k tok/s throughput. Decode is pretty stable, but I think circa 100 tok/s. I got DFlash working above 200 tok/s on up to 50/70k context fill. Need to see if it drops above 100k context. Seems good. Might miss vLLMs PP but might be changing flavours with llama.cpp for now. gg

The speed is only part of the picture. For example, I would not use 35b for long chain agentic coding. It starts to hallucinate when the context gets large, like over 120k, and then makes too many mistakes, keeps doubting itself, etc. On a 5090 I would go for qwen3.6 27b nvfp4 with built in mtp and fp8 kv cache or better. I love the speed of 35b, but it’s just not good enough for a lot of real coding work in large repos.
indeed 35B is not great for "complex" agentic coding, but still has utility. however, you're meant to choose the right tool for the job. also 27B on NVFP4 is not that superb either, when a Q5 or Q6 offers better fidelity. altough the 27B still beats 35B-A3B at 4-bit in that case👍

3.6 35B-A3B MTP has been my favorite so far, especially for gaming GPUs, im switching around desktop configuration at the moment, and adding a second dusty RTX3060 gpu to run another model, trying to get everything up and running this week, waiting on shipment of a m.2 -> pcie adapter. then use a shared context pool/coordinator so they can share context quickly. hopefully cuda isnt going to complain and Ampere + Blackwell wont cause problems. So ill probably be on Open Kernel Modules package

just switched to it from 27B dense and I'm not regretting it. ~2k tps prefill and up to 100tps decode at Q5_K_XL 200k Q8_0 KV cache on two 5060 TIs. And that's on a Dual E5-2640 v4 Xeon from the stone-age.
I still use both. The MoE is useful on some personal workflows and these bursts help a lot.

Its not a good model for code. Crap tokens are still crap tokens.

What is it best at ? Coding or agent or chat ?
use it for all when tasks are light enough when isn't gaslighting me short of info - otherwise 27B

If you like that try Ornith, though I don’t know offhand if a MTP version is available.
originally it didn't. I know some folks grafted MTP.

Running local or through virtual environment?

Context size?
iirc 262k as I switched later to Q5 to get about circa 180k
Interesting, will try this out.

Runs batches of requests too - e.g. 24 concurrently, at much higher throughput decode toks/s.

That only leaves around 12GB for rag and context

Yeah.. But what's the point ? The quality is substandard.
if you know better, enlighten, or stay quiet forever.
Sorry, I didn't mean to be rude. The 5090 runs Qwen 27b, which offers better token quality and is more interesting in my opinion. Sacrificing quality for speed is not worth it to me.
That's cool. I'm just fatigued by the 27B cult. Different tools for different ends. My daily driver IS a 27B and I occasionally pair the MoE variant for fast loops - which is where this drafting is useful as I can loop super fast where it matters. I don't disagree 27B is overall better, but I have private repo forks for benchmarks and 35B-A3B does come out on top of 27B for my usecases - I have still some old Rust/Next.JS benchmarks shared on my profile as proofs of receipts. I can do more work per unit of time, with less stress on the GPU for equivalent results where I need.

Avec une 5090 tu ne peux pas rester sur le 35b-A3B… il faut passer sur le 27B

Do you train the weights with qlora? Or out of the box?

I like the strive to optimize performance for local AI for sports. But why would you want a 1000 tok/s slop machine? I dont see the use case, please enlighten me! Its not like we are gonna trust the knowledge unless it has 4 digit b parameters
I'm an iterative coder. Function over form here. Coding loops exposes agent to repeated patterns, since code repeats itself, it makes it easier for drafter to predict next tokens. This means during loops, the agent will have these bursts. Faster inference, fewer heat cycles, more work done.