Video wird geladen...

Video konnte nicht geladen werden

Zur Startseite

Running a local agent 24/7 until it successfully gets paid for a security bug bounty Qwen3.8-27B - intel arc b70 - 262k context - vision - 60 tok/s decode - 1500-6000 tok/s prefill
192,144 Aufrufe • vor 27 Tagen •via X (Twitter)

40 Kommentare

Profilbild von Noah Bertilson
Noah Bertilsonvor 27 Tagen

Bought a B70 yesterday afternoon, but I've run into errors/issues running your config. May be because I'm on Artix instead of Omarchy. Host kernel is latest: 7.2.7-artix, not sure what compute runtime, IGC, LZL versions.

Profilbild von 0xSero
0xSerovor 27 Tagen

Do you have a Claude/codex sub or maybe free opencode? Give them the repo and ask them to figure the issue out fix it and test it then file a pr

Profilbild von Noah Bertilson
Noah Bertilsonvor 27 Tagen

Unfortunately not that token-wealthy. I'll just keep asking Hermes about it with my OpenRouter credits...

Profilbild von 0xJustice.eth 👹🔥
0xJustice.eth 👹🔥vor 27 Tagen

Happy to share this repo with you if you like. I learned a lot in the process. All documented.

Profilbild von Sacred Pop | Catholic Music
Sacred Pop | Catholic Musicvor 27 Tagen

I'm probably sleeping on leveraging my 5090 for something like this, where is a good market for these kinds of bounties? Aren't they saturated markets?

Profilbild von 0xSero
0xSerovor 27 Tagen

How will they saturate when “frontier models” refuse to do it

Profilbild von Sacred Pop | Catholic Music
Sacred Pop | Catholic Musicvor 27 Tagen

Good point, do you have a link to where these bounties are? I would be interested in putting my local qwen on some.

Profilbild von NeoCortex1984
NeoCortex1984vor 27 Tagen

@0xSero Unironically task your local agent to find it and evaluate yourself if the links are solid. Let it be it's first task into this world.

Profilbild von Sacred Pop | Catholic Music
Sacred Pop | Catholic Musicvor 27 Tagen

@0xSero Maybe I ask too much..

Profilbild von Jason - looking for work
Jason - looking for workvor 27 Tagen

What backend is hitting that prefill speed? I get 85 t/sec decode on Qwen 35b and haven't noticed much over 700 prefill on llama. 5000+ is what I get on the 4090.

Profilbild von 0xSero
0xSerovor 27 Tagen

sglang with exl3 kernels

Profilbild von Robin
Robinvor 27 Tagen

Intel didn’t lie with their GPUs - would have never imagined they would do such a good job on them

Profilbild von Maciej 'sorek' Łoboda
Maciej 'sorek' Łobodavor 27 Tagen

Have you tried parallel? I run hyperqwen on my 4090D 48GB and 160k x4 context is really fast up to 350t/s!

Profilbild von kenny
kennyvor 27 Tagen

you gave it the poidh skill yeah? pretty sure we've paid out like 5 different agents in the past week

Profilbild von jsunnn
jsunnnvor 27 Tagen

Make the GPU pay rent.

Profilbild von ignas
ignasvor 27 Tagen

how is it a 3k machine? and b70 > 3090?

Profilbild von Yamura
Yamuravor 27 Tagen

Do you use a custom harness? If not, I recommend mine (+pi) also PLEASE let it or yourself double check what it finds, and ensure it is not inflated. Triagers hate false positives. Then also, use Email bug bounty programs with a crit paying ~1k max.

Profilbild von Cuth
Cuthvor 27 Tagen

Try my version of Qwen 27b homie. Takes Bonsai and boosts it’s accuracy

Profilbild von Jim Wallace
Jim Wallacevor 27 Tagen

I get these automated emails from people like you who have found jack shit but claim it’s some huge vulnerability worthy of a bug bounty 🙄

Profilbild von Xenomayo
Xenomayovor 27 Tagen

You might have discussed this at a previous time but how are you finding agent performance on Omarchy?

Profilbild von Donald Watts
Donald Wattsvor 27 Tagen

The 27b is a surprisingly successful model. With enough iterations and the right context, my money's on qwen.

Profilbild von AJ Seelund (Chief Chicken Officer)
AJ Seelund (Chief Chicken Officer)vor 27 Tagen

Money printer glitch

Profilbild von Flex
Flexvor 27 Tagen

oh, i assumed bug bounties were all eaten up by ppl using big AI models, keep us posted pls

Profilbild von Alejandro Méndez
Alejandro Méndezvor 27 Tagen

qwen will do it.

Profilbild von 1bitLabs
1bitLabsvor 27 Tagen

That’s not a bad idea!

Profilbild von cdog420
cdog420vor 27 Tagen

Lmk when it hits

Profilbild von bnanw
bnanwvor 27 Tagen

I am aiming for that.

Profilbild von Core Control Unit
Core Control Unitvor 27 Tagen

Living the dream aren't you?

Profilbild von Coda
Codavor 27 Tagen

interesting lol keep updated!

Profilbild von 0xSudome
0xSudomevor 27 Tagen

How do you collect a bounty on something like this?

Profilbild von Harold Agudelo
Harold Agudelovor 27 Tagen

Q4?

Profilbild von NightlyMania
NightlyManiavor 27 Tagen

You’ve said different numbers for the decode speed, what would I actually expect if I got this card

Profilbild von 🤖Sergio
🤖Sergiovor 27 Tagen

How the hell do you get those speeds?!!!! I can't get those with my RX 7900 XTX

Profilbild von Jason Comerford
Jason Comerfordvor 27 Tagen

27b gotta wait 27 years

Profilbild von ༽Europurr༼
༽Europurr༼vor 27 Tagen

OMG Maybe I sold my 2x B70s too soon

Profilbild von HumanSynthetic
HumanSyntheticvor 27 Tagen

I can't get my B60 Qwen3.8-27b over 22 tok/s! What is your set up?

Profilbild von Jay Ballentine
Jay Ballentinevor 27 Tagen

a man shouldn't sound so timid. put some bass and confidence in your voice man.

Profilbild von Gianluca Alloisio - Hoxfall live on Gamefound
Gianluca Alloisio - Hoxfall live on Gamefoundvor 27 Tagen

It would be useful if you specified the quant and version of the model, even if the original full one.

Profilbild von killermonkyrecordz
killermonkyrecordzvor 27 Tagen

you can test with lazyown redteam framework in mode auto mcp

Profilbild von Nathan Keilar
Nathan Keilarvor 27 Tagen

What bug bounty program are you searching on… it’s a good use for the compute when I don’t have an experiment running.

Ähnliche Videos

Qwen3.8-27B running at full BF16 on a free Kaggle TPU is kind of ridiculous. No quantization. No tiny context window. No expensive GPU instance. Just Qwen3.8-27B running on a Kaggle TPU v5e-8. The reported numbers: ~130 tok/s decode ~10,000 tok/s prefill 262K context That prefill number is especially wild. You can throw a huge amount of code or context at the model and ingest it extremely quickly, while still getting around 130 tokens per second during generation. And because it’s running in full BF16, you’re not relying on an aggressive quant just to make the model fit. But the really interesting part isn’t even the raw throughput. You can expose it as an OpenAI-compatible endpoint. That means you can plug the model into tools that already understand OpenAI-style APIs. Claude Code. Codex. OpenCode. And other compatible clients. So the workflow becomes pretty simple: Spin up the Qwen3.8-27B endpoint on Kaggle. Point your coding tool at the API. And suddenly you have a 27B coding model sitting behind the same interface you’d normally use for hosted models. The 262K context is also a huge deal for agentic coding. Large repositories can fit into a single context. Long conversations don’t need to be constantly trimmed. And tools can feed much more information back to the model without hitting a tiny context ceiling. The fact that this can be built around a free TPU environment is what makes this especially interesting. We’re getting to a point where experimenting with serious open models doesn’t always require owning a $2,000 GPU or paying for a large cloud instance. Free compute + open weights + an OpenAI-compatible API + existing coding agents. That’s a pretty powerful combination. Qwen3.8-27B is already an interesting model. Running the full BF16 version at ~130 tok/s with 262K context on free Kaggle TPU compute makes it a lot more interesting.

FHILY👑

36,136 Aufrufe • vor 1 Monat

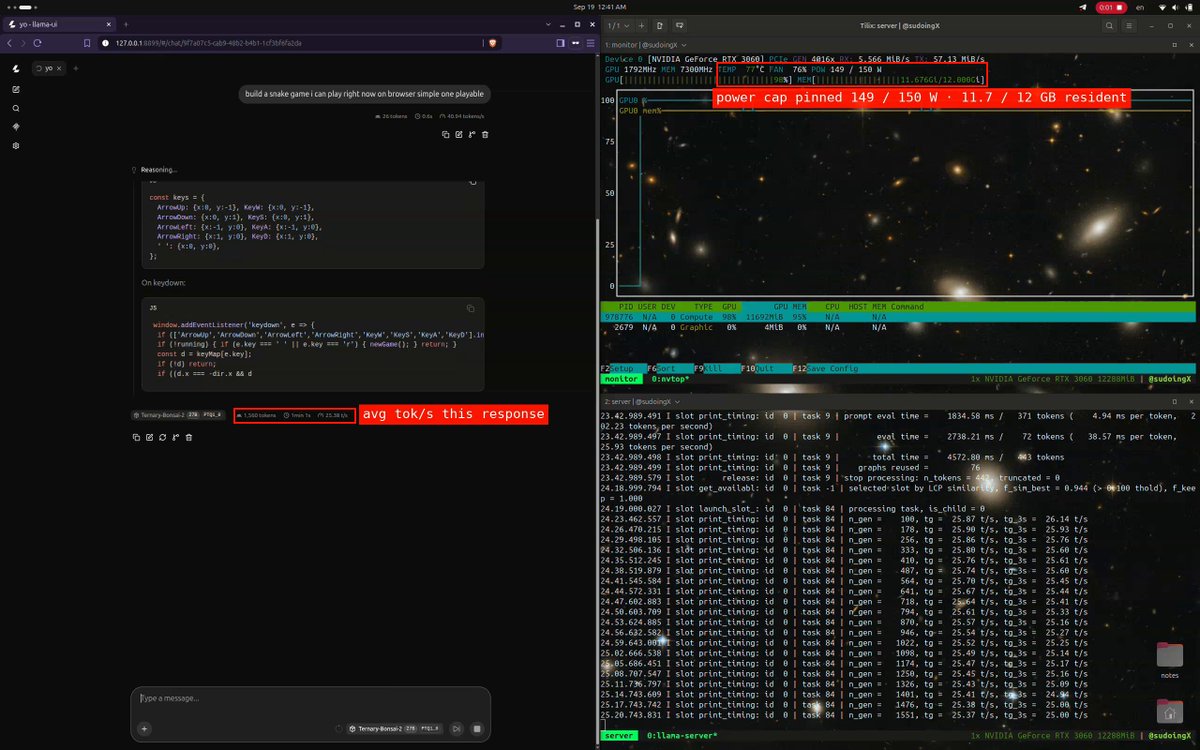
bonsai 2 27b on an rtx 3060 12gb, the full receipt sheet. save this one, the 12gb row of the small gpu guide is built from it. speed by depth, then what context costs, live server, thinking on, real sessions > 7k deep: 24.4 tok/s > 12k deep: 21.9 tok/s > 35k deep: 17.8 tok/s > 77k deep: 13.0 tok/s > 64k window: 7.3gb resident > 128k window: 8.8gb resident > 192k window: 10.2gb resident > 262k window: 11.7gb resident, 0.6gb to spare, the whole native window on a 12gb card > every 64k of context costs 1.47gb, so 327k would not fit > a 41,312 token build session from 35k to 77k of context averaged 15.0 tok/s across 46 minutes > prefill 295 tok/s at 2k of context, 243 tok/s at 35k, first token in 0.6 seconds, fresh decode 26.1 tok/s > the card pinned 149 of 150 w the entire time, 78c, fan at 80%, power bound, not heat bound > 0.158 tok/s per watt at the fresh end the setup > model: ternary bonsai 2 27b, PTQ1_0, 1.75 bits per weight, 5.95gb on disk, base qwen 3.8 27b, apache 2.0 > runtime: prismml llama.cpp fork, prebuilt cuda 12.4 binary, no compile > serve: full 262k native window resident, q4 kv cache, flash attention, one slot, 11.7 of 12gb in use for anyone who followed bonsai 1 in july, that was the 3.9gb 1bit file at 42 tok/s on a 3060 ti, a faster card and a smaller file, so the same card comparison is not on the table yet, it comes with the 8gb test. what changed is the base, qwen 3.8 instead of 3.6, and the retention, 98.2% on their suite instead of 95%, and the whole 262k window fitting on 12gb.

Sudo su

31,174 Aufrufe • vor 1 Monat