Loading video...
Video Failed to Load
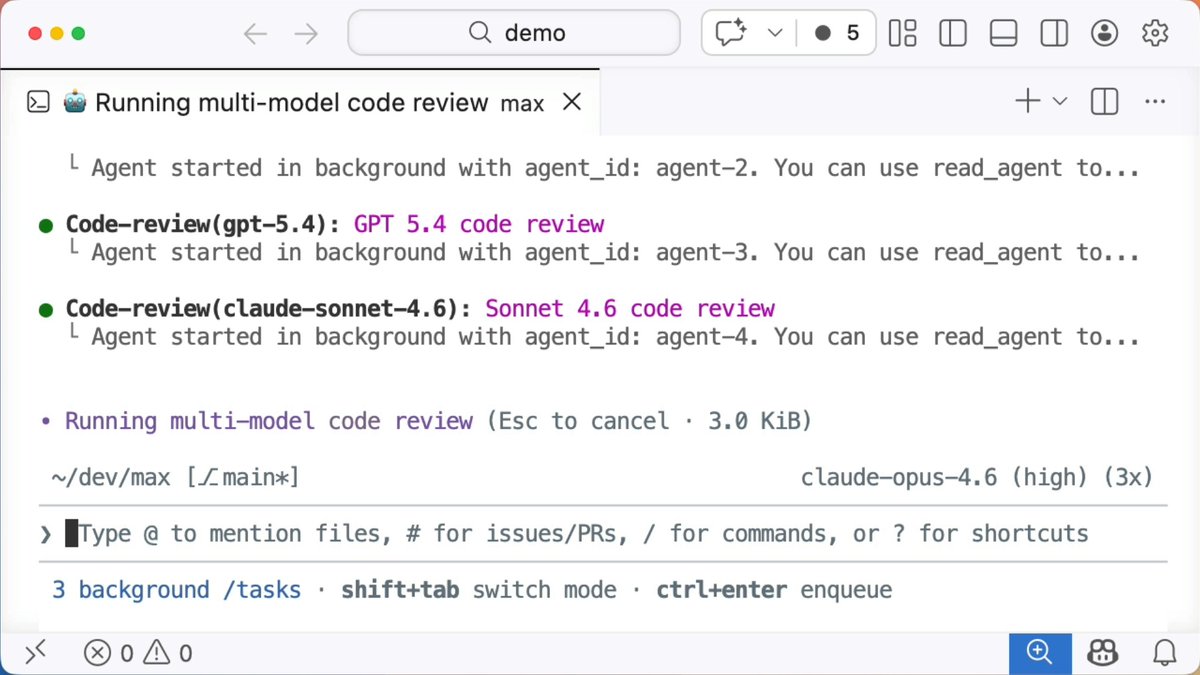
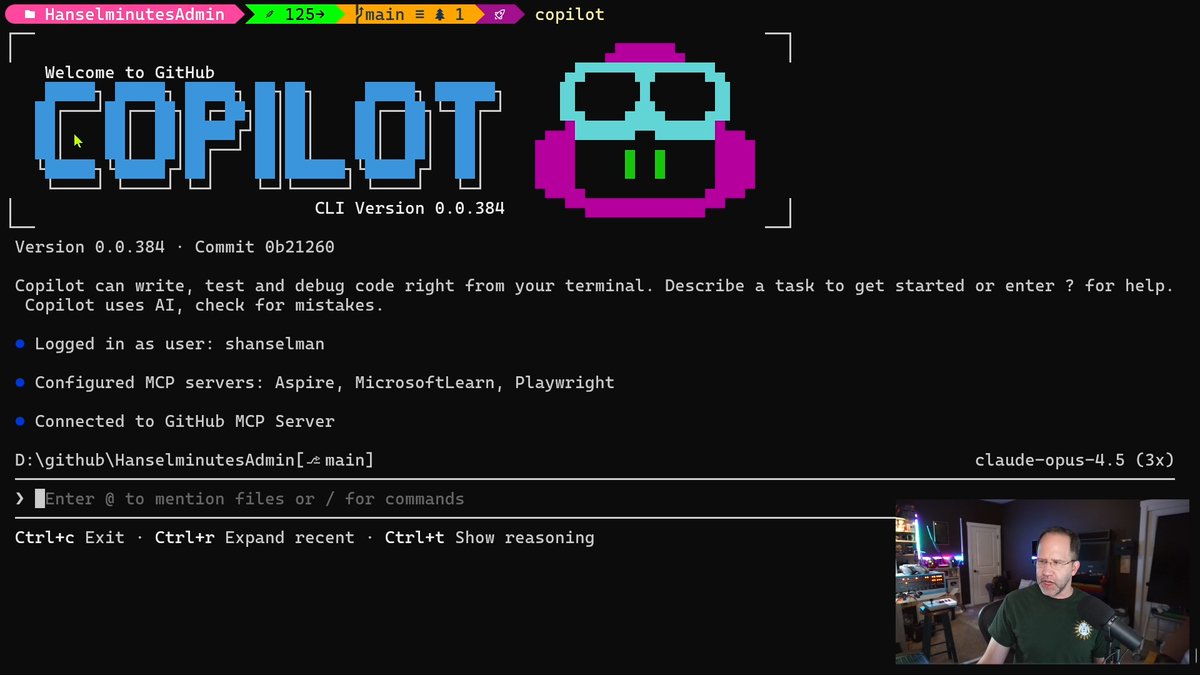
The @GitHub Research folks released a "Rubber Duck" agent for the Copilot CLI. Automatically get a review from a model from a different AI family. And their data shows that yes, this does in fact help. Quite a bit.
244,322 views • 7 months ago •via X (Twitter)
31 Comments

Check their receipts on SWE Bench. Rubber duck closes 75% of the gap between Sonnet and Opus.

@gregor_suttie @github This has kind of been my workflow for a while now. Claude writes the code. A fresh Claude context reviews the code. Codex reviews the code too. Then copilot does its reviews during pull request. So 3 sets of eyes basically. Anecdotally codex finds more logic errors than Claude

@github how is this different from just an agent skill that could be invoked whenever needed?
@dpandiyan @github It's invoked automatically and is part of the harness, which means it's gonna be way more reliable than a skill. That said, you could approximate this with a skill. A lot of people already do I think.

@github Can I argue that introducing the rubber-duck agent pushes the primary model to apply some self-evaluation That feeling when you are trying so hard to find what could be wrong WHILE being assessed, hoping to spot and fix something before it is pointed out
@github Oh that's super interesting! Just calling the rubber duck caused the model to reevaluate itself? I think the idea is that GPT 5.4 has strengths over Claude family and vice versa. But I'm not clear on what those strengths are exactly.

@_Evan_Boyle @github Codex for code, Copilot for PR review has been my workflow (small ball, side projects) for a few months now. I really like the adversarial approach to reviews. Don’t have time to evaluate all the models, had to pick two. Copilot is very thorough in my experience, has good taste.

@github First of all: very cool! love seeing copilot innovating Second of all: thats not a rubber duck :(

@github That’s a why I created a claude code plugin for @Github Copilot
@github Wait - this calls Copilot from CC?
@github Yes, the main idea is that Gpt5.4 for review and adversarial review of code or plan file
@github But you can also delegate tasks because Premium Requests is better than current CC pricing and usage

@github Have you done any comparisons yet to Anvil and its adversarial review?

@github Your boss @satyanadella retweeted

@github rubber ducking helps, but pairing it with property-based tests multiplies the impact

@github Rubber Duck agent for cross-model review is brilliant — different model families catch different blind spots.

The 74.7% gap closure is wild. We've been doing something similar manually — running Claude Code output through a GPT review step before committing. Cross-model validation catches a completely different class of errors than self-review. The key insight: models from the same family share the same blind spots. A second opinion from a different architecture is like getting a code review from someone with a different tech stack background.

@github Great, it's my workflow since we can ask for copilot some like this: "use gpt 5.x to build, Gemini and opus to review the code. In the end make a debate to validate the findings."
@github Love the "debate" word there. That probably does a lot of heavy lifting on the semantics of the prompt.

@amandaksilver @github Fascinating

@github Seems like this naturally offloads complex reasoning to higher model and leaves straightforward execution to cheaper model. So you could rubber duck Sonnet with Opus and still get more efficiency.

@martinwoodward @github Do we have this in vs code too?
@martinwoodward @github Not quite yet!

@github They should now plan for a graceful shut down of GitHub Copilot. They kind of fucked up the advantage - typical Microsoft.

Cross model review is such a good idea. Different training data means different blind spots. The principle that two sets of eyes catch more bugs applies to AI too. Running critical payment logic through multiple models for review is something teams should start building into their workflows.

@github The rubber-duck feature is really useful but it seems incredibly slow. Any idea what the reason for that is? How can we debug this? @_Evan_Boyle

@github

@github Smart

@github Is this available for copilot chat?
@github Just the CLI atm

This is such a powerful validation of multi-model cross-checking. Using a different AI family effectively breaks the "echo chamber" effect of a single LLM, catching the logical blind spots that one specific architecture might overlook. It feels like we’re moving toward a future where the gold standard for production code will be "consensus-driven" validation across diverse model architectures.