Video wird geladen...

Video konnte nicht geladen werden

Zur Startseite

Today we release LFM2.5-Encoder-230M and LFM2.5-Encoder-350M: bidirectional encoders that stay fast at long context, even on CPU. > LFM2.5-Encoder-230M: about 3.7x faster than ModernBERT-base on CPU at 8,192 tokens. Under 30s per forward pass, versus over a minute and a half. > LFM2.5-Encoder-350M: 4th of 14 models on GLUE,...

198,990 Aufrufe • vor 1 Monat •via X (Twitter)

35 Kommentare

Profilbild von Liquid AI
Liquid AIvor 1 Monat

Two sizes in the same family: > LFM2.5-Encoder-350M: the higher-accuracy pick. > LFM2.5-Encoder-230M: smaller and faster, for tighter hardware or higher throughput. Both are pre-trained with a masked-language objective, so you fine-tune them for classification, token-level tasks, or retrieval. (2/6)

Profilbild von Liquid AI
Liquid AIvor 1 Monat

Built on the LFM2 hybrid backbone, adapted from causal decoders into bidirectional encoders: bidirectional attention, non-causal short convolutions, and a 30% mask rate. The backbone's cost grows slowly as inputs get longer. > Context: 8,192 tokens, about 13 to 15 pages in one forward pass. > Runs on CPU with no GPU, where the speed edge is largest. > On GPU, the same pattern holds at the longest inputs. (3/6)

Profilbild von Liquid AI
Liquid AIvor 1 Monat

See it in action. We built demos that run entirely on CPU: > Prompt routing: > Policy linting: > Spell checker: Bonus: we even run the encoder as a masked-diffusion chatbot. (4/6)

Profilbild von Liquid AI
Liquid AIvor 1 Monat

LFM2.5-Encoder-230M and LFM2.5-Encoder-350M are available now. > LFM2.5-Encoder-230M: > LFM2.5-Encoder-350M: > Blog: > Docs:

Profilbild von HT - Galactic President Superstar McAwesomeville
HT - Galactic President Superstar McAwesomevillevor 1 Monat

Will there be ONNX weights released? Can't wait to run it on the edge!

Profilbild von Maksim Kuznetsov
Maksim Kuznetsovvor 1 Monat

Great news! Excited to try it out. LFM2-2.6B was a perfect base model for our C3LM!

Profilbild von Pau Labarta Bajo
Pau Labarta Bajovor 1 Monat

Great job Viviana ❤️

Profilbild von Jaya Nayak
Jaya Nayakvor 1 Monat

Sub-30 second forward passes on a CPU at 8k tokens is absolute magic. 😊

Profilbild von AX⚡
AX⚡vor 1 Monat

952.4 t/s 0.6gb vram for 350M

Profilbild von Vantix AI Agency
Vantix AI Agencyvor 1 Monat

LFM2 5 Encoders deliver long context speed on CPU

Profilbild von Axly
Axlyvor 1 Monat

LiquidAI just makes a great model. I recently built an iOS app, that runs the LFM 8b a1b at 50 tokens per second. Crazy, right?

Profilbild von Neeraj Kumar
Neeraj Kumarvor 1 Monat

Fast long context on CPUs could quietly unlock many practical deployments. Impressive work.

Profilbild von Hussein Kizz ★
Hussein Kizz ★vor 1 Monat

You guys are doing the most important work right now, and making AI applicable and useful, thanks so much!

Profilbild von Jacob Portes
Jacob Portesvor 1 Monat

awesome! @zach_nussbaum

Profilbild von Gregor
Gregorvor 1 Monat

the under 30s figure, what batch size is that at? single sample vs batched throughput is a totally different story for anything doing live inference at scale

Profilbild von luis
luisvor 1 Monat

@Presidentlin

Profilbild von Melvin Vivas
Melvin Vivasvor 1 Monat

wow, this is awesome

Profilbild von Ege Sabanci
Ege Sabancivor 1 Monat

incredible work! we are deeply admiring the open source contributions of @liquidai as @koniclabs keep up team 🫡

Profilbild von paolo
paolovor 1 Monat

Great job, I am looking for a simple practical application in office wotk

Profilbild von Mykhailo Sorochuk
Mykhailo Sorochukvor 1 Monat

8k token context on CPU at that speed is a game changer for lightweight pipelines

Profilbild von AI Mastery Guide
AI Mastery Guidevor 1 Monat

Beating a model 10x its size on GLUE is a huge efficiency win.

Profilbild von bnw
bnwvor 1 Monat

question: when would I use this over something like sentence-BERT? for larger documents and if I want it on CPU?

Profilbild von Sebastian Buzdugan
Sebastian Buzduganvor 1 Monat

cpu wins at batch size 1 often disappear once batching enters production

Profilbild von GANGA TODAY
GANGA TODAYvor 1 Monat

Generative Reasoning Protocol (GRP) v0.6

Profilbild von Andrii
Andriivor 1 Monat

4th of 14 on GLUE/SuperGLUE while being roughly a third the size of most competitors is a legitimate benchmark result, but the more interesting number is the 3.7x CPU speedup at 8,192 tokens — that's the one that actually determines whether prompt routing runs cheaply enough to sit in front of every request instead of being a nice-to-have.

Profilbild von Aivan Monceller
Aivan Moncellervor 1 Monat

Are you planning to publish the training code for the t the zero shot dual tower head, and an official ONNX

Profilbild von Eplurubusnullus
Eplurubusnullusvor 1 Monat

You guys beat me to it. This is what I've been trying to train for meept (

Profilbild von Mauro S.
Mauro S.vor 1 Monat

great job!👏

Profilbild von toriset
torisetvor 1 Monat

looks pretty cool, but is this worth it to use for LLM routing? by like choosing the subset that a task is in, out of hundreds, and then later after its classified pick the model that fits all criterias / scores best?

Profilbild von ZenithAi
ZenithAivor 1 Monat

Impressive efficiency gains for long-context encoder workloads

Profilbild von 코지베어 🐻 CozyBear
코지베어 🐻 CozyBearvor 1 Monat

Bidirectional encoders staying fast on CPU at 8k tokens is quietly a bigger deal than most launches this week. Reranking is the part of RAG everyone still ships to a GPU box out of pure habit. Curious how much of that 3.7x survives int8 quantization. Did you benchmark on commodity hardware too?

Profilbild von Mert Kaya
Mert Kayavor 1 Monat

Great work!

Profilbild von Sophie
Sophievor 1 Monat

350M 跑 128K 上下文延迟多少?

Profilbild von No Body
No Bodyvor 1 Monat

Babe wake up liquid AI just dropped a new thalamus routing model

Profilbild von Regi Kusumaatmadja
Regi Kusumaatmadjavor 1 Monat

interesting!

Ähnliche Videos

QVAC SDK 0.15.0 is live. This release adds multiple prompts batching, brings a native AMD GPU backend to the stack, moves more vision encoders onto mobile GPUs, and adds a second local coding-agent integration. Main highlights: - Prompt batching for the LLM addon. Batch multiple prompts into one job and process them concurrently, with each answer returned the moment its generation finishes. - Native AMD GPU backend. A first-class HIP/ROCm backend in @qvac/vla-ggml, auto-selected over Vulkan with clean fallback when ROCm is absent. - A second local coding agent. OpenClaw joins OpenCode for local, cloud-free agent workflows. AGENTS - OpenCode plugin update (@qvac/opencode-plugin). Aligned with the current SDK, CLI, and AI SDK provider packages. A fresh install runs OpenCode against managed local QVAC models out of the box, from the default qvac/qwen3.5-9b, with no manual qvac serve setup. - OpenClaw plugin (@qvac/openclaw-plugin). A second coding-agent integration alongside OpenCode. A fresh setup installs the plugin, creates a local qvac provider through onboarding, and runs a QVAC model through OpenClaw🦞's local service path. LANGUAGE MODELS - Prompt batching (LLM addon). Batch multiple prompts in one job and run them concurrently, each answer returns the moment its generation finishes, no waiting on the others. - Reasoning-context trimming on hybrid + recurrent models (@qvac/llm-llamacpp). remove_thinking_from_context now works beyond pure-attention models. Same JS API, no throw. VOICE AND SPEECH - Transcription (transcription-parakeet 0.9.0). More robust CPU fallback on GPU failure and a faster Vulkan backend on Pixel 9. - Text-to-speech features (tts-ggml 0.4.0). Adds LavaSR for noise removal and adjustable output frequency up to 48 kHz, plus Japanese via Chatterbox. - Text-to-speech fixes (tts-ggml 0.4.1). CPU fallback on GPU failure, a q8_0 KV crash fix on Metal with Chatterbox. VISION - Qwen3.5 vision encoder on GPU (Android). Image encoder moves onto the phone GPU, with a smarter tile-grid preprocessor and default image-token caps, for flagship Android: Vulkan on Mali (Pixel 9 Pro) and OpenCL on Adreno 830 (Galaxy S25). - Gemma-4 vision encoder on GPU (Android). Vision encoder runs on the phone GPU instead of CPU, same flagship Android targets. PLATFORM AND PERFORMANCE - AMD GPU backend (@qvac/vla-ggml). Native HIP/ROCm backend, auto-selected over Vulkan with clean fallback when ROCm is absent (Linux x64 only). Comes with ~23% faster than Vulkan, ~14% faster than PyTorch-ROCm, parity preserved. Unified code style. A cleaner, more consistent, easier-to-contribute codebase. Let's build. npm install @qvac/sdk

QVAC

29,260,217 Aufrufe • vor 2 Monaten

UC Berkeley just open-sourced FreeToken. (2–4x faster local LLM inference than Ollama) the results are wild: - Qwen3.6-35B on an 8GB GPU at 39.3 tokens/s - DeepSeek-V4-Flash 284B on a 32GB GPU at 22 tokens/s - GLM-5.2 753B on a 96GB GPU at 14.9 tokens/s a 35B model at 16-bit precision needs about 70GB just for its weights. even at 4 bits it is close to 18GB, and FreeToken serves it on an 8GB GPU. let me explain how: all three models mentioned above are Mixture-of-Experts, and that is what FreeToken takes advantage of. each layer holds hundreds of separate experts plus a small router that picks a few of them per token. Qwen3.6-35B activates roughly 3B of its 35B parameters per token. DeepSeek-V4-Flash picks 6 of 256 experts per layer, so 13B of its 284B run at a time. so compute was never the bottleneck. the weights a single step touches fit comfortably on a consumer GPU. every expert the router might pick still has to exist somewhere. they sit in system RAM, and the GPU keeps a cache of the ones the model has been using recently. so everything comes down to what happens when the router picks an expert that is not on the GPU. there are two ways to serve that miss: 1. copy it over PCIe and run it on the GPU 2. run it on the CPU, where it already lives both read from the same system memory, so they compete for one pool of bandwidth instead of adding to each other. existing engines pick one option and freeze it when the model loads. but routing changes on every token, so a fixed choice misses most of what the model asks for. FreeToken measures both bandwidths on your machine and splits each step's misses between the two paths in proportion. the GPU and CPU results then merge exactly, with no approximation. two machines with the same GPU can end up wanting opposite strategies, which I did not expect. a 5090 in a gaming desktop should push nearly everything over PCIe, while an 8GB laptop is better off computing most misses on the CPU. none of that is readable off a spec sheet, so the engine profiles it once per machine. the second half of the design is about agents. coding agents constantly rewrite their own history, and every edit normally forces thousands of tokens back through prefill. FreeToken saves its checkpoints at the exact boundaries agent frameworks cut on, so it only reprocesses the new part. its slowest first token stays under 44 seconds, while llama.cpp peaks at 232 and KTransformers at 946. it serves the OpenAI and Anthropic APIs under Apache 2.0, so Claude Code and Codex can point at it directly. releasing weights publicly decides who can download a model, not who can afford to run one. frontier open models keep shipping, and running them still assumes a rented cluster. meanwhile there are over a hundred million consumer machines with discrete GPUs sitting mostly idle. closing that gap was never a hardware problem, and work like this is what turns open weights into something you can actually use. paper: repo: almost every idea in this post, from why memory bandwidth decides the outcome to why moving weights costs more than computing on them, comes straight out of how a GPU is built. I wrote a detailed primer on that. the article is quoted below.

Akshay 🚀

343,270 Aufrufe • vor 1 Monat

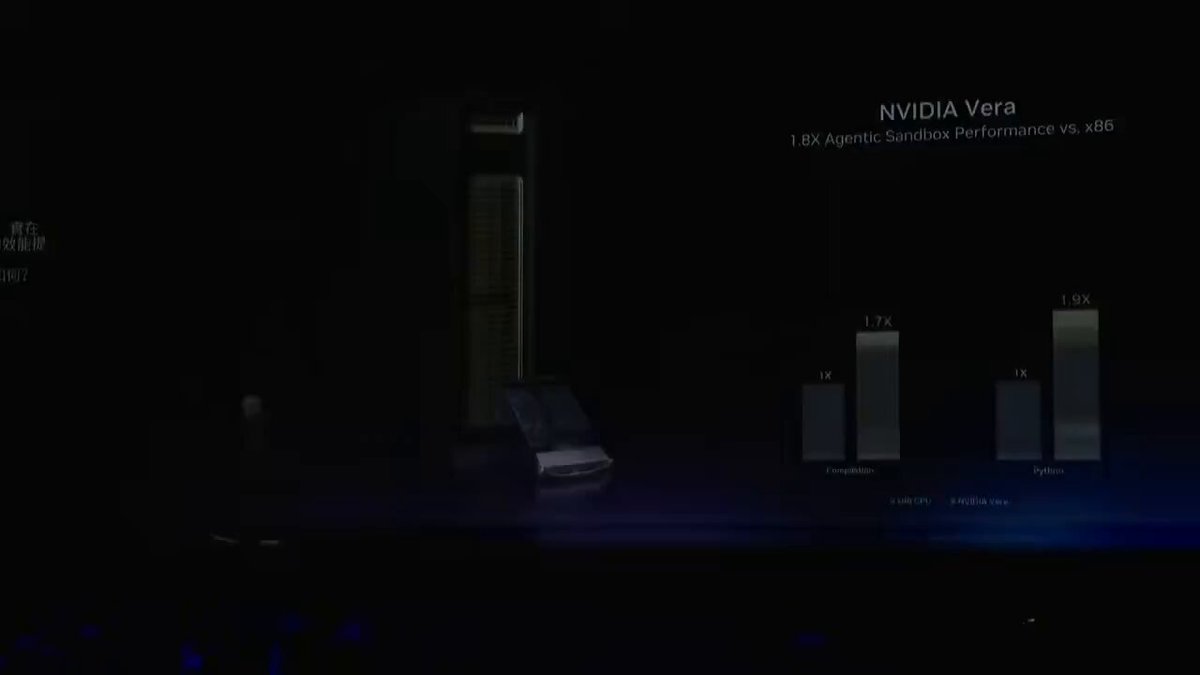
Jensen Huang just identified the next $200 billion market (Save this). The shift starts with a observation about agentic AI that changes everything about infrastructure. In the era of training and inference, the GPU was everything while CPU was a traffic cop, scheduling work, managing memory, dispatching tasks while the GPU did the heavy lifting. Agentic AI breaks that model entirely. An AI agent does not just run a single inference pass but rather it plans, calls tools, executes code in sandboxes, retrieves data from multiple sources and loops through complex multi-step reasoning sequences often thousands of times per second at scale. Every one of those operations runs through the CPU and the GPU sits idle waiting for the CPU to prepare the next task, supply the right context and execute the retrieval and tool calling logic fast enough to keep the accelerators fed. The CPU is now the conductor and the GPU is the orchestra and the bottleneck is the conductor falling behind. This is showing up in production AI factory utilization right now, which is exactly why Jensen built Vera from scratch rather than licensing x86. Vera achieves 40% lower peak memory latency than x86, 50% faster core to core communication, and 1.8 times the agentic sandbox performance of current x86 processors on a purpose-built architecture designed around the agentic loop. Now here is where the investment thesis gets interesting. The obvious beneficiary is Nvidia itself, and that thesis is real. Nvidia's CFO has guided for nearly $20 billion in Vera CPU revenue this fiscal year alone, a market Nvidia had zero presence in just three years ago. Intel held 60% of server CPU market share as recently as Q4 2025 and that transition is now happening at a pace Intel structurally cannot respond to. But the deeper question is, what architecture is Vera actually built on? Vera's Olympus cores are ARM compatible and every single Vera CPU deployed in every Vera Rubin rack in every data center in the world runs on ARM architecture. And ARM Holdings collects a royalty on every one of them. ARM does not make chips but rather licenses the instruction set architecture and CPU core designs that others build on top of. Every time Nvidia ships a Vera CPU, every time a hyperscaler deploys a Vera Rubin rack, every time an enterprise qualifies Vera for their AI factory, ARM earns a royalty. The secular tailwind here is almost perfectly constructed for ARM's business model. Amazon's Graviton, Microsoft's Cobalt, Google's Axion, Apple's silicon stack, and Qualcomm's data center push all run on ARM. And now Nvidia's Vera, which is projected to displace Intel as the largest server CPU supplier by revenue in a single fiscal year, is ARM. ARM's royalty rate on high end server chips is estimated at roughly 1 to 2% of chip selling price. At $5,000 per Vera CPU and 4 million units projected for FY2027, that is a royalty line growing from near zero to potentially $400 million to $800 million annually from Nvidia's data center CPU business alone before counting Amazon, Microsoft, Google, Apple, and Qualcomm. The total ARM addressable royalty base across all the silicon it already licenses is compounding at a rate that the current $130 billion market cap does not fully reflect. Jensen's CPU thesis is the most underappreciated catalyst in ARM's fundamental story, and the royalty compounding has barely started. Come join Milk Road Pro and get our full ARM royalty model and our entire AI trade thesis. Link below!

Milk Road AI

11,819 Aufrufe • vor 3 Monaten

Google just proved that bigger isn't always better. Their 308M parameter model is outperforming models 2x its size. Google just released 𝗘𝗺𝗯𝗲𝗱𝗱𝗶𝗻𝗴𝗚𝗲𝗺𝗺𝗮, and it's proving that lightweight embedding models can punch way above their weight class. At just 308M parameters (578MB), it's the new state-of-the-art for models under 500M parameters across MTEB multilingual, English, and code benchmarks. But the really impressive part is that it ranks 8th overall on MTEB(Multilingual, v2) - that's 𝟭𝟳 𝗽𝗹𝗮𝗰𝗲𝘀 above the second-best sub-500M model, and it's delivering performance 𝗰𝗼𝗺𝗽𝗮𝗿𝗮𝗯𝗹𝗲 𝘁𝗼 𝗺𝗼𝗱𝗲𝗹𝘀 𝗻𝗲𝗮𝗿𝗹𝘆 𝗱𝗼𝘂𝗯𝗹𝗲 𝗶𝘁𝘀 𝘀𝗶𝘇𝗲. There are three key parts of their training recipe that sets it apart: 𝟭. 𝗘𝗻𝗰𝗼𝗱𝗲𝗿-𝗗𝗲𝗰𝗼𝗱𝗲𝗿 𝗜𝗻𝗶𝘁𝗶𝗮𝗹𝗶𝘇𝗮𝘁𝗶𝗼𝗻 Instead of starting from a decoder-only Gemma 3 model, they first adapted it to encoder-decoder, then used just the encoder. By basing EmbeddingGemma off an LLM that already has world and language understanding, it gives it a stronger starting point. 𝟮. 𝗧𝗵𝗿𝗲𝗲-𝗟𝗼𝘀𝘀 𝗧𝗿𝗮𝗶𝗻𝗶𝗻𝗴 They combine three different loss functions, instead of just having one: • Contrastive loss (NCE) with in-batch negatives and hardness weighting • Spread-out regularization to ensure embeddings utilize the full space (for quantization and ANN retrieval) • Embedding matching distillation from Gemini Embedding - not just learning from relevance scores, but directly aligning the embedding space with the teacher model 𝟯. 𝗠𝗼𝗱𝗲𝗹 𝗦𝗼𝘂𝗽𝗶𝗻𝗴 Rather than just averaging checkpoints from the same training run, they use optimization techniques to find multiple specialized training mixtures. Each mixture creates an "expert" model in different domains, and averaging all their parameters creates a final model that's actually better than individual models. Extras: • Matryoshka embeddings supporting 768, 512, 256, and 128 dimensions • Quantization-aware training - maintains quality even at int4 precision • 100+ languages from Gemma 3 pretraining • Exceptional performance on low-resource languages (check their XTREME-UP results) Is it the absolute best embedding model? No - Gemini Embedding still leads overall. But that's not really the point. EmbeddingGemma proves you can achieve state-of-the-art performance in a small package that's actually deployable on-device, in low-latency applications, and in resource-constrained environments. This makes good embeddings accessible for use cases that I'm seeing more and more: offline applications, privacy-sensitive deployments, and high-throughput scenarios where inference cost actually matters. Full paper: Shoutout to the EmbeddingGemma team at Google DeepMind for this awesome open source work 💙 and to Daniel Williams for helping me with this video! 🫶

Victoria Slocum

21,610 Aufrufe • vor 10 Monaten

New short course: Attention in Transformers: Concepts and Code in PyTorch. Last week we released a course on how LLM transformers work. This week, go deeper and learn about the technical ideas behind the attention mechanism, and see how to code it in PyTorch. This course is built with Joshua Starmer, Founder and CEO of StatQuest. The attention mechanism was a breakthrough that led to transformers, the architecture powering large language models like ChatGPT. Transformers, introduced in the 2017 paper: "Attention is All You Need" by Viswani and others, took off because of its highly scalable design. In this course, you’ll learn how the attention mechanism, a key element of transformer-based LLMs, works and implement it in PyTorch. You'll develop deep intuition about building reliable, functional, and scalable AI applications. What you will do: - Understand the evolution of the attention mechanism, a key breakthrough that led to transformers. - Learn the relationships between word embeddings, positional embeddings, and attention. - Learn about the Query, Key, and Value matrices, and how to produce and use them in attention. - Walk through the math required to calculate self-attention and masked self-attention to learn why and how they work. - Understand the difference between self-attention and masked self-attention and how one is used in the encoder to build context-aware embeddings and the other is used in the decoder for generative outputs. - Learn the details of the encoder-decoder architecture, cross-attention, and multi-head attention and how they are all incorporated into a transformer. - Use PyTorch to code a class that implements self-attention, masked self-attention, and multi-head attention. There're lots of exciting technical details in this course. Please sign up here:

Andrew Ng

132,516 Aufrufe • vor 1 Jahr