Загрузка видео...
Не удалось загрузить видео
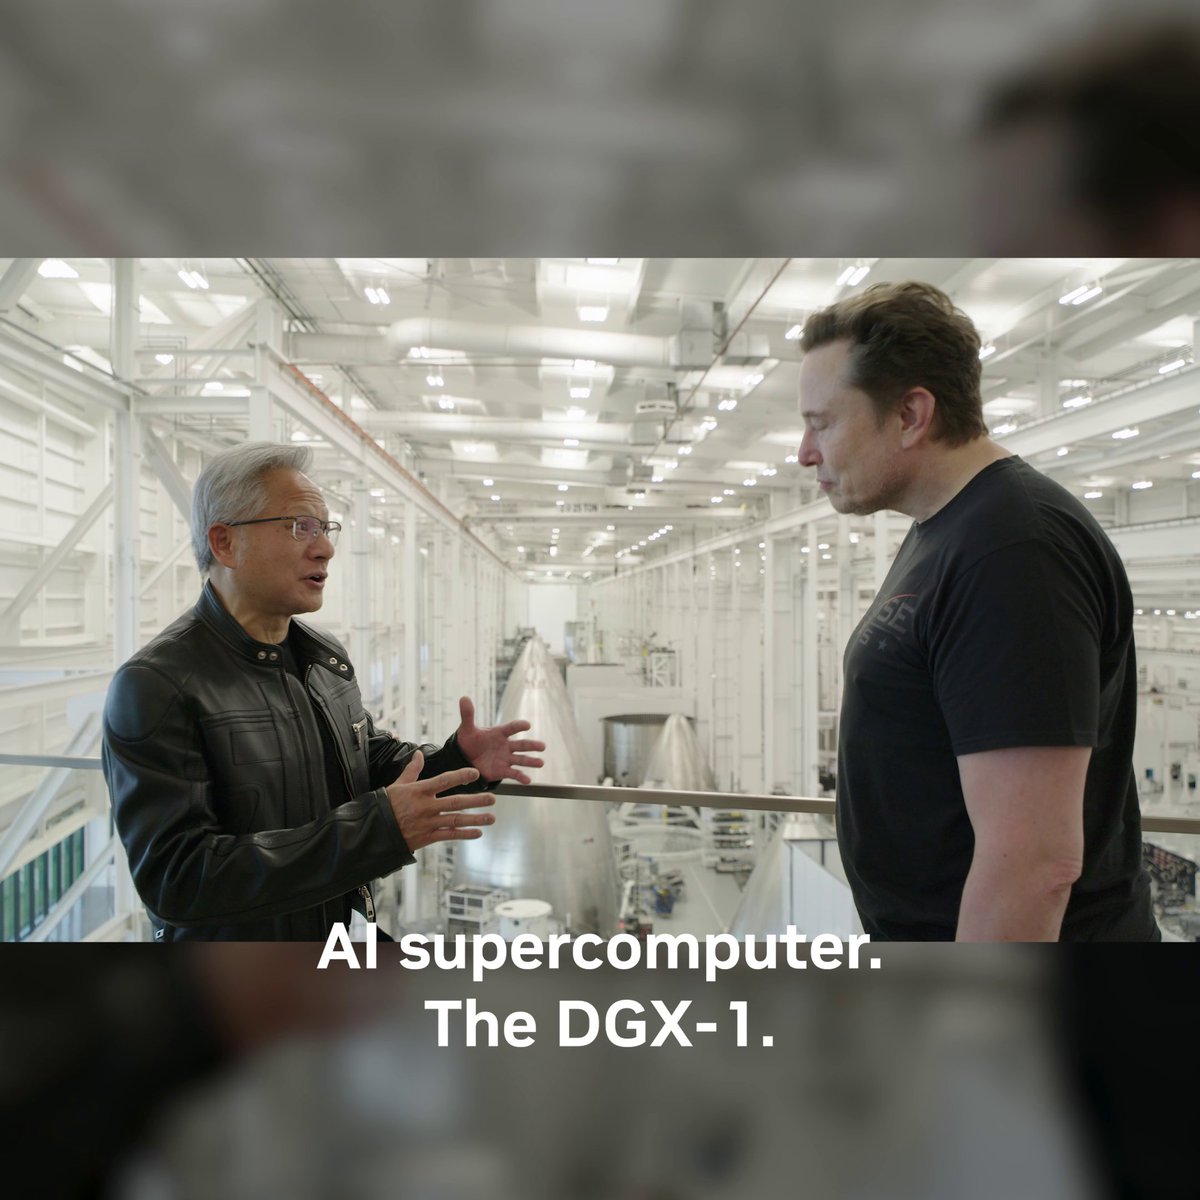
Watch Gemma-4-26B running 18 concurrent sessions on a single NVIDIA AI DGX Spark — delivering a cumulative 300 tokens per second. 🔥
23,211 просмотров • 2 месяцев назад •via X (Twitter)
Комментарии: 44

It this blows your mind wait for the next video 👀
ttft was almost instant on all 18 sessions

@NVIDIAAI 300 tok/s cumulative is nice, but at 18-way concurrency I immediately want TTFT and p95 latency. Aggregate TPS is the GPU's lawyer.

@NVIDIAAI Nice you have a chatbot. Now try to make tool calling. Lol...

@NVIDIAAI That is rocking!!!!
@NVIDIAAI pretty insane yeah
@NVIDIAAI I have a sneaking suspicion this may be THE coding model for single Spark

@NVIDIAAI With RTX5070Ti, I can get 300tps on Gemma with enough money remaining to purchase over 50 pogo sticks.

@NVIDIAAI

@NVIDIAAI 🔥

@NVIDIAAI I’m seeing similar numbers.

@NVIDIAAI Wow

@NVIDIAAI Can DGX run Gemma and Qwen at once for agentic setup via Hermes? If so hiw many tokens and context it can do?
@NVIDIAAI It can but I wouldn't recommend. Better run one model are have the most kv cache possible to maximize concurrency.
@NVIDIAAI Got it! So ideally DGX 2x 😅

@NVIDIAAI What is the context size?
@NVIDIAAI 256k with mtp

@NVIDIAAI this is gemma4 26b qat model? what setting u using on dgx
@NVIDIAAI I just posted a full recipe

@NVIDIAAI Are these sessions doing anything useful?
@NVIDIAAI Yes, they test how well concurrent sessions work with Gemma4-26b on a DGX Spark.

@NVIDIAAI Are they slowly all writing the same book? lol

@NVIDIAAI It looks like all tasks are repeating the same story. How does it perform when doing 18 concurrent coding tasks? what's the quality of the output?

@NVIDIAAI This feel amazing Mia! I need to start playing more and find use case, is this cmux ?
@NVIDIAAI tmux with xpanes

@NVIDIAAI Can you share how you start the serving software (vLLM, Ollama with parameter)?🙇🏻
@NVIDIAAI There is a recipe

@NVIDIAAI Impressive 🔥

@NVIDIAAI But what is it DOING? My feed is full of countless influencers posting stuff like this but hardly ever anything that’s actually concrete for their business in a way that pays for itself plus all the opportunity cost that could have went into other parts of the business.

But do they do anything useful? Like surf the web and retrieve data, or run multiple successful tool calls in succession? I see a lot of these demos, but when you connect them to real harnesses, they fail miserably due to a focus on speed and not accuracy. You need both to be practical and useful.

@NVIDIAAI Concurrency is the real superpower. What was the context of each roughly?

@NVIDIAAI If you are looking for a cheap local AI dictation app for Mac. Checkout

@NVIDIAAI $4k for wht ( DGX Spark I mean )? Let's see wht world class product it comes out with those 18 sessions.

@NVIDIAAI ok how much is that spark?

@NVIDIAAI that’s insane,how would you rate the quality of the output

@NVIDIAAI if this is a loop then it madness😯

@NVIDIAAI

@NVIDIAAI What's the prefill speed like

@NVIDIAAI 最有趣的不是 300 tok/s 這個數字 而是 DGX Spark 作 ISP 這種不常見的把戲 把 NPU 當實驗計畫管理大師 這種資源分配模式其實跟編譯器 idle pipeline 很像 只是 inputs 是 human conversations

@NVIDIAAI This is great and all but I don't think Gemma4 good enough to actually use for anything

@NVIDIAAI 300 tokens of 🔥 garbage that is >.>

@NVIDIAAI now verify the output isn’t 100% trash.

@NVIDIAAI ok over what? vllm? llama.cpp? would be nice if you can not only flex, but also help...

@NVIDIAAI My iPhone crashed watching this.