Loading video...

Video Failed to Load

Go Home

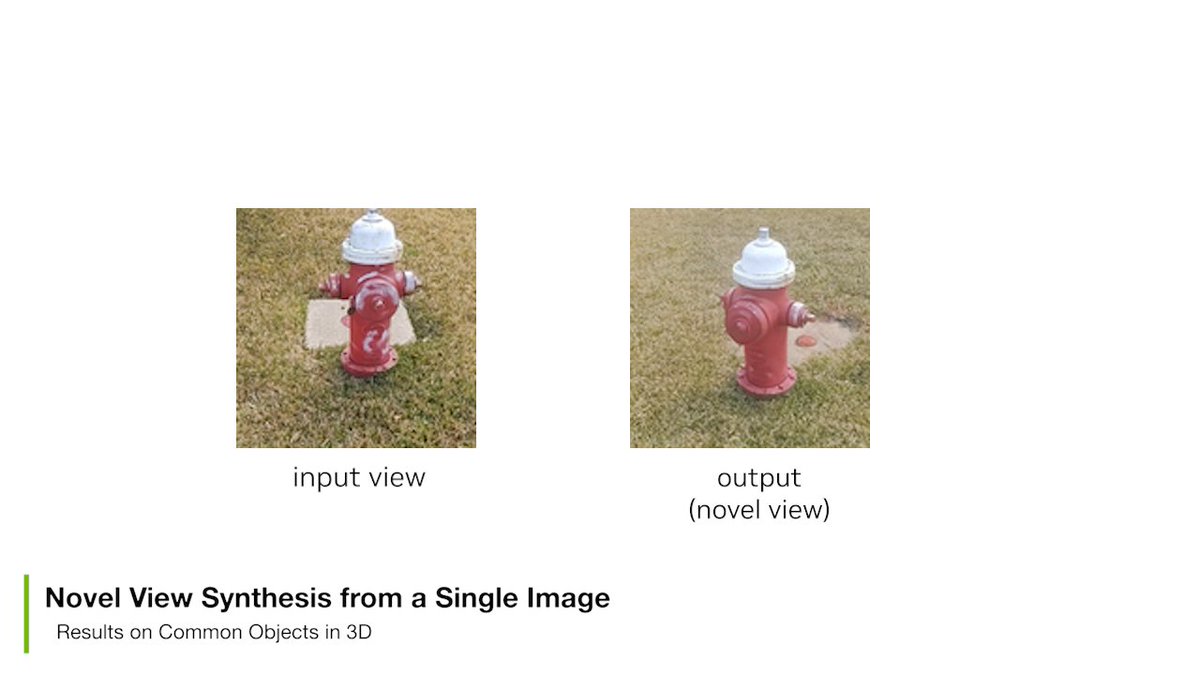
We also present another paper at ACM SIGGRAPH 2023 on neural implicit 3D Morphable Models that can be used to create a dynamic 3D avatar from a single in-the-wild image. (Lead author Connor Lin).
12,786 views • 3 years ago •via X (Twitter)

2 Comments

Koki Nagano's profile picture
Koki Nagano3 years ago

@connorzl Our method uses flexible implicit 3D representations for geometry/color but also learns explicit UV texture parametrization to allow intuitive texture editing as well as provides all intuitive controls like traditional 3DMMs. Paper and more results:

soyboy's profile picture
soyboy3 years ago

@siggraph @connorzl Q. Is there anything in the pipeline that makes it face specific? With chair training data, can it produce chairs?

Related Videos

One-2-3-45: Any Single Image to 3D Mesh in 45 Seconds without Per-Shape Optimization paper page: Single image 3D reconstruction is an important but challenging task that requires extensive knowledge of our natural world. Many existing methods solve this problem by optimizing a neural radiance field under the guidance of 2D diffusion models but suffer from lengthy optimization time, 3D inconsistency results, and poor geometry. In this work, we propose a novel method that takes a single image of any object as input and generates a full 360-degree 3D textured mesh in a single feed-forward pass. Given a single image, we first use a view-conditioned 2D diffusion model, Zero123, to generate multi-view images for the input view, and then aim to lift them up to 3D space. Since traditional reconstruction methods struggle with inconsistent multi-view predictions, we build our 3D reconstruction module upon an SDF-based generalizable neural surface reconstruction method and propose several critical training strategies to enable the reconstruction of 360-degree meshes. Without costly optimizations, our method reconstructs 3D shapes in significantly less time than existing methods. Moreover, our method favors better geometry, generates more 3D consistent results, and adheres more closely to the input image. We evaluate our approach on both synthetic data and in-the-wild images and demonstrate its superiority in terms of both mesh quality and runtime. In addition, our approach can seamlessly support the text-to-3D task by integrating with off-the-shelf text-to-image diffusion models.

AK

179,061 views • 3 years ago

Want to create an avatar from a single image? FlexAvatar is a transformer model that creates full 360°, high-quality, and expressive 3D head avatar from just a single portrait image in minutes. Real-time Demo: FlexAvatar's lightweight architecture allows both animation and rendering in real-time, enabling interactive user experiences. To create a new 3D head avatar, only one image is required, e.g., from a webcam. The final avatar is ready after 2 minutes. Architecture: Under the hood, FlexAvatar adopts a transformer-based encoder-decoder design. The encoder maps the input image onto a latent avatar space, while the decoder produces 3D Gaussian attribute maps by incorporating the animation signal via cross-attention. The model learns all facial animations directly from the data without relying on pre-built 3D face models. This equips the avatars with realistic facial expressions. The internal avatar latent space can be conveniently used to integrate additional observations of a person via fitting. This enables use-cases where more than one image of a person is available, e.g., from a phone scan of the person. We train jointly on 2D monocular videos and multi-view data. However, in monocular videos, the animation signal leaks the target viewpoint, causing the model to produce incomplete 3D heads. We call this phenomenon entanglement of driving signal and target viewpoint. To prevent entanglement, we introduce bias sinks. These are learnable tokens that indicate whether a training sample stems from a monocular or a multi-view dataset. During training, the model learns to produce incomplete 3D heads only when the monocular token is present. During inference, FlexAvatar then always uses the multi-view token for which the model has learned to produce complete 3D heads. This simple design allows to combine the generalizability from monocular data with the quality of multi-view data. FlexAvatar summary: - Input: Single-image, phone scan, or monocular video - Output: Full 360° head avatar - Expressive animations - Real-time rendering and animation - Generalization to any portrait - Create a new avatar in 2 minutes - Use bias sinks to combine 2D and 3D data 🏠 🌍 🎥 Great work by Tobias Kirschstein and Simon Giebenhain!

Matthias Niessner

96,371 views • 10 months ago