Video yükleniyor...
Video Yüklenemedi
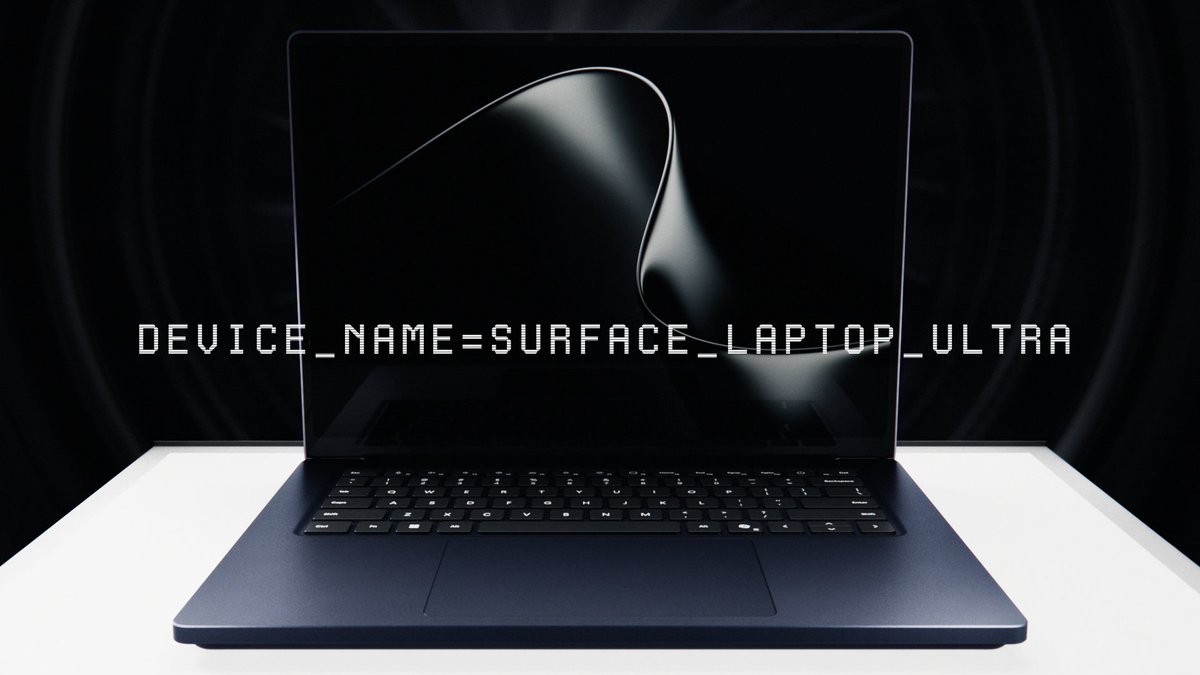
We are getting 2 new devices from NVIDIA and Microsoft: 1. The DGX Station, with GB300 superchip and up to 748GB of memory. 2. The RTX Spark laptop, with 1 petaflop of AI performance and 128GB of unified memory. The hardware here is pretty bonkers! Think about it this way:

15,307 görüntüleme • 3 ay önce •via X (Twitter)
13 Yorum

For the first time ever, you will be able to run a trillion-parameter model on your personal hardware. They announced many more things, but there's something else I want to share: They are running a 5-day mini-program to help developers ship agentic AI running on NVIDIA-accelerated Azure AI Foundry. Here is the Builder's Arcade program: • Day 1 - Run your first AI workload • Day 2 - Deploy your model as a service • Day 3 - Wire your model into an agentic workflow • Day 4 - Make your model faster and cheaper • Day 5 - Focus on governance, monitoring, and observability Go through this. It will take a few hours, and you'll learn a TON! Link to the Builder's Arcade: Here is the link to the announcements: Thanks to the Microsoft and NVIDIA teams for partnering with me on this post.

1 petaflop inference, 748GB training. Both companies announcing because custom silicon is coming. This is what it looks like when a duopoly gets spooked.

trillion param on local hardware changes everything for voice agents. latency was always the killer. this might actually fix it

a dgx station class box on the factory floor changes the math — no cloud bill, no latency, production data never leaves the building. we've held off on vision models partly over connectivity 🤔 wonder how they'll price these vs a year of cloud inference?

A time will come when you’ll be able to run big ai models on your laptop itself

I'm not worried about the hardware. I'm more worried about Microsoft executing the software well. ARM laptops have existed before.

Running voice agents on edge hardware, latency matters more than size. What's the actual inference speed on consumer GPUs? Trillion-param means nothing if it's slow.

I really want the RTX Spark. Could run Deepseek like a dream.

more and more hardware built specifically for AI is appearing

That RTX Spark laptop with 128GB unified memory? That's huge for local LLM fine-tuning without the cloud. We've been waiting for this kind of power.

RTX Sparkの128GB統合メモリは素晴らしいが、1ペタFLOPの性能を維持するには冷却と電源供給が鍵だ。

Awesome. Pretty keen to see the laptop pricing when it eventually comes out. Hopefully some 'budget' 32GB and 48GB type options are released also.

A petaflop laptop with 128GB unified memory changes local model math completely.