正在加载视频...
视频加载失败
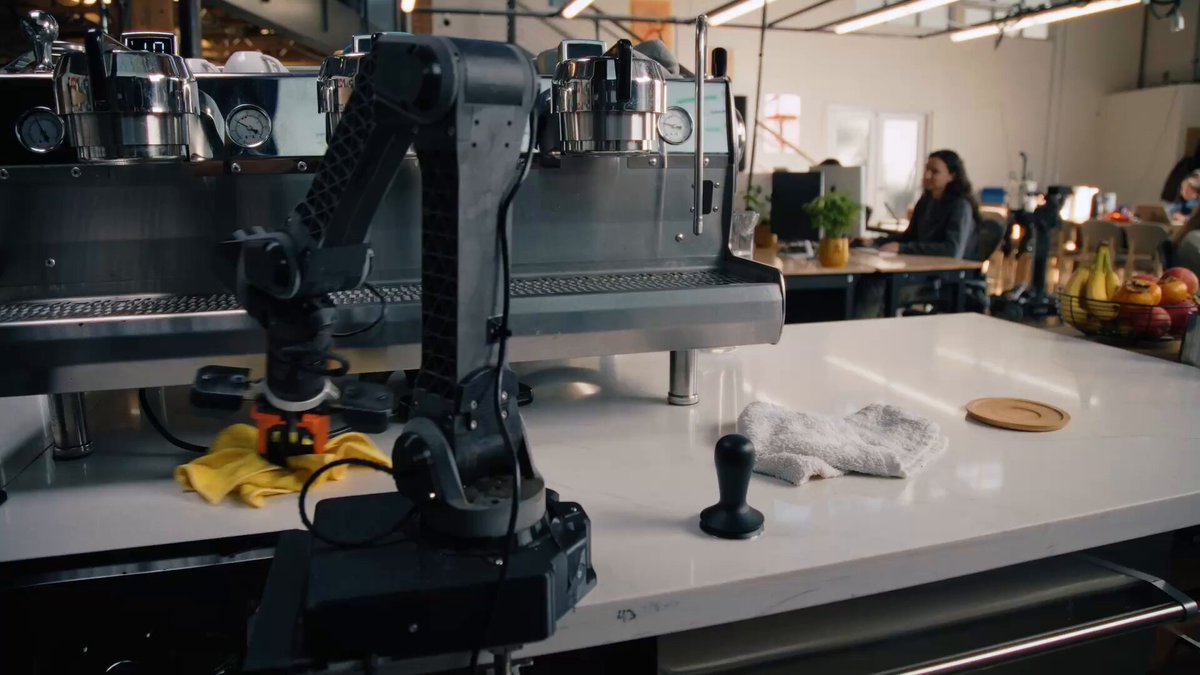
We can learn a model that provides shaped "process rewards" for robotic RL, that evolves automatically as the policy gets better. This improves performance on benchmarks, and works in the real world! Some fun new work with Raymond Tsao & Andrew Wagenmaker
38,514 次观看 • 4 个月前 •via X (Twitter)
5 条评论

Sergey Levine4 个月前
In the real world, this leads to drastically faster learning, in just a few thousand time steps.
Sergey Levine4 个月前
To learn more, check out website: paper:

Hari4 个月前
@ajwagenmaker This is cool! Every time I do robotics research I remember dense reward is still overpowered for task mastery, and the more self supervised we can learn the better :)

Manan4 个月前
@ajwagenmaker Cool!

Ferbin4 个月前
@ajwagenmaker Does that hold with actual robots, or just in simulation?