Wësche's banner
Wësche's profile picture

Wësche

@WescheNex1q2,685 subscribers

Day time artist and night time AI enthusiast. Building & benchmarking frontier LLMs on 4x DGX Spark clusters + Mac. Creator of Vesica Studio. Houston

Shorts

Qwen 3.8 27b nvfp4 vs Grok 4.6 Someone tell me how this local model that is 100x smaller and 10x slower made a better animation?! Elon Musk help us solve this, both with their highest thinking mode (xhigh vs max)

Qwen 3.8 27b nvfp4 vs Grok 4.6 Someone tell me how this local model that is 100x smaller and 10x slower made a better animation?! Elon Musk help us solve this, both with their highest thinking mode (xhigh vs max)

166,698 Aufrufe

4 DGX Sparks running DeepSeek V4.1 Flash 6 concurrent sessions, 170.73 tok/s coding throughput. 🔥 1,200 output tokens in 7.028 seconds. Warm single-stream: 💻 Code: 77.61 tok/s 🧮 Math: 74.08 🧠 Reasoning: 48.75 ✍️ Prose: 33.02 6-stream aggregate: 💻 Code: 170.73 tok/s 🔢 Counting: 291.64 tok/s 552B MoE · MXFP4 · TP4 · vLLM + DSpark + CUDA graphs ✅ Tool calling + vision ✅ 127,480-token retrieval test passed ✅ 300K configured context Video replays the actual recorded streams at 1× speed. Thinking OFF, 200-token cap per coding request. Short-prompt coding throughput Credit to Tech2Wild for the Boot9 recipe. NVIDIA AI

4 DGX Sparks running DeepSeek V4.1 Flash 6 concurrent sessions, 170.73 tok/s coding throughput. 🔥 1,200 output tokens in 7.028 seconds. Warm single-stream: 💻 Code: 77.61 tok/s 🧮 Math: 74.08 🧠 Reasoning: 48.75 ✍️ Prose: 33.02 6-stream aggregate: 💻 Code: 170.73 tok/s 🔢 Counting: 291.64 tok/s 552B MoE · MXFP4 · TP4 · vLLM + DSpark + CUDA graphs ✅ Tool calling + vision ✅ 127,480-token retrieval test passed ✅ 300K configured context Video replays the actual recorded streams at 1× speed. Thinking OFF, 200-token cap per coding request. Short-prompt coding throughput Credit to Tech2Wild for the Boot9 recipe. NVIDIA AI

23,510 Aufrufe

Day-0 Qwen3.8-27B vs Qwen3.6-27B: the voxel pagoda test. Same prompt, one attempt each, single DGX Spark, both NVFP4. 3.8: 75,291 tok · 52m 56s · 23.7 tok/s (vLLM, native MTP) 3.6: 12,117 tok · 5m 13s · 38.8 tok/s (llama.cpp, DFlash K10) 3.8 thought for 160K characters before writing a line of code.

Day-0 Qwen3.8-27B vs Qwen3.6-27B: the voxel pagoda test. Same prompt, one attempt each, single DGX Spark, both NVFP4. 3.8: 75,291 tok · 52m 56s · 23.7 tok/s (vLLM, native MTP) 3.6: 12,117 tok · 5m 13s · 38.8 tok/s (llama.cpp, DFlash K10) 3.8 thought for 160K characters before writing a line of code.

97,988 Aufrufe

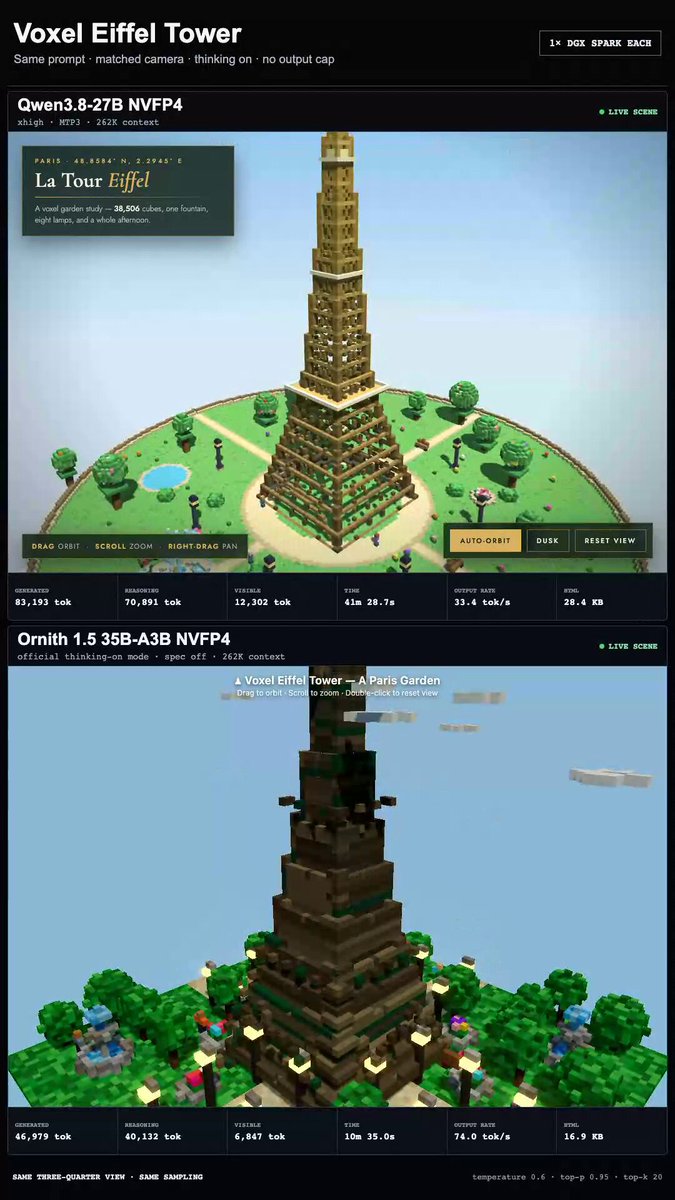
Two models. One DGX Spark One identical voxel Eiffel Tower prompt. Qwen3.8-27B xhigh: 83K tokens, 41m29s, 33.4 tok/s Ornith 1.5 35B-A3B: 47K tokens, 10m35s, 74.0 tok/s Thinking on, no token ceiling, matched camera. Ornith finished much faster; Qwen spent far more tokens.

Two models. One DGX Spark One identical voxel Eiffel Tower prompt. Qwen3.8-27B xhigh: 83K tokens, 41m29s, 33.4 tok/s Ornith 1.5 35B-A3B: 47K tokens, 10m35s, 74.0 tok/s Thinking on, no token ceiling, matched camera. Ornith finished much faster; Qwen spent far more tokens.

51,404 Aufrufe

Local showdown: Qwen vs Deepseek fireworks one-shot: "build a fireworks show over a city, single HTML file, no libraries." two locals on DGX Sparks, temp 0.6, one attempt, no edits. DeepSeek-V4-Flash (2x GB10): 1m20s, 5,214 tokens, Qwen3.8-27B NVFP4 (1x GB10, xhigh): thought for 21 minutes before typing one character of the answer. 38,269 tokens total, ~29K of them thinking

Local showdown: Qwen vs Deepseek fireworks one-shot: "build a fireworks show over a city, single HTML file, no libraries." two locals on DGX Sparks, temp 0.6, one attempt, no edits. DeepSeek-V4-Flash (2x GB10): 1m20s, 5,214 tokens, Qwen3.8-27B NVFP4 (1x GB10, xhigh): thought for 21 minutes before typing one character of the answer. 38,269 tokens total, ~29K of them thinking

40,134 Aufrufe

This is the worst model I have ever tested, even 9b models outperform it. What even is this pagoda? Same prompt I always use. - Total time: 9 min 21 s (560.9s) - Tokens: 6,891 completion (710 reasoning + ~6,181 answer) | 84 prompt - Speed: ~12.3 tok/s end-to-end - First token: 0.15s - Output: 22,094 chars answer / 17.2KB HTML, natural stop (finish_reason=stop, no cap hit)

This is the worst model I have ever tested, even 9b models outperform it. What even is this pagoda? Same prompt I always use. - Total time: 9 min 21 s (560.9s) - Tokens: 6,891 completion (710 reasoning + ~6,181 answer) | 84 prompt - Speed: ~12.3 tok/s end-to-end - First token: 0.15s - Output: 22,094 chars answer / 17.2KB HTML, natural stop (finish_reason=stop, no cap hit)

18,306 Aufrufe

Qwen3.6-27B dense quality ladder. Same tasks. Same grader. Same day. How much does compression cost? FP8 - 83.3 · 29GB NVFP4 - 83.0 · ~15GB BF16 - 81.9 · 56GB GPTQ-Pro - 79.4 · 13GB IQ2_XXS - 79.0 · 9.4GB Who wins where: 🥇 Raw quality → FP8 (83.3) 🥇 Practical default → NVFP4 (83.0 at ~15GB) 🥈 Full precision → BF16 is NOT better (81.9) ❌ "Just use any 4-bit" → GPTQ-Pro loses 3.6 pts vs NVFP4 🛟 Emergency tiny → IQ2 still holds at 79.0 Overall winner: If you care about the absolute number: FP8 If you care about running it on a real box: NVFP4 is the overall pick. Same quality class as full precision. Half the size of FP8. ~4× smaller than BF16.

Qwen3.6-27B dense quality ladder. Same tasks. Same grader. Same day. How much does compression cost? FP8 - 83.3 · 29GB NVFP4 - 83.0 · ~15GB BF16 - 81.9 · 56GB GPTQ-Pro - 79.4 · 13GB IQ2_XXS - 79.0 · 9.4GB Who wins where: 🥇 Raw quality → FP8 (83.3) 🥇 Practical default → NVFP4 (83.0 at ~15GB) 🥈 Full precision → BF16 is NOT better (81.9) ❌ "Just use any 4-bit" → GPTQ-Pro loses 3.6 pts vs NVFP4 🛟 Emergency tiny → IQ2 still holds at 79.0 Overall winner: If you care about the absolute number: FP8 If you care about running it on a real box: NVFP4 is the overall pick. Same quality class as full precision. Half the size of FP8. ~4× smaller than BF16.

24,599 Aufrufe

Videos

Keine weiteren Inhalte verfügbar