
Antid
@antisadh • 2,485 subscribers
studying AI daily | helping you save & make money with it
Videos
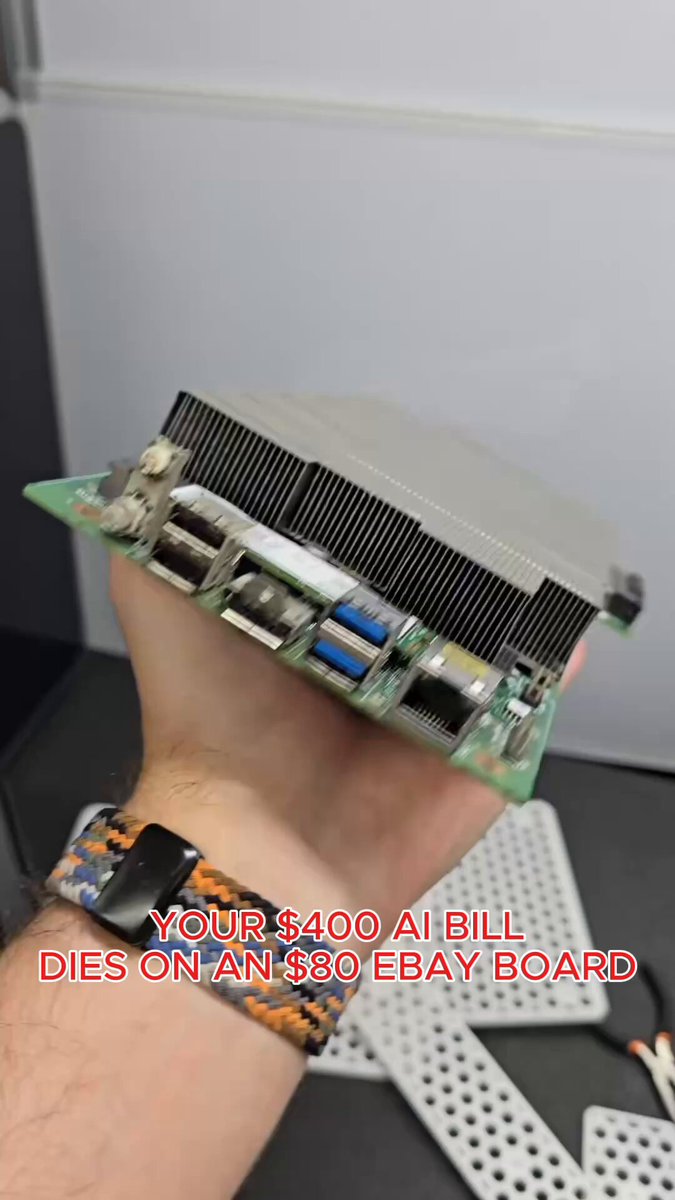
NVIDIA WANTS $2,000 FOR 16GB OF VRAM. SONY'S PS5 CHIP DOES IT FOR $80 AND BITCOIN OPERATIONS ARE LIQUIDATING THEM FASTER THAN EBAY CAN LIST THEM, THE PRICE JUMPED 50% IN THREE WEEKS 01:01 he holds it up to the camera and says "these were originally produced for mining bitcoin, but now a lot of bitcoin operations are starting to sell these off" $80 bc250 off ebay -> a slimmed down ps5 apu with 16gb of shared gddr6 -> m.2 slot, sata, dual ethernet, displayport, all on the card -> $50 flex itx psu -> 3d print the case, then 3d print a second tool just to pry the heatsink fins open -> clip a fan onto it -> ubuntu and ollama in one curl line nvidia charges $2,000 for a card with this much vram and sony put the same class of silicon in 117 million consoles, then bitcoin operators bought the mining variant by the pallet and started dumping it, the listings went from $80 to $120 in three weeks and they are still moving the honest part: these shipped as rack cards with server fans screaming through a row of them, pull one out alone and it has no cooling story at all, the entire diy scene exists because this hardware was never meant to live outside a rack amd bc250 + 16gb shared gddr6 + flex itx psu + 3d printed case and fin tool + ubuntu + ollama watch and save it, elon open sourced grok's body and moonshot open sourced kimi's brain, the full $600 to $14 build is in the article below
Antid59,393 Aufrufe • vor 1 Monat

NVIDIA SOLD THESE TESLA K80s FOR $5,000 EACH AND KILLED DRIVER SUPPORT FOR THEM IN 2018. HE PAID $578 FOR THE WHOLE 24-CORE WORKSTATION AND 48GB OF VRAM CAME WITH IT 00:12 he wipes three years of dust off the case and says "back in april of 2023 I picked up this workstation, it's a 24 core dual processor, no OS, no GPU, for 578" $578 dual xeon e5, 24 cores, 128gb of ram -> two tesla k80s at 24gb each, 48gb pooled -> six ball bearing fans already inside -> the k80s ship with no fans at all because datacenters ducted the air for them -> 3d print a shroud and hope it clears the cables -> drop a 3080 ti in the top x16 while the prints run each k80 draws 300 watts and is slower than a 3060 that costs a fraction of that, and every card presents as two separate gpus, so two cards land in your system as four devices that most inference stacks handle badly the honest part: he says outright he may pull them back out, dirt cheap vram is not free vram when it costs 600 watts and a weekend of 3d printing to make it breathe dual xeon e5 + 128gb ddr4 + 2x tesla k80 at 48gb pooled + 3080 ti 12gb + 3d printed fan shrouds + linux watch and save it, musk gave away the agent and moonshot gave away the weights, the full $400 to $25 routing table is in the article below
Antid49,756 Aufrufe • vor 1 Monat

NVIDIA CHARGES $30K FOR AN H100 WITH NVLINK. TENSTORRENT SELLS THE SAME 800GBIT/S INTERCONNECT IN A $2K CARD. HE PLUGGED 4 INTO PCIE x1 SLOTS AND RUNS OPUS-5 LOCALLY FOR $6/MONTH buy a tenstorrent card for $2k -> plug into any $50 pcie x1 slot -> connect cards via qsfp-dd 800g -> skip the nvidia pcie bandwidth wall -> pool 100gb+ of vram across cards for less than one h100 -> run opus-5 locally for $6/month. that loop is why every serious solo ai builder is quietly ordering tenstorrent cards and openai's infrastructure team went quiet for 3 days after keller's announcement. tenstorrent accelerator + qsfp-dd 800g interconnect + cheap pcie x1 slots + linux + no nvidia tax - that's the stack. watch and save it, then order a tenstorrent card this weekend.
Antid88,517 Aufrufe • vor 2 Monaten

NVIDIA KILLED DRIVER SUPPORT FOR THESE IN 2018. HE BOUGHT TWO OFF EBAY FOR $150 ANYWAY AND SPENT A WEEKEND WATCHING THEM REFUSE TO POST. KIMI DOES THE SAME WORK FOR $19/MO 03:11 he's holding a molex adapter he already knows is a mistake and says "this is so not a good idea, like this is a pretty foolish idea, I should not be doing this really" 2 tesla k80s for $150 -> 48gb of vram on paper -> no video out on either card -> no video out on the motherboard either -> hunt down a single-slot gpu just to see BIOS -> the y-splitter that shipped with them is bridged wrong -> improvise from three 6-pin rails -> 266 watts at idle -> 6 beeps -> nothing on screen kepler shipped in 2014, nvidia cut cuda support in 2018, and datacenters dumped millions of these onto ebay where they still list as "AI accelerator, 24GB" because 24 is a bigger number than 12 and nobody checks the compute capability the honest part: he swapped both cards, pulled the sata power, ran one alone off the correct rails, and neither one posted, the host boots fine with the slot empty, $150 gone and the weekend with it 2x tesla k80 + dual xeon host + 3d printed 120mm shroud + molex-to-8pin adapters + 6 bios beeps + zero tokens generated watch and save it, then kill your $439 stack this weekend, kimi does the same work at $19 flat and the whole map is in the article below
Antid54,180 Aufrufe • vor 1 Monat

NVIDIA CHARGES $4,000 FOR AN RTX 5090 WITH 32GB. INTEL SELLS THE SAME 32GB FOR $950. HE STACKED TWO INTO 64GB AND KILLED $200/MO CLAUDE CODE AND $200/MO CHATGPT PRO FOR $3 IN ELECTRICITY 00:09 he's been at it since the middle of the night and admits it up front, "I've been testing these pretty much non stop since about 2am today" 2x intel arc pro b70 at $950 each -> 64gb pooled for less than half a 5090 -> asrock taichi lite, both in x8 slots -> ryzen 9600, 64gb ddr5 -> ubuntu 26.04 sees both cards instantly, zero driver hunting -> intel's own stack, not community packages -> mixture of experts models fly nvidia wants $4,000 for 32gb, intel put the same capacity in a card at 23% of that, so a 70b rig went from a $4,000 ticket to $1,900 for double the memory, and the $400 a month altman and amodei charge becomes $3 in electricity the honest part: q8 hits a hard bottleneck on battlemage, bizarre because intel's older alchemist cards were faster at q8 than q4, dense models are rough, and running both cards together has been ugly so far 2x intel arc pro b70 32gb + asrock taichi lite + ryzen 9600 + 64gb ddr5 + ubuntu 26.04 + intel's own inference stack watch and save it, musk gave away the agent and moonshot gave away the weights, the full $400 to $25 routing table is in the article below
Antid39,138 Aufrufe • vor 1 Monat

SONY SHIPS THIS APU IN A $200 PS5. BITCOIN OPERATIONS DUMPED IT ON EBAY FOR $40. HE 3D PRINTED A CASE OVERNIGHT AND KILLED $439 A MONTH IN ANTHROPIC AND OPENAI BILLS 00:34 he turns the board over and says "this was actually meant for bitcoin mining originally, and this uses ps5 adjacent hardware for the apu" $80 bc250 off ebay -> one 8 pin connector, no pcie, no motherboard -> $50 flex itx 500w psu -> 20 hour ASA print for the case -> blow four years of mining dust out with an air compressor -> 16gb gddr6 unified, ollama up in 4 minutes sony sold 117 million ps5s on this silicon, bitcoin operations bought the mining variant by the pallet, ethereum's merge stranded all of it, and now the same oberon apu that renders spider-man runs a local coding model for the price of a dinner the honest part: it arrived filthy, the compressor barely touched the dust, and you need a 3d printer before the board does anything at all $80 amd bc250 + $50 flex itx 500w + 20h ASA print + oberon apu with 16gb gddr6 + ubuntu + ollama watch and save it, then kill your $439 stack this weekend, kimi does the same work at $19 flat and the whole map is in the article below
Antid35,879 Aufrufe • vor 1 Monat

ONE BUILDER WIRED 4 RASPBERRY PI MODULES INTO A €450 AI CLUSTER WITH 64GB OF RAM AND KILLED HIS $200/MONTH CHATGPT SUBSCRIPTION 00:37 he points at the terminal, "loaded, loaded, loaded - 4 nodes synced over gigabit, 64 gigabytes total, llama 3.1 partitioned across the cluster" he stacked 4 raspberry pi CM5 lite modules with 16 gigabytes each onto a sipeed nanocluster board, the whole rig runs off a single 65 watt power supply and a gigabit internal switch distributed llama partitions the model across the nodes with synchronized workloads handled over the internal fabric, no quantization needed, the cluster hits about 30 tokens per second on small models a heavy developer pays $200 a month for chatgpt pro and another $200 for claude code, this rig cost €450 in parts and breaks even on the stack in month 2 most people will keep paying anthropic and openai forever, a few will spend a weekend wiring 4 raspberry pi modules and never see a subscription invoice again the window is open, follow and bookmark before it closes
Antid64,291 Aufrufe • vor 3 Monaten

JENSEN HUANG STRIPPED NVLINK OUT OF CONSUMER CARDS IN 2021 TO PROTECT A $30K PRODUCT LINE. JIM KELLER PUT IT BACK IN A $1,400 CARD. HE MESHED TWO OFF A SINGLE PSU AND RUNS KIMI K3 FOR $6/MONTH 00:13 he holds up the green cable bundle, looks at the camera and says "we're not hooking team green up to these" 2 blackhole p150a for $2,800 -> skip the adapter chain entirely -> two 600w cables direct off one seasonic -> qsfp-dd 800g mesh card to card -> the pcie slot goes idle after model load -> kimi k3 at full 1m context for $6/month nvidia's whole $30k moat is the interconnect, keller shipped it on a card that costs 4.6% of an h100, tenstorrent's queue hit 11 weeks and the pcie bus that nvidia optimizes around stopped mattering in this build entirely the honest part: the software stack is 6 months behind cuda, you will lose a weekend to driver builds before the first token lands 2x tenstorrent blackhole p150a + qsfp-dd 800g + 1000w seasonic + ubuntu 26.04 + neo4j + kimi k3 watch and save it, then kill your $439 stack this weekend, kimi does the same work at $19 flat and the whole map is in the article below
Antid25,925 Aufrufe • vor 1 Monat

INTEL SELLS THIS CHIP FOR $60 TO CASH REGISTERS. HE WIPED WINDOWS 11 WITH ONE COMMAND AND KILLED $200/MO CLAUDE CODE MAX AND $200/MO CHATGPT PRO FOR $5 OF ELECTRICITY 02:10 he drags the image file straight into the terminal window and says "next up is where the magic happens, we're going to use the dd command" $150 n97 mini pc -> one switch on the back, top panel off with no screws -> one screw and the 512gb windows drive comes out intact -> diskutil unmount /dev/disk9 -> sudo dd if=image of=/dev/disk9 bs=1m -> 9.13gb written -> secure boot disabled in the bios -> ubuntu and ollama up in 4 minutes microsoft says you need a 40 tops npu before it counts as an ai pc, this box has zero tops and no gpu, and the same $60 chip that scans your groceries now answers your prompts for less than one coffee a month the honest part: with no npu a 7b model runs on cpu at reading speed and nothing above 7b moves at all, this is not a frontier experience, it is a $5 one $150 n97 mini pc + 16gb ddr5 + 512gb nvme + one dd command + secure boot off + ubuntu + ollama + qwen 2.5 7b watch and save it, then kill your $439 stack this weekend, kimi does the same work at $19 flat and the whole map is in the article below
Antid24,281 Aufrufe • vor 1 Monat

OPENAI PAYS NVIDIA $30K PER H100. INTEL SELLS THE SAME 32GB VRAM IN A $950 ARC PRO B70. HE STACKED 2 AND RUNS OPUS-5 LOCALLY FOR $3/MONTH buy 2 intel arc pro b70 for $1,900 -> plug them into any dual-x8 pcie motherboard -> boot ubuntu 26.04 -> gpus recognized instantly -> load a q4 moe model like qwen 35b-a3b -> run 64gb of local ai for $3/month in electricity that loop is why nvidia's 5090 monopoly on 32gb vram just quietly cracked and openai's inference costs are about to look ridiculous 2x intel arc pro b70 + asrock taichi lite + ryzen 5 9600 + 64gb ddr5 + ubuntu 26.04 + intel's ipex stack - that's the stack watch and save it, then order your first b70 this weekend
Antid28,739 Aufrufe • vor 2 Monaten

MICROSOFT JUST BROKE COMPATIBILITY WITH A HOMELAB GUY'S $80 AI RIG. HIS 90-SECOND FIX IS ALREADY IN A GITHUB REPO 4,700 PEOPLE FORKED old ai server -> windows 10 expiring -> microsoft blocks win11 upgrade -> tpm chip missing -> boot linux instead -> flash modded firmware -> keep running 15gb of local ai for $0/month that loop is why microsoft's tpm requirement just accidentally handed linux every serious homelab in 2026 linux + amd bc-250 + segfault firmware + moth enjoyer's docs + 6.8tb pcie ssd - that's the stack watch and save it, then move your ai server off windows this weekend
Antid28,509 Aufrufe • vor 2 Monaten

NVIDIA'S $30K H100 JUST GOT OUT-INFERENCED BY A $250 RYZEN. 18 TOKENS/SEC ON A 35B MODEL, $0.03 IN ELECTRICITY, $47B GONE FROM NVDA BY FRIDAY download qwen3 35b-a3b -> load in lm studio -> disable gpu entirely -> run on cpu + ram -> hit 18 tokens/sec on a 6-core ryzen -> pay nothing per token. that loop is why moe models just made every consumer cpu a viable ai host and nvidia's inference monopoly is quietly on borrowed time. qwen3 35b-a3b + lm studio + ryzen 5 9600x + 32gb ddr5 + zero gpu - that's the stack. watch and save it, then run a 35b model on your laptop this weekend.
Antid23,745 Aufrufe • vor 2 Monaten

ALIBABA GAVE QWEN AWAY FREE, ZUCKERBERG GAVE LLAMA AWAY FREE, AND JENSEN HUANG STILL CHARGES $300 FOR THE 12GB THAT RUNS THEM. THE $80 AMD BOARD HAS 16GB. HE IS TESTING BOTH THIS WEEK AGAINST $200/MO CLAUDE CODE MAX AND $200/MO CHATGPT PRO 00:19 he points at a dead gtx 680 he keeps on the shelf purely for decoration and says "i'm actually really gpu poor" $300 rtx 3060 with 12gb -> $80 bc250 with 16gb -> ubuntu server on both -> 8gb tier, 12 to 16 tier, 24gb ceiling on a four year old 3090 -> qwen against llama at every tier -> tokens per dollar published jensen shipped 12gb on the 3060 in 2021 and consumer vram has barely moved since, alibaba and meta gave the weights away for nothing, the models are free and the only thing left to buy is memory the honest part: he says it himself, this is apples and oranges, and there is not a single benchmark number in this video yet $80 amd bc250 with 16gb gddr6 + $300 rtx 3060 with 12gb + a four year old 3090 with 24gb + ubuntu server + ollama + qwen + llama watch and save it, then kill your $439 stack this weekend, kimi does the same work at $19 flat and the whole map is in the article below
Antid13,974 Aufrufe • vor 1 Monat

A $40 BC250 BOARD WITH 16GB GDDR6 GETS A GITHUB FIRMWARE FLASH, THE DEFAULT 8/8 CPU/GPU SPLIT REWRITES TO 0.5/15.5 AND OPENS 15.5GB OF UNIFIED MEMORY TO OLLAMA, DEAD CRYPTO HARDWARE JUST DOUBLED ITS AI CEILING 01:08 the operator points at the chart, "you only give 512 megs to the GPU part and that's reserved, that means all the rest of the RAM is available to either the CPU or the GPU" a BC250 ships from the factory with 16GB GDDR6 split 8/8 between Oberon CPU cores and the RDNA 2 iGPU, the iGPU only ever uses 4-5GB during inference, the other 3-4GB sits stranded SEC Bolt's firmware mod on the moth-enjoyer GitHub flashes a 0.5/15.5 split, the GPU reserves 512MB and 15.5GB falls into a unified pool that ollama treats as VRAM, qwen 3.6 14B at 4 bit fits with 2GB context headroom 15.5GB on a $40 board with a $40 CH347 flasher beats the $249 Jetson Orin Nano's 8GB by nearly 2x at 1/6th the price, the firmware is open source, the dump backup process takes 4 minutes per board your map's tier zero floor was the OptiPlex at $35-50 with iGPU only, the modded BC250 sits at the same $40 mark with 15.5GB of GDDR6 and an actual RDNA 2 GPU, the buyer who flashes once unlocks a 13B class local AI host for the price of a dinner the window is open, follow and bookmark before it closes
Antid25,619 Aufrufe • vor 3 Monaten

7-YEAR-OLD RASPBERRY PI WITH 2GB OF RAM IS RUNNING DEEPSEEK RIGHT NOW WHILE SAM ALTMAN BILLS $200/MO AND DARIO AMODEI BILLS $200/MO FOR A MODEL YOU NEVER GET TO KEEP 00:34 he points at the smallest board on the bench and says "out of all these I'm genuinely shocked that I actually got it up and running on this raspberry pi 4b with 2 gigs of ram" raspberry pi 4b, 2gb, seven years old -> ollama with deepseek r1 1.5b -> a dell micro form factor doing cpu-only inference next to it -> an m1 max macbook with 64gb unified memory beating the dual gpu tower on large models -> four machines, four architectures, all serving locally apple's unified memory puts the ram on the same die as the cpu and gpu, so a laptop outruns a two-card workstation on big models, and the cheapest board on that bench costs less than four days of a claude max seat the honest part: 2gb is the actual floor and he says it was rough to get there, a 4gb or 8gb pi would have taken minutes instead, and 1.5b parameters is a model you use for structure not for answers raspberry pi 4b 2gb + dell micro form factor + m1 max 64gb + dual gpu tower + ollama + deepseek r1 watch and save it, musk gave away the agent and moonshot gave away the weights, the full $400 to $25 routing table is in the article below
Antid10,442 Aufrufe • vor 1 Monat

TWITTER ORDERED THESE EPYC CHIPS AND NEVER TOOK DELIVERY. HE BOUGHT THE ORPHANED BATCH, STACKED 512GB OF RAM AND NOW RUNS DEEPSEEK 671B UNQUANTIZED WHILE ANTHROPIC BILLS $200/MO FOR THE SAME CLASS OF MODEL 00:17 he holds the cpu up and says "these were custom made I think for twitter and then all the twitter stuff happened, so they never got put to use" amd epyc 7v13, the cancelled twitter batch -> supermicro h12ssl-nt, 8 memory channels -> 8x 64gb ddr4-3200, 512gb total -> noctua sp3 cooler -> gutted an old atx case -> the whole model loads into ram, no swap, no quantization his gaming rig has a 9950x3d and 128gb of ddr5 and only two memory channels, this board has eight, so older ddr4 on the epyc moves more data per second than the newer ram on the gaming machine, that's the whole reason cpu inference works at all here the honest part: he expects 1 to 4 tokens per second, which is slower than reading speed, you run this because it holds a 671b model at full precision, not because it's fast amd epyc 7v13 + supermicro h12ssl-nt + 512gb ddr4-3200 across 8 channels + noctua sp3 + deepseek 671b + llama 405b watch and save it, musk gave away the agent and moonshot gave away the weights, the full $400 to $25 routing table is in the article below
Antid10,074 Aufrufe • vor 1 Monat

A 24 BAY DELL POWEREDGE T550 TOWER SERVER FITS IN A HOME OFFICE WITHOUT A RACK, 384TB OF RAW SAS STORAGE HOSTS EVERY OPEN SOURCE LLM EVER RELEASED LOCALLY, THE HOME AI LIBRARY TIER UNDER YOUR MAP 00:25 the reseller spins the chassis around, "it's a 24 bay Dell T550 tower server man, look it's got a boss card for dual NVMe boot SSDs" a refurbished T550 ships at $900-1,100 with single Xeon Silver, 64GB DDR4 ECC and 24 hot swap SAS bays in a tower form factor that fits next to a desk without a server rack 24x 16TB SAS drives at $80 each on eBay equals 384TB raw storage for $1,920, the same array on enterprise Mac Studio Pro tier would cost $35,000 in thunderbolt JBOD enclosures Llama 3.3 70B is 42GB, Qwen3-235B is 110GB, DeepSeek-V3 is 100GB, Mistral Large is 80GB, the entire ollama public model library fits inside 4TB, you can mirror every open weights release for the next decade your map covers compute boxes that swap one model at a time, the T550 is the model warehouse tier that feeds them, a homelab operator wires the tower over 10GbE to a mac mini and the mac never waits 30 seconds to pull a swap the window is open, follow and bookmark before it closes
Antid18,526 Aufrufe • vor 3 Monaten
Keine weiteren Inhalte verfügbar