
Gradient
@Gradient_HQ • 685,698 subscribers
Advancing open intelligence through efficient, accessible infrastructure for AI inference and post-training.
Shorts


Videos
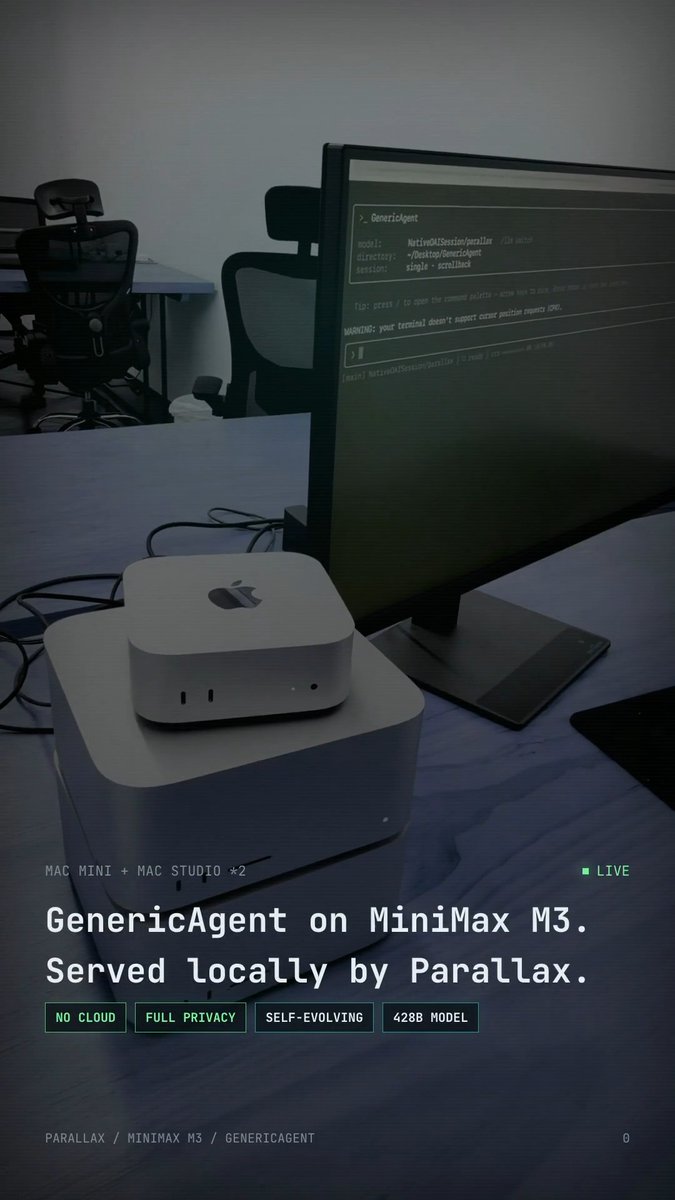
A self-evolving agent + a 428B model + 3 Macs = ? Your own AI lab. We ran MiniMax (official) M3 locally with Parallax, right on our desk. Then GenericAgent took over to create a 5-stock portfolio and write it to disk. No cloud. No API bills. Nothing left the machine. Wild to see a ~3K-line agent drive all this with a 400B+ model on local hardware. Thanks to the GenericAgent and MiniMax teams for making local AI feel real.
Gradient154,509 次观看 • 4 个月前
SWE-bench Verified has become saturated. Seven models scored 95–97% (Vals AI, Sep 2026). But how well can coding agents build complete software projects from scratch? Zero2Repo is a Gradient Data research initiative building hard, verifiable tasks and training data for whole-project development. Agents start with a full spec, an interface contract and an empty workspace. They build the entire repo without reference code, then submit it for hidden deterministic testing. Every test must pass for a task to count. No LLM judge is used. The first release includes 17 tasks derived from real open-source projects across Python, TypeScript, Go, C, C++ and Zig. Across 18 model–harness configurations, scores range from 1/17 to 15/17. The top 10 span 47 percentage points, compared with 5 points on SWE-bench Verified. No configuration has completed all 17 tasks. This matters for self-iteration: small unresolved issues can persist and compound as agents continue developing a project. Reliable self-evolution remains an open research challenge. We’re expanding the task collection and looking for contributors to suggest seed repositories, develop tasks and review requirements and hidden tests. More cases are coming. 👉 👉
Gradient22,843 次观看 • 19 天前

Reinforcement Learning is the future tense of intelligence. Echo is how it scales. Echo is Gradient’s distributed RL framework, running on everyday consumer devices. From its early experiments, Echo powered a 30B Sokoban model that outperformed DeepSeek-R1 and GPT-OSS-120B.
Gradient279,386 次观看 • 1 年前


没有更多内容可加载