Sudo su
@sudoingX • 39,554 subscribers
GPU/local LLM. more RAM and OSS... everywhere
Shorts


Videos

when you realize the 6gb uncensored model on your own gpu just did the work opus 5.5 refused
Sudo su188,824 views • 3 days ago


this is what 12gb of vram builds in 2026, absolute magic > rtx 3060 12gb, #1 gpu on steam > bonsai 2 27b + mtp, 5.95 gb of weights > hermes agent, 5 hours, 328k tokens written > 8 js files, 2,368 lines, zero hand written code > 50 tok/s fresh, 22 tok/s average, 125k context watch the full video, 5 hours in 12 minutes of pure dance of a local ai model on rtx 3060 12gb vram, and stay till the end for the full gameplay. this entire game was built by bonsai2, a qwen 3.8 27b dense compressed to ternary, and this small model is punching way above its weight. it built multi file engineering work using hermes agent, sure it's not fast but perfect for overnights and routine work and the quality is insane, and context holding is another best one, it does not lose the thread. i ran PrismML bonsai 1 made from qwen 3.6 27b dense and i built things with it, but this time with the latest base model qwen 3.8 these results are insane, and because i loved building with it a lot i thought many more of you would run it because this gpu exists in almost every home. so i packaged mtp, doubled the speed from 26 tok/s to 50 tok/s, packed the prefill fix in and released it on huggingface, almost 4,000 downloads in 3 days. i'll leave a link below.
Sudo su87,876 views • 24 days ago

single most useful thing for my local ai setup that made life easy is my 2x DGX Spark becoming one serving box for every device i own here is how i do it: > 1. the two sparks run one vLLM server together with one endpoint, i use dgx sparks, you can use any nodes that can run an llm > 2. install tailscale to have all your nodes and machines on the same tailnet, the endpoint lives there so every device reaches it from anywhere and no port is open to the internet > 3. that one tailnet endpoint with the exposed port is your base url for everything, it speaks OpenAI chat, OpenAI Responses and Anthropic Messages, so any chat app, coding agent or phone bot you point at it talks to the same model > 4. the server also answers to the name "local", so clients can ask for "local" instead of a model name and when i swap the model on the servers nothing on the devices needs a config change. right now it's serving GLM 5.3-Flash, next week it can be something else this video below is the whole thing running end to end, orange dots are requests going in, white and green are tokens coming back it takes however many requests you throw at it, your config decides how many run at once and the rest wait their turn, when several run together each request's tok/s drops a bit while the box moves more tokens in total. mine is set to one at a time right now, so when every device fires together they queue up this setup really improved my quality of life with local ai, if you get stuck anywhere setting it up leave a comment and i'll help you
Sudo su32,890 views • 17 days ago

Qwopus on a single RTX 3090. Claude Opus 4.6 reasoning distilled into Qwen 3.5 27B dense, running through Claude's own coding agent (claude code). 29-35 tok/s with thinking mode on. the jinja bug that kills thinking on base Qwen doesn't carry over. harness and model matched. the base model would pause mid task on Claude Code. just stop generating. that's why i ran it through OpenCode, which handles stalled states automatically. this distilled version doesn't stall. it waits for tool outputs, reads them, selfcorrects when something breaks, and keeps going. i gave it a benchmark analysis task. went 9 minutes autonomous. wrote a README nobody asked for. zero steering. video is 5x speed but fully uncut. if you have a 3090, you can run this right now. free. no API. no subscription. opus structured reasoning on localhost. octopus invaders is next. same prompt that base qwen passed in 13 minutes and hermes 4.3 failed on 2x the hardware. i want to see if the distillation changes the outcome or just the style. more data soon.
Sudo su296,392 views • 7 months ago

the timeline spent two days saying bonsai 2 cannot build. here is 1 hour 24 minutes of it building, one shot, from one paragraph, on an rtx 3060 12gb, sped to 8x so you can watch the whole thing. what you are watching is a 5.9gb ternary compression of qwen 3.8 27b, served through the prismml llama.cpp fork with the full 262k window resident, writing a terminal gpu monitor in one html file. it thinks, it calls a tool mid build, it keeps going until finish. the clock in the corner is real. 8x, one frozen recorder stretch cut, nothing else touched. for anyone new here, the 3060 is the most owned gpu on steam, a five year old card, and this is the kind of card the model was compressed for. for anyone who followed july, bonsai 1 built the wankel engine on an 8gb 3060 ti, this is the sequel one tier up. the numbers, live server, thinking on > 26 tok/s fresh, 22 at 12k, 18 at 35k, 13 tok/s at 77k deep > 262k context resident on 11.7 of 12 gb > 76k tokens, 77 minutes, 149 of 150 w the entire run if you own a 12gb card, this runs on it tonight. serve line, model, fork and the exact prompt in the replies.
Sudo su41,330 views • 29 days ago

i think spacex browser game just fixed my fried focus, lol spent 20 min last night manually docking a crew dragon to the iss and my head went dead quiet for the first time in weeks. it's the real spacex sim, free, runs in the browser, no install. ease the translation in, null your rotation rate, hold the crosshairs dead center, soft capture. and that's the actual manual procedure the crew falls back on if autonomous docking ever drops. go dock something tonight.
Sudo su155,016 views • 4 months ago

nvidia's 3B mamba destroyed alibaba's 3B deltanet on the same RTX 3090. only 24 days between releases. same active parameters, same VRAM tier, completely different architectures. nemotron cascade 2: 187 tok/s. flat from 4K to 625K context. zero speed loss. flags: -ngl 99 -np 1. that's it. no context flags, no KV cache tricks. auto-allocates 625K. qwen 3.5 35B-A3B: 112 tok/s. flat from 4K to 262K context. zero speed loss. flags: -ngl 99 -np 1 -c 262144 --cache-type-k q8_0 --cache-type-v q8_0. needed KV cache quantization to fit 262K. both models held a flat line across every context level. both architectures are context-independent. but nvidia's mamba2 is 67% faster at generating tokens on the exact same hardware and needs fewer flags to get there. same node, same GPU, same everything. the only variable is the model. gold medal math olympiad winner running at 187 tokens per second on single RTX 3090 a card from 6 years ago. nvidia cooked.
Sudo su187,758 views • 6 months ago
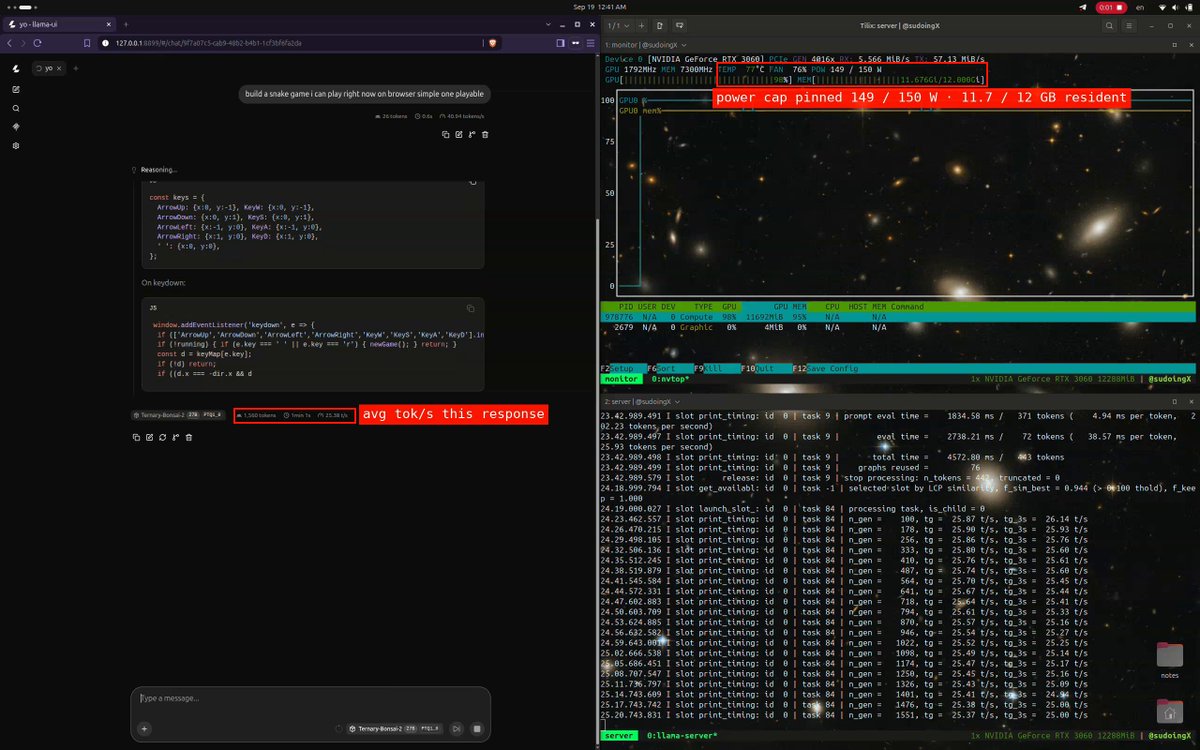
bonsai 2 27b on an rtx 3060 12gb, the full receipt sheet. save this one, the 12gb row of the small gpu guide is built from it. speed by depth, then what context costs, live server, thinking on, real sessions > 7k deep: 24.4 tok/s > 12k deep: 21.9 tok/s > 35k deep: 17.8 tok/s > 77k deep: 13.0 tok/s > 64k window: 7.3gb resident > 128k window: 8.8gb resident > 192k window: 10.2gb resident > 262k window: 11.7gb resident, 0.6gb to spare, the whole native window on a 12gb card > every 64k of context costs 1.47gb, so 327k would not fit > a 41,312 token build session from 35k to 77k of context averaged 15.0 tok/s across 46 minutes > prefill 295 tok/s at 2k of context, 243 tok/s at 35k, first token in 0.6 seconds, fresh decode 26.1 tok/s > the card pinned 149 of 150 w the entire time, 78c, fan at 80%, power bound, not heat bound > 0.158 tok/s per watt at the fresh end the setup > model: ternary bonsai 2 27b, PTQ1_0, 1.75 bits per weight, 5.95gb on disk, base qwen 3.8 27b, apache 2.0 > runtime: prismml llama.cpp fork, prebuilt cuda 12.4 binary, no compile > serve: full 262k native window resident, q4 kv cache, flash attention, one slot, 11.7 of 12gb in use for anyone who followed bonsai 1 in july, that was the 3.9gb 1bit file at 42 tok/s on a 3060 ti, a faster card and a smaller file, so the same card comparison is not on the table yet, it comes with the 8gb test. what changed is the base, qwen 3.8 instead of 3.6, and the retention, 98.2% on their suite instead of 95%, and the whole 262k window fitting on 12gb.
Sudo su31,174 views • 29 days ago

this is what 12 gigs of VRAM built in 2026. a 9 billion parameter model running on a 5 year old RTX 3060 wrote a full space shooter from a single prompt. blank screen on first try. i came back with a bug list and the same model on the same card fixed every issue across 11 files without touching a single line myself. enemies still looked wrong so i pushed another iteration and now the game has pixel art octopi, particle effects, screen shake, projectile physics and a combo system. all running locally on a card that was designed to play fortnite. three iterations. zero cloud. zero API calls. every token generated on hardware sitting under my desk. the model reads its own code, finds what's broken, patches it, validates syntax and restarts the server. i just describe what's wrong and it handles the rest. people are paying monthly subscriptions to type into a browser tab and wait for a server farm to respond. meanwhile a GPU you can find used on ebay is running a full autonomous hermes agent framework with 31 tools, 128K context window and thinking mode generating at 29 tokens per second nonstop. the game still needs work. level upgrades don't trigger and boss fights need tuning. but the fact that i'm iterating on gameplay balance instead of debugging whether the code runs at all tells you where this is headed. every iteration the game gets better on the same hardware. same 12 gigs. same 9 billion parameters. same RTX 3060 from 5 years ago your GPU is not a gaming card anymore. it's a local AI lab that never sends your data anywhere.
Sudo su170,848 views • 7 months ago

update: qwen 3.6 27b dense q4 just one shotted octopus invaders game on a single 3090. hermes agent drove the whole thing, ~41 tok/s gen 21gb vram at full 262k context, thinking mode on. one prompt in and the canonical multi-file space shooter benchmark out, the same exact prompt i ran on qwen 3.5 27b dense back in march on the same card. 3.5 needed one external scope bug fix before the game would even load on first play. 3.6 needed nothing. 11 of 11 files written, 2411 lines of code, zero steering interventions, zero external fixes, playable on first load. 16 minutes 41 seconds wall clock from prompt to playable. consumer tier king on a single 3090 is locked tonight, and the silicon underneath my desk did not change between march and now. the open source ecosystem just moved the floor. watch it ship itself, the full 16 minutes 41 seconds sped to 3 minutes 45, no human touched the keyboard between the first prompt and the final frame.
Sudo su126,733 views • 5 months ago

first test results are in. qwen 3.6 27b dense just banged 10 out of 10 on a single rtx 3090 24gb tier at 40 tok/s. no quant tricks. no fused kernels. just q4_k_m straight cut on llama.cpp. i wrote a particle swarm benchmark this morning, fed it the prompt, and the model autonomously built a 500 particle boids flocking system. velocity driven hue, density based brightness, trail blend rendering, mouse attraction physics, click bursts, drag paint. then it used browser automation to test its own work, found the failing tests, iterated through the code, patched tests.js, and landed all 10 green on its own. i sat there hooked for 8 minutes playing. simple but mesmerizing. mouse trails build beautiful patterns, palette cycles with space, click sends particles flying, drag paints through the swarm. simplicity that hooks you. i'll open source this prompt and the build soon so anyone can reproduce it as their own benchmark. this is the first of 5 single file agent tests i wrote for this model. four more coming. octopus invaders flagship after as final. watch the full video below. see it autonomously build from one prompt. haven't slept well since this model dropped yesterday.
Sudo su133,732 views • 5 months ago

okay the fuss around hermes agent is not just air. this thing has substance. installed it on a single RTX 3090 running Qwen 3.5 27B base (Q4_K_M, 262K context, 29-35 tok/s). fully local. my machine my data. first thing i did was tell it to discover itself. find its own model weights, check its own GPU, read its own server flags, and write its own identity document. it did all of it autonomously. nvidia-smi, process grep, file writes. clean execution. the TUI is genuinely premium. dark theme, ASCII art, color coded tool calls with execution times, real time streaming. you actually enjoy watching it work. 29 tools. 80 skills (that's what it reports on boot). file ops, terminal, browser automation, code execution, cron scheduling, subagent delegation. and it has persistent memory across sessions. setup took 5 minutes. one curl install, setup wizard, point to localhost:8080/v1, done. dropping qwopus for this test btw. distilled models compress reasoning and lose precision on real coding tasks. base model only from here. more experiments coming. octopus invaders (the same game that broke qwopus) will be built using hermes agent next. comparing flow and results against claude code on the same model. if you want to run local AI agents on real hardware this one deserves a serious look.
Sudo su162,824 views • 7 months ago

testing Qwen3.5-35B-A3B latest optimized version by UnslothAI on a single RTX 3090. one detailed prompt. zero handholding. watch a 3B model scaffold an entire multifile game project autonomously. the setup: > model: Qwen3.5-35B-A3B (80B total, only 3B active per token) > quant: UD-Q4_K_XL by Unsloth (MXFP4 layers removed in latest update) > speed: 112 tok/s generation, ~130 tok/s prefill > context: 262K tokens > flags: -ngl 99 -c 262144 -np 1 --cache-type-k q8_0 --cache-type-v q8_0 > engine: llama.cpp > agent: Claude Code talk to localhost:8080 (llama.cpp now has native Anthropic API endpoint. no LiteLLM needed) q8_0 KV cache cuts VRAM usage in half vs f16 at 262K. -np 1 is default but worth noting. parallel slots multiply KV cache and at 262K that's an instant OOM. the prompt was more detailed than this but you get the idea: build a space shooter with parallax backgrounds, particle systems, procedural audio, 4 enemy types, boss fights, power-up system, and ship upgrades. 8 JavaScript modules. no libraries. game's called Octopus Invaders. gameplay footage dropping next.
Sudo su167,244 views • 7 months ago

this is what a 24gb VRAM builds in 2026. one prompt. ten files. 3,483 lines of code. zero handholding. i gave Qwen3.5-35B-A3B a single detailed spec describing the full game architecture and hit enter. enemy types, particle systems, procedural audio, powerups, boss fights, ship upgrades, parallax backgrounds, everything in one message. the model planned the file structure itself, wrote every module in dependency order, wired all the imports, and served the game on port 3001. it ran on first load. when it hit a bug in collision detection it read its own error output, found the issue, fixed it, and kept building. this is pure agent loop running on local hardware. what you're looking at is pixelated octopus aliens with tentacle animations, 4 layer parallax space background with planets at different depths, a full particle system handling explosions and ink splatter and engine trails and bullet impacts, procedural audio through Web Audio API with zero sound files loaded, unleash mode with combo multiplier, boss fights every 5 levels, ship upgrades that unlock as you progress. no libraries. no frameworks. vanilla JS and Canvas. 3B active parameters. single RTX 3090. llama.cpp with q8_0 KV cache at 262K context. Claude Code pointed at localhost:8080 through the native Anthropic endpoint. no API costs. 112 tok/s. a GPU you can buy used for $800. game is called Octopus Invaders and i actually like playing it.
Sudo su153,735 views • 7 months ago

i measured qwen 3.8 27b dense, raw on a single RTX 3090 24gb GPU, before the hype finished loading. here is the honest read: 25.4 tok/s on the exact card and test where 3.6 ran 40tok/s. slower on day one, and i'm posting it anyway, because the rest of the data says watch this space. decode holds dead flat as context fills, 25 empty, 26 at 90k deep, no 27b has ever done that on my bench. one turn in the video generated 33,614 tokens and averaged 22.9 the whole way. the full 262k window sits resident in 22.2GB. the vision tower boots and the card genuinely sees. and the server logs show llama.cpp ignoring the model's MTP tensors completely, multi-token prediction trained into the weights and not wired up yet. this is the floor, measured before the optimizers woke up. tomorrow there are builders wiring MTP, tuning the hybrid attention, shipping kernels, and every commit is free speed for the same card. i benched day one so we can all watch it climb. build video, receipts, full chart in the gallery. repro below.
Sudo su48,648 views • 2 months ago

ok this is wild. 10 year old gtx 1080 8gb pascal card running qwen3 8b locally at 18-20 tok/s via hermes agent and it's actually doing the thing. asked it to build a wireworld cellular automata simulator with 10 tests. autonomous run, no hand holding. expected it to fail on the tool calls. that's not what happened. write_file works. browser_navigate works. terminal commands work. file ops, package installs, version probes, environment setup. agent is firing tool calls cleanly and the model is reasoning about next steps at 18-20 tok/s. on hardware that pre dates "agentic" as a word. it even hit an npm install fail because node 12 is too old. didn't crash. didn't ask me. just started bootstrapping nvm on its own to fix the environment. 10 minutes in. 40% context used. 7.5gb of 8gb vram occupied. still going. i did not think this would work on this hardware. this is the most i've been wrong this month.
Sudo su92,686 views • 4 months ago

first impressions of qwen 3.5 27B dense on a single RTX 3090. 35 tok/s. from 4K all the way to 300K+ context. no speed drop. hermes 4.3 started at 35 and degraded to 15 as context filled. qwen dense holds. MoE held 112 flat. 3x faster but only 3B of 35B active per token. architecture tradeoff. Q4_K_M on 16.7GB. native context 262K. pushed past training limit to 376K before VRAM ceiling on 24GB. tried q8 KV cache at 262K, speed collapsed to 11 tok/s. q4_0 KV is the sweet spot. flash attention mandatory. built in reasoning mode. the model thinks step by step before it answers. full chain of thought surviving Q4 quant. 1,799+ token thinking chains with self correction loops. on a single consumer GPU. gave it one prompt: "build a realtime particle galaxy simulation in one HTML file." 3,340 tokens. 95 seconds. one shot. ran on first load. full reasoning and coding in the video below. optimal config if you want to skip the hours of testing: llama-server -ngl 99 -c 262144 -fa on --cache-type-k q4_0 --cache-type-v q4_0 this is just the warmup. octopus invaders is next: 10 files, 3,400+ lines, zero steering. the prompt hermes quit at 22%. already more impressed than expected. full results coming soon.
Sudo su122,051 views • 7 months ago

watch bonsai 3.9gb model crush tool calls. this is running in hermes agent locally, and it doesn't just fire blind, it reasons first before every single action, thinks through what it actually needs, then makes the call. zero failures the whole run, not one dropped, not one malformed, across a full multi step agent loop. for anyone new here, bonsai is a 1 bit quant of qwen 3.6 27b dense, the exact model i spent all month calling the king of the 3090. PrismML took the king, crushed it down to a single sign bit per weight, 3.9gb, small enough to sit next to a gemma 12b, and it still holds an agent loop and reasons before it acts. sub 4 bit is where models are supposed to turn to mush. someone even clocked it at tool-calling 0 out of 100. not in my runs. this is the warm-up. the real test is the build gauntlet my q4 27b nailed, elements, particle swarm, mandelbrot, and openclaw runs the same one right after. we find out if 1bit actually keeps up.
Sudo su55,466 views • 3 months ago
single RTX 3090. 24 GB VRAM. Qwen3.5-35B-A3B. 4-bit quant, 113 tokens per second at full 262K context harnessing Claude Code locally with no API, no subscription, no proxy. told it what it is. 30 Mamba2 layers, 10 attention, 256 experts, 8 active per token. said "build something that shows off what you can do." it visualized its own architecture. interactive. tokens flowing through layers. 256 experts lighting up on routing. served in the browser from the same GPU running inference. single prompt. then i said level up. 3D. Three.js. separate files. flythrough camera. clickable layers. it planned first, scaffolded 6 files, hit one API bug, fixed it itself, then optimized for smooth framerate. two iterations to a working 3D neural network explorer. llama.cpp just merged a native Anthropic endpoint. Claude Code points at localhost. the whole setup is two commands. no LiteLLM. no proxy config. the open source models coming out of china right now are genuinely changing what's possible on consumer hardware. respect to the Qwen team. this is acceleration.
Sudo su110,464 views • 7 months ago