David Hendrickson
@TeksEdge • 11,966 subscribers
CEO & Founder | PhD | Startup Advisor | @Columbia | Author Generative Software Engineering https://t.co/9oqvHuTX5f | 🔔 Follow for AI & Vibe Coding Tips 👇
Shorts

Videos

🤯 A localmaxxer hit ~381 tok/s on a SINGLE RTX 3090 with Qwen3.8-27B. This developer has turned a 24GB RTX 3090 into a monster Qwen inference box - w/some creativity. Four days ago 👉 ⚡ ~82 tok/s single-user Then 👉 ⚡ ~114 tok/s with optimized MTP ⚡ ~138 tok/s with DFlash2 + lookup drafting Now 👉 🔥 ~381 tok/s on ONE request How? The recipe combines ... 🧠 Qwen3.8-27B 🎮 1× RTX 3090 24GB @ 250W ⚙️ heavily optimized vLLM ⚡ DFlash2 speculative decoding 🔎 lookup-augmented drafting 📚 prefix caching 🧮 16-token verification blocks 💾 quantized KV / heads / activations DFlash2 normally proposes 7 tokens. The developer realized the verification block doesn't have to stop there. If Qwen is answering from a document already sitting in the prompt, the system can fill the remaining draft positions using tokens found directly in that context. 🎯 So the target model can verify 16 tokens at once. On a ~25K-token document reproduction task: Previous DFlash2 👉 ~260 tok/s Longer verification + context lookup 👉 🔥 ~382 tok/s Acceptance: 🤯 15 of 16 tokens per verification step That is where the crazy number comes from. ⚠️ On ordinary real-world chat prompts, the same setup is around ~133 tok/s Still extremely fast for a dense 27B model on an RTX 3090. The 381 tok/s mode shines when the answer largely comes from material already in context so these are best use cases 📚 RAG / document Q&A 💻 Coding assistants applying edits 📝 Quoting or rewriting documents 🔎 Extracting information from long prompts And another optimization 👉 With prefix caching, a second question against the same 25K-token document reportedly goes from: 🐌 22.4 sec TTFT → ⚡ 0.56 sec TTFT Because the model doesn't need to process the whole document again. 🎯 It's specifically a mode for RAG front ends and coding agents. Follow iamMess on Reddit or syv-ai on GitHub 🔗 Reddit: r/LocalLLaMA/comments/1vtup5s/ 🔗 GitHub: /syv-ai/qwen38-27b-rtx3090
David Hendrickson330,726 görüntüleme • 1 ay önce
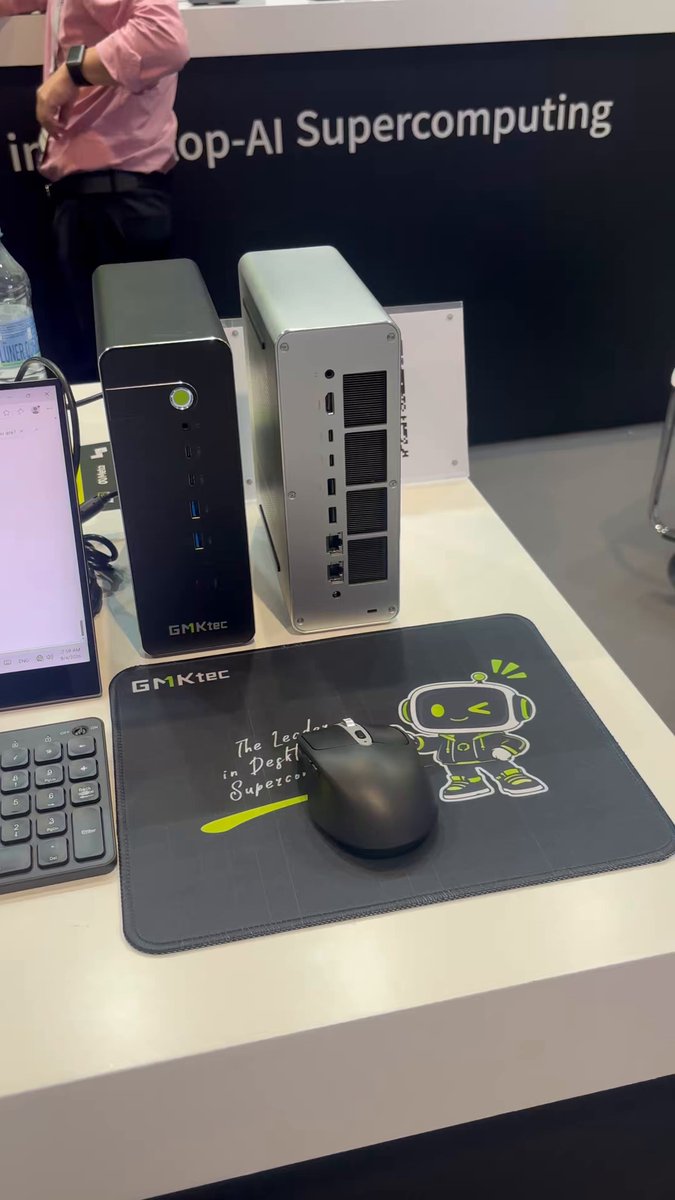
🖥️ UPDATE: GMKtec released it! Last week I said “fingers crossed they actually ship the EVO-X5 Pro with the full 192GB.” Confirmed today at IFA: they are. 🔥 GMKtec just officially unveiled its new Local AI monster: 🧠 192GB unified memory 🎮 Up to 160GB GPU memory ⚡ Ryzen AI Max+ PRO 495 🧮 16 Zen 5 cores / 32 threads 🎮 Radeon 8065S / 40 CUs 🤖 55 TOPS NPU 💾 Up to 24TB storage 🔌 4× USB4 incl. USB4 v2 🎮 eGPU support 🔗 Multi-node clustering And here’s the crazy part: GMKtec says the EVO-X5 Pro can run 300B-parameter LLMs fully offline on ONE box. AMD independently says the PRO 495’s 160GB graphics-memory allocation can support 300B+ models at 4-bit. ⚠️ No tps yet. GMKtec explicitly says the 300B claim is theoretical for now and real performance comes with the commercial launch. 📅 Ships October 2026 💰 Price: not announced 128GB Strix Halo changed Local AI. Now we’re getting 192GB. The question is no longer “will GMKtec actually build it?” How fast will a 300B GGUF run on it? 👀🔥
David Hendrickson55,790 görüntüleme • 1 ay önce

Been tracking how LLMs do on IQ tests, especially on TrackingAI. Regardless of what you think about the test, LLMs have struggled to exceed 130, especially on questions not included in its training. Recently, models have breached this and now test better than 99% of humans
David Hendrickson84,393 görüntüleme • 2 ay önce

Qwen3.8-Flash-Next is really bad in my test. ☹️ Qwen3.8-27B killed my Cosmic Dodge game (in a good way), it one-shotted it, and the second shot gave it polish. Qwen3.8-Flash-Next really struggled. In 5 tries, it didn't get it completely correct. Bosses don't die, and neither does the player. It seems like Qwen4 still has a way to go before we can say goodbye to Qwen3.8.
David Hendrickson33,129 görüntüleme • 1 ay önce

DeepSeek V4 Flash 0731 vs Opus 5. Only 7 days separated their releases. While Opus 5 accomplished in 1 shot what took DS 3, DeepSeek V4 Flash did it in ~900 lines vs ~3000 lines for Opus. Cost delta is stark. DeepSeek cost 1 cent. DS V4 Flash 0731 is new baseline for value-perf
David Hendrickson43,797 görüntüleme • 2 ay önce

A 27B model with 96K context built an actual game locally on a 16GB RTX 5070 Ti at 75 tps. This wasn't a benchmark but an actual working villager simulation. Setup 👇 🎮 RTX 5070 Ti 16GB 🧠 Qwen3.8-27B 📦 UD-Q3_K_XL GGUF 🚀 Fully GPU-offloaded 🦙 beellama.cpp + Kvarn optimizations 🔮 MTP n=2 🧮 Kvarn3 KV cache 📚 96,256 context ⚡ up to 75 tok/s generation 📥 up to 1,700 tok/s prefill 🪟 Windows The model incrementally built a browser-based village simulation with: 🏠 housing 🌦️ weather + seasons 🌙 day/night cycles 🍖 hunger 🪵 resources 💀 deaths 🚶 obstacle avoidance 👨🌾 autonomous villagers 🎯 The user deliberately chose a Q3_K_XL model + heavily compressed KV cache so the entire 27B model, MTP and ~96K context could stay inside 16GB VRAM instead of spilling weights to CPU. Their conclusion was not to fear Q3 models or aggressive KV quantization when the alternative is CPU offload and a massive speed hit. 😁🔥 ⚠️ This also uses beellama.cpp/Kvarn, not stock llama.cpp. 🔗 Reddit /r/LocalLLaMA/comments/1w821fg/ninfer_vs_llamacpp_vs_vllm_quality_speed/
David Hendrickson20,899 görüntüleme • 1 ay önce

GLM-5.2 is legit. It produces games easily and as accurately as SOTA closed-source models. My GLM 5.2 versus Fable 5 comparison is close, but I prefer Fable 5 just a little. Both games are equal in nearly all respects, but Fable 5 produced slightly better graphics and more challenging gameplay. Both needed 2 shots to get all the prompt instructions correct.
David Hendrickson18,785 görüntüleme • 4 ay önce

🆕 Fable 5 vs Nex-N2-Pro. Anthropic's new Fable 5 did NOT one-shot my Cosmic Dodge prompt, unlike Nex-N2-Pro. imho Nex-N2's output is more exciting, gameplay more aggressive, and bonus drops faster, but the outputs are still very close. 🏆 I give Nex-N2 the WIN, but very close. ✦ Fable 5 $50/1M > Nex-N2 $0/1M ✦ Nex-N2 1-shot > Fable 5 2-shot
David Hendrickson18,495 görüntüleme • 4 ay önce
Daha fazla içerik yok.