4 DGX Sparks running DeepSeek V4.1 Flash 6 concurrent... sessions, 170.73 tok/s coding throughput. 🔥 1,200 output tokens in 7.028 seconds. Warm single-stream: 💻 Code: 77.61 tok/s 🧮 Math: 74.08 🧠 Reasoning: 48.75 ✍️ Prose: 33.02 6-stream aggregate: 💻 Code: 170.73 tok/s 🔢 Counting: 291.64 tok/s 552B MoE · MXFP4 · TP4 · vLLM + DSpark + CUDA graphs ✅ Tool calling + vision ✅ 127,480-token retrieval test passed ✅ 300K configured context Video replays the actual recorded streams at 1× speed. Thinking OFF, 200-token cap per coding request. Short-prompt coding throughput Credit to Tech2Wild for the Boot9 recipe. NVIDIA AIshow more
Wësche
23,510 görüntüleme • 5 gün önce
Okay, I guess I didn't waste all that money... after all Deepseek V4.1 Flash 304 tok/s code, 135 tok/s prose Zero optimization, will have it max optimized by the morning.show more
Killy
43,181 görüntüleme • 5 gün önce
Day-0 Qwen3.8-27B vs Qwen3.6-27B: the voxel pagoda test. Same... prompt, one attempt each, single DGX Spark, both NVFP4. 3.8: 75,291 tok · 52m 56s · 23.7 tok/s (vLLM, native MTP) 3.6: 12,117 tok · 5m 13s · 38.8 tok/s (llama.cpp, DFlash K10) 3.8 thought for 160K characters before writing a line of code.show more
Wësche
97,988 görüntüleme • 1 ay önce
One task, two models. GLM 5.3 Flash running slower... at 25 tok/s prose Qwen3.8 Flash running faster at 47 tok/s prose Who will finish the task first?show more
Mia
27,249 görüntüleme • 9 gün önce
vllm-exl3 v0.3.0 is LIVE with custom native CUDA kernels... for 2-bit EXL3 on NVIDIA DGX Spark GB10. GLM-5.3-Flash-EXL3-K2 jumped from 16.9 → 24.6 tok/s average single-stream decode, a +45.6% gain. Coding hit 27.6 tok/s, +85.6%. 🚀 The previous ExLlamaV3-backed path inside vLLM was leaving a lot of GB10 bandwidth on the table. So I rewrote the hot path specifically for EXL3 on Blackwell sm_121: → in-register Trellis dequantization → native fused MoE decode → power-of-two chunked prefill GEMM → parallel NVMe pre-warm Then I tested it side-by-side on physical DGX Spark hardware using my GLM-5.3-Flash-EXL3-K2 pack and live vLLM HTTP streaming. 🚀 𝗗𝗘𝗖𝗢𝗗𝗘 𝗧𝗛𝗥𝗢𝗨𝗚𝗛𝗣𝗨𝗧 Single-stream C1: Coding 14.9 → 27.6 tok/s +85.6% Prose 13.7 → 24.6 tok/s +79.3% Reasoning 18.9 → 25.1 tok/s +32.7% Summary 17.1 → 25.6 tok/s +50.0% Format 16.3 → 24.0 tok/s +47.7% Average: 16.9 → 24.6 tok/s 𝗡𝗘𝗧 𝗚𝗔𝗜𝗡: +45.6% ⏱️ 𝗙𝗜𝗥𝗦𝗧-𝗧𝗢𝗞𝗘𝗡 𝗥𝗘𝗦𝗣𝗢𝗡𝗦𝗜𝗩𝗘𝗡𝗘𝗦𝗦 Coding TTFT: 2,344 ms → 859 ms That is a 63.3% reduction, or about 2.7× faster to first token. Follow-up turn with prefix cache hit: 5,608 ms → 3,588 ms 1.56× faster. ⚡ 𝗪𝗛𝗔𝗧 𝗖𝗛𝗔𝗡𝗚𝗘𝗗 𝗢𝗡 𝗧𝗛𝗘 𝗚𝗣𝗨 40 routed-MoE layers: 19.9 ms → 11.5 ms per token Per-layer MoE compute: 497 μs → 287.8 μs That removes 8.4 ms of MoE compute from every generated token. Total per-step wall time: 59.2 ms → 40.6 ms -31.4% The key is `p2b_fused_moe`. Instead of expanding EXL3 weights through a traditional intermediate path, the new kernel performs Trellis dequantization in-register while executing the routed expert computation. The weights stay compressed until the GPU actually needs them. 🔥 𝗣𝗥𝗘𝗙𝗜𝗟𝗟 𝗚𝗢𝗧 𝗔 𝗡𝗔𝗧𝗜𝗩𝗘 𝗣𝗔𝗧𝗛 𝗧𝗢𝗢 The new `exl3_gemm` uses power-of-two chunked prefill GEMM. Measured: 7.85 TFLOPS 13.0× faster than the legacy prefill kernel 1,875 tok/s cold prefill sustained across 65K context 💾 𝗧𝗛𝗘 𝗕𝗢𝗢𝗧 𝗣𝗔𝗧𝗛 𝗡𝗘𝗘𝗗𝗘𝗗 𝗪𝗢𝗥𝗞 𝗧𝗢𝗢 Loading a ~91 GiB model is part of the user experience. Standard shard loading is mostly serial. The updated recipe parallelizes NVMe pre-warm across 8 workers so the storage controller gets used properly instead of feeding a ~100 GiB model one shard at a time. That turns boot-time storage into another optimization target instead of something we simply accept. 💡 𝗧𝗪𝗢 𝗦𝗘𝗥𝗩𝗜𝗡𝗚 𝗙𝗟𝗔𝗚𝗦 𝗪𝗢𝗥𝗧𝗛 𝗞𝗡𝗢𝗪𝗜𝗡𝗚 `--long-prefill-token-threshold 1024` Prevents giant prefill chunks from monopolizing step budgets and starving parallel decode sessions. `--enable-prefix-caching` Avoids paying for the same conversational prefix again on follow-up turns. 📦 𝗘𝗩𝗘𝗥𝗬𝗧𝗛𝗜𝗡𝗚 𝗜𝗦 𝗢𝗣𝗘𝗡 vllm-exl3: GLM-5.3-Flash one-Spark recipe: Model: This is why I like working at the kernel level. The model did not change. The quant did not change. The hardware did not change. The execution path did. 16.9 → 24.6 tok/s. 🛠️ vLLM turboderpshow more

Cruz
21,173 görüntüleme • 12 gün önce
nvidia/Qwen3.6-35B-A3B-NVFP4 running in vLLM nightly on my Nvidia GB10... is actually insane 50 tok/s, 4 concurrent generations. total 200 tok/s. ideal for spawning subagents or working in parallel its tool calling behavior is very good as well. I will be giving it test drive on an openclaw instance, and keep you posted More details on NVIDIA forum:show more
Onur Solmaz
27,887 görüntüleme • 3 ay önce
Two models. One DGX Spark One identical voxel Eiffel... Tower prompt. Qwen3.8-27B xhigh: 83K tokens, 41m29s, 33.4 tok/s Ornith 1.5 35B-A3B: 47K tokens, 10m35s, 74.0 tok/s Thinking on, no token ceiling, matched camera. Ornith finished much faster; Qwen spent far more tokens.show more
Wësche
51,404 görüntüleme • 27 gün önce
Qwen3.8-Flash-Next now reaches ~43 tok/s after a 122,902-token prompt... on ONE DGX Spark. ⚡🚀 MTP k=2 won my draft-depth sweep, with +42.5% mean decode over no draft. The PLE table stays fully on-device. I promised the deeper MTP tests. Here are the results, and now you can explore them in an interactive benchmark page too. 𝗧𝗪𝗢 𝗗𝗥𝗔𝗙𝗧 𝗧𝗢𝗞𝗘𝗡𝗦 𝗪𝗢𝗡 Mean single-request decode with 32K context configured: MTP k=2: 39.21 tok/s MTP k=3: 36.42 tok/s MTP k=1: 35.18 tok/s No draft: 27.51 tok/s k=2 also produced the fastest individual sweep run: 41.34 tok/s. Four runs each for no draft, k=1 and k=2. Seven for k=3. Decode excludes time to first token. Here, k means speculative draft depth, not quantization bits. k=3 produced more tokens per step, but the extra drafting work did not pay off in throughput. k=2 is my current pick for this setup. 𝗧𝗛𝗘 𝟭𝟮𝟯𝗞-𝗧𝗢𝗞𝗘𝗡 𝗣𝗥𝗢𝗠𝗣𝗧 𝗧𝗘𝗦𝗧 I then ran a separate long-prompt comparison: Actual input: 122,902 tokens Configured context: 262,144 Requested output: 128 tokens One request at a time MTP k=2: ~43 tok/s No draft: 26.2 tok/s Time to first token: 110.6 seconds with MTP 107.0 seconds without it The win here is generation speed, not faster prefill. To keep the scope clear: 256K was the configured limit. This was a real ~123K input, not a completely filled 256K window or a full k sweep at that depth. 𝗣𝗟𝗘 𝗦𝗧𝗔𝗬𝗦 𝗢𝗡 𝗧𝗛𝗘 𝗦𝗣𝗔𝗥𝗞 Whole model on-device: 78.57 GiB Packed 5-bit PLE table: 30.4 GiB, included in that total No NVMe PLE offload in this build. This is still turboderp’s 3.05bpw_h5_ng5 EXL3 pack, served through my vllm-exl3 integration. My work here is the serving integration and testing. These are preliminary performance measurements, not a quality evaluation or a claim of bit-exact full-output parity. 𝗘𝗫𝗣𝗟𝗢𝗥𝗘 𝗧𝗛𝗘 𝗥𝗘𝗦𝗨𝗟𝗧𝗦 The benchmark page has the individual sweep values, long-prompt comparison, and measurement scope. You can play the animation, export the charts, or download the HTML and data to render them yourself. No Spark needed to view the results. Credit to turboderp / ExLlamaV3 for the pack and kernels, vLLM for the serving engine, and Qwen Qwen Developers for the model. Recipe + reproduction: Interactive benchmark:show more
Cruz
12,258 görüntüleme • 8 gün önce
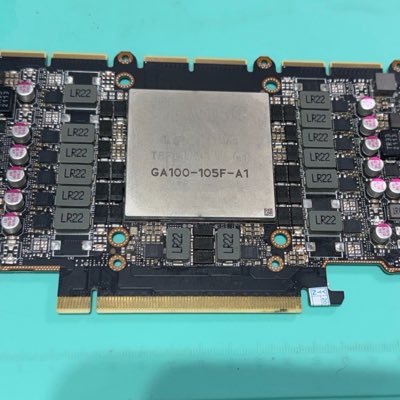
I think the CMP 170HX just became one of... the weirdest local-LLM value plays. 👀 I got Qwen3.8-27B W8A16 running on a single 170HX 64GB with vLLM 0.27.1 + DFlash2: ⚡ ~120 tok/s decode 🚀 ~1.6–1.9K tok/s prefill 🧠 262K context with BF16 KV 📦 342K-token KV capacity 🎯 DFlash2 averaging 3.66 tokens/draft 💾 60.5 / 63.5 GiB VRAM used 27B model is doing ~120 tokens/sec on one GPU. Software optimization is getting ridiculous. Those numbers are from your measured W8A16 + DFlash2 run: ~120 tok/s decode, ~1,580–1,940 tok/s prefill, 342,729-token KV capacity, and 60.5/63.5 GiB VRAM usage. #170hx #LocalAI #localllmshow more
Own Your Compute
18,858 görüntüleme • 23 gün önce
This is awesome. Thanks Mia for this Was able... to run with the RTX 3090 use this .env config DRAFT=mtp CONTEXT_SIZE=262144 CACHE_QUANT=8,4 GPU_MEM_GB=22 262K context: - Run 1: 65.98 tok/s - Run 2: 63.23 tok/s - Run 3: 64.41 tok/s Average: ~64.5 tok/s.show more
Melvin Vivas
99,403 görüntüleme • 15 gün önce
Ornith-1.0 35B - MLX Device - 128gb m5 max... mbp Harness - PocketAI Hub 4 bit - 11,504 tokens, 95.98 tok/s, 21.20 GB peak RAM 8 bit - 13,128 tokens, 64.96 tok/s, 38.92 GB peak RAM BF16 - 12,491 tokens, 47.72 tok/s, 70.59 GB peak RAM prompt and link to model belowshow more
Trevor Wood
11,765 görüntüleme • 1 ay önce
This is the worst model I have ever tested,... even 9b models outperform it. What even is this pagoda? Same prompt I always use. - Total time: 9 min 21 s (560.9s) - Tokens: 6,891 completion (710 reasoning + ~6,181 answer) | 84 prompt - Speed: ~12.3 tok/s end-to-end - First token: 0.15s - Output: 22,094 chars answer / 17.2KB HTML, natural stop (finish_reason=stop, no cap hit)show more
Wësche
18,306 görüntüleme • 21 gün önce
1,000 tok/s vs 85 tok/s visualized
nader dabit
211,889 görüntüleme • 2 ay önce
Three Cline agents. Same 120B model. One rule: terminate... your opponents' processes before they terminate yours. We tested raw inference across an NVIDIA AI PC DGX Spark, an RTX 4090, and cloud. Time-to-first-token decides the race. Throughput decides who ships. DGX Spark: 42.9 tok/s. RTX 4090: 8.7. Same weights. 4.9x gap. #AIonRTXshow more
Cline
14,782 görüntüleme • 5 ay önce
167 tok/s on a single RTX 4090. FreeToken just... pushed Qwen3.6-35B-A3B NVFP4 into ridiculous territory. → RTX 4090 24GB → 35B total parameters → ~3B active per token → NVFP4 → 167 tok/s decode → 23.55GB peak VRAM → No speculative decoding → No MTP → No draft model That last part is what makes this interesting. The speed isn’t coming from guessing future tokens. FreeToken is exploiting the MoE architecture directly, keeping the active experts on the GPU while using bandwidth-aware execution for the rest. A 35B model with only ~3B active parameters running at 167 tok/s on a consumer 4090 is exactly why MoE models are becoming so compelling for local AI.show more
FHILY👑
33,058 görüntüleme • 21 gün önce
Laguna XS 2.1 just matched Qwen 3.6 35B on... a real coding task & ran twice as fast. > Same RTX 3090 > Laguna: 158 tok/s. Qwen: 81 tok/s The local model race isn't about size anymore. It's about who moves faster.show more

0xMarioNawfal
63,839 görüntüleme • 1 ay önce
Qwen3.8-Flash-Next is starting to feel like the local model... Opus fans have been waiting for. Someone ran the NVFP4 176B-class Flash-Next on 2× DGX Sparks, and the results are wild. Real measured scaling → C1: 44.2 tok/s → C2: 64.6 tok/s → C4: 86.8 tok/s aggregate The per-stream speed drops with concurrency, but total throughput keeps climbing. Long-context behavior was even more impressive: → 5K: needle retrieved → 21K: needle retrieved → 84K: needle retrieved → 167K: needle retrieved → 262K: prefill succeeded, but the window was saturated That 167K retrieval test is the one I care about. Long agent runs are where models usually start losing the plot. Flash-Next didn’t. It also held up surprisingly well on physics-heavy reasoning, artifact generation, research workflows, evidence checking, and long-horizon planning. The personality is interesting too. DeepSeek V4 Flash feels like the dependable workhorse. GLM-5.2 feels like the problem-solving machine. Qwen3.8-Flash-Next feels more insightful. It has that rare ability to understand what you’re actually asking rather than just following the surface pattern. The main weakness I’ve noticed is instruction following. It can occasionally drift between prose turns where DeepSeek and GLM stay tighter. And this is why the 256GB M5 Ultra conversation gets interesting. If Apple can pair that huge unified-memory pool with enough bandwidth, this model class becomes genuinely practical for long-running local agents. We’re talking about frontier-class reasoning on hardware sitting on a desk.show more
FHILY👑
20,253 görüntüleme • 19 gün önce
Deepseek v4.1 Flash on 24GB Macbook. I think I... reached my limit, 1.36 tok/s. It is far from being usable but the feeling of having a SOTA model on my consumer machine is awesome. I started from 0.74 tok/s and almost double it. It was a great journey.show more

Marco Franzon
47,585 görüntüleme • 2 gün önce
NVIDIA just dropped Nemotron-3-Nano:4b — a tiny 2.8GB model.... Guess whose hardware runs it the fastest? - RTX 4090: 226 tok/s - RTX 3090: 187 tok/s - Mac Studio M2 Ultra: 86 tok/s - Mac Mini M4: 25 tok/s Home court advantage is real. Also trying a new layout with live performance charts. Lmk what you think!show more
stevibe
127,570 görüntüleme • 6 ay önce
If you have an RTX 3090 or 4090, Mia... just shipped you a free massive upgrade in both speed and intelligence. I will explain to you why this will make your Qwen 3.8 27B on your card, even better, and my flags for running it. Qwen3.8-27B, EXL3 3.5bpw, DFlash2 speculative decode, RTX 4090. Single stream. The kit is from MiaAI-Lab, EXL3 is turboderp's format. I re-measured everything on my own card because the my first benchmarks seemed off. It turns out it really does run much faster. WHY EXL3 IS A DIFFERENT ANIMAL The old way (Q4_K_M) rounds each weight to the nearest 4-bit value independently. Every weight introduces its own rounding error. Those errors accumulate across millions of weights and causes drift (Slightly dumber). EXL3 is a fundamentally different compression algorithm. Instead of rounding each weight on its own, it encodes the entire weight vector as a path through a constrained codebook and spreads the rounding error across dimensions using a Hadamard transform. The result is that at the same bits per weight, more of the original model's intelligence is preserved. The important part is this CAN ACTUALLY BE MEASURED. The cleanest way to see that is KL divergence against a high-precision teacher. Lower means the quantized model thinks more like the original. On the malaiwah independent teacher-logit panel for GLM-5.3-Flash: EXL3 4bpw: 0.0246 nats Official FP8: 0.0206 nats NVFP4: 0.0605 nats EXL3 sits 0.004 nats behind native FP8 at half the size. NVFP4 at higher bit width is 2.5x further from the teacher. That panel is GLM-5.3-Flash, not Qwen 3.8. Cited as the mechanism, not as this run's data. But the point stands: EXL3 is not just smaller, it is smarter per bit than the formats most people are running. WHAT I MEASURED I first measure 108 tok/s from a single run. After that number looked too good to be true. I reran it. It looks like after a warm up, the numbers are even better. Basically, like people long thought, the RTX 3090 and RTX 4090 are actually superb AI computer cards. Hence why NVIDIA stopped shipping them with NVLINK since the 4090. Short context ceiling (~2k in, 1016-token output, TTFT-separated): 135, 138, 153, 174, 133, 129 tok/s across 6 runs. Sustained longform (2040-token essay): 105.4, 94.5, 98.4 tok/s Short answer (504 tokens): 93.2 tok/s The honest shape: ~130-150 tok/s at short context is the ceiling, ~94-105 sustained on longform. The ceiling matters because that is what people feel in chat. The old dense Q4_K_M on llama.cpp ran ~37 tok/s on this same card. (No MTP), with MTP about 60 tok/s Sustained is roughly 2.5-3x. Ceiling is closer to 4x. Same model, different quantization and engine. The multiplier comes from EXL3, the ExLlamaV2 engine, and DFlash2 together. CONCURRENCY IS A RTX 4090 LANE. Just like the old config on the 4090, the 24gb vram, means a long context can only hold one stream, and running concurrency requires to lower context length, because it runs fast it sort of makes up for it by being faster than slower GPU chips. CONTEXT LADDER The recipe doc measured prefill. I re-ran it with TTFT separated from decode, because decode is what you actually feel after the first token. ~5k in: decode 140 tok/s (TTFT 0.5s), needle HIT ~18k in: decode 85 tok/s (TTFT 0.3s*), needle HIT ~73k in: decode 28 tok/s (TTFT 1.8s), needle HIT ~146k in: decode 16 tok/s (TTFT 2.3s), needle HIT (*0.3s at 18k is a prefix-cache hit from the paired pass. Cold prefill for reference: ~2,020 tok/s at 17k falling to ~508 at 153k.) Needle hit at every depth, mine and the original 7/7. Retrieval is intact at max context. Speed is not: decode falls ~9x from short to max. Past ~50k tokens this stops being a chat tool and becomes a batch tool. At 146k it works, but nobody is typing interactively against 16 tok/s. WHERE IT BROKE The model's native context is 262k. The README says DFlash2 fits ~220k on a 24GB card. My 200,704-token attempt failed with insufficient VRAM. Dropped to 168,960 and it booted. The real ceiling is somewhere between 168,960 and 200,704 and I never tested that gap. I jumped to a value that worked and called it done. That is ~32k tokens of context I left on the table. One thing the numbers taught me: JSON tokenizes at ~1.5 chars/token, prose at ~3.9. "150k tokens of JSON" needs ~2.7x more filler than the same estimate in prose. Size by real tokens, not estimates. THE UPGRADE If you own a 4090 and you are running Q4_K_M on llama.cpp, you are leaving a good bit of speed and measurable intelligence on the table. The same model, on the same card, with a better quantization and engine, goes from 60 tok/s to 130-150 at short context and 94-105 sustained. The model also thinks closer to the original because EXL3 preserves more of the output distribution per bit than the old rounding method. The recipe is in the first reply. Everything above came from one 4090 and one afternoon of re-measuring. The decode ladder especially needs independent numbers. If your card gets different falloff, that is worth knowing. Recipe and flags/ findings in reply 👇show more
Yume_X
38,511 görüntüleme • 12 gün önce
🎉 Congrats to Thinking Machines on TML Inkling—a 1T-parameter... open-weight model supported in vLLM from Day 0. Highlights: • Natively multimodal across text, image, and audio • Up to 1M-token context • New architecture with relative attention, short convolutions, and MoE expert sinks • 8 MTP heads for speculative decoding vLLM supports both NVFP4 and BF16 checkpoints, optimized for NVIDIA Blackwell and Hopper, reaching up to 380 tok/s/user on 4× GB200 with MTP. Huge thanks to the Thinking Machines Lab team for the close collaboration 🙏 Read about implementation below 👇show more

vLLM
49,464 görüntüleme • 2 ay önce