Tiny Recursive Models: A tiny 7M parameter model that... recursively refines its answer beats LLMs 100x larger on hard puzzles like ARC-AGI We independently reproduced the paper, corroborated results, and released the weights + API access for those looking to benchmark it 🔍show more

alphaXiv
52,843 次观看 • 1 年前
STARBOY perceives its environment through a camera, microphone, temperature... sensor, and accelerometer. We trained multiple tiny image models that run locally on the device, letting it recognize human faces and hand gestures.show more
Daniel Kuntz
116,682 次观看 • 7 个月前
Turn any open LLM into a Jev-style model: Researchers... just open-sourced AnyJev, a Python library that extracts typed choices, yes/no judgments, scores, and probabilities from causal LLMs. Beyond its raw baseline, AnyJev offers three levels depending on how much labeled data and calibration you need: - L0 requires no labels. It rotates the answer options to reduce position bias, but its probabilities remain uncalibrated. - L1 uses 100-500 labeled examples per question to calibrate those probabilities through temperature scaling. It improves confidence estimates without changing the answer ranking. - L2 uses 100-300 labels to fit a closed-form head on an intermediate hidden state. It leaves model weights untouched and can stop inference before the full forward pass completes. The main constraint is model access. AnyJev requires access to logits or hidden states, so it is built for open models. L2 heads are also specific to a model and question. It is compatible with several open causal LLMs. Repo: (don't forget to star it ⭐ ) If you want to dive deeper, I also wrote about a similar mechanism in a hands-on guide. It covers building a Jev-style decision path with open models, entirely locally. Read it below.show more

Avi Chawla
56,140 次观看 • 23 天前
LongWriter Unleashing 10,000+ Word Generation from Long Context LLMs... discuss: Current long context large language models (LLMs) can process inputs up to 100,000 tokens, yet struggle to generate outputs exceeding even a modest length of 2,000 words. Through controlled experiments, we find that the model's effective generation length is inherently bounded by the sample it has seen during supervised fine-tuning (SFT). In other words, their output limitation is due to the scarcity of long-output examples in existing SFT datasets. To address this, we introduce AgentWrite, an agent-based pipeline that decomposes ultra-long generation tasks into subtasks, enabling off-the-shelf LLMs to generate coherent outputs exceeding 20,000 words. Leveraging AgentWrite, we construct LongWriter-6k, a dataset containing 6,000 SFT data with output lengths ranging from 2k to 32k words. By incorporating this dataset into model training, we successfully scale the output length of existing models to over 10,000 words while maintaining output quality. We also develop LongBench-Write, a comprehensive benchmark for evaluating ultra-long generation capabilities. Our 9B parameter model, further improved through DPO, achieves state-of-the-art performance on this benchmark, surpassing even much larger proprietary models. In general, our work demonstrates that existing long context LLM already possesses the potential for a larger output window--all you need is data with extended output during model alignment to unlock this capability.show more
AK
50,995 次观看 • 2 年前
Average US AI lab: > builds the strongest model... > gets scared of its own model > spends months arguing about safety > fights other AI labs over who has the strongest model > delays the release for more safety testing > regulators ask for even more safety > switches users to a dumber model > keeps it closed source Average Chinese AI lab: > trains Kimi K3 > builds a 2.8T parameter monster > gives it a 1M context window > beats GPT-5.6 and Claude Fable 5 on some tasks > open-sources the weights > publishes the architecture > refuses to elaborate > leavesshow more
Tornado guy
161,361 次观看 • 3 个月前
Microsoft made 100B parameter models run on a single... CPU. bitnet.cpp: The official inference framework for 1-bit LLMs. The math behind 1-bit LLMs is what makes them revolutionary. Traditional LLMs use 16-bit floating point weights. Every parameter is a number like 0.0023847 or -1.4729. When you run inference, you multiply these floats together. Billions of times. That's why you need GPUs, they're optimized for floating point matrix multiplication. BitNet b1.58 uses ternary weights: {-1, 0, 1}. That's not a simplification. That's a fundamental change in the math. When your weights are only -1, 0, or 1: → Multiply by 1 = keep the value → Multiply by -1 = flip the sign → Multiply by 0 = skip entirely Matrix multiplication becomes addition and subtraction. No floating point operations. No GPU required. This is why bitnet.cpp achieves: → 2.37x to 6.17x speedup on x86 CPUs → 1.37x to 5.07x speedup on ARM CPUs → 71.9% to 82.2% energy reduction on x86 → 55.4% to 70.0% energy reduction on ARM The speedups scale with model size. Larger models see bigger gains because there are more operations to simplify. A 100B parameter model running at human reading speed (5-7 tokens/second) on a single CPU. That's not optimization. That's a different paradigm. Why 1.58 bits? Because log₂(3) ≈ 1.58. Three possible values = 1.58 bits of information per weight. The key insight: These models aren't quantized after training. They're trained from scratch with ternary weights. The model learns to work within the constraint. No precision loss. No quality tradeoff.show more

Tech with Mak
23,202 次观看 • 6 个月前
Today, we are releasing Stable Video Diffusion, our first... foundation model for generative AI video based on the image model, Stable Diffusion. As part of this research preview, the code, weights, and research paper are now available. Additionally, today you can sign up for our waitlist to access a new upcoming web experience featuring a Text-To-Video interface. To access the model & sign up for our waitlist, visit our website here:show more
Stability AI
1,024,881 次观看 • 2 年前
I love this opensource project! Someone just put a... 28.9M parameter AI model on an ESP32-S3. A chip that costs only a few dollars. No cloud. No API. No internet. It runs locally at ~9.5 tokens/s and can generate stories on a tiny screen. This changes the way we think about AI hardware. The next generation of AI toys, robots, and IoT devices may not need the cloud at all. Small chips are getting smarter. 🤖show more

Steven Cheng
105,352 次观看 • 2 个月前
🚀 Self-speculation brings 6.75x real speedup for LLM generation... with SGLang inference! Same model drafts future tokens in Diffusion mode → then verifies them in AR (causal) mode. One model and one KV cache. Just different attention masks. Thanks to perfect alignment, we get 2× longer acceptance lengths than MTP techniques (Eagle-3, MTP, dFlash). We run 2 forward passes… but the 2× higher acceptance means we break even - and with zero overhead from extra drafter, KV cache, or LM head that comes with MTP - those are not free. Last week we released Nemotron-Labs-Diffusion + Tri-mode LLMs! We did continued pre-training on Ministral-3 models by switching attention patterns (block causal bidirectional). Result: one model that runs AR mode, Diffusion mode, and Self-Speculation. Diffusion mode already shows high benchmark accuracy - excited to see what happens when someone beats left-to-right acceptance! 🔥 Github: Paper: SGLang inference: Try the models on HF:show more

Pavlo Molchanov
66,604 次观看 • 4 个月前
🇯🇵 A JAPANESE LAB SAYS IT MATCHED FABLE 5... LEVELS. While the world braced for China to crack the frontier, a Tokyo lab did something stranger. Sakana AI, co-founded by one of the authors of the original Transformer paper, launched Fugu today. It's not a bigger model. It's a conductor. One API that quietly assembles a team of other models, splits the work, verifies it, and hands you one answer. Sakana claims its top tier matches Anthropic's Fable 5 and Mythos.show more
CryptoGoos
27,467 次观看 • 3 个月前
🚨VITALIK: AGI MAY MARK THE POINT OF NO RETURN... FOR HUMAN DOMINANCE! Vitalik warns in a new thread that AI could soon cover nearly all human capabilities, leaving us without unique advantages. He defines AGI as systems that could independently sustain civilization if humans disappeared, and stresses we're gambling on whether LLMs and tools will get there, or if deeper integration keeps human agency alive. He favors slowdowns and open weights to navigate safely.show more

Crypto Banter
53,713 次观看 • 3 个月前
I'll always root for a team that open-sources its... best work, and Robbyant just did it properly. Robbyant, Ant Group's embodied-AI company, released LingBot-Vision, a vision foundation model for robots, and the part I love is the data. They trained it on 161M images, filtered down from 2B raw ones and mostly pulled straight from the open web, with no human labels, no edge detectors, no depth sensors anywhere in the loop. It learns the exact edges of objects from raw pixels. That's roughly a tenth of the data DINOv3 saw, and under a third of the training. And it shows in the results. On depth, working out how far away things are, the 1B model edges out a 7B on NYU-Depth. It also powers LingBot-Depth 2.0, which reads the surfaces cameras usually choke on, glass and mirrors, and halves indoor depth error. LingBot-Vision is fully open. Weights from the 1.1B flagship down to a tiny 21M version, code, and the paper. This is the timeline I want more of. Robbyantshow more
Chubby♨️
48,249 次观看 • 3 个月前
The newest GTA 6 gameplay trailer dropped yesterday. we... ran our subnet vision models on it. Person, car, gun, segmented and tracked across every scene. night, water, motion blur, freefall over the city. footage the model had never seen. The part that matters is that this isn't a huge model. it's tiny, and it runs near real time. Vision that works in the real world...and the fake one.show more

Score
681,581 次观看 • 1 个月前
Big win for open-source LLMs! DeepSeek V4 Pro holds... the top open-weights score on SWE-bench Verified, in the GPT-5.5 range. GLM 5.2 leads the open-weight intelligence index and sits near the closed frontier on long-horizon coding. But this leaderboard number is a weak proxy for real performance. It comes from one task set, run through one harness, served at one precision. The same weights can even score differently across providers, since many hosts quantize activations to fp8 and drift the model off its reference weights. Real performance is determined based on whether a model can read a repo, make coordinated edits across files, run the tests, and recover when one breaks. By that measure, the top open models hold up, but only inside the right harness. The teams that actually put DeepSeek V4 into production pipelines as a frontier substitute got there through the harness they built around the model, not by picking a stronger model. If you want to see this in practice, Cline (64k+ stars) has actually built that harness around open models, tuned so they run at production quality. And it's tuned so that these LLMs can run at production quality, with plan and act modes, checkpoints, and terminal feedback. ClinePass is the new access layer on top of it. It runs a curated set of those models inside Cline, narrowed to the ones tested for coding-agent use, with 2 to 5x the standard rate limits and no separate provider accounts, keys, or billing to track. The video below shows the setup, and I worked with the team to put this together. It runs alongside custom keys and local models as well, not in place of them.show more
Avi Chawla
44,124 次观看 • 3 个月前
Most recent diffusion language model research (that I’ve seen)... seems to be using masking as the noising process. It looks like, however, most closed-source models (Google Gemini Diffusion and possibly Inception Labs’ Mercury) use a different noising process, where instead of masking tokens, they replace them with different tokens (either with a random token or a semantically similar token). I wondered how they were getting such high throughput with the latter noising process, since I believed that optimizing inference with KVCache approximation would be more difficult (for various reasons). I visualized this noising process with tiny-diffusion and compared it to normal unmasking, and was very surprised to see how fast the generation “settles” into a reasonable output, and then only slightly refines afterwards, requiring much fewer steps in total. Unmasking (where tokens are never remasked, the typical implementation) is inherently limited in generation speed by the fact that an increase in tokens decoded per step leads to more errors due to the mismatch between individual and marginal token probability distributions we sample from. The token replacement noising process seems to have a much different set of characteristics. Because we sample each token per step, every token makes “progress” towards the final output each iteration (in addition to *potentially* giving other tokens more information in future steps). Generally, masking has outperformed other noising processes, which is probably why most research focused on it (using smaller models). But the paper referred to in the retweet shows that random replacement as a noising process may scale better as model size increases. Big labs might have noticed these results much earlier (due to having drastically more training resources and being able to test larger models), which may explain the discrepancy in the choice of noising process. I’m gonna test this with larger models, since tiny-diffusion only has 10M parameters.show more

nathan (in sf)
40,440 次观看 • 9 个月前
1-bit Qwen3.8-27B just more than DOUBLED its MMLU-Pro score.... They didn’t change the decoder. 29.04% -> 61.54%, according to a new paper from ISTA-DASLab. Same lab behind GSQ-RCO, some of the best tiny Qwen3.8-27B quants in my book. Their method is called Disaggregated Quantization. You use different weights to read the prompt and generate the answer. A trained NVFP4 prefiller processes your input and builds the cache. Then the tiny GGUF decoder takes over. They train the prefiller specifically for that decoder, so it learns to produce representations the heavily compressed model can use. The extra checkpoint is 12.8 GiB, but you don’t need all of it in VRAM. Stream it from SSD layer by layer, reusing GPU memory. With a long enough prompt, loading can overlap computation. That’s a pretty fucking good reason to pay attention if your GPU is short on memory. I want to test this on my 4x3090 rig with NVMe. The released implementation targets Blackwell, so this needs adaptation. First I’ll check whether the quality gains survive on Ampere, then measure whether offloading actually helps. Paper:show more
Alexey Fateev
19,870 次观看 • 19 天前
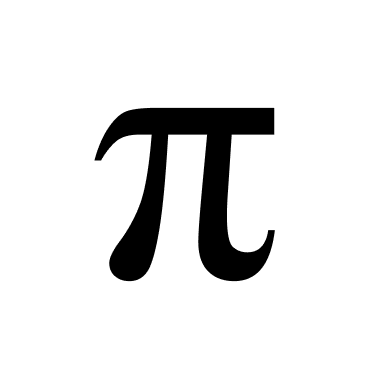
Many of you asked for code & weights for... π₀, we are happy to announce that we are releasing π₀ and pre-trained checkpoints in our new openpi repository! We tested the model on a few public robots, and we include code for you to fine-tune it yourself.show more
Physical Intelligence
442,397 次观看 • 1 年前
We released physics-intern: a simple harness for science problems!... It gets models like Gemini 3.1 Pro to go from 17.7 -> 31.4, thus beating GPT 5.5 Pro. The physics-intern harness can wrap any model and via dedicated subagent boost the performance of the vanilla reasoning models. While I think more and more of these harness capability gains will be absorbed into the models (like prompting tricks disappeared over time) there is a lot to be gained right now by building good scaffolds for those models and integrating tools well. Interestingly, the exception we found that GPT 5.5 Pro actually didn't benefit from the physics-intern harness! Read more about it here: PS: I think the Harness[Model] notation is kind of nice.show more
Leandro von Werra
97,519 次观看 • 4 个月前
Moonshot AI is casually giving developers free daily access... to Kimi K3 😳 no subscription no upfront payment just sign in and start using one of the largest open AI models available what you get for $0: - Kimi K3 with 2.8T parameters - 1M token context window - strong coding and reasoning performance - native vision capabilities - free daily credits that refresh automatically why this is worth checking: > access a frontier model without paying API fees > long context for large codebases and documents > works on web, desktop, mobile, and CLI getting started takes less than 2 minutes: 1. go to 2. create a free account 3. Kimi K3 is available as the default model 4. start chatting or coding with your daily free credits bonus: Moonshot Together lets you invite friends for a chance to earn 3, 7, 15, 30, or even 365 days of Kimi Membership through its rewards program benchmark highlights: > 2.8T parameter MoE model > 1M context window > strong performance across coding, browsing, and reasoning benchmarks important: free credits reset daily, rate limits apply on the free tier, and the open-weight release is expected on July 27 A simple way to try one of the latest frontier AI models without paying for API accessshow more
K2S
23,110 次观看 • 3 个月前