正在加载视频...

视频加载失败

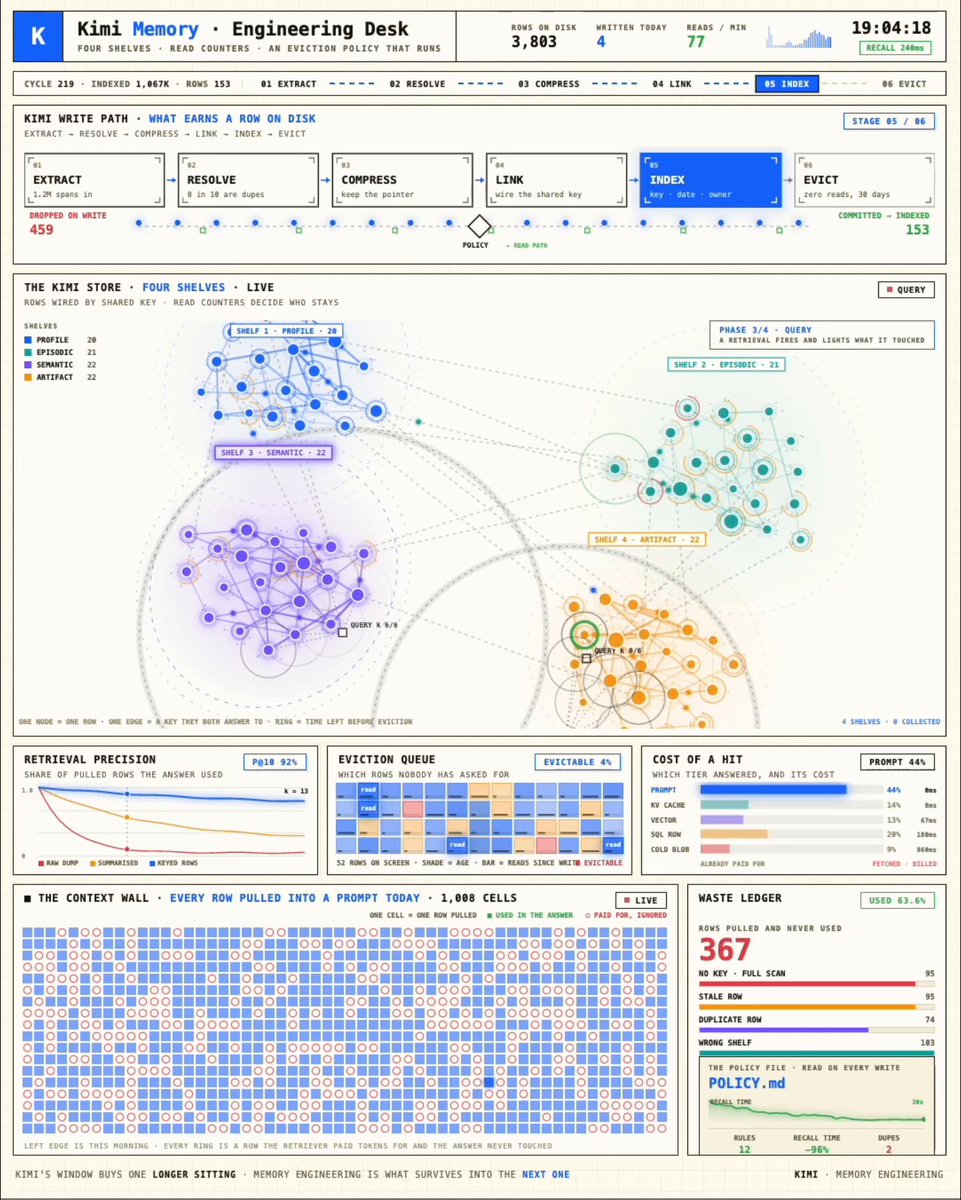
A million-token window solved the wrong problem, and Kimi K3 shipping one made that harder to see. 2.8T parameters, weights on your disk, an entire codebase in one prompt. Feels like memory. Isn't. Memory is what survives the session ending. A window is what survives the next token. Self-hosting...

17,620 次观看 • 2 个月前 •via X (Twitter)

0 条评论

暂无评论

原始帖子的评论将显示在这里

相关视频

context engineering vs graph engineering. every few months the list gets a new word and everyone treats it as a replacement for the last one. these two are not on the same list. one decides what the model sees this turn, the other decides what exists at all. the cleanest way to tell them apart is to ask what a single unit of work looks like. > context engineering is the window the window opens empty, every single time. you assemble what goes in it. the prompt, the docs, the history, the tool results. the assembling is the work. the window only grows. it never shrinks on its own, so eventually something gets dropped. usually from the middle. usually without telling you. then the turn ends and the window is thrown away. not archived, thrown away. the next turn opens empty again and you re-explain what you already explained. good context engineering is knowing what to leave out, not what to pack in. the unit of work is one window. > graph engineering is the structure the same material arrives from the same sources. instead of packing it into a window, you pull entities out of it, resolve the duplicates into one node, and write typed edges between them. nothing here is stored as text you hope to find again. it is stored as a thing with a name and its connections to other things. when the turn ends, the graph is still there. the next turn does not start from zero. it starts by querying what already exists, and the query walks edges instead of guessing at similarity. good graph engineering is deciding what counts as the same thing twice. the unit of work is one relationship. > they are not alternatives the graph is what refills the window. context engineering decides what fits. graph engineering decides what there is to choose from. remove the graph and every session starts blind. remove the context work and the best structure in the world arrives as an unreadable dump. that also tells you which one broke. the answer drifted from what you actually said, or forgot something from this same session. that is the window. the answer is coherent but invents a connection that does not exist, or cannot join two facts it has clearly seen. that is the structure. people debug the prompt because the prompt is the easiest thing to edit. it keeps taking the blame for failures that live a layer down. save this - then read the full breakdown below

Hanako

19,160 次观看 • 3 个月前

Context vs. Graphs, clearly explained! context engineering is great, but it has a ceiling: you can make one window perfect. there is still only one of it. every technique on that layer is rationing the same scarce thing. compact, retrieve less, delete, defer. all of it is deciding what to drop. Graph engineering fixes this by moving the decision up a layer: not what goes in the window, but how many windows there are and what each one is for. you need both. here's how it works: ↳ inside a window: context engineering. what loads, in what order, what gets compacted ↳ between windows: the graph. how many lanes, what each one is allowed to see, what comes back Prompts → Context → Harness → Loops → Graphs each lane gets a clean window, nothing in one competes with anything in another, and your main thread stops filling up. the trick is being selective about what comes back. a subagent reads six thousand tokens of files and hands you a four hundred token summary. that ratio is the whole point. send back the raw material instead and you have moved the problem, not solved it. one thing to know before you scale it. not everything survives compaction equally, and almost nobody knows the table. ↳ the project-root rules file and auto memory are re-injected from disk. they come back intact ↳ path-scoped rules and nested rules files live in message history. they get summarized away and do not return until a matching file is read again so a rule that genuinely must persist cannot be path-scoped. move it to the root and pay the always-loaded cost, or accept that it is advisory in any long session. and the one that eats whole nights: shared context makes parallel agents converge. four auditors on one window produce one opinion with three echoes. you paid four times for it. below i have quoted my full guide on graph engineering. it covers the three topologies, the verifier patterns, and where the gate should actually open. save this and read it below ↓

Hanako

36,970 次观看 • 2 个月前

Memory vs. Graphs, clearly explained! memory is great, and the ceiling arrives quietly: it stores what happened. it does not store what to do about it. six runs later your file has fifty lines, and the model reloads all of them before it does anything. Graph engineering fixes this by changing what memory is: not a place things are kept, but an edge that runs backwards. you need both, and here is the sentence that resolves the whole confusion: a store keeps what happened. an edge keeps what to do about it. ↳ a store grows with every run, and every line is reloaded before the next one ↳ an edge carries one derived rule, and the rule replaces the run that produced it Prompts → Context → Harness → Loops → Graphs the transcript goes away, the constraint stays. and the constraint is smaller, because "adapters preserve keyword args exactly" is four hundred tokens shorter than the run that proved it. the same four blocks work on anything you can cut into lanes. i pointed them at token launches on Robinhood Chain, open source, nothing leaves your terminal the trick is knowing what deserves to survive. an output is not memory. "ported the utils slice, green on first pass" tells the next run nothing it can act on. the rule you derived from it does. one thing to know before you scale it. what you write down is not what comes back. ↳ the root rules file and auto memory are re-injected from disk. they come back intact, every time ↳ path-scoped rules live in message history. they get summarized away and do not return until a matching file is read again so a rule that must persist cannot be path-scoped. move it to the root and pay the always-loaded cost, or accept that it is advisory in any long session. and the one that eats whole nights: a memory file that has never had a line deleted is not memory. it is a tax on every run you will ever make, and nobody reads it back. below i have quoted my full guide on graph engineering. it covers the three topologies, the verifier patterns, and where the gate should actually open. save this, and the repo that runs it is below ↓

Hanako

48,225 次观看 • 1 个月前

Micron is going to $4,000 and once you understand what inference actually is, the number stops sounding crazy (Save this). Dylan Patel just said that by 2030, OpenAI and Anthropic alone will need over 100 gigawatts of compute combined and by 2040, we may not even be measuring AI infrastructure in gigawatts anymore. We may be talking about terawatts. Every single one of those gigawatts needs memory to function. Without it, the compute is worthless. Most people heard that and thought about Nvidia but they should be thinking about Micron. Every AI model generating a response has two phases. The first is prefill, processing your prompt which is compute-heavy and the second is decode generating each word one token at a time and that phase is almost entirely memory-bound, not compute-bound. During decode, the GPU's processing units sit idle more than 95% of the time, waiting for data to arrive from memory. Google confirmed it in a research paper that decode-phase bottlenecks are dominated by memory bandwidth and capacity not raw compute. The GPU is not the bottleneck but the memory feeding the GPU is. This matters because inference is now where all the money lives. Training a model happens once, Inference happens billions of times a day every ChatGPT response, every Claude output, every agentic workflow running in the background and every one of those token streams is a billing event tied directly to memory performance. Adding more GPUs does not fix this because GPUs are already underutilized in inference because they are sitting idle waiting on memory. Adding more memory bandwidth and capacity is what directly reduces token cost, reduces latency, and allows the same cluster to serve dramatically more users simultaneously. Longer context windows compound the problem further, a model running a 1 million token context window requires dramatically more memory per session than a 10,000 token window, and every new model generation pushes context longer. The market treats memory as a downstream beneficiary of Nvidia orders. The correct framework is the opposite, Micron is the upstream constraint on how much value every Nvidia GPU can actually generate at inference scale. Micron guided Q4 to $50 billion in revenue, has HBM4 ramping at twice the pace of the prior generation, and CEO Sanjay Mehrotra has said supply will not catch demand before the end of 2027. At 8x forward earnings on $112 projected FY2027 EPS, Micron is the most undervalued infrastructure company in the entire AI stack. Inference is memory. Memory is Micron and the inference ramp has barely started. Milk Road Pro members are already up massively on this position and we're just getting started. If you want the full breakdown of what we're buying and why, come join us for just a dollar using the link below!

Milk Road AI

130,756 次观看 • 4 个月前

The creator of High Bandwidth Memory (HBM) put a number on the AI build that should stop every infra investor cold. A cluster of a million GPUs runs at roughly 10-20% utilization (Save this). Kim Jung-ho spent thirty years building what feeds the GPU, and his claim is that the GPU is barely working. Here is what is actually happening. Every time a model generates output, the data has to be read out of memory, computed, and written back. The read and the write swallow almost the entire cycle. While that data moves, the GPU does nothing. It sits there, fully powered, fully paid for, waiting. By Kim's estimate the memory is doing only about 30 percent of the work it needs to do. The processor idles the rest. So a million installed GPUs run at 10 to 20 percent. You are not compute constrained. You are memory constrained, and the expensive part is standing around. Adding more GPUs does not fix this. It gives you more processors starving for the same data. Here is the part that decides the next decade. Memory can grow. When a cell cannot shrink any further, you stack it into a high-rise, layer on layer. A GPU cannot be stacked. It runs too hot and needs a cooler bolted to its back, so the one move that rescues memory is closed to the processor. The thing that can keep stacking compounds. The thing that cannot plateaus. The marginal dollar in an AI build now buys more by fixing the memory path than by bolting on another idle GPU. Which is why the companies that control memory bandwidth and supply are not suppliers to the AI trade. They are the AI trade.

Fireside Alpha

38,370 次观看 • 4 个月前

Sapling is live. the final Zcash launchpad on Solana. STAMP proved Zcash can carry a record of a burn. you destroy a token, you get a receipt. we built what it could have been: you burn, you get paid, and then you get the receipt/stamp on Zcash mainnet. every coin planted on Sapling is a coin, paired with $ZEC instead of SOL. same curve, same graduation, same terminals. one difference: every coin has roots. the roots are a vault of ZEC under the coin. every trade feeds it: at least 0.50% of every trade, in ZEC. that floor is written into the program. burn the token on solana in one transaction. your share of the roots comes back in ZEC, in the same transaction. roots × your tokens ÷ supply. no claim, no wait. add a zcash address and a stamp lands on zcash mainnet, cut with exactly what you destroyed and exactly what the roots paid you. one-way, verifiable, and held by nobody but you. a stamp tells the world what you burned. Sapling pays you for it first. Zcash can't hold memecoins yet. it can hold proof. a stamp is a record, not a token. the first one is already on Zcash mainnet: certificate: on Zcash mainnet (transaction): 3edfa6cd1a8e3afbe7604e0c5f167c8b46d20ca1a7a6b56ec11a247fe78d7b04 the rest of the 2%: 0.80% to the deployer, almost 3x what pays. or hand it to your holders: ZEC pushed to every wallet holding $20+. permanent. 0.50% buys $SAPLING and burns it. every coin, every trade. 0.20% keeps the lights on. every fee, split, burn, harvest, payout and stamp sits on with its signature. the vault program went through a full security review before a single coin was planted. check it yourself: vault program (Solana): A9zFnNZpVjBbcE1SAPY92Z6H7WhicysLNPYPpDz15UxF rootstock (buys + burns $SAPLING): 3G6yQGLssh4VTNDaGpLn9CgARSZkXk2xRvfeu4f4SLA9 stamp issuer (Zcash): t1bBCoaVRECAc8Y8E5BRrhDPQ36nt27kX29 stamp rules + verifier: plant a coin. grow it in ZEC.

Sapling

29,776 次观看 • 1 个月前

researchers gave a tiny local model human-style memory and its context limit basically stopped existing a team from MBZUAI, Princeton and Weizmann took a 1B model and rebuilt how it reads. instead of attending to everything at once, the model reads in 1,024 token chunks and passes the important stuff forward through an associative memory, the same way you carry the plot of a book between chapters without rereading them. the design mirrors human memory on purpose. full attention inside a chunk works as short-term memory. the module that carries information between chunks works as long-term memory. they even trained it like a person, starting with short easy texts and raising the difficulty gradually, because memory thrown into the deep end learns nothing. the numbers back it up. the normal model burns 40GB of GPU memory on a long document and collapses hard past its limit, dropping from 0.86 to 0.32 accuracy. the memory version holds 0.71 at double that length while using a flat 12GB no matter how long the input gets. it also needs about 30% fewer FLOPs. the part i keep thinking about is that nobody scaled anything here. they didn't build a bigger model, didn't stretch the window, didn't add compute. they looked at how a brain handles a long day and copied the architecture. a model small enough to run on a consumer gpu now survives documents its own architecture used to choke on. we keep treating intelligence as a compute problem. sometimes it's a memory problem.

Alex Veremeyenko

16,147 次观看 • 3 个月前

this video is the CLEAREST explanation of how claude skills + AI agents work and how to use them most people set up an AI agent and wonder why it keeps disappointing them. the context window is everything context is what the model assembles before it takes any action. think of it like everything the agent needs to read before it does anything. the quality of what goes in determines the quality of what comes out. the models are genuinely really good right now. claude and gpt are exceptional. the variable is almost always the context you give them. 1. agent.md files are mostly unnecessary every single line you put in an agent.md file gets added to every single conversation you have with your agent. a 1000 line file is around 7000 tokens burning on every run. the model already knows to use react. it can read your codebase. save the agent.md for proprietary information specific to your company that the model genuinely cannot know on its own. 2. skills are the actual unlock a skill.md file works differently. what loads into context is only the name and description, around 50 tokens. the full instructions only appear when the agent recognizes it needs that skill. so instead of 7000 tokens on every run you have 50. and the agent stays sharp because the context window stays lean. the closer you get to filling the context window the worse the agent performs, same way you perform worse when someone dumps 10 things on you at once. 3. here is how to actually build a skill the right way most people identify a workflow and immediately try to write the skill. what you want to do instead is run the workflow by hand with the agent first. walk it through every single step. tell it what to check, what good looks like, what bad looks like. correct it in real time. once you have had a full successful run from start to finish, tell the agent to review everything it just did and write the skill itself. it writes a better skill than you will because it has the full context of what actually worked in practice not in theory. 4. recursively building skills is how you go from frustrated to reliable when the skill breaks, and it will break, ask the agent exactly why it failed. it will tell you specifically what went wrong. fix it together in that same conversation. then tell it to update the skill file so that failure mode never happens again. ross mike did this five times with his youtube report generator. it now pulls from eight different data sources and runs flawlessly every single time without him touching it. 5. sub agents are something you earn not something you set up on day one start with one agent. build one workflow. turn it into one skill. once that works add another. ross mike has five sub agents now covering marketing, business, personal and more. it took months to get there and every single one exists because a workflow proved it deserved to exist. the people who set up 15 sub agents on day one and wonder why nothing works skipped all the steps that make the thing actually run. 6. your workflow is the thing the model cannot get anywhere else the model has been trained on everything. it knows more than you about most things. what it does not have is your specific process, your taste, your way of doing things. that is what skills capture. that is what makes your agent actually useful versus a generic one. downloading someone else's skill means downloading their context onto your setup and it will not work the way you want it to because it was never built around how you work. this is the clearest explanation of how agents actually work i have heard. Micky runs this stuff every single day and the results show it. full episode is now live on The Startup Ideas Podcast (SIP) 🧃 where you get your pods people charge for this sorta stuff i give away the sauce for free i just want you to win watch

GREG ISENBERG

194,990 次观看 • 6 个月前

UC Berkeley just open-sourced FreeToken. (2–4x faster local LLM inference than Ollama) the results are wild: - Qwen3.6-35B on an 8GB GPU at 39.3 tokens/s - DeepSeek-V4-Flash 284B on a 32GB GPU at 22 tokens/s - GLM-5.2 753B on a 96GB GPU at 14.9 tokens/s a 35B model at 16-bit precision needs about 70GB just for its weights. even at 4 bits it is close to 18GB, and FreeToken serves it on an 8GB GPU. let me explain how: all three models mentioned above are Mixture-of-Experts, and that is what FreeToken takes advantage of. each layer holds hundreds of separate experts plus a small router that picks a few of them per token. Qwen3.6-35B activates roughly 3B of its 35B parameters per token. DeepSeek-V4-Flash picks 6 of 256 experts per layer, so 13B of its 284B run at a time. so compute was never the bottleneck. the weights a single step touches fit comfortably on a consumer GPU. every expert the router might pick still has to exist somewhere. they sit in system RAM, and the GPU keeps a cache of the ones the model has been using recently. so everything comes down to what happens when the router picks an expert that is not on the GPU. there are two ways to serve that miss: 1. copy it over PCIe and run it on the GPU 2. run it on the CPU, where it already lives both read from the same system memory, so they compete for one pool of bandwidth instead of adding to each other. existing engines pick one option and freeze it when the model loads. but routing changes on every token, so a fixed choice misses most of what the model asks for. FreeToken measures both bandwidths on your machine and splits each step's misses between the two paths in proportion. the GPU and CPU results then merge exactly, with no approximation. two machines with the same GPU can end up wanting opposite strategies, which I did not expect. a 5090 in a gaming desktop should push nearly everything over PCIe, while an 8GB laptop is better off computing most misses on the CPU. none of that is readable off a spec sheet, so the engine profiles it once per machine. the second half of the design is about agents. coding agents constantly rewrite their own history, and every edit normally forces thousands of tokens back through prefill. FreeToken saves its checkpoints at the exact boundaries agent frameworks cut on, so it only reprocesses the new part. its slowest first token stays under 44 seconds, while llama.cpp peaks at 232 and KTransformers at 946. it serves the OpenAI and Anthropic APIs under Apache 2.0, so Claude Code and Codex can point at it directly. releasing weights publicly decides who can download a model, not who can afford to run one. frontier open models keep shipping, and running them still assumes a rented cluster. meanwhile there are over a hundred million consumer machines with discrete GPUs sitting mostly idle. closing that gap was never a hardware problem, and work like this is what turns open weights into something you can actually use. paper: repo: almost every idea in this post, from why memory bandwidth decides the outcome to why moving weights costs more than computing on them, comes straight out of how a GPU is built. I wrote a detailed primer on that. the article is quoted below.

Akshay 🚀

345,385 次观看 • 2 个月前

your agent reviewing its own work is not a check. it is a second opinion from the same source. this is the most common gap in agent systems and it hides in plain sight, because the step exists. there is a review. it just cannot do the thing you think it does. here is the mechanism. the model produced an output from a context. you then ask the same model, holding the same context, whether that output is correct. it answers fluently, because that is what it does. and the answer is drawn from the same distribution that produced the thing being judged. same weights, same window, same blind spots. if the reason the output is wrong is something the model does not know, the review does not know it either. if the reason is something the context does not contain, the review has the same context. the failure mode and the detector share a cause. > why it feels like it works because most of the time the output is fine, and the review says fine. agreement is not evidence of detection. a reviewer that says pass on everything agrees with reality most of the time too. what you actually want to measure is what happens on the cases that are wrong. that is the only place a check earns its name, and it is exactly the place where a self-review is weakest. there is research on this. Huang and colleagues at DeepMind showed at ICLR 2024 that intrinsic self-correction, revising without external grounding, does not reliably help and often makes things worse. > what to actually do move the check outside the model. a test that runs, a schema that validates, a file that exists or does not, an exit code from something you did not write. these are not smarter than the model. they are just not correlated with it, and that is the entire value. when the judgement genuinely needs a model, at minimum use a different family. same family means shared blind spots, and frontier judges measurably inflate scores for outputs that look like their own. and split the work by kind. anything objectively checkable goes to code. only the genuinely semantic calls go to a judge, and those get a rubric written as one line. a review inside the loop tells you the model is confident. a check outside it tells you whether the work is done. save this - then read the eval setup below

Hanako

14,325 次观看 • 2 个月前

Agents vs. Graphs, clearly explained! spawning more agents is great, but it has a ceiling nobody says out loud: five agents is a count. a graph is a shape. only one of them changes the answer. point five agents at the same pile with the same window and they converge. the first one writes a finding, the rest read it, and all five reports centre on the same thing. you paid five times for one opinion with four echoes. Graph engineering fixes this by moving the decision up a layer: not how many agents, but who is allowed to look at what. you need both. here's how it works: ↳ the count buys you throughput. five things happening instead of one ↳ the shape buys you coverage. five different things happening instead of the same one five times Prompts → Context → Harness → Agents → Graphs the node that does this is the splitter, and it decides more than any other node in the system. cut a repository by folder and four workers audit the same three files. cut it by blast radius and each one sees something the others cannot. the trick is being selective about what each lane is allowed to see. separate contexts are not a nice-to-have, they are the mechanism. if two agents are meant to produce different things, they must not share a window. if they are meant to produce the same thing, you did not need two agents. one thing to know before you scale it. a branch that throws does not reject the batch. it resolves to null, and that is the containment. which means your merge quietly receives a short list. ↳ filter the nulls before the merge, or one dead lane poisons the whole result ↳ never index a merge by position. eight good branches and one failure will shift everything by one, silently skip that and the run looks like it worked. the output is just missing a lane, and nothing errored. and the one that eats whole nights: multi-agent setups can use up to fifteen times the total tokens of a single chat, because every lane reloads its own core. you are trading total tokens for a clean main window. usually the right trade, always a choice. below i have quoted my full guide on graph engineering. it covers the three topologies, the verifier patterns, and where the gate should actually open. save this and read it below ↓

Hanako

97,154 次观看 • 2 个月前

A tricky LLM interview question: You're serving a reasoning model on vLLM, and it keeps running out of GPU memory on long traces. So you add KV cache compression and evict 90% of the cached tokens. VRAM usage stays as is and GPU still runs out of memory. Why? (answer below) Evicting 90% of the KV cache can free almost none of the memory it was using. This sounds counterintuitive, but it follows directly from how production servers store the cache today. The KV cache grows with every token a model generates. Each token appends its key and value vectors across every layer, and nothing is freed while generation continues. This is the dominant memory cost for reasoning models. If a 32K-token CoT caches ~32K tokens of KV vectors, a Qwen3-32B with 4-bit weights will run out-of-memory around 24K tokens on a 24GB GPU. One obvious solution is to keep the important tokens and drop the rest, since attention is sparse enough to allow it. But this does not solve the memory problem yet. The reason is paged attention, which is the memory manager behind vLLM and most production servers. Under the hood, it splits GPU memory into fixed physical blocks, each one holds the KV for about 16 tokens. This block returns to the allocator only when every slot inside it is empty. Since the eviction logic selects tokens by importance, and such tokens are scattered across blocks... ...so despite eviction, almost every block is left with at least some survivor tokens. For instance, if the logic evicts 14k of 16k tokens across 1,000 blocks, most likely every block will still have a token. This means the allocator frees almost nothing. Placing the new tokens into those freed slots is not ideal because it breaks the cache's layout. Say token 16,001 arrives, and it's placed in the slot the 40th token used to hold. The cache now reads position 38, then 16,001, then 41, so the cache is no longer in token order. Attention can still compute the right answer from that, but only if every slot now carries a separate note recording which position it actually holds. This introduces another bookkeeping cost that an in-order layout inherently avoids. So the cache is logically 90% smaller and still physically the same size. Many compression results miss this because they measure on pre-allocated contiguous tensors rather than a paged server. There's another problem. Eviction methods pick which tokens to keep by looking at the attention scores themselves (as expected). But fast attention kernels used in production, like FlashAttention, never save those scores. They compute attention in small pieces and throw the full score grid away as they go, which is also why they're fast. So the exact signal eviction methods need isn't available in memory. The workaround is to fall back to eager attention and build the full matrix, which gives up the speed FlashAttention was there to provide. NVIDIA published a method called TriAttention to solve both these problems. It never needs attention scores. Instead, it scores tokens from the geometry of the model's key and query vectors before RoPE is applied, where those vectors sit in stable clusters. For the memory problem, it runs a compaction pass every 128 decoded tokens. The surviving tokens slide forward to close the holes eviction creates, so whole blocks empty out and return to the allocator while the cache stays in token order. On long reasoning traces, the approach matches full-attention accuracy while decoding 2.5x faster and using 10.7x less KV memory. KV cache compression is a big infrastructure problem. The number that decides whether it works is the count of freed blocks, not the count of evicted tokens. You can find the NVIDIA write-up here: I wrote a first-principles breakdown of how the KV cache works. It walks through why the model stores keys and values at all, why the cache grows with every token, and a comparison of LLM generation speed with and without KV caching. Read it below.

Avi Chawla

273,899 次观看 • 4 个月前

Engineer runs a Kimi K3 memory layer that costs $11 a month and remembers what a $500,000 vector database keeps losing. No embeddings. Four nodes and one rule about what's allowed to be forgotten. He published the whole schema. His version starts from the opposite idea. Memory is not a pile you search. It's a set of claims that expire unless something keeps paying to keep them. Four nodes. Every memory carries a clock someone has to reset: > WRITER - stores a fact with the reason it mattered, never raw text > DECAY - ages every memory down. Silence is deletion > RENEWER - only re-lifts a memory the model actually used again > GRAVE - holds what died, and why nobody reached for it Three nodes keep memory alive. One keeps the dead ones. Recall isn't storage here. It's rent a fact has to keep earning. That's the entire design. When everything is remembered forever, the useful and the stale retrieve identically. He replayed two months of agent context. 90,000 stored facts. 71,000 never retrieved once. The vector store returned all of them on similarity. Similarity graded closeness. Nobody graded whether the memory was ever right. Everyone else stuffs more into the context window and calls it memory. He built a layer that lets a fact die unless it keeps proving itself. The cost isn't storage. It's finding out how much of what your agent "knows" it has never once used. The article below is the full build - node prompts, the decay curve, the renewal rule. Save it. You'll want it open in the other tab.

wast3

67,778 次观看 • 2 个月前