Video wird geladen...

Video konnte nicht geladen werden

Zur Startseite

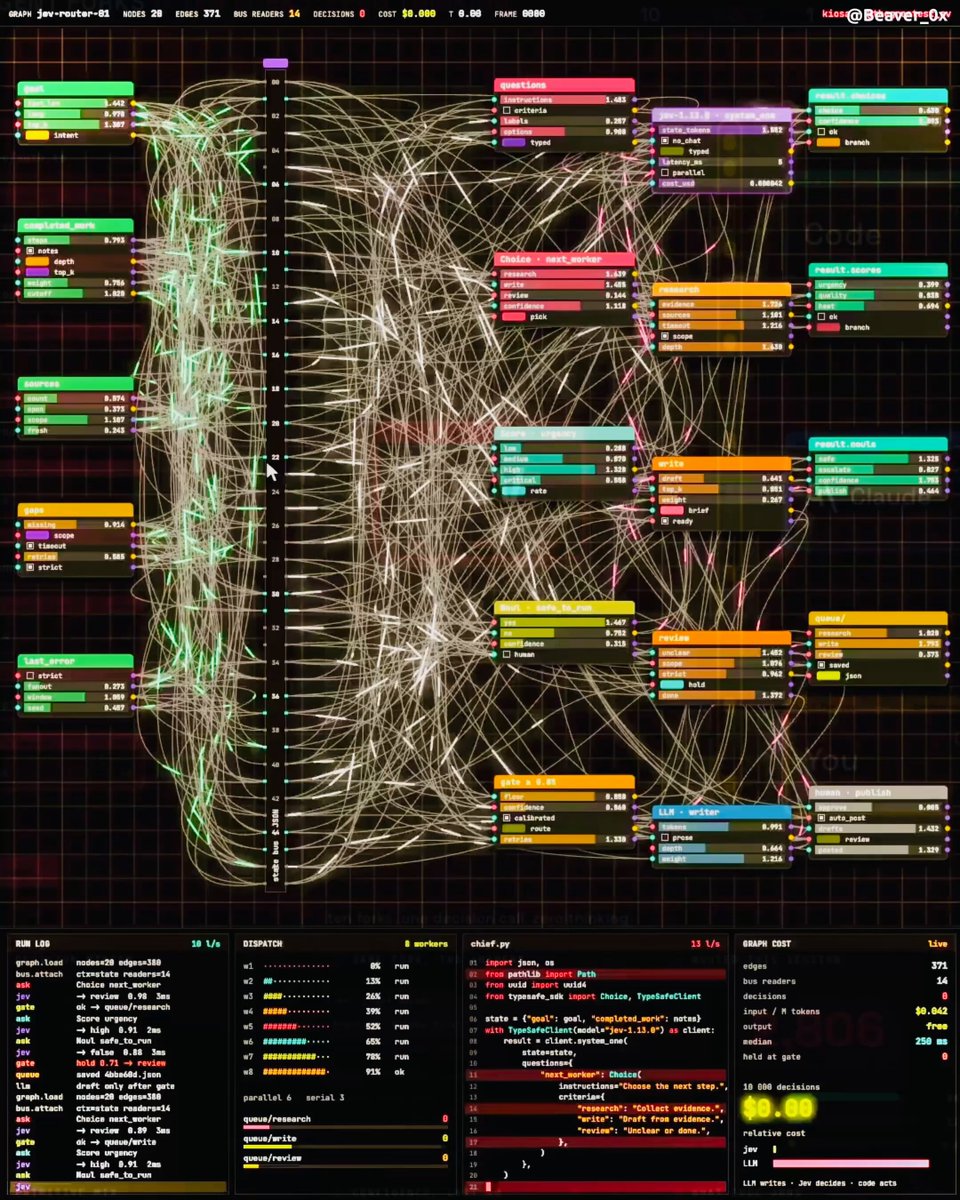
Anthropic turned one GitHub request into a living 3D model that answers every new issue with a rebuilt version of itself Opus 5.5 builds the whole system from that first request, from geometry and rig to the viewer and the pipeline behind it. > REQUEST - one issue describes...

16,350 Aufrufe • vor 23 Tagen •via X (Twitter)

18 Kommentare

Profilbild von Dekos
Dekosvor 23 Tagen

I wonder when the development of SHIT will stop.

Profilbild von Insomnia
Insomniavor 23 Tagen

bro I love to see it now

Profilbild von Danylo Fedorenko
Danylo Fedorenkovor 23 Tagen

this is such a cool idea. does it rebuild from scratch every time or just patch the old one?

Profilbild von 0xbobaa
0xbobaavor 23 Tagen

What kind of repository is this?

Profilbild von Zero
Zerovor 23 Tagen

damn, that’s insanely detailed!

Profilbild von shmidt
shmidtvor 23 Tagen

cool dot

Profilbild von beamnxw ./
beamnxw ./vor 23 Tagen

insane

Profilbild von Celebs Hub
Celebs Hubvor 23 Tagen

The idea that a 3D asset is dead until reopened in software is doing a lot of heavy lifting here; git already did this for code, you just pointed it at a mesh.

Profilbild von kemal buger
kemal bugervor 23 Tagen

Evren resmen davetiye göndermiş, FungoLabs daha neyi bekliyor?

Profilbild von magsimich
magsimichvor 23 Tagen

Wow this looks good to me

Profilbild von Biscuit
Biscuitvor 23 Tagen

client revisions would be so much easier

Profilbild von monokern
monokernvor 23 Tagen

new render in every pr is smart

Profilbild von Ridark
Ridarkvor 23 Tagen

You have a unique terminal with a really interesting approach for real for sure honestly for real, how did you build it out?

Profilbild von Antony Claude
Antony Claudevor 23 Tagen

this is pretty cool and very useful for 3d devs

Profilbild von kiosa
kiosavor 23 Tagen

Cool Fam

Profilbild von Lummox
Lummoxvor 23 Tagen

It’s really pretty

Profilbild von Gipp 🦅
Gipp 🦅vor 23 Tagen

plain text requests in opus 5.5 always flag my mesh changes cleaner than my old modeling workflow

Profilbild von Codio
Codiovor 23 Tagen

share that github repo with me via dm

Ähnliche Videos

Fusion Models by robinhood:0xa92768863a55d8a0591709f7f5e594a249d36ea3, explained properly. Why a panel beats one model: Ask three models the same hard question and they disagree. The disagreement is the information, where they contradict each other is where one of them is wrong, and a judge can see it. OpenRouter shipped exactly this in June and their panels beat any single frontier model. Credit to them and their $10B sale to stripe. Why the same panel for everyone is the wrong shape: You don't have one best model. You have a best model per job. The one you trust for code is not the one you trust for writing, and neither is the one you'd pick for a five-line reply. A panel chosen per request, identical for every user, can't know that. A panel arranged around you can. The number that matters isn't price: It's cost per answer that works. Model A costs $4 per million tokens and gets your job right one time in four. Model B costs $10 and gets it right three times in four. Per answer you actually keep, A costs $16 and B costs $13. The cheap model was the expensive one. Everyone comparing price lists is measuring the wrong thing. You never rate anything: Stopping an answer halfway is a rating. Regenerating is a rating. Switching model and asking again is the loudest rating there is. Every one of those already writes a row we can learn from. The router learns which models earn your credits, per job, and tries a cheaper one now and then to check. Fusion only when it pays: Cost mode tries the cheap model first and escalates only if a judge says it failed. Performance mode fans out to your panel and merges. Most simple prompts never fuse. That's why it costs less, not more. Put it together and you have a personal model: Not trained. Assembled. Your profile from a two-minute questionnaire and everything you've imported from Claude or ChatGPT. Your memory, shared across every model so switching never starts from zero. Your skills, workflows you build once and run on any model. Your scorecard, which models earn your credits per job. One per person. Nobody else has yours. Every model is someone else's; the arrangement is you, and it leaves with you. People aren't loyal to models. They're loyal to results. A moat can't be a commodity, but it can be our own creation.

askr

13,917 Aufrufe • vor 1 Monat

Production traffic is not uniform. You get a few requests that need your best model, but most are simple questions and lookups you can solve with cheaper, faster models. The most expensive mistake you can make today is sending every request to your strongest model. You need routing. Period. This is the simplest trick to improve the architecture of whatever you are building. Please, don't implement routing yourself. You don't have to. I'm currently working with TrueFoundry's Auto Routing. It reads each request, classifies it as simple, medium, or complex, and sends it to the model assigned to that tier. You have two choices: 1. Send every request to the free heuristic classifier to score signals such as technical vocabulary, code, prompt length, and multi-step reasoning. 2. Send the request to an LLM classifier when its difficulty requires a more nuanced judgment. The beauty of using routing is that nothing changes in your code. You still call a single endpoint model, but routing works behind the scenes to pair every request with the best possible model. TrueFoundry ran several experiments with two different setups: 1. Send every request to Claude Opus 2. Send every request to a router with Haiku, Sonnet, and Opus The first experiment ran 550 deterministically graded academic prompts through every setup. Auto Routing was 69% cheaper while retaining 98% of the baseline quality. The second experiment ran three production-shaped workloads through every setup, using user chats, developer chats, and long agent tasks. Auto Routing was 80% cheaper. Thanks to the TrueFoundry team for partnering with me on this post.

Santiago

15,543 Aufrufe • vor 1 Monat

A university lab had an LLM build 3D molecules and only kept the ones the model itself couldn't explain Most generative chemistry rewards confidence, which means the output is a very expensive average of the training set. They inverted the filter, the model builds the structure and then has to justify why it works, and the ones it can't justify are the only ones that go forward: > Generate: structures are built against the target property as usual > Explain: the model writes the mechanism it believes makes each one work > Score: a confident, familiar explanation sends the candidate to the discard pile > Keep: anything it builds but cannot account for goes to the bench • Why the unexplainable ones are the valuable ones > A structure the model can explain is one the literature already implies > Novelty lives exactly where the learned pattern stops predicting > The explanation is a proxy for how crowded that chemical space already is • What came out of the first run > Four scaffolds with no close analog in any published series > One binding mode the model described as unlikely and the assay confirmed > A discard pile full of compounds three other groups were already patenting • Where this breaks if you're careless > Unexplainable also describes garbage, so synthesis screening runs first > Every keeper has to survive the same physical validity checks > A candidate with no route to the bench is dropped regardless of novelty One generate-and-filter cycle produces about 30 keepers from 400,000 builds. And the part that broke my brain: Every other pipeline ranks candidates by how sure the model is about them. This lab reads that same confidence as proof somebody already got there. Same model. One version optimises for the middle of what's known. The hard part was never generating molecules. It was noticing that the confident ones are the crowded ones ↓

Codio

11,228 Aufrufe • vor 6 Tagen

Continuous batching in LLMs, clearly explained: (a popular LLM interview question; bookmark this) In traditional ML inference, a batch is a matrix. Every input is padded to the same length, one forward pass runs, and every row finishes at the same moment. LLM decoding does not work that way. One forward pass produces one token per sequence, so a request needs as many passes as it has output tokens, and nobody knows that count until the model emits a stop token. Under static batching, membership is fixed when the batch starts. A request that finishes in 30 tokens holds its slot until the slowest request in the same batch finishes at 400. The GPU keeps paying the full weight read for a batch that is mostly empty. Loading model weights out of HBM costs the same whether four slots are producing tokens or one. Continuous batching moves the decision boundary. Instead of scheduling once per batch, the scheduler runs a single forward pass, gets control back, and decides again. A finished request leaves at the next iteration boundary, and a queued request takes its slot right there. No slot stays reserved for work that is already done. Anyscale benchmarked both OPT-13B on a single A100. With uniform generation lengths, the two policies came out about level (as expected), and as output length variance rose, static batching fell to around 81 tokens per second while vLLM reached 23x the throughput of naive Hugging Face serving. Variance drives the entire gap. Production traffic mixes 30-token replies with 400-token ones, which is exactly the condition static batching handles worst. None of this alters the model. vLLM, SGLang, TGI, and TensorRT-LLM all run it by default, and NVIDIA ships the same mechanism under the name in-flight batching. The animation below runs both policies on the same 16 requests and the same 4 slots, stepping in lockstep. The only difference is when a new request is allowed in. To dive deeper into continuous batching specifically, I wrote a full breakdown of the scheduler underneath it. It covers what happens between two forward passes, how tokens get handed out against a fixed budget, why the scheduler needs no separate path for prefill and decode, and what preemption costs you when the KV cache fills up mid-generation. Read it below.

Avi Chawla

16,140 Aufrufe • vor 2 Monaten