Video yükleniyor...
Video Yüklenemedi
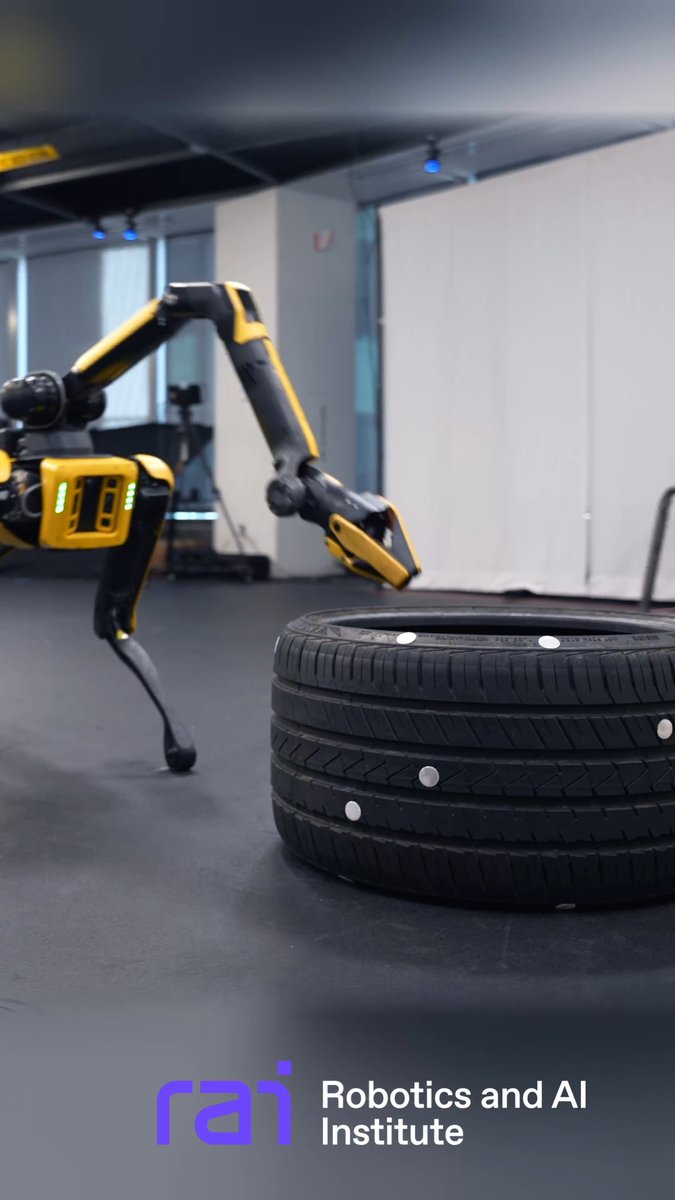
Can reinforcement learning replace traditional inverse kinematics for robot arms? PolicyIK takes an interesting approach. Instead of relying on numerical IK solvers and hand-tuned controllers, it trains a goal-conditioned RL policy to convert end-effector pose errors into joint-position updates. The team also trained the policy directly on a physical... show more
48,295 görüntüleme • 10 gün önce •via X (Twitter)
13 Yorum

PolicyIK: High-Precision Inverse Kinematics for Robot Arms with Reinforcement Learning Paper: Code:

polite way to say we finally stopped writing IK solvers
Pretty much 😀

For PolicyIK, I'd compare both approaches near joint limits and kinematic singularities under the same control budget. Alongside pose error, log settling time and joint reversals. Does the learned controller still hold position under a small disturbance?

Training an RL policy directly on hardware, interesting especially if it handles physical compliance and slack better than simulations.
Exactly, simulators rarely capture real-world slack and gravity sag accurately, so letting the policy adapt directly on the arm makes a huge difference for holding sub-millimeter precision.

This would work equally well for impedance control or other inverse dynamics setups too - neat - and i totally buy it.
Exactly. Glad it resonates nd love that it translates so easily to those setups.

This is the right way
Thanks Chris. Excited to see how far RL-based low-level control can push precision manipulation.

This is a shocker for an old robotic engineer like myself I studied IK more than 20 years ago and I always assumed it would have been impossible to replace. My doubt: what is precision recall e.g. unseen goal data does it still solve it ? What about sinularity avoidance ?
You can read the paper and code for more details

agreed with the conclusion. but the essentials are mixed with boring/unnecessary tricks. from my testing, double scale keypoint based reward + absolute joint action work well enough. deployment protocol looks soooo unnatural.