正在加载视频...
视频加载失败
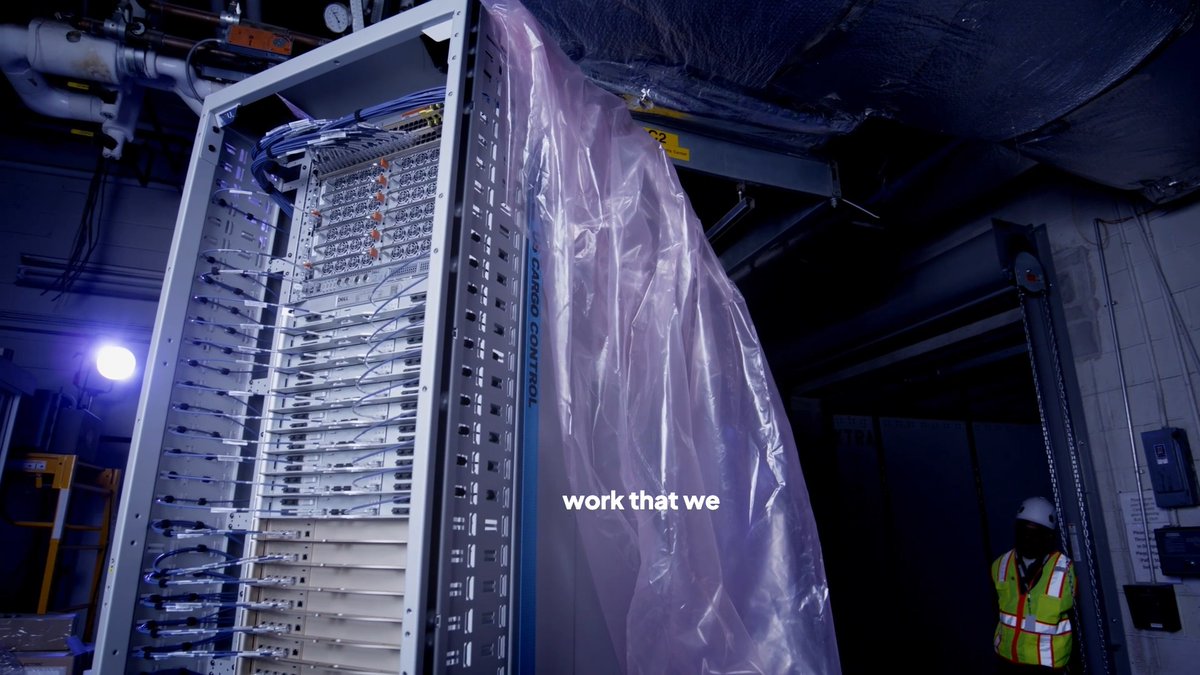
Cognition is the first customer running @NVIDIA Vera Rubin, powered by CoreWeave! Hopper in 2022. Blackwell in 2024. Now Vera Rubin: On SWE-2 inference, the new chips deliver about 4.8x more token throughput than GB200 at the same decode speed. More compute, better agents!

35 条评论

@nvidia @CoreWeave Hardware also matters!

@nvidia @CoreWeave more compute, better agents!

@nvidia @CoreWeave I'd say thanks for taking care of getting SWE-2 on this amazing hardware!

@nvidia @CoreWeave lfg

@nvidia @CoreWeave So that's why the speeds got faster today!

@nvidia @CoreWeave monumental

@nvidia @CoreWeave cognition is not going to slow down any sooner 🔥

@nvidia @CoreWeave Always stay shipping!

@nvidia @CoreWeave Accelerate!!!

@nvidia @CoreWeave 🔥🔥🔥

@dabit3 @nvidia @CoreWeave Love it! But music is too loud over his speech

@sandeepDshah @nvidia @CoreWeave ⚡️

@nvidia @CoreWeave LFG!

@nvidia @CoreWeave now that's banger

@nvidia @CoreWeave 4.8x the tokens per second so the agent can now be wrong at a much higher speed

@nvidia @CoreWeave Congrats! Been using Devin daily. Keep up the awesome work!

@nvidia @CoreWeave @KampnerSam

compute always wins

@nvidia @CoreWeave

@dabit3 @nvidia @CoreWeave crazy!!

@nvidia @CoreWeave So epic!

@nvidia @CoreWeave I bet you factory already running quantum computers. That's why y'all behind.

@nvidia @CoreWeave I really love when I see Cognition name under this kind of announcements.

@nvidia @CoreWeave this is gonna be an insane combo for agentic workloads

@nvidia @CoreWeave You also steal board members from competitors. Losers

@nvidia @CoreWeave 🥳🥳

@nvidia @CoreWeave swe 如果一直免费我将一直订阅

@nvidia @CoreWeave @NVIDIA Vera Rubin delivers 4.8x more tokens on SWE-2 than previous chips. It looks like Cognition and CoreWeave have built something fast for AI coding tasks.

@nvidia @CoreWeave Will the 4.8x throughput gain reduce queue times for Devin users during peak hours?

@nvidia @CoreWeave Love this take

@nvidia @CoreWeave 4.8x throughput boost is really impressive. This iteration will definitely push agent performance to a new level.

@nvidia @CoreWeave 4.8x on SWE-2 with same decode speed — that's the unlock for agentic workloads. inference bottlenecks become a thing of the past at this rate

@nvidia @CoreWeave LFG

@nvidia @CoreWeave So Jump Trading lied ?

@nvidia @CoreWeave How much of that throughput gain translates into a lower cost per completed task, once retries and tool calls are included?