Video yükleniyor...

Video Yüklenemedi

Ana Sayfaya Dön

DeepSeek-V4.1-Flash-1017 decodes code at 80.5 tok/s on one Mac Studio M5 Ultra 256 GB with BobClawblaw's recipe on TensorFold. Setup: – Recipe and TensorFold branch deepseek-v41-main (72a552ed), his own tool and settings – Context 524,288 tokens, 4 streams, DSpark drafts on, temperature 0 – Speed and quality with thinking...

11,028 görüntüleme • 4 gün önce •via X (Twitter)

16 Yorum

Ash Hart profil fotoğrafı
Ash Hart3 gün önce

Cheers for all the testing Niklas!

Niklas profil fotoğrafı
Niklas3 gün önce

🙏🏽

Dangwon profil fotoğrafı
Dangwon3 gün önce

@ksuniri What a great result! Thanks for sharing.

Martin Kessler profil fotoğrafı
Martin Kessler3 gün önce

There’s an upstream PR that almost doubles this.

Niklas profil fotoğrafı
Niklas3 gün önce

Very nice, thank you. I will have a look at it.

Marc Grau profil fotoğrafı
Marc Grau3 gün önce

@TechMDAI

Alizeh profil fotoğrafı
Alizeh3 gün önce

80 tok/s on mac studio crazy fast

try.works profil fotoğrafı
try.works3 gün önce

Those are actually really bad scores on mmlu pro and LCB. The API gets like 80+

杉山靖彦/AI&IT×税務会計×海外リモワ profil fotoğrafı
杉山靖彦/AI&IT×税務会計×海外リモワ3 gün önce

おお!Mac Studioが届くのが楽しみだ😊❗️

Gabriel Garrett profil fotoğrafı
Gabriel Garrett3 gün önce

Which quant level?

Jay profil fotoğrafı
Jay3 gün önce

How much mem does it use?

Laurent Marques profil fotoğrafı
Laurent Marques3 gün önce

what quant version 1, 4 bits ?

MrUniverse profil fotoğrafı
MrUniverse3 gün önce

@rez0__

Sean Cowan profil fotoğrafı
Sean Cowan3 gün önce

These evals and your site are such a great resource for the community! Any chance you'll be adding a few other tiers for Mac like 64/128 GB or a harness shootout?

汉卿 | hanqing profil fotoğrafı
汉卿 | hanqing3 gün önce

本地 80 tok/s,DeepSeek 在 Mac Studio 上跑得真快。

Elliot profil fotoğrafı
Elliot3 gün önce

What quant is this?

Benzer Videolar

Incredible! I have never seen a better music machine for my prompt, Opus and Sonnet included. 9/10. Turn your sound on. DeepSeek-V4.1-Flash-1017 built it on four DGX Sparks in 93.9 min, with Mia's TensorFold recipe. I checked it myself: this is not an Opus output. It ran on my own Sparks. Setup: – Recipe: Mia's, commit 6beaad9, with the 8 TF_DS_* switches her README table sets on; one model split across all four Sparks (TP4), 16 streams – Context: 1,048,576 tokens – Agent: DeepSeek Harness 0.2.1-rc.2, one prompt, one try, no help, thinking on – Sampling from the DeepSeek model card: temperature 1.0, top_p 1.0, top_k 20 – The sandbox had no internet; all 71 requests went to my local server Speed: – Decode, code: 69.5 tok/s (separate speed run, thinking off) – Decode, prose: 70.2 tok/s – 500 words: about 10.0 s – Eight requests at once: 139.0 tok/s in total The machine: – Built in 93.9 min, 272,026 tokens – Browser check: 9.0/10 – 18 voices, a wheel with 720 sockets, 6 marble types, 4 pieces – All sound is synthesized live in the browser, no samples – Sound on: the music in the video is what the page plays itself Good to know: – After 90 minutes the harness told the model to finish, and it was done at 93.9. – The browser check took 1 point off for the frame-rate test (under 3 fps, it renders in software). – The recipe's default answer budget is 32,768 tokens, the model card allows 262,144, so I raised the limit to that. – On her own README method my ring gets 119.9 tok/s on code, hers is 117.4. Her README lists 165.3 tok/s at eight requests (prose, thinking on, temperature 0.7); my speed test runs thinking off at the model card's sampling. – The ranking card at the end is the class ranking from my voxel-world test. Play the music machine in your browser, every number and the raw output: Mia's recipe and the exact setup: Recipe by Mia. TensorFold engine by Ash Hart. Model by DeepSeek.

Niklas

23,772 görüntüleme • 3 gün önce

GLM-5.3-Flash on two DGX Sparks built this voxel sky kingdom in 71.1 min, on Mia's recipe and the TensorFold Python engine. Mia's recipe at commit 3fd60dfc: EXL3 4 bpw quant, one model split across both Sparks (TP2), DFlash2 draft model, 8 slots (her recipe allows up to 8; the default on two Sparks is 4). Agent: OpenCode 1.19.3. One prompt, one try, no help. Thinking on, sampling from the model card: temperature 1.0, top_p 0.95. Voxel world: done in 71.1 min Tokens written: 109,305 Browser check: 9/10 Decode, code: 51.2 tok/s (separate speed run, thinking off) Decode, prose: 48.6 tok/s 500 words: about 14.0 s Eight requests at once: 99.2 tok/s in total Context: 1,048,576 tokens, the recipe's setting Aetherfall: floating isles over a cloud sea with a sky whale and its calf, a waterfall, a windmill, a castle, a shrine, airships and its own camera tour. Open: parts of the world are cut off hard at the edges, most likely a bug in the generated code. Answer limit in the build test: 65,536 tokens, the figure names for its Terminal-Bench runs. Its model card names up to 163,840 for another test. The longest answer was 54,782 tokens, so none was cut. Before this I ran the same task on Mia's Zig-engine branch, which her docs call work in progress: Decode, code: 26.6 tok/s Decode, prose: 25.5 tok/s Voxel world: done in 98.8 min Browser check: 8.0/10 The Python engine is the one her main recipe runs. Play the world in your browser. Every number, the exact command and the raw output: Recipe and quant by Mia. TensorFold engine by Ash Hart. GLM-5.3-Flash by Z.ai. DFlash2 draft by Inco AI.

Niklas

16,730 görüntüleme • 5 gün önce

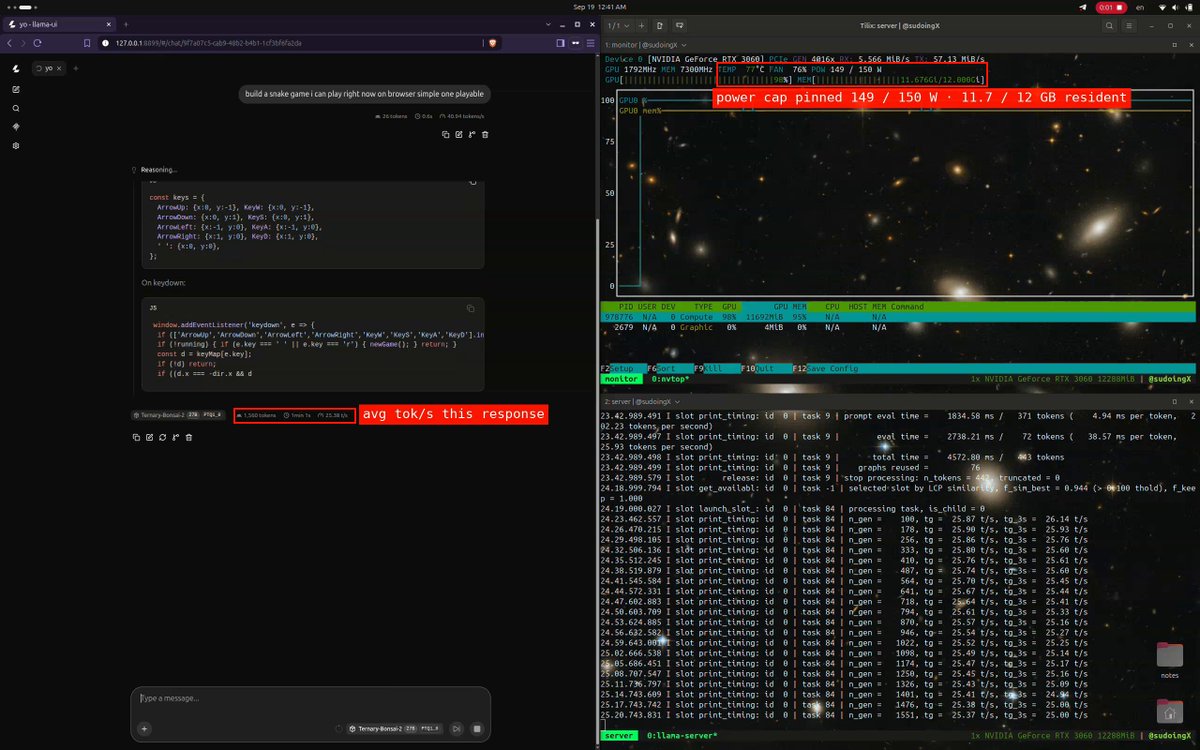
bonsai 2 27b on an rtx 3060 12gb, the full receipt sheet. save this one, the 12gb row of the small gpu guide is built from it. speed by depth, then what context costs, live server, thinking on, real sessions > 7k deep: 24.4 tok/s > 12k deep: 21.9 tok/s > 35k deep: 17.8 tok/s > 77k deep: 13.0 tok/s > 64k window: 7.3gb resident > 128k window: 8.8gb resident > 192k window: 10.2gb resident > 262k window: 11.7gb resident, 0.6gb to spare, the whole native window on a 12gb card > every 64k of context costs 1.47gb, so 327k would not fit > a 41,312 token build session from 35k to 77k of context averaged 15.0 tok/s across 46 minutes > prefill 295 tok/s at 2k of context, 243 tok/s at 35k, first token in 0.6 seconds, fresh decode 26.1 tok/s > the card pinned 149 of 150 w the entire time, 78c, fan at 80%, power bound, not heat bound > 0.158 tok/s per watt at the fresh end the setup > model: ternary bonsai 2 27b, PTQ1_0, 1.75 bits per weight, 5.95gb on disk, base qwen 3.8 27b, apache 2.0 > runtime: prismml llama.cpp fork, prebuilt cuda 12.4 binary, no compile > serve: full 262k native window resident, q4 kv cache, flash attention, one slot, 11.7 of 12gb in use for anyone who followed bonsai 1 in july, that was the 3.9gb 1bit file at 42 tok/s on a 3060 ti, a faster card and a smaller file, so the same card comparison is not on the table yet, it comes with the 8gb test. what changed is the base, qwen 3.8 instead of 3.6, and the retention, 98.2% on their suite instead of 95%, and the whole 262k window fitting on 12gb.

Sudo su

31,578 görüntüleme • 1 ay önce