Loading video...
Video Failed to Load
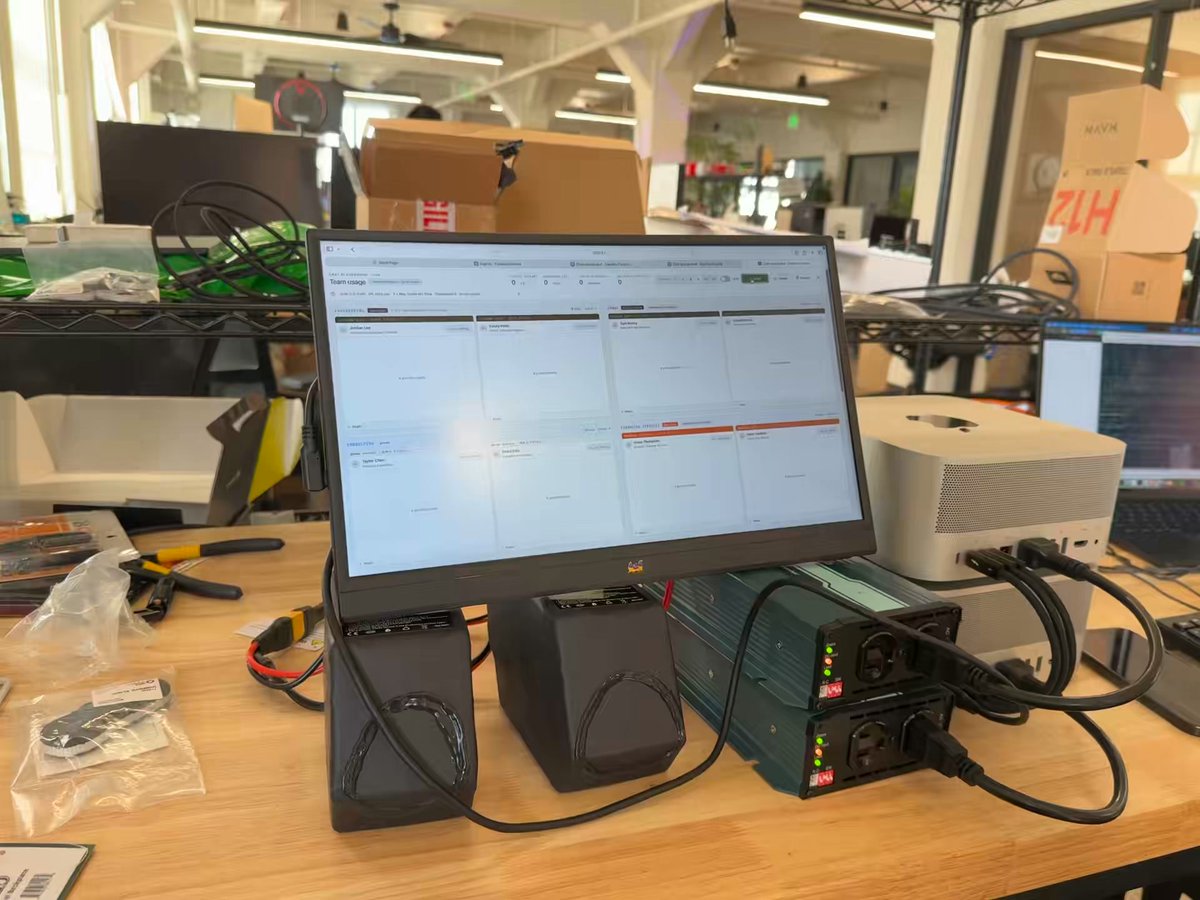
GLM-5.2 Nvidia NVFP4 No pruning, no quantising, exact same model card. 110 tok/s single stream. My friend is a genius, holy fudge. Here's the repo, he got full DS4-Flash on a 5090 + DDR5 at 38.5 tok/s This is a breakthrough.
158,188 views • 4 months ago •via X (Twitter)
45 Comments

This will work on 2x 6000s and 256gb of ddr4/ddr5
Dies of excitement overload. No more excessive compression, truly a work of art. Genius.
well quantised during runtime with hot expert recovery it's a bit hard to explain.

Nice... I have 2x5090s to try this on! 32 tk/s on a single 5090 is better than I get currently on 6 3090's with DS4 Flash Q4
A bit of tinkering but any of the top 10 models can get it working in no time

I need to try this wow

Does glm 5.2 run on a single spark now?
Not yet.

Did you get GLM 5.2 NVFP4 working?
This engine works with the NVFP4 it does some dynamic compression which is a bit new and under tested the 3.25 bit one Hybrid is battle test and holds up really well. I recommend the MXFP8-NVFP4-FP3 Hybrid first Scores 88.8 on GPQA Diamond and in 91% on aider polyglot
what would be the better choice for 8xpro6000?

110 tok/s on a 5090 is wild. It's like finding out your old Honda Civic can suddenly hit 300km/h because someone rewritten the fuel injection logic.

wtf
bro have you seen ffmpeg, we're not even close to cracking inference.

Wow 🤯 will this work on a DGX Spark?

What

wait, you are confusing me, where does glm 5.2 come into play here?

well thank you for that blackwell ISA

This one looks interesting too

Wow 😮

Isn't this a repo for deep seek?

Madness

looks like this is a DeepSeep-v4-Flash 2‑bit MoE quant, no?

How much ram, I've got a 5090 & 192gb ram

Can you check this out and let me know what you think

OOHHH i get it - took me a second. Your friend made a fork of vllm and runs both GLM-5.2 and ds4-flash fast. Dual 6k pros here, but on PCIE 3.0, I can dial either 512gb ddr4 ram or 192gb ddr4 ram in this system. I'm leaning towards running ds4-flash. what yould you suggest?

Whaaaat theeeee flipping flop?!??!!?! 🔥🔥🔥🔥

So this should also be possible on the larger memory Mac Studio M3 Ultras with MLX? alot slower I'd expect.

I am so confused by this. Now do I install this or wait 24 hours for the one that fits on a 1080Ti?

Woah

There is a bug in the author’s repo: their dspark patch file accidentally includes diffs for __pycache__/*.pyc files — compiled Python bytecode that Python regenerates automatically. git apply can’t process those binary entries and aborts, even though every real code change in the patch applies cleanly. I fixed it with a one-line edit to the Dockerfile — git apply --exclude='*/__pycache__/*' — which skips the junk entries and loses nothing.

This says DeepSeek‑V4‑Flash on Blackwell (SM120)
it works for any moe
Cool thanks I’m spinning up a test pod now

Is there a link to the glm model? Is the one by destroyed in the discord?
That’s the trick, it works with any GLM-5.2 I am using the Nvidia one

I’m running three 6000 workstation at 288 vram and 256 ddr5 what would the setup look like?
Check and see
Ok I checked it out, will it work on tp=3?

Hey, we've got a commercial hardware project from China and we'd love to collaborate with you on it. Would you be interested?

I read through that link holy fuck

Holy shit this is incredible quantization and engineering 🤯

@grok what app is this local inference running in ?
Will GLM-5.2 Nvidia NVFP4 run on dual Spark DGX?

this is straight up pure MoE degeneracy and I love it