Loading video...
Video Failed to Load
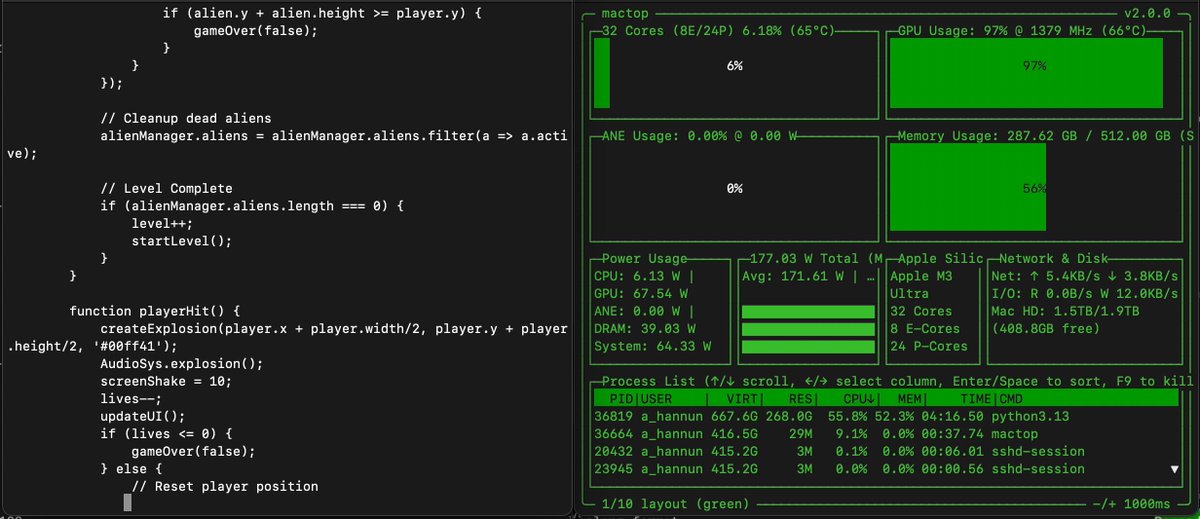
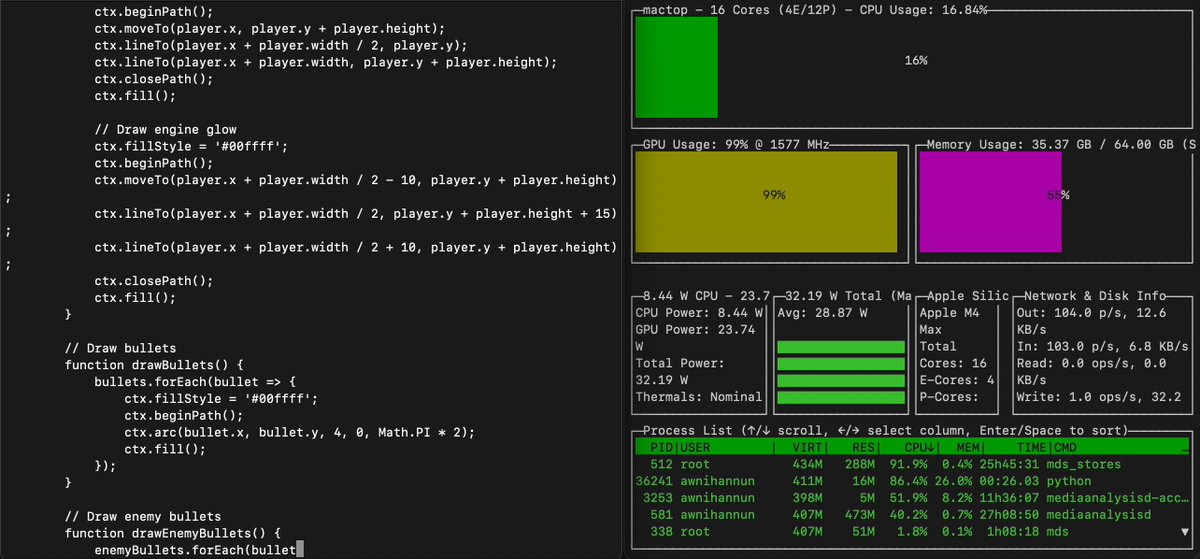
GLM 4.7 Flash is supported in mlx-lm 0.30.3 (h/t Ivan Fioravanti) The 4-bit runs fast (43 tok/s generation, ~800 tok/s prefill) on a base M5 32GB laptop.
141,299 views • 9 months ago •via X (Twitter)
22 Comments

@ivanfioravanti I suddenly have a lot of trouble to find room on my disk for all the shiny new things 😅

@ivanfioravanti ANE on GPU on m5 still does nothing. Is it just a waste of silicon? Thanks for the test

@ivanfioravanti If it's good at the tool call, it will be a beast for the local agent.

@ivanfioravanti 800 tok/s prefill is wild. does it handle long context well or does it start to choke past 8k tokens?

@ivanfioravanti As a Hugging Face Partner Provider, @novita_labs has already deployed GLM-4.7-Flash, available pay-as-you-go with no monthly subscription required, making it easy for developers to test, build, and scale instantly.

@ivanfioravanti That’s awesome

@ivanfioravanti Getting 55 tokens/second on my M4 Pro 24GB, not much room for context, though. Wishing I had opted for the 36 GB of RAM version...

@ivanfioravanti Wow nice

@ivanfioravanti @grok how much you estimate on a 4090 ?

@ivanfioravanti Use btop

@ivanfioravanti Ang hope for 1.58b? 16gb M4 mini.

@ivanfioravanti What do they compare it to gpt-oss-20b instead of gpt-oss-120b?

@ivanfioravanti Can you tell us about the set context size? 800tok/s sounds like a dream, I just wonder if it is at an usable context size

@ivanfioravanti On a dedicated server would be much faster 😇

@ivanfioravanti I got ~50 TPS with reasoning off. ~33 TPS reasoning on.

@ivanfioravanti Nice

@ivanfioravanti Will this work max mini then?

@ivanfioravanti that's pretty impressive for a base M5 laptop. 43 tok/s for generation is no joke. can't wait to see what people do with this!

@ivanfioravanti Whats the time to first token?

@ivanfioravanti thanks for this! do you think it’s useable on a m5 24gb ?

@ivanfioravanti those prefill numbers on m5 are surprisingly strong

@ivanfioravanti rtx 5060ti ,16 gb vram, offload (10 layers gpu) q4 gguf , 25 tks prompt, 8tks