正在加载视频...

视频加载失败

gpu kernels on on my computer writing other gpu kernels for the same chip to simulate 100ks of particles, each an agent + neural network sensing K bg fields and allocating energy to A actions, at 1000s steps/s, for thermodynamic artificial life i think maybe not a bubble lads
32,653 次观看 • 3 个月前 •via X (Twitter)

0 条评论

暂无评论

原始帖子的评论将显示在这里
相关视频

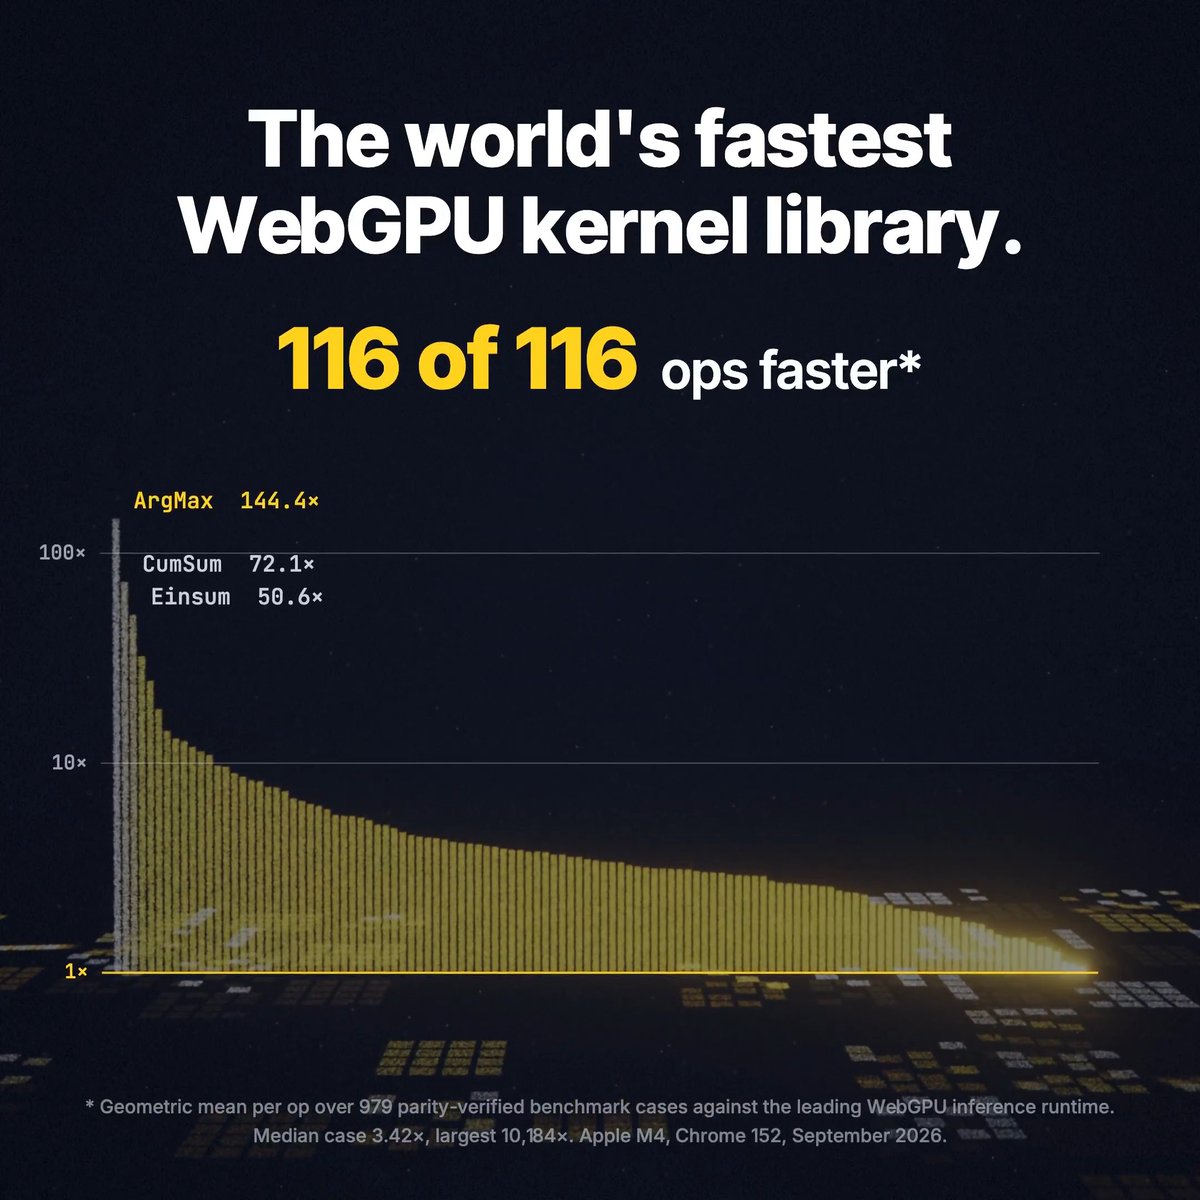
Big win for local LLM inference! This open-source engine generates tokens 2.7x faster than Ollama on a MacBook: I tested it on a base M5 MacBook Pro with Qwen3.5 4B at 4-bit and the same 9.2k-token prompt. Ollama ran its MTP build, so both had speculative decoding. - Prefill: Ollama 464 tok/s, Magnitude 755 tok/s (1.6x) - Decode: Ollama 22.6 tok/s, Magnitude 60.0 tok/s (2.7x) - End to end, Magnitude finished in half the time The video below shows both runs side by side. The Ollama numbers don’t mean it’s badly built. Its kernels were simply tuned in advance. A kernel is the small GPU program behind every matrix multiply and attention step. Its speed depends on choices like how work is split across GPU cores and how data moves through memory. The best choices change with every chip. Apple Silicon alone spans 8 to 80 GPU cores and under 70 to over 800 GB/s of bandwidth, and every model has its own layer sizes. A prebuilt engine has to pick one set of settings for all of them, so most local setups run on a compromise. Magnitude replaces that compromise with tuning on your machine: ↳ When you download a model, it compiles that model’s kernels locally. ↳ It tries different kernel configurations and keeps whichever runs fastest on your chip. ↳ It pairs each model with the fastest speculative decoding drafter it has found, so each pass of the model produces more than one token. GitHub repo: (don’t forget to star it 🌟) This matters most for agents. Every file and tool output has to be processed before the model writes anything, and that prefill step is where kernel efficiency shows up. Concurrent sessions also share prefix caches, so parallel agents don’t slow each other down. Magnitude is an open-source (Apache 2.0) inference engine written in Rust. It plugs into Claude Code, Codex, OpenCode, Pi and other agents with one click. I shared the GitHub repo above.

Akshay 🚀

34,322 次观看 • 1 天前