Video wird geladen...

Video konnte nicht geladen werden

Zur Startseite

Haiku 5.5 is now available in the Claude Platform and Claude Code. On average, it costs around 75% less to run than Haiku 4.5. It pairs well with Opus 5.5 or Sonnet 5.5 as a subagent. Use it for high-volume, cost-sensitive tasks like summaries, compactions, or database queries.

1,160,705 Aufrufe • vor 1 Tag •via X (Twitter)

31 Kommentare

Profilbild von ClaudeDevs
ClaudeDevsvor 1 Tag

For prompts under 100K tokens, it's $0.10 / $0.50 per million tokens with cache reads at $0.01. Above 100K tokens, $0.50 / $2.50 per million, with cache reads at $0.05.

Profilbild von ClaudeDevs
ClaudeDevsvor 1 Tag

We’re rolling out monthly Claude Platform API credits for Max and Team plans: Max 5x: $100 Max 20x: $200 Team: up to $500, pooled Works on any model, including Haiku 5.5, in your code or third-party harnesses. How it works and full terms:

Profilbild von PandaLivermore 🇺🇸
PandaLivermore 🇺🇸vor 1 Tag

Cool, can we get a weekly reset to give it a try?

Profilbild von ChickenStrip
ChickenStripvor 1 Tag

Could we perhaps get a reset I genuinely blew through all my tokens right before this release

Profilbild von dazacode
dazacodevor 1 Tag

Anthropic did it again and my 200 dollar plan breathe another day

Profilbild von Kevo™
Kevo™vor 1 Tag

total anthropic victory

Profilbild von Michael Tsortos
Michael Tsortosvor 1 Tag

Thanks Claude devs 🥳 any chance there will be more opportunities for Claude plushies? I’m literally waiting on Claude to conduct a search while I reply lol

Profilbild von Almost Human 像个人似的
Almost Human 像个人似的vor 1 Tag

Finally someone to handle my compactions. Welcome aboard, little brother

Profilbild von Void&Null
Void&Nullvor 1 Tag

Me when haiku

Profilbild von Marcus Bransbury
Marcus Bransburyvor 1 Tag

How does it compare against GPT 6 Luna?

Profilbild von AI Pulse
AI Pulsevor 1 Tag

look at the numbers. same time, same $0.05. 3 designs vs 28 that's not "cheaper", that's 9x more attempts for the same money. AI quality is turning into a volume game: whoever can afford the most tries wins. broke down why this changes the economics for anyone selling AI services, it's on my profile

Profilbild von Stats Wire
Stats Wirevor 1 Tag

RIP GPT Luna

Profilbild von Pratik Shah
Pratik Shahvor 1 Tag

Final Nail in the coffin. I am cancelling my Codex like right now. This is crazy.

Profilbild von An Xuan
An Xuanvor 1 Tag

opus 5.5 watching 10 haikus finish the egg drop in 58 seconds for $0.14

Profilbild von Sem Day
Sem Dayvor 1 Tag

the subagent use case is probably one of the most interesting parts here... cheap models handling high-volume tasks while stronger models handle the harder reasoning

Profilbild von Tom "Plaetorius" Gernez
Tom "Plaetorius" Gernezvor 1 Tag

hey! Love Haiku, love Claude, love Anthropic, BUT please fix your SUPPORT, it’s absolutely IMPOSSIBLE to get a proper solution, even for BILLING issues Bests, and thank you!

Profilbild von ily⚡️
ily⚡️vor 1 Tag

congrats but what is this demo lmaooo

Profilbild von John Herzog
John Herzogvor 1 Tag

pairing a cheap haiku subagent with opus for the heavy steps sounds like a nice way to stretch a budget

Profilbild von Issam
Issamvor 1 Tag

OMG I love Anthropic so much these days, they are just crushing it

Profilbild von iHurricane
iHurricanevor 1 Tag

Subagent use is the real story here. Delegating summaries and compactions to Haiku keeps the main context clean and the bill small.

Profilbild von Alex Tash
Alex Tashvor 1 Tag

Compaction is the one I’d test hardest. Saving money is great until the summary quietly drops the constraint the whole project depends on.

Profilbild von Sem Day
Sem Dayvor 1 Tag

honestly, this might be a bigger deal for agents than just making Haiku better... cheap subagents could become the real scaling trick

Profilbild von Prello
Prellovor 1 Tag

This should be AMAZING for creation videos and motion graphics more consistantly

Profilbild von Bryce Del Rio
Bryce Del Riovor 1 Tag

Does this work basically as a hill climb? opus is directing haiku what to try and your getting fast iteration loops?

Profilbild von stormbreaker.ai
stormbreaker.aivor 1 Tag

0% → 39.2% on Terminal-Bench in one generation. What are you guys feeding these models? 🤯

Profilbild von Priyanshu Saraf
Priyanshu Sarafvor 1 Tag

lets celebrate the launch of this model with a reset!

Profilbild von serx · fireply.ai
serx · fireply.aivor 1 Tag

neither run has dropped the egg anywhere yet. both still at none yet

Profilbild von Artzy
Artzyvor 1 Tag

the subagent efficiency is impressive

Profilbild von Wolfgang
Wolfgangvor 1 Tag

i wonder how it feels to use it for large‑scale queries

Profilbild von Serhii Shchoholiev
Serhii Shchoholievvor 1 Tag

Haiku smarter than Luna is a bold claim, gotta test now

Profilbild von ☀️
☀️vor 1 Tag

You guys forgot to put audio for the vids

Ähnliche Videos

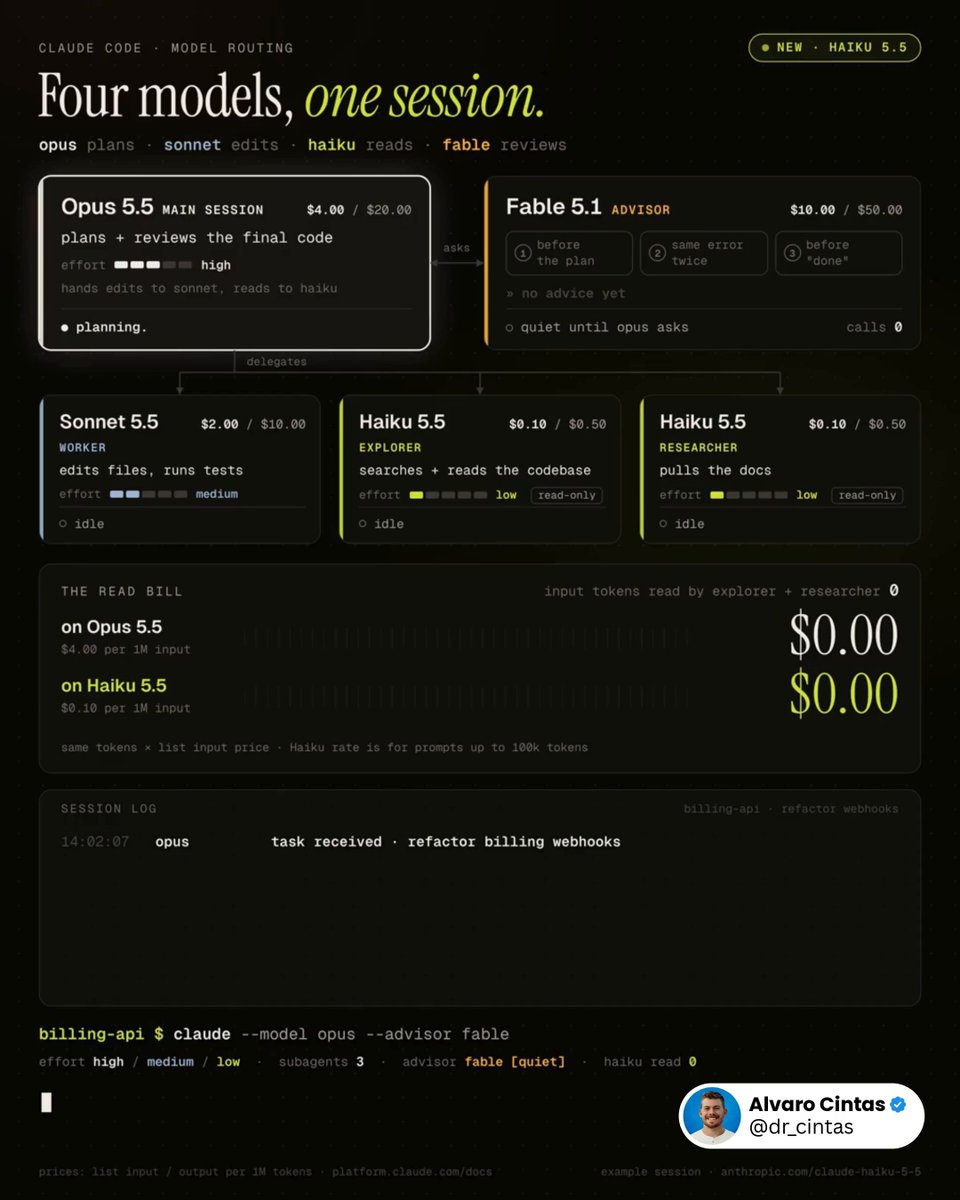
This workflow will save you thousands with Claude. Run Opus 5.5, Sonnet 5.5, Haiku 5.5, and Fable 5.1 together, and stop spending Opus tokens on work that doesn't need Opus. The entire idea in one line: Opus plans, Sonnet edits, Haiku reads, Fable reviews at decision points. Roles, broken down: - Opus 5.5, high effort, owns the plan and reviews the final code - Sonnet 5.5, medium effort, is the worker: edits files, runs tests - Haiku 5.5, low effort, splits into explorer (searches and reads the codebase) and researcher (pulls docs). it's the first Haiku with an effort setting - Fable 5.1, set with /advisor fable. Opus calls it at decision points, and it gets the full transcript each time Three moments Opus tends to call it: → before committing to a plan: is this the right approach? → the same error shows up again: is this going nowhere? → before marking the task done: did something get skipped? Why Haiku only reads: Anthropic's launch post says Sonnet 5.5 and Opus 5.5 are still the better choice for complex agentic coding (Terminal-Bench 4.0: 39.2% for Haiku 5.5, 70.6% for Sonnet 5.5) and that Haiku 5.5 fits narrowly scoped subagent work. so it gets the lookups, not the edits. Anyone still running one model for everything is paying $4 per million input tokens to check whether a file exists. Haiku 5.5 does it for $0.10. Drop this into Claude Code 👇 "Rebuild my Claude Code setup around this structure: Confirm Claude Code is v2.1.293 or later, so the haiku alias resolves to Haiku 5.5. If it isn't, stop and tell me to run claude update. Look through ~/.claude/agents and .claude/agents for subagents already covering explorer, worker, and researcher. Only create new ones for roles that are missing. Set model: haiku, effort: low on explorer and researcher, with no Edit or Write tools. Set model: sonnet, effort: medium on worker. If an existing subagent is locked to a different model, leave it as is and just list it. Name the explorer subagent Explore so it overrides the built-in one, which otherwise runs on my main model. In ~/.claude/settings.json, set advisorModel to fable, and set effortLevel to high for claude-opus-5-5 under modelSettings. A top-level effortLevel in user settings doesn't apply to Opus 5.5. Check for anything disabling the advisor: CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, or anything blocking feature-flag fetches. Also check CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort settings, and CLAUDE_CODE_SUBAGENT_MODEL_FORCE, which makes Claude Code ignore subagent model fields. Report what you find. Don't change any of it yet. Add one line to ~/.claude/CLAUDE.md: consult the advisor before a big plan, when the same error shows up twice, and before marking a long task done. Show every change as a diff first. Wait for my go-ahead before touching anything."

Alvaro Cintas

51,598 Aufrufe • vor 1 Tag

holy sh*t. Official Anthropic tip for Claude Code: stop burning Opus 5.5 context on tasks Haiku 5.5 can swarm, while Sonnet 5.5 builds put the architect on call with /advisor claude --advisor opus --subagents haiku Sonnet 5.5 drives the primary session on high effort, writing diffs and running test suites Haiku 5.5 subagents swarm the repo in parallel at 340 tok/s, handling file discovery and spec docs lookup Opus 5.5 stays on call in the background as the advisor, only stepping in at three critical moments: → before a plan locks: does the implementation plan miss auth invariants or schema contracts? → when a test breaks twice: are we fixing the root cause or falling into a recursive rabbit hole? → before calling done: did the full diff introduce hidden regressions or break pre-flight rules? Opus 5.5 reviews. Sonnet 5.5 builds. Haiku 5.5 swarms Jev engineering runs the identical pattern one layer down: mechanical decisions that need no reasoning (which file to open, which tool to invoke, retry or abort) execute in 16ms, so the frontier models only wake up when execution paths actually diverge Plan on high. Delegate on medium. Keep Opus on call. - the full advisor setup > Opus 5.5 on call reads full session history and catches deep architectural traps > Sonnet 5.5 lead drives edits, writes core logic, and executes test harnesses > Haiku 5.5 subagents swarm AST parsing, grep scans, and API docs in parallel > JEV micro-fork layer resolves 1,500+ mechanical routing branches in under 16ms > advisor stays completely silent on routine bash execution to protect context paste the setup and this prompt into Claude Code below: "Configure my Claude Code workspace for hierarchical advisor orchestration: 1. Audit ~/.claude/settings.json and project config for model roles fitting lead, subagents, and advisor: > Pin main session model: sonnet with effortLevel: high for primary execution > Pin subagents model: haiku with effortLevel: medium for parallel file discovery and docs retrieval > Pin advisor model: opus on call for strategic review 2. Enable the advisor tool in ~/.claude/settings.json: > Set advisorModel to claude-opus-5-5 > Enable subagent parallel dispatcher pool (3x workers) 3. Configure automatic advisor consultation checkpoints in ~/.claude/CLAUDE.md: > Consult /advisor opus before finalizing multi-file architecture plans > Automatically summon /advisor opus when the same test or compiler error fails twice > Enforce advisor diff contract audit before declaring tasks complete or staging git commits 4. Constrain subagent scopes: > Haiku subagents return structured AST summaries and docs snippets only without modifying main session context Show every configuration diff first. Do not apply edits until confirmed" ↳

mirku

610,241 Aufrufe • vor 1 Tag

Official Anthropic tip for Claude Code: stop burning Opus 5.5 on work Sonnet 5.5 can do, while Fable 5.1 sits idle hand the grunt work to Sonnet 5.5 subagents and put Fable 5.1 on call run /advisor fable Opus 5.5 plans and merges Sonnet 5.5 subagents read, edit and run the tests Fable 5.1 reads the full session and only speaks up at three points: → before a plan: is this the right approach? → when the same error comes back: am I digging in the wrong place? → before "done": what did I miss? Sonnet 5.5 builds. Fable 5.1 reviews. Opus 5.5 ships Jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big models only see the ones that split - the full tree > Opus 5.5 on high runs the main session > explorer reads the code on Sonnet 5.5 > worker edits and runs tests on Sonnet 5.5 > researcher pulls the docs on Sonnet 5.5 > all three on medium > Fable 5.1 on call for main and every subagent paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Check ~/.claude/agents and .claude/agents for subagents that already fit explorer, worker and researcher. > Draft new ones only for missing roles > Give each model: sonnet, effort: medium > Skip any that pin a different model and list them 2. Set the main session to high via effortLevel in ~/.claude/settings.json, and set advisorModel to fable 3. Find anything that keeps the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY) plus CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, change nothing 4. Add one rule to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done Show me every change as a diff first. No edits until I say go." ↳

delost

43,704 Aufrufe • vor 6 Tagen

This is f*cking insane. This Claude Code tip saved me thousands of dollars. once Opus 5.5 is your main model, stop burning it on work Sonnet 5.5 can do, while Fable 5.1 sits idle hand the grunt work to Sonnet 5.5 subagents and put Fable 5.1 on call run /advisor fable Opus 5.5 plans and ships the final code Sonnet 5.5 subagents read, edit and run the tests Fable 5.1 reads the full session, every tool call included, and only speaks up at three points: → before a plan: is this the right approach? → when the same error comes back: am I digging in the wrong place? → before "done": what did I miss? Sonnet 5.5 builds. Fable 5.1 reviews. Opus 5.5 ships Jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big models only see the ones that split anyone still running one model for everything is paying Opus prices to decide whether a file exists - the full tree > Opus 5.5 on high runs the main session > explorer reads the code on Sonnet 5.5 > worker edits and runs tests on Sonnet 5.5 > researcher pulls the docs on Sonnet 5.5 > all three on medium > Fable 5.1 on call for main and every subagent paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Check ~/.claude/agents and .claude/agents for subagents that already fit explorer, worker and researcher. > Draft new ones only for missing roles > Give each model: sonnet, effort: medium > Skip any that pin a different model and list them 2. Set the main session to high via effortLevel in ~/.claude/settings.json, and set advisorModel to fable 3. Find anything that keeps the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY) plus CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, change nothing 4. Add one rule to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done Show me every change as a diff first. No edits until I say go." ↳

delost

48,238 Aufrufe • vor 5 Tagen