Loading video...

Video Failed to Load

Go Home

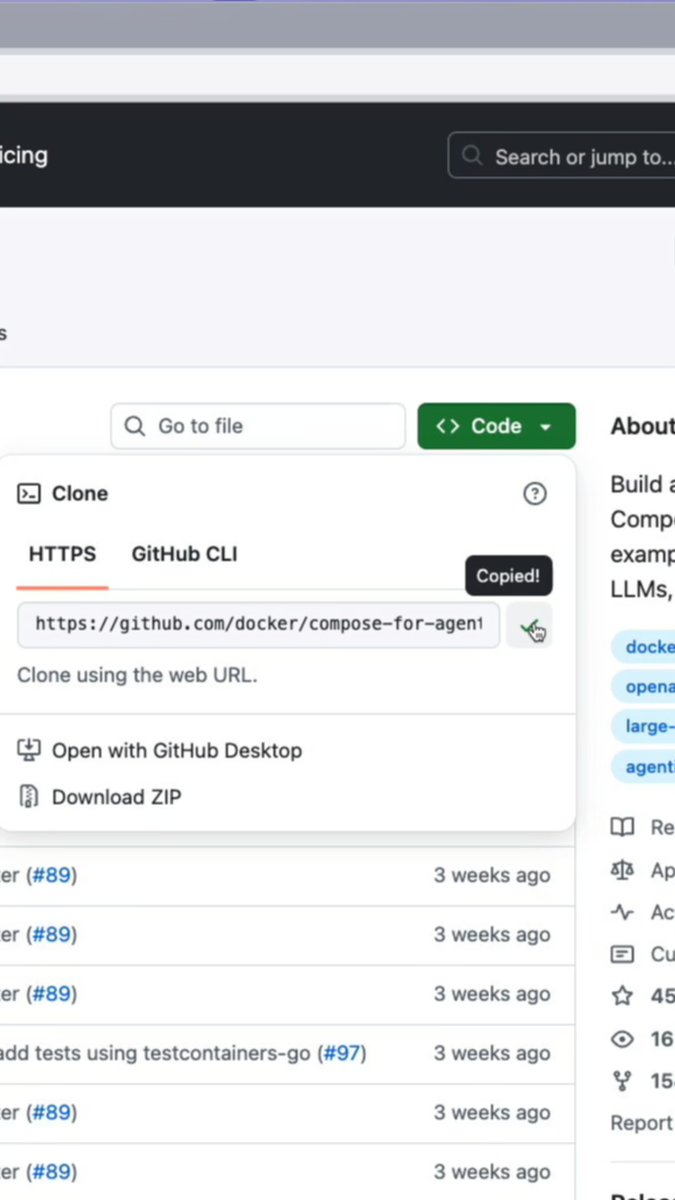
Here is an example Pipecat project for trying PhoneLLM Alpha 1. Deploy the model to a Modal endpoint with one click. Client from the video in repo too (with all that sweet sweet terminal-ish aura.) Next up, a TTS that can pronounce Merve Tan's name correctly? 😅
21,006 views • 21 days ago •via X (Twitter)

6 Comments

ata's profile picture
ata20 days ago

@bmervetan tts’e merve’yi okutabiliriz. agent kullanıcıdan yeni bir özel isim duyduğunda son audio turn’de ilgili span üzerinde phoneme extraction çalıştıracak, sonra aynı isim için sonraki tts turn’lerine phoneme override enjekte edecek. yw :)

Tim 🚴‍♂️ Builder's profile picture
Tim 🚴‍♂️ Builder20 days ago

@bmervetan Für mich ist das Repo fast wichtiger als der Model-Launch: Client plus Deploy-Pfad schaffen erst die Basis für faire Vergleiche. Als Nächstes würde ich ein deutsches Eval-Set für Unterbrechungen, Tool Calls und Namen bauen. Dort zeigt sich, wie alltagstauglich Voice Agents sind.

yian's profile picture
yian21 days ago

@bmervetan I tried this model and it didn't know what tomorrow was, (thought today was Thursday, tomorrow was Saturday)

Scott Thomas's profile picture
Scott Thomas21 days ago

@bmervetan hi I'm actively building a voice sales agent. I tried phonellm through live kit and it could not tool call very well. Any suggestions? Willing to also give pipecat a try

LukeHalley's profile picture
LukeHalley21 days ago

@bmervetan I'm thinking of doing this for our platform - trying to handle bursty traffic without running a GPU 24/7. We currently use API endpoints to keep costs down, as we don't need 24/7 inference, but we'd love this low latency. Any words of wisdom?

Ahmed Omar.'s profile picture
Ahmed Omar.20 days ago

@bmervetan Jon we'd love to partner. please dm

Related Videos

Introducing PhoneLLM, an open model for voice agents. GPT 5.6 Terra performance on typical voice agent tasks at 1/3 the latency and 1/18 the cost. For voice agents, we need models that are both very low latency and very good at tool calling and instruction following. There's a trade-off here, and we often have to compromise on either latency or capability when building voice agents. With PhoneLLM (and the training and data stack that made this model possible) we're fixing this problem. For the last couple of years, most of the effort in frontier model development has gone towards leveraging test-time compute. Which is awesome! Models of all shapes and sizes are available that perform really, really well ... if you have "thinking" turned on for your model. But if you need your agent to respond at voice conversation speed, you can't use thinking models. PhoneLLM is a full-weights fine-tune of NVIDIA Nemotron Nano 30B. We trained on a wide range of real-world telephone and customer support use cases. The training focused on taking the excellent Nano 30B base capabilities and teaching the model to do typical voice agent tasks with thinking disabled. The results are really good: accurate tool calling and concise, on-topic responses in long conversations. And fast: TTFAT measured server-side is <100ms if you run PhoneLLM on a lightly loaded B200. :-) But seriously, when we characterize model latency, we do it with full, end-to-end, batched request simulations using real Pipecat voice agent pipelines. You can serve more than 80 concurrent agents on a single B200 with P95 end-to-end TTFAT <600ms. Including network overhead. That's an LLM cost-per-minute around $0.0025. (1/4 of a cent.) At a latency lower than any third-party API offers today. More details about this model, including weights on Hugging Face, how to spin it up with one click on Modal, and a starter project repo you can clone, are in the thread ...

kwindla

329,729 views • 22 days ago