Video yükleniyor...
Video Yüklenemedi
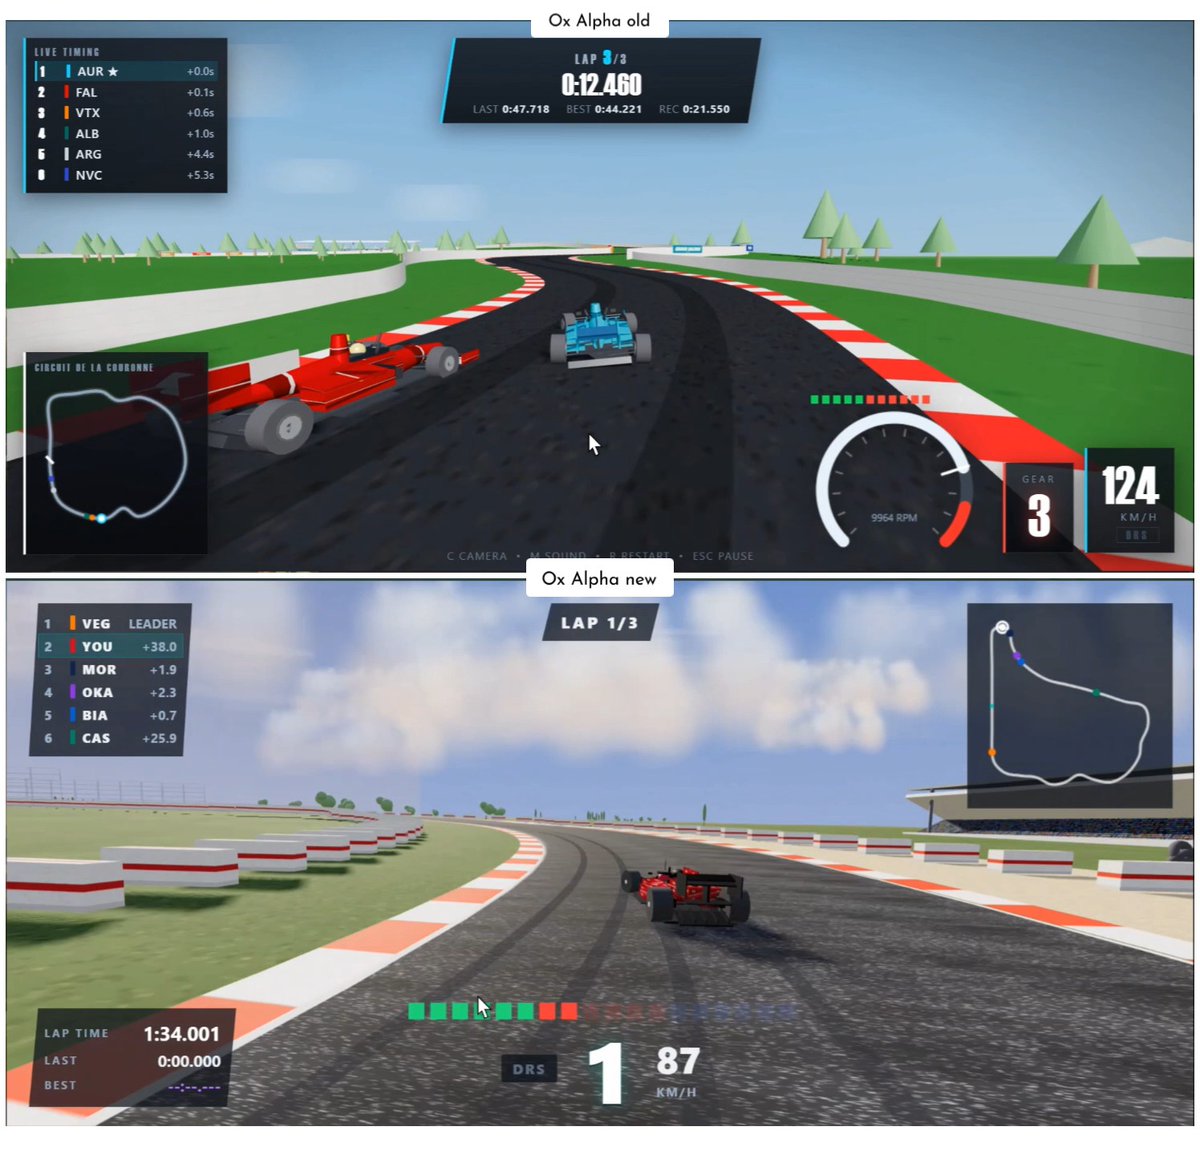
I feel Ox Alpha has continual learning and is modifying itself each day coz how else does it keep improving on it's own? i gave it the same prompt i used on the first day and the output is drastically improved, with a more detailed and accurate 3d model... show more
546,299 görüntüleme • 1 ay önce •via X (Twitter)
45 Yorum

It told me to go to bed last night

that’s weird coz only Claude does that
I know. Exactly.

Don’t tell me it’s grok 4.7 🙄
nobody knows who's behind the model, but everyone will be surprised when it gets revealed

@adrixy0 Or you've forgotten those LLM ain't deterministic
@TimJayas technically they are deterministic, but in production environment kernels aren't batch-invariant, and varying server load changes the batch size results in non-deterministic behaviour

@Rouge_Encore @TimJayas Nah, even disregarding those things very rarely do you do greedy sampling, usually leads to worse model performance

@adrixy0 @Rouge_Encore @TimJayas @grok what are these nerds talking about? What do those words mean?

They're debating why the same AI prompt can give different answers. Deterministic = same input always yields same output. LLMs can be (via greedy sampling: always pick the single most likely next word). But in real servers the low-level GPU math routines (kernels) aren't batch-invariant. Server load changes how many requests get processed together (batch size), causing tiny floating-point differences and non-deterministic results. Greedy sampling is rarely used anyway—it usually makes outputs worse and more repetitive.

soon it will reach opus 5 level
and then Mythos preview

Y'all know that LLMs are non deterministic right? ...which means that you might get better results sometimes, and worse results other times.

You're not just using the model, you're training it through your interactions

Run the prompt 10 times and report back.

Reminder: These models are non-deterministic.

ohh this looks way better now
yup it's improving itself each day

Or it could just be RNG like with any other model. One shots prove nothing and never have.

That would mean the ZDR part is false advertising or opens up a very interesting set of questions around how to define ZDR.

Stealth continual-learning model?

It should be from SSI this is the scaling part they talked about!

The free run is a massive way to gain RL data, would not be surprised if it periodically retrains the weights. Biggest gains from models these days is on the computer use RL gains side.

Been thinking the same. Look at the reasoning token percentage changes... I think it might be outsourcing it's reasoning to a dynamically routed advisor model. I suspect semantic cache optimization as well and maybe even per user routing to A/B based on if it thinks you're cool.

i think you are being fooled by randomness there a bit.

hmmm, try it 10 more times and get 10 different results? also, probably improving ofc, why do you think they’re giving free tokens lol

Ilya’s model????

No it doesnt…

It's just a different seed

Or, and this is gonna blow your mind, it's an LLM and is non-deterministic thus outputs can vary.

Could it be ssi's new model ?

might be ssi's model that has recursive learning 👀

lol it would be great if that is the case ! We will have a lot stronger model. Like I posted , I think it will improve itself by a lot.

Or it in training and checkpoint are changing

Is Ox alpha AGI?

Because llm outputs are non deterministic?

I didn’t expect we hit AGI this year. An unknown company released AGI, with no information. And people are using it for free??

How would this be possible with ZDR?

sample size N = 2🗿

It is getting really good for me. I'm literally burning billions a day for an experiment hopefully I can distill all the knowledge it finds

They are changing the model, to see which one is better, or the config of the model, because there was down time by hours they might been changing the model

What changed for me is mostly that the provider keeps throwing errors now

Man learns LLMs are non deterministic

Maybe this is SSI’s secret model

it’s free to use because they’re getting insane value from the recursive self improvement on the data, china is cooking rn