Video wird geladen...

Video konnte nicht geladen werden

Zur Startseite

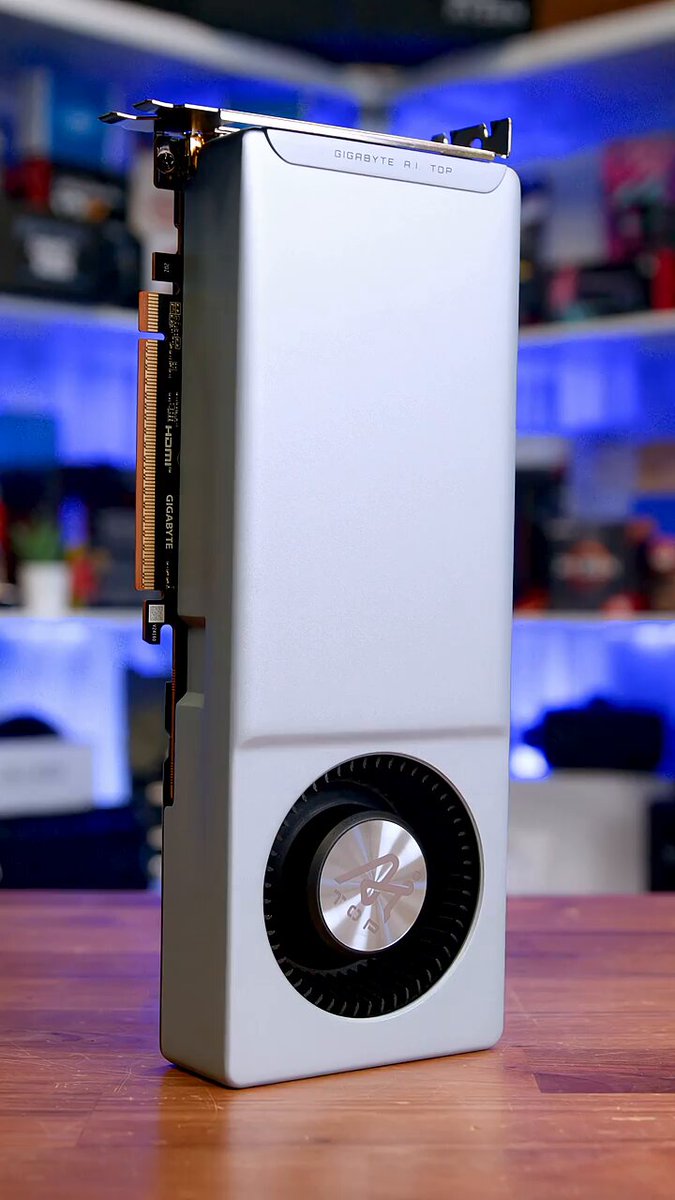
Introducing KausaCompute. Running AI models privately is expensive and complicated. Traditional cloud providers require credit cards, KYC verification, and complex setup processes. For many developers, especially in emerging markets, accessing GPU compute remains out of reach. KausaCompute changes that. Deploy any Docker container with NVIDIA GPU, pay with USDC...

10,945 Aufrufe • vor 3 Monaten •via X (Twitter)

0 Kommentare

Keine Kommentare verfügbar

Kommentare vom Original-Post werden hier angezeigt

Ähnliche Videos

AMD might have disrupted Nvidia's entire cloud GPU rental business. In January at CES, AMD CEO Lisa Su demonstrated a $1,499 mini PC running the same class of AI model that currently costs companies $2,500 to $3,000 every month to rent from Nvidia-powered cloud servers. AMD's own branded version opened pre-orders this month at $3,999. Third party manufacturers have been selling the same chip since 2025 starting at $1,499. Here is exactly why this is dangerous for Nvidia. Nvidia's $75 billion quarterly revenue is built almost entirely on one business model, companies rent access to Nvidia GPUs through cloud providers like AWS and Lambda Labs to run AI. They pay monthly. Nvidia gets paid every time someone runs an AI model in the cloud. That recurring rental income is what turned Nvidia into a $5 trillion company. The AMD box eliminates that monthly fee permanently. One AI consultant switched from $2,800 per month in Nvidia cloud rental costs to $8 per month in electricity. The hardware paid for itself in 11 days. Over 8 months he generated $47,000 running the same AI workloads that previously left him paying Nvidia's ecosystem $2,800 every single month. Multiply that across thousands of enterprise customers and the revenue erosion becomes structural. Every business that buys this box stops paying cloud rental fees forever. Lawyers, doctors, banks, accountants, and financial advisors, businesses with sensitive data that cannot legally go to a cloud server represent billions in annual cloud GPU fees that Nvidia is now at risk of losing permanently. The threat is also closing in from the top. Google signed deals worth tens of billions with Anthropic and Meta to replace Nvidia with its own chips. Amazon built its own AI chips across AWS. Apple trained its AI on Google's chips, not Nvidia's. Custom silicon has grown from 21% of the AI chip market in 2025 to 28% in 2026. Nvidia's rental model only worked because serious AI compute had no alternative.

Bull Theory

26,765 Aufrufe • vor 3 Monaten

Revolutionizing Access to #GPU Power - One Node at a Time.⚡️ Our 10th Utility is coming out on June 20.🚨 BIG GPU Nodes Platform isn’t just another name in the crowded GPU cloud services space, we’re a game-changer. Our platform is purpose-built to bridge the gap between server owners and those hungry for raw, high-performance computing power. 🖥️ We specialize in connecting suppliers from individual server owners to enterprise-scale GPU rig operators with consumers who demand serious horsepower for AI, machine learning, data science, and other compute-heavy applications. Whether you’re offering a sleek single-GPU setup or a massive mining-style array with multiple GPUs, BIG GPU Nodes is your launchpad. We make it simple to rent out underutilized GPU resources and just as easy for users to find exactly what they need — fast, affordable, and tailored to their workload.⛓️‍💥 This is more than cloud computing. This is decentralized GPU power for the future of innovation. ♾️ This product will generate revenue and we will give back to our loyal $CNCT holders. ✨ We’re proud to have MESSIER | M87 as our trusted partner and advisor, backing us with this vision. #M87 🤝 $CNCT From the very beginning, we promised you ONE BIG ECOSYSTEM, and a seamless space where everything you need comes together. Now, that vision is becoming reality. Millions of users will soon be connected, working, creating, and thriving within it. 🌍

Fixera AI

26,682 Aufrufe • vor 1 Jahr

Jensen Huang, CEO of Nvidia, is telling you where to invest in 2026. He has personally directed Nvidia's capital into 8 specific companies for a combined total of over $45 BILLION. This is where the most important company in the AI economy is putting its money. Here’s the full list: OpenAI: $30 billion The largest commitment of the 8. Nvidia is funding the buildout of OpenAI's compute infrastructure from the inside. OpenAI is also Nvidia's single largest customer. GLW Corning: $3.2 billion Optical glass and fiber to physically connect AI clusters. You cannot move data between millions of GPUs without it. IREN: $2.1 billion AI cloud provider with one of the deepest power positions in North America. MRVL Marvell: $2 billion Custom networking chips that move data between GPUs at massive scale. LITE Lumentum: $2 billion Lasers and optical components for the fiber backbone of every AI data center. COHR Coherent: $2 billion Fiber optic transceivers that connect GPU clusters inside data centers. CRWV CoreWeave: $2 billion GPU-as-a-service provider. Nvidia's largest cloud customer outside the hyperscalers. NBIS Nebius: $2 billion AI cloud infrastructure company. Quietly building hyperscale GPU capacity for the AI labs. Whatever Nvidia is buying is where the money is going next. At The Assembly, we’re a team of 8 with one goal: help you find the right stocks early. Turn notifications on so you don’t miss our alerts. This is VERY important. If you’re not following us yet, you will regret it later.

The Assembly

7,307,633 Aufrufe • vor 4 Monaten

Chamath Palihapitiya just dropped the number that explains the entire AI infrastructure trade (Save this). A gigawatt of compute now costs $100 billion and when he started his Arizona data center project it was $4 to $5 billion, it has gone up 20x in a single investment cycle. The implication is not just that AI infrastructure is expensive but rather that the capital barrier to owning meaningful compute has become so high that only a handful of entities in the world can actually build it and the companies who got there early are sitting on what may be the most durable pricing power in the history of the technology industry. This is the neocloud trade. The neocloud market, purpose-built GPU cloud providers like CoreWeave, Nebius, and Lambda Labs was worth $35 billion in 2026 and is projected to reach $236 billion by 2031, compounding at 46% annually. For context, that is faster growth than cloud computing itself posted in its first decade. The reason is very simple, hyperscalers like AWS, Azure, and Google are building for everything, storage, databases, enterprise software, networking and their GPU pricing reflects the overhead of that full-stack infrastructure. Neoclouds build for one thing only, AI compute. The result is a 60% to 85% cost advantage on the same Nvidia silicon, bare metal H100s at $0.78 to $2.79 per GPU-hour on a neocloud versus $3.43 to $5.07 per GPU-hour on a hyperscaler. That spread does not close as AI demand scales but rather it widens, because hyperscalers have to amortize legacy infrastructure and margin expectations that neoclouds do not carry. Gartner projects that by 2030, neoclouds will capture 20% of the $267 billion AI cloud market, and Vultr's own analysis says at least 80% of GPU market share by end of 2026 will be held by a small group of scaled neocloud providers. Now zoom into Nebius specifically, because it is the most interesting publicly traded proxy for this trade. Nebius is the infrastructure arm of the former Yandex Russia's equivalent of Google rebuilt from the ground up after Russia's invasion of Ukraine by Arkady Volozh and relisted on Nasdaq in October 2024. The team that built it already knew how to run internet-scale infrastructure at the lowest possible cost, which is exactly the operational DNA a neocloud requires. In Q1 2026, Nebius reported revenue of $399 million and already generating serious cash on a young business with revenue growing nearly eightfold year-over-year. Then in March 2026, Meta signed a five-year infrastructure agreement with Nebius worth up to $27 billion, $12 billion in committed dedicated GPU capacity deployments beginning early 2027, plus up to $15 billion more tied to Meta purchasing Nebius's unsold third-party capacity. The deal will be executed on one of the first large-scale deployments of Nvidia's Vera Rubin platform, the next-generation architecture after Blackwell making Nebius one of a tiny number of operators in the world with confirmed priority access to the most advanced AI hardware available. Following the contract, Nebius guided to $7 to $9 billion in annualized recurring revenue for 2026 representing 540% year-over-year growth. Chamath Palihapitiya point about the $100 billion capital moat is the bear case for new entrants and the bull case for incumbents. No one can afford to build the next CoreWeave or Nebius from scratch at current hardware and power costs. The companies that are already built, already contracted, and already deploying Nvidia's latest silicon have a moat that compounds with every GPU generation cycle because they get allocations first, they deploy fastest, and their customers re-sign rather than wait for a new operator that does not yet exist. Come join Milk Road Pro for our full breakdown, the complete neocloud competitive landscape, how to think about Nebius's valuation versus CoreWeave and AI entire thesis. Link below.

Milk Road AI

139,047 Aufrufe • vor 3 Monaten

QVAC SDK 0.14.0 is live. This release makes the on-device stack faster on mobile, ships the developer-agent path, and takes local text-to-speech to 31 languages. Main highlights: - OpenCode and OpenClaw. The first official OpenCode plugin, plus a maintained OpenClaw compatibility path, both built on managed mode and qvac serve. Point a coding agent at a local model with far less setup and far fewer surprises. - Brain-computer interface transcription, on the SDK. Take recorded neural signal data and decode it into text, fully on-device, no cloud. Stream it in chunks through a simple API. In 0.14 it runs GPU-accelerated on iOS. - Text to Speech in 31 languages with our Supertonic3 upgrade. VOICE AND SPEECH - Supertonic3 multilingual TTS, 5 languages to 31. - Chatterbox and Supertonic now run on the Android GPU, with lower memory use (especially on iOS), quantized s3gen Chatterbox support, and a fix for Chatterbox occasionally emitting random speech. - Whisper transcription now runs on the iOS GPU. Parakeet runs on the Android GPU, with steadier real-time streaming. VISION AND OCR - VLM multi-tile batching: high-resolution Pan and Scan images are encoded in one pass instead of tile by tile, for faster vision throughput. - OCR on ggml (EasyOCR and DocTR) reaches full speed parity with the onnx path, across Metal, OpenCL, and Vulkan. PLATFORM AND RELIABILITY - Dynamic compute backends on Linux: one build picks the right backend at runtime, and opens the door to ROCm and CUDA support without per-backend builds. - Thinking tokens are kept out of the model context, so reasoning no longer fills the KV cache. SDK 0.14.0 is now leaner and faster to start. Let’s build.

QVAC

23,995,874 Aufrufe • vor 2 Monaten

UC Berkeley just open-sourced FreeToken. (2–4x faster local LLM inference than Ollama) the results are wild: - Qwen3.6-35B on an 8GB GPU at 39.3 tokens/s - DeepSeek-V4-Flash 284B on a 32GB GPU at 22 tokens/s - GLM-5.2 753B on a 96GB GPU at 14.9 tokens/s a 35B model at 16-bit precision needs about 70GB just for its weights. even at 4 bits it is close to 18GB, and FreeToken serves it on an 8GB GPU. let me explain how: all three models mentioned above are Mixture-of-Experts, and that is what FreeToken takes advantage of. each layer holds hundreds of separate experts plus a small router that picks a few of them per token. Qwen3.6-35B activates roughly 3B of its 35B parameters per token. DeepSeek-V4-Flash picks 6 of 256 experts per layer, so 13B of its 284B run at a time. so compute was never the bottleneck. the weights a single step touches fit comfortably on a consumer GPU. every expert the router might pick still has to exist somewhere. they sit in system RAM, and the GPU keeps a cache of the ones the model has been using recently. so everything comes down to what happens when the router picks an expert that is not on the GPU. there are two ways to serve that miss: 1. copy it over PCIe and run it on the GPU 2. run it on the CPU, where it already lives both read from the same system memory, so they compete for one pool of bandwidth instead of adding to each other. existing engines pick one option and freeze it when the model loads. but routing changes on every token, so a fixed choice misses most of what the model asks for. FreeToken measures both bandwidths on your machine and splits each step's misses between the two paths in proportion. the GPU and CPU results then merge exactly, with no approximation. two machines with the same GPU can end up wanting opposite strategies, which I did not expect. a 5090 in a gaming desktop should push nearly everything over PCIe, while an 8GB laptop is better off computing most misses on the CPU. none of that is readable off a spec sheet, so the engine profiles it once per machine. the second half of the design is about agents. coding agents constantly rewrite their own history, and every edit normally forces thousands of tokens back through prefill. FreeToken saves its checkpoints at the exact boundaries agent frameworks cut on, so it only reprocesses the new part. its slowest first token stays under 44 seconds, while llama.cpp peaks at 232 and KTransformers at 946. it serves the OpenAI and Anthropic APIs under Apache 2.0, so Claude Code and Codex can point at it directly. releasing weights publicly decides who can download a model, not who can afford to run one. frontier open models keep shipping, and running them still assumes a rented cluster. meanwhile there are over a hundred million consumer machines with discrete GPUs sitting mostly idle. closing that gap was never a hardware problem, and work like this is what turns open weights into something you can actually use. paper: repo: almost every idea in this post, from why memory bandwidth decides the outcome to why moving weights costs more than computing on them, comes straight out of how a GPU is built. I wrote a detailed primer on that. the article is quoted below.

Akshay 🚀

343,270 Aufrufe • vor 1 Monat

Mark Zuckerberg is explaining one of the most misunderstood dynamics in AI and it has direct investment implications (Save this). The concept he's describing is model distillation, and it's one of the most important techniques to emerge in AI over the past year. Here's how it works. You train a massive, enormously expensive model, in Meta's case, Llama 4 Behemoth, a 2 trillion parameter teacher model and then you use that model to teach a much smaller, cheaper model. The smaller model inherits roughly 90 to 95% of the intelligence of the giant while running at 10% of the cost and on a fraction of the compute. Meta already did this with the Llama 4 family and Behemoth serves as the teacher. Llama 4 Scout and Maverick, the publicly released open-source models were distilled from it. Scout runs on a single H100 GPU with a 10 million token context window and outperforms models that cost far more to operate. Maverick, at 17 billion active parameters, rivals DeepSeek V3 in coding at half the parameter count and beats GPT-4o on multimodal benchmarks. Both are completely free for commercial use. What Zuckerberg is pointing at is a structural shift in how AI gets deployed in the real world. Companies aren't taking a frontier model off the shelf and running it as-is but rather taking open-source models, fine-tuning them on their own proprietary data, distilling them into even smaller custom models tailored to their specific use case, and running them on infrastructure they control at a fraction of the cost of a closed frontier API. The investment implication of this is significant and runs in two directions. For Meta specifically, this is a strategic masterstroke. Every company that builds on Llama, fine-tunes it, distills it, or deploys it through their infrastructure is pulling into Meta's orbit while Meta builds the most powerful open teacher model. The ecosystem of companies using it grows and that ecosystem generates commercial activity across Meta's platforms and data services. Meta's AI research benefits from billions of real world deployment signals and it's a flywheel that closed model providers cannot replicate because their strategy requires charging per token, which is now a 65x cost disadvantage against the open-source alternative. For the broader market, distillation changes the economics of inference in a way that has barely been priced in. As intelligence becomes extractable into smaller and cheaper models, the absolute demand for compute doesn't decline but rather it explodes, because now the number of applications that are economically viable expands by orders of magnitude. Every task that was previously too expensive to automate at $3.25 per call becomes viable at $0.05 that means more total token usage, more total GPU utilization, and more demand for the infrastructure companies, the Nebiuses, the GE Vernovas, the Constellation Energies that supply the underlying compute and power.

Milk Road AI

27,908 Aufrufe • vor 2 Monaten