正在加载视频...

视频加载失败

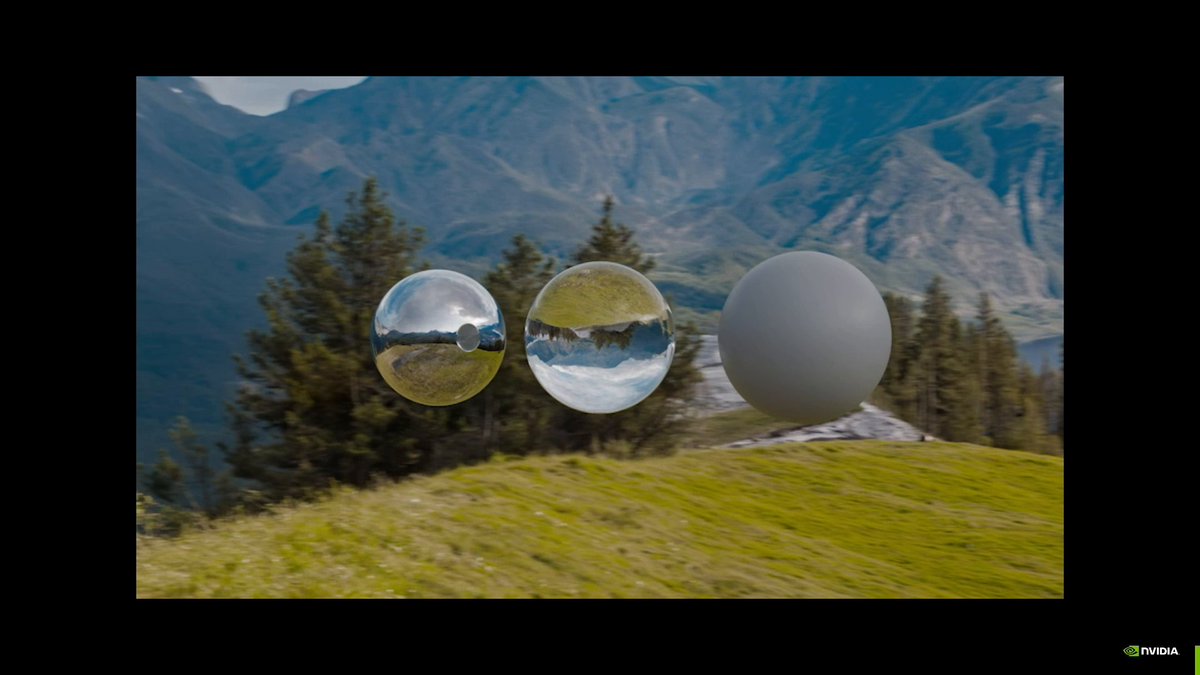
Introducing Modality Forcing, a recipe for post-training T2I models for SOTA RGB-Depth generation! Text-to-image (T2I) models learn rich representations of the spatial world. How do we build on this prior for high-quality depth generation? 🧵 [1/6]
66,635 次观看 • 3 个月前 •via X (Twitter)

11 条评论

Bardienus Duisterhof 的头像
Bardienus Duisterhof3 个月前

Modality Forcing trains one DiT backbone with a separate noise level per modality. A modality’s noise level sets whether it’s generated or conditioned on. A single model does image→ depth, depth→ image and joint RGB-D generation. [2/6] [2/6]

Bardienus Duisterhof 的头像
Bardienus Duisterhof3 个月前

Does the T2I prior actually help with depth? We train T2I models from scratch across a range of scales and find a clean trend: bigger T2I models trained on more data give better depth. The spatial prior scales. [3/6]

Bardienus Duisterhof 的头像
Bardienus Duisterhof3 个月前

Applied to FLUX.2-klein-9B, Modality Forcing matches the best dedicated depth models (MoGe-2, PPD) — creating crisp, robust depth maps with few floating artifacts. It even generalizes well beyond the training distribution, e.g., animals and humans. [4/6]

Bardienus Duisterhof 的头像
Bardienus Duisterhof3 个月前

Furthermore, traversing any denoising trajectory enables conditioning at arbitrary strength. Introducing Corgi-Anything: a demo to show many animals can be reshaped to a Corgi! Try it out yourself on the website 🐶 [5/6]

Bardienus Duisterhof 的头像
Bardienus Duisterhof3 个月前

Big thanks to all collaborators @theworldlabs @CarnegieMellon - @RamananDeva @jeff_ichnowski @jcjohnss @KeunhongP Project Page: arXiv: Code: HF Demo 🤗: [6/6]

David 的头像
David3 个月前

@BDuisterhof nice!

Mike Roberts 的头像
Mike Roberts3 个月前

@BDuisterhof This is awesome! Please cite the datasets used in this work (i.e., include them in the bibliography) in the arXiv paper when you have a chance 😅

Bardienus Duisterhof 的头像
Bardienus Duisterhof3 个月前

Thank you! And apologies, totally slipped and will update asap. Hypersim is awesome!

vince_cartillier 的头像
vince_cartillier2 个月前

@BDuisterhof This is very cool! Do you know whether the backbone's t2i performance improves after Modality Forcing (post-training with depth constraints)?

Bardienus Duisterhof 的头像
Bardienus Duisterhof2 个月前

Thank you! The dept-conditioned generation becomes more aligned, but I don’t believe generic image generation improves with only post-training FLUX. If you had access to training data and co-trained it might be different.

Taro Bushidō 的头像
Taro Bushidō3 个月前

@BDuisterhof Using the spatial world model already in T2I and forcing it toward depth output is elegant. How does interpretability of the depth features compare to the original representation space?

相关视频

Google presents Still-Moving Customized Video Generation without Customized Video Data Customizing text-to-image (T2I) models has seen tremendous progress recently, particularly in areas such as personalization, stylization, and conditional generation. However, expanding this progress to video generation is still in its infancy, primarily due to the lack of customized video data. In this work, we introduce Still-Moving, a novel generic framework for customizing a text-to-video (T2V) model, without requiring any customized video data. The framework applies to the prominent T2V design where the video model is built over a text-to-image (T2I) model (e.g., via inflation). We assume access to a customized version of the T2I model, trained only on still image data (e.g., using DreamBooth or StyleDrop). Naively plugging in the weights of the customized T2I model into the T2V model often leads to significant artifacts or insufficient adherence to the customization data. To overcome this issue, we train lightweight Spatial Adapters that adjust the features produced by the injected T2I layers. Importantly, our adapters are trained on "frozen videos" (i.e., repeated images), constructed from image samples generated by the customized T2I model. This training is facilitated by a novel Motion Adapter module, which allows us to train on such static videos while preserving the motion prior of the video model. At test time, we remove the Motion Adapter modules and leave in only the trained Spatial Adapters. This restores the motion prior of the T2V model while adhering to the spatial prior of the customized T2I model. We demonstrate the effectiveness of our approach on diverse tasks including personalized, stylized, and conditional generation. In all evaluated scenarios, our method seamlessly integrates the spatial prior of the customized T2I model with a motion prior supplied by the T2V model.

AK

40,489 次观看 • 2 年前