Video yükleniyor...
Video Yüklenemedi
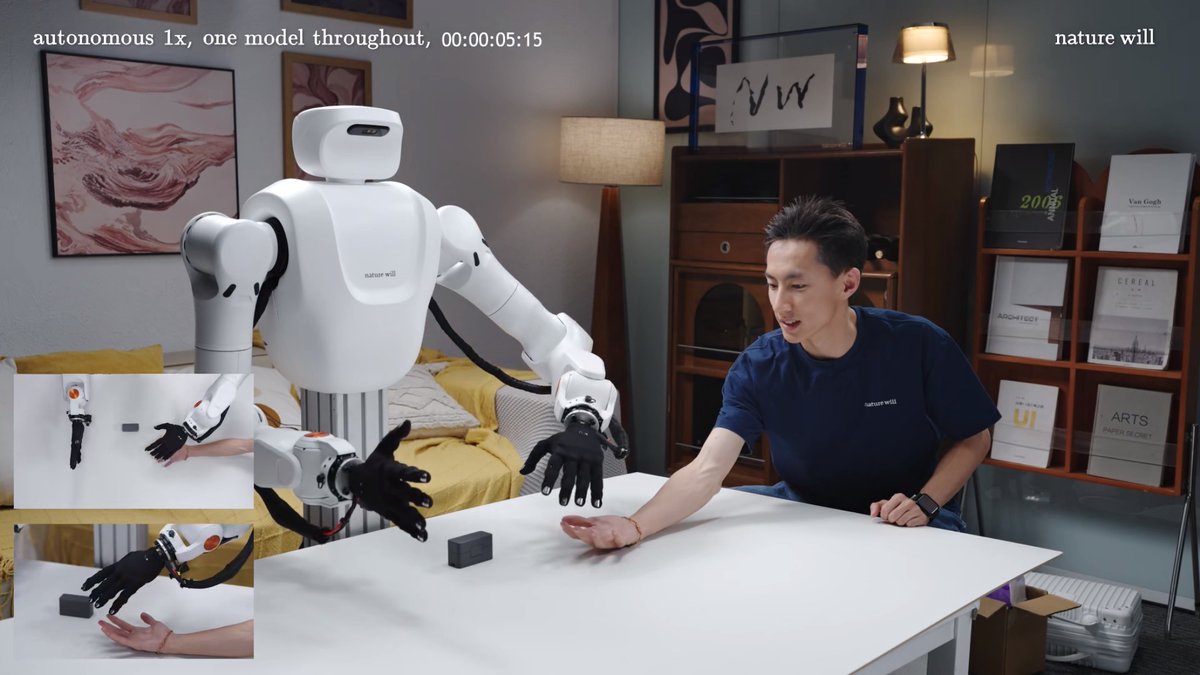
Introducing Natura-1, our first general foundation model for the physical world. It follows natural-language instructions zero-shot and turns them into action with dexterous hands. Natura-1 is a 50-billion-parameter mixture-of-experts (MoE) model pretrained on one million hours of egocentric human experience. On top of this foundation, we conduct efficient post-training... show more

1,043,474 görüntüleme • 21 gün önce •via X (Twitter)
39 Yorum

With task-specific tuning, Natura-1 demonstrates sustained autonomous execution across workflows that combine precise manipulation with multi-step coordination. The six demos below show continuous, single-take autonomous workflows, several lasting multiple minutes without human intervention. Each requires a single policy to coordinate precise, dexterous actions across multiple steps and carry the task through from start to finish.
Strong instruction-following capabilities enable users to interact naturally with Natura-1, giving it the potential to become part of everyday life and turn the users' intentions into action. The video below presents a complete, nearly 30-minute recording of our everyday interactions with Natura-1, filmed in a single continuous take.
We built Natura-1’s infrastructure to support both efficient training and real-world deployment, combining distributed parallelism, shared GPU kernels, and a robot serving system with state tracking, monitoring, and latency below 100 ms.
Designed to maximize its scaling potential, Natura-1 stays close to a standard 50B mixture-of-experts transformer. Its algorithmic innovations lie in the arrangement of multimodal tokens within a single sequence and the causal structure of attention, keeping the backbone simple and scalable.
With egocentric training data scaled from 44K to 1M hours, Natura-1 predicts actions more accurately on unseen human and robot data. Prediction MSE error on real-robot data falls by 67.7%, without fine-tuning on robot data.
Explore Natura-1’s real-world demos and scaling results in our technical blog, alongside a closer look at its training data, model architecture, and infrastructure.

physics shapes nature, will drives actions. Natura-1.

Training a foundation model on human egocentric data to achieve true dexterous manipulation is a massive leap for physical AI. The ability to generalize to unseen scenarios with minimal robot data is exactly what the industry needs right now.

🫡🫡🫡

Starting from human experience and adapting to robot bodies flips the data problem entirely.

AI startups raise millions building features users ignore

This absolutely slaps. Some of these are genuinely difficult tasks

Everyday actions ask a lot of our hands. Bringing that versatility to robots is a direction worth watching

a robot doing calligraphy before i've fixed my own handwriting is rude

Beautiful

Natura-1 is a huge leap toward truly intelligent robots! 🤖 Turning human experience into real-world action with zero-shot reasoning is incredible. The future of robotics is here! 🚀
If this scales, it points to something much more important than another manipulation demo: learning physical intelligence from human experience, then generalizing zero-shot to new tasks and conditions on real robot hands.

amazing

Impressive work Zero shot dexterous manipulation from human video is a big leap.

Impressive demo! I wonder how well it generalizes outside this controlled home setup. Real messy daily life is a far harder test.

Million hours of human hands plus a little robot data. Whoever owns egocentric video owns the cheapest teacher.

A model that plans hands and faces needs strong tests, not just good demos. How do you measure failure when many people move at once?

@grok who founded nature will

The wonton task is a good stress test.

Going from 44K to 1M hours of egocentric data is a big jump. Curious how much of that million hours is outdoors?

Very impressive to see the robot making dumplings and practicing calligraphy!

dexterous hands are such a challenging frontier for robotics

dope Training on a million hours of human experience and adapting with limited robot data is an interesting path toward more general-purpose robotics.

amazing

one million hours of egocentric footage and the first thing it does is cook and clean for us. humanity really looked at the robot uprising and said actually lets just get a housewife

Physical world unlocked 🔥

for the do not pick instruction, leaving the hand still could be a useful negative action label.

One million hours of egocentric video is dense only if it covers the contact regimes the demos never had. Did post-training include contact-variation trials like wet, dusty and deformable objects, or is zero-shot generalization measured only across camera and scene changes?

Natura-1 is a major step toward autonomous physical intelligence. The ability to turn natural-language instructions into real-world actions is impressive.

Amazing

@foxieonline save it!

This is pretty fascinating. Getting a robot to understand an instruction is one thing; carrying it out reliably in the physical world is a whole different challenge.

does the identity model that emerges from all that egocentric training data stay with the robot, or can it move? that's the part we're building the protocol for 🧠

A foundation model for the physical world is exciting.