Video yükleniyor...

Video Yüklenemedi

Ana Sayfaya Dön

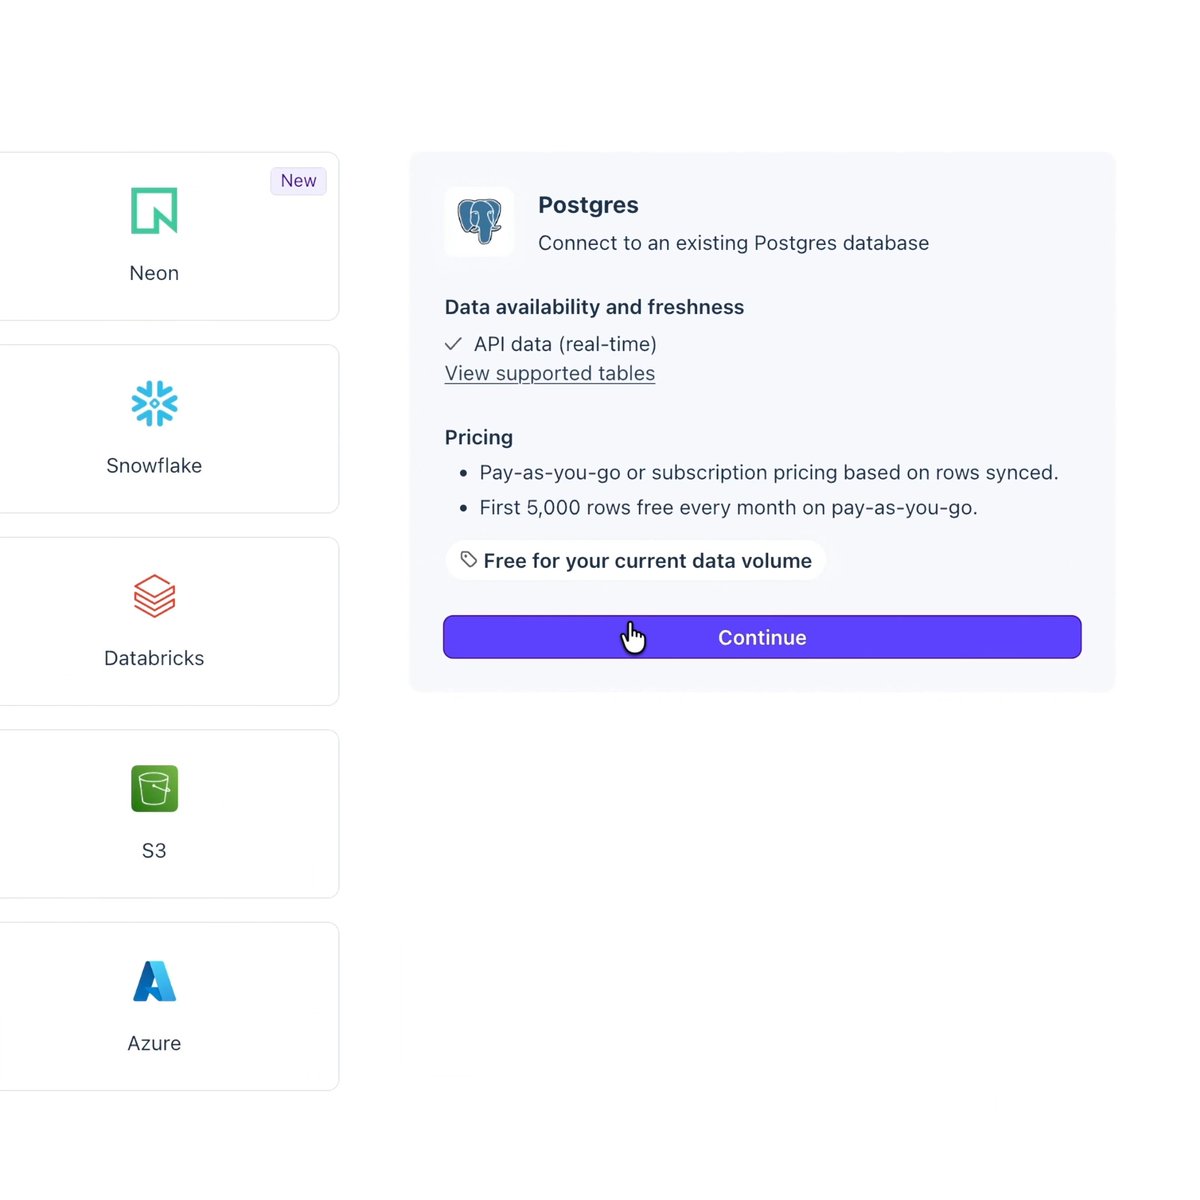
Introducing Supabase Pipelines. Your app runs on Postgres, but your analytics usually live somewhere else, like BigQuery. Pipelines keeps that data in sync for you in near real time, with no pipeline to build or maintain.
63,426 görüntüleme • 3 ay önce •via X (Twitter)

21 Yorum

Supabase profil fotoğrafı
Supabase3 ay önce

It's built on Postgres logical replication, powered by our open-source engine, Supabase ETL. It runs the initial sync, replicates every insert, update, delete, and truncate, and keeps your destination schema in sync as your Postgres schema changes. BigQuery is live now. ClickHouse, Snowflake, and DuckLake are available on request. Read more:

Supabase profil fotoğrafı
Supabase3 ay önce

Tune into our weekly livestream on Mondays at 23:00 UTC to ask questions and talk about Supabase Pipelines.

Mojeeb | Arcapush.com profil fotoğrafı
Mojeeb | Arcapush.com3 ay önce

amazing! i’ll set this up, right away.

Tech PlusX profil fotoğrafı
Tech PlusX3 ay önce

👀👀

Hixon profil fotoğrafı
Hixon3 ay önce

Love anything Supabase does

Jaya Nayak profil fotoğrafı
Jaya Nayak3 ay önce

No more wasting engineering hours building custom data pipelines.

Layerbase profil fotoğrafı
Layerbase3 ay önce

Clickhouse on Layerbase has been a hit. Surprised it took this long

Samian profil fotoğrafı
Samian3 ay önce

so you're telling me my bigquery pipeline built on a cron job and a prayer was unnecessary this whole time

AI Mastery Guide profil fotoğrafı
AI Mastery Guide3 ay önce

Keeping Postgres and BigQuery in sync automatically saves so much hassle

Sebastian Buzdugan profil fotoğrafı
Sebastian Buzdugan3 ay önce

near real time breaks first on schema drift not raw replication speed

skellertor profil fotoğrafı
skellertor3 ay önce

Glad I was forced to use you for a project. Never looking back now

Marco profil fotoğrafı
Marco3 ay önce

Right now im using GCP DataStream for this. Is this in any way better, faster or cheaper?

Hussain Fakhruddin profil fotoğrafı
Hussain Fakhruddin3 ay önce

No pipeline to build or maintain is the real win.

Carmelo schepis profil fotoğrafı
Carmelo schepis3 ay önce

why sync when you could just not

Mathieu Kessler profil fotoğrafı
Mathieu Kessler3 ay önce

No pipeline to build or maintain is the real win.

Fabio Lauria profil fotoğrafı
Fabio Lauria3 ay önce

Most teams waste weeks shuffling data between systems instead of analyzing it. The real bottleneck isn't the pipeline—it's converting synced data into actionable decisions quickly enough to drive impact. I focus on delivering insights in minutes, not days waiting for analytics teams to surface them 📊

Guru Meditation profil fotoğrafı
Guru Meditation3 ay önce

Is that similar to ClickPipes?

Camaleón Raro profil fotoğrafı
Camaleón Raro3 ay önce

real-time pipelines without building one is the actual unlock. most teams i know spend 60% of analytics eng time on the sync layer the failure mode nobody talks about: schema drift between postgres and bigquery. thats where every pipeline I've seen buckle after 3-4 months

MixRoute AI profil fotoğrafı
MixRoute AI3 ay önce

Love to see any new features Supabase adds.

Emile Kratiroff profil fotoğrafı
Emile Kratiroff3 ay önce

No app big enough to have analytics on big query runs on supabase

Valenciana profil fotoğrafı
Valenciana3 ay önce

@grok what does this mean for my backend in simple terms

Benzer Videolar

Your agents can't keep up with real-time data. Especially when it's scattered across dozens of sources. Most teams waste weeks building custom connectors for every database, API, and data warehouse. Then they build ETL pipelines to sync everything. By the time your agent retrieves the data, it's already outdated. Picture this: Your Postgres database updated 5 minutes ago. Your MongoDB collection changed 2 minutes ago. Your agent is still pulling from yesterday's snapshot. This is why most production RAG systems fail. There's a better approach: MindsDB is an open-source AI platform with a federated data engine that lets you query multiple data sources in real-time using SQL - without moving any data. Here's what makes it different: ↳ Your data stays in place. No ETL pipelines or data duplication ↳ Query Postgres, MongoDB, REST APIs, and more using consistent SQL ↳ JOIN across different sources in real-time with a unified interface ↳ Works with both structured and un-structured data And here's the best part: You don't even need to write SQL. Just describe what you want in plain English, and MindsDB converts it to SQL automatically. The system does all the heavy lifting. The breakthrough for AI agents is simple: When data updates at the source, your agent gets fresh results immediately. No sync delays. No stale embeddings. No custom code for each integration. You can literally write a SQL query that joins a Postgres table with a MongoDB collection and gets live results. This is what production AI applications need but rarely get. In this video, I give you a complete walkthrough of what we just discussed and how to actually do it. Make sure you watch this till the end. I've shared the link to MindsDB's GitHub repo in the next tweet!

Akshay 🚀

65,672 görüntüleme • 11 ay önce