Загрузка видео...
Не удалось загрузить видео
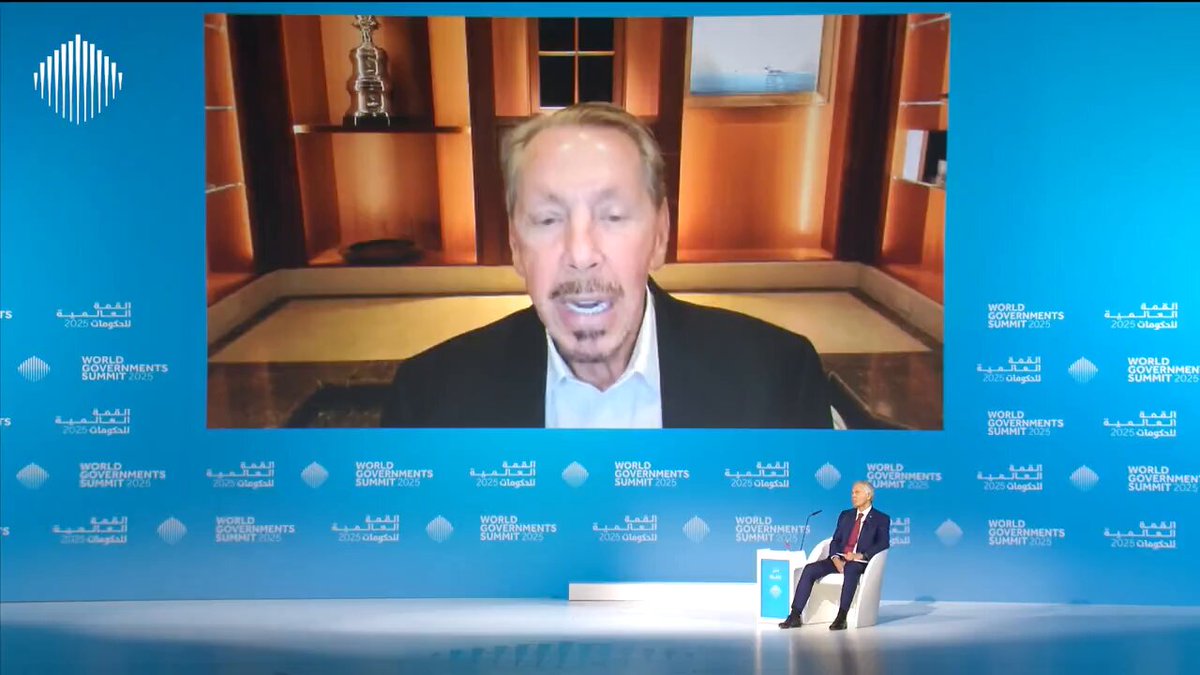
Larry Ellison $ORCL highlighted something critical: models like ChatGPT, Gemini, Grok, and Llama are all trained on largely the same public internet data. When everyone trains on the same information, models inevitably converge. That’s why AI is moving toward commoditization. The real moat isn’t the model itself. It’s the... show more

1,171,212 просмотров • 7 месяцев назад •via X (Twitter)
Комментарии: 34

This is why Europe, and Germany especially, is less focused on winning the race for the best foundation model and more about building AI on proprietary industrial data for industry and manufacturing. (Siemens, BASF, Bosch)

You people get impressed so easily. Saying this is as obvious as saying that we have LLMs because all trained with transformers architecture. If someone developed a better method it would win. Come on!

He doesn't know about Hub

Wow. Larry figured out the endgame for this bullshit only a decade or so after Google.

🙏

A trillion dollar race to see who can summarize a 2014 Reddit thread about how to boil an egg the most efficiently.

He's right, there is zero moat. I just went back to Perplexity yesterday after a year because I got bored of Claude and Geminis UI and UX. Perplexity is just more fun right now at the same time becoming the financial king of LLM the way Claude leads in Coding

Larry Ellison dropping truth bombs on AI: everyone's models are basically sipping from the same public data fountain, so they're all starting to taste the same. The real winner? Companies with exclusive, proprietary data nobody else can touch. Bull case: Oracle's quietly building that moat in cloud/AI infra, with earnings growth +38% YoY, analysts screaming +86% upside to targets, top-tier quality (ROE 69%!), and big money like Capital Research Global Investors just massively loaded up +29.28% on their 30,137,126-share position! Bear case: Momentum's been rough (-39% recently), so the stock's taken some hits even as the fundamentals look strong. Our data: 71/100 confidence score (high conviction, top 35% of stocks we track), 59% chance it's higher in a year, median +9.3% expected return, with serious volatility. Risk/Reward → only ~2.3:1. When the smartest players are piling in and the data edge is everything... you gonna FOMO on the company literally powering the proprietary data revolution, or watch everyone else eat? $ORCL hot take below – buy the dip or nah?

Yes, so who has that? Google, AMZN, and TSLA/X

I don't think most people realize that the majority of high-value corporate data lives inside an Oracle database. That's been true for decades. Which means that Oracle has the inside scoop on helping all those big corporations unlock the proprietary value of their data. Using Oracle tools and Oracle Cloud. Are all you AI investors factoring that aspect in?

That's why they are begging for people to "just try out an AI before you fall behind your peers". They don't care about you. They need you to feed it YOUR data. Think of the CRE analysts uploading rent rolls and T-12's protected by an NDA. Lawyers uploading privileged info.

This is complete bullshit. If it were true, then Facebook and Apple would dominate the market.

And this should terrify EVERYONE. •

1. More garbage NOT > less garbage. 2. @BrianRoemmele has saved 'high-protein' information for decades, and started Zero Human Company based on a tranche of very 'high-protein' information from a company that had done EXTENSIVE research before folding.

Which is why Oracle is buying healthcare IT companies like Cerner. They want your health data.

This is why Twitter is the best investment of all time.

This isn't even true anymore.

Larry Ellison wants to change something so that nothing changes. Oracle's private AI consulting and AI maintenance contracts will replace Oracle's software consulting and maintenance contracts. Smart guy!

@grok what companies is this bullish for?

Even those data will soon be converge and models learn from each other . I believe these are all changing in 2-3 years

Anyone who has read the Shadow Run novels from the 1990s will recognize (crazy) similarities to present. And then you know, chummer, that data (expensive to collect, well protected, exclusive, and unique) will be a valuable economic asset in the future.

I know Fortune 50 companies that don't allow any AI in the workplace.Not because they're anti-AI. They're pro-IP. They can't risk their company secrets ever being processed by an LLM.When every company runs on the same dataset and the same engine, everything looks the same. Differentiation dies. Their business model stays the moat. It always has been. What the LLM doesn't know becomes more valuable than everything it does know.

That’s pre training, post training is where the real difference is these days.

when every model tastes the same the wrapper becomes the whole product

If intelligence becomes abundant, it’s not about the model anymore. It’s about control. Control of distribution, compute, data, workflows. So who are the real winners?

like the data Tesla has

That's not true at all. While data is one of the main pillars of AI, the other four: compute, algorithms, energy, and operational costs are just as important. For example, Gemini has access to far more proprietary data than OpenAI, yet it currently lags behind.

Thus why Musk bought X

Didn’t Rockefeller do exactly that? He collected past medical knowledge (data), cornered the market, and shifted everything toward patented synthetic pills—turning natural health wisdom into a profitable drug industry.

Walled Gardens

I’m gonna be ok The rest of you need this

Training data is less important than inference time reference data. The training data is pretty done. It’s distillations and synth data from now on.

That’s exactly what @NewConstructs has been saying for years!!!

I think there’s more to AI than just data