Video wird geladen...
Video konnte nicht geladen werden
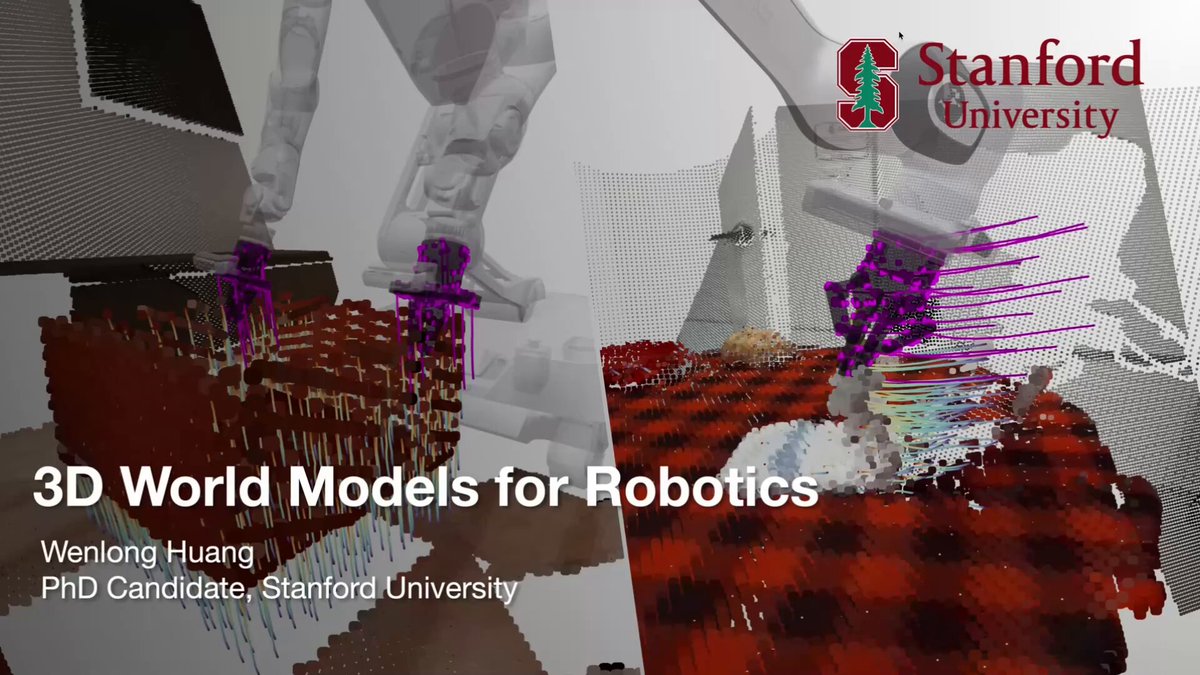
Learning robust, general-purpose reward functions for robotics unlocks many potential applications, like on-robot reinforcement learning or dataset validation. However, there’s a question of how to actually train such reward functions. Training success/failure prediction leads to ambiguous signals partway through a demonstration — it’s hard to measure progress — making... show more
14,751 Aufrufe • vor 4 Monaten •via X (Twitter)
0 Kommentare
Keine Kommentare verfügbar
Kommentare vom Original-Post werden hier angezeigt