正在加载视频...
视频加载失败
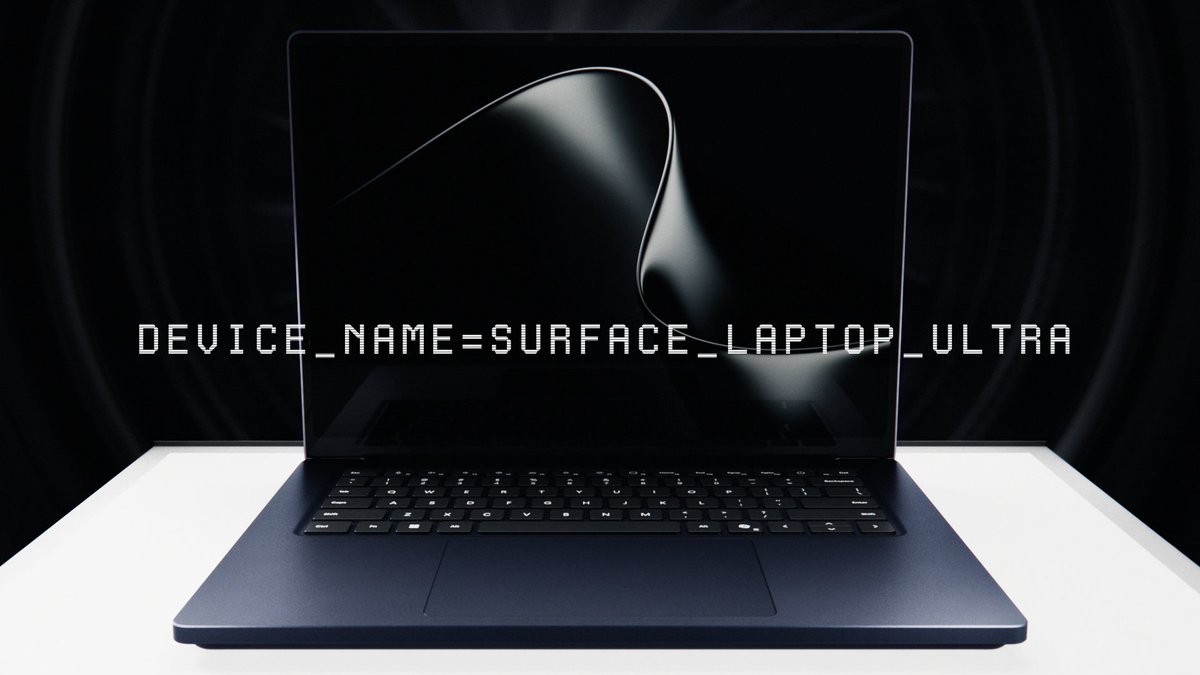
Microsoft today showcased DeepSeek V4 Flash, a 284B-parameter open-weight model, runs locally on a Windows PC once quantized to 1.6 bits, which brings it down to about 60GB of memory. Their new Surface Laptop Ultra, built on Nvidia's RTX Spark chip with up to 128GB of unified memory, has... show more

25 条评论

1.6 bits on a 284B model, does it still know anything

any benchmarks for the 1.6bit quantization?

full video

Dwarfstar 4 does DS4F at 2 bits with intelligent router at FP8, 81 gb which worked on MacBook Pro and for the last 4-5 months. This doesn't seem that impressive, in fact it's a worse bitrate.

284B at 1.6 bits is about 57GB, so the memory math works. did Microsoft show what the 1.6 bit version scores against full precision, and what tokens per second on that chip

This says more about the how the model was made than about the hardware. Props to the deepseek guys.

Running a 284B model locally is a wild direction for consumer hardware.

Micosoft is shilling other folks models wtf?!

They're trying to beat Apple it its own game

1.6 bits is the number that needs a benchmark next to it. fitting 284B into 60GB is a memory story. whether it still beats a ~30B model at 8 bits on the same laptop is the question that decides if anyone runs it

Yeah but what's the cost of this fucking thing

60GB to run a quantized 284B locally means my laptop fans are filing a restraining order before the first token

Laptops will mean a different thing in the future. Maybe phones too. Or maybe we'll just think with chips on our temple!

Getting a 284B model to fit on a laptop is wild, curious what kind of generation speed they actually hit.

First 3 speakers are Indian origins😂

How useful is quanted 1 bit ds4f

Who the fuck brags about q1.6? It is the equivalency of bragging that you have Down syndrome

I am not sure which part of the news make sense …

太贵了…

Great

And then no one buys cloud subscription 😂

the memory math checks out, 284 billion weights at 1.6 bits is about 57 gb. what to check next is quality, since a model squeezed to 1.6 bits can lose accuracy compared with the same model at 4 bits, and speed per token depends on memory bandwidth too.

who da fuck has 60GB of RAM? I need alternatives for poor people with 16GB on a linux laptop

And to comprehend that they tried best to frighten window users from running deepseek, when it came out.

I wonder if all those quantization heroes realize how the model builds up gradient during RL :)