Video wird geladen...
Video konnte nicht geladen werden
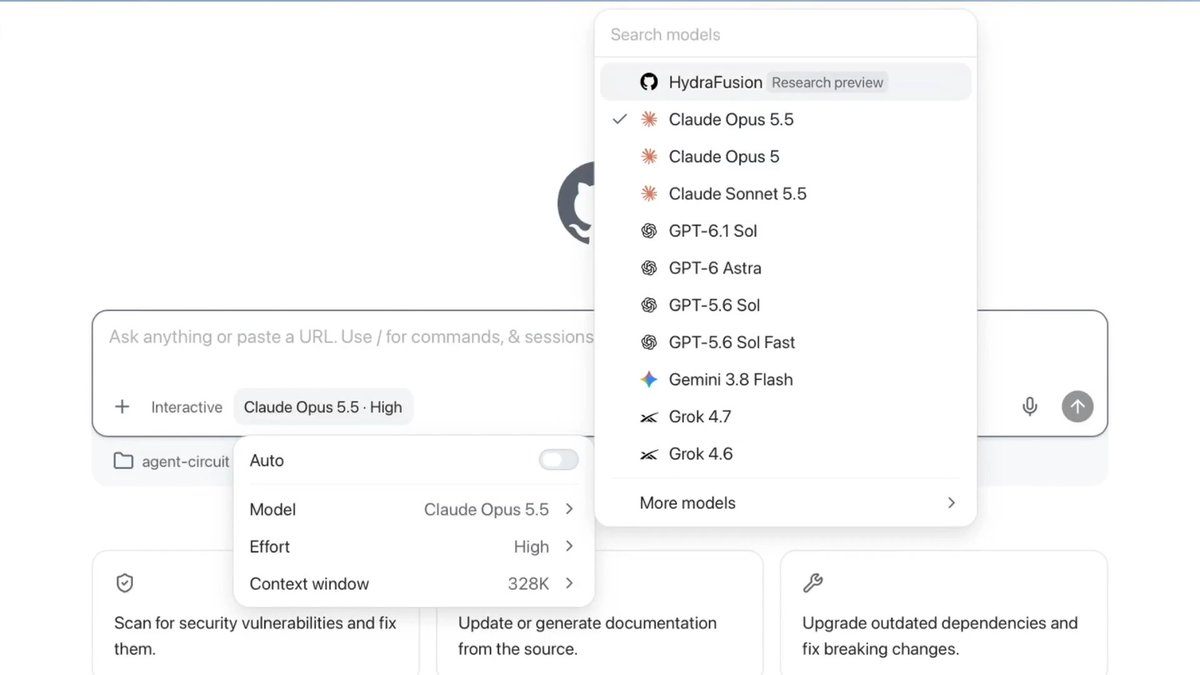
Model Council is now available inside Computer. Run independent analysis across multiple frontier models, choose your analysis depth, and get a single cited report on where models agree, where they disagree, and what each found that others missed.
89,227 Aufrufe • vor 3 Monaten •via X (Twitter)
34 Kommentare

Read more about using Model Council inside Perplexity Computer:

Love what you guys have done and you probably have good harnesses- but this is pretty powerful open source out of the box via Karpathy

Me remembering when perplexity promised that pro users would get model council momths ago :(

This sounds like an absolute dream workflow for research. 🤩

@AravSrinivas Another feature I was hoping for. Perplexity continues to kick ass.

@perplexity_ai this is a game changer for model comparisons! gonna save so much time running these analyses separately. finally, some clarity in the chaos!

Integrating an automated council directly into execution environments cuts down on the friction of manual cross-model verification. It allows teams to stress-test ideas across different architectures without breaking their flow.

Amazing work!

Thanks for sharing! Curious to see how people use these new capabilities in real-world workflows.

A powerful step for AI workflows. Comparing multiple frontier models in one place makes it easier to validate insights, reduce blind spots, and make more confident decisions.

A model council is useful until five models repeat the same bad source with different accents. The citations matter more than the vote.

With so many capable models available, the quality of research and agent tooling on top is becoming the bigger differentiator.

run the same analysis across frontier models in one report, see where they agree and what each missed, the consensus is the wisdom 💀

this is actually useful for when i need to fact check something at 3am without waking up a group chat

This is the right direction: model choice should become an explicit analytical surface, not a hidden implementation detail. For serious workflows, seeing agreement, disagreement, citations, and missed angles is much more useful than pretending one model is the oracle.

언제나 그렇지만 사용량과 토큰 제한이 문제 ㅜㅜ

the next AI interface might not be a chatbot. it might be a room full of models arguing until they find the strongest answer

Five models voting on an answer is not the same as five independent experts checking the facts. Most frontier models trained on the same data, so they tend to agree on the same wrong things. Ask the council about any niche legal question or recent news event and you will get a confidently cited consensus that is just confidently wrong together.

This is how AI should work-multiple perspectives, one reliable answer.

This is innovative and very nearly what I had recently tried to design myself. Thanks!

the disagreement part is what i'd actually pay for, agreement across models is just consensus theater.

Cost is the real question here — running multiple frontier models per query isn't cheap for the end user.

This is how AI research should feel: multiple expert opinions, one consolidated answer. Huge upgrade for complex tasks. 👏

do the council members retrieve independently too, or do they all reason over the same source bundle? shared retrieval would make agreement look stronger than it is.

worth knowing this is web and computer only for max subscribers, not something free tier users get access to right now

great

Model Council makes AI analysis much more reliable

It doesn't just look at the answer of one model, but at once, it looks at the consensus and conflicts of several front-line models. It seems that AI analysis now relies more on perspective comparison than just one correct answer. Model Council, it's quite an important direction.

Really useful feature, you get the best from each model. One thing to notice: you pay for each model's answer, so it costs more. Makes sense and worth it, just good to remember. Ironically, I am sometimes doing the same thing - just manually.

the real value here is the disagreement part, not the agreement. when three models converge you move fast, when they don't you know exactly where to dig deeper instead of trusting one confident answer blind

Getting multiple models to argue it out before you decide is such a smart idea.

I think it's time I had perplexity to my system softwares

Very good I can say. This will enable one to compare different results and choose the best among.

finally being able to run the same question across multiple frontier models and get a clear report on the consensus and the gaps feels like a real upgrade. most of the time you’re still stuck with one model’s view. when you can see where they agree and what each one caught that the others missed, the whole process becomes more grounded. the systems that last are the ones that make cross-checking easy instead of forcing you to trust a single output.